# GlassFlow® documentation GlassFlow is the observability and context layer for teams running AI agents in production. Two products sit under the GlassFlow umbrella. Pick one to get started.
Rius
Agent observability
Trace every LLM call, tool invocation, and agent step. Monitor cost, tokens, and errors.
Built for long-running agents, with MCP in both directions and extended trace retention. Query every trace from your AI client, no dashboard required.
Explore Rius →
Tares
Context infrastructure
The context layer for your agents.
Instead of an agent calling each tool at runtime, Tares pre-processes and delivers exactly the data your agent needs, cutting token consumption and latency.
Explore Tares →
--- # Rius _Agent observability: every LLM call, tool invocation, and agent step, traced end to end._ Rius by GlassFlow® is the agent observability product in the GlassFlow family. ![The Rius console: the Home page with volume, cost, tokens, and error rates](/assets/ui_home.png) Your agents send OpenTelemetry GenAI traces, through the `glassflow-rius` SDK or any OpenTelemetry SDK or collector, and Rius turns them into something you can interrogate: ask *why did this run cost $4?* and walk one waterfall from the failing root span to the exact generation, with its prompt, token counts, and cost on the span. You never send a cost or a latency value: cost is computed server-side from the model and token usage, and time to first token is derived from the first-token event the instrumentors stamp on streamed generations. Traces tell you what an agent did; [heartbeats](/rius/platform/agents) tell you whether the process is alive right now, ready, mid-run, or gone. And the [MCP server](/rius/mcp) turns the whole thing conversational: connect Claude, Cursor, or your editor and ask about your telemetry from where you already work. Rius is a managed platform: [create an account](https://console.rius-glassflow.com), mint an API key, send traces. Nothing to host. ## How it works 1. **Instrument**: `init()` once; the SDK auto-instruments the LLM libraries you already use (OpenAI, Anthropic, LangChain, and friends) and `observe` covers your own functions. No SDK? Raw OTLP and third-party instrumentation land with the same analytics. 2. **Ingest**: traces post to the OTLP receiver at `https://ingest.eu.console.rius-glassflow.com/v1/traces` (the SDK's default), authenticated by an API key; the key decides the workspace, and content-privacy controls are applied before anything leaves your process. 3. **Explore**: the console renders the trace list, waterfall, map view, and span detail, with cost, tokens, and time to first token (TTFT) computed server-side. 4. **Monitor, alert, and ask**: the Agents view classifies every instrumented process by liveness, Home tracks volume, cost, and errors per period, alerts fire on recurring errors, silent failures, tool loops, and thresholds you set, and the MCP server answers questions over all of it in plain language. ## Data model - A **workspace** is where traces live; every trace belongs to exactly one, determined by the API key that sent it. - A **trace** is one run of your agent; a **span** is one step of it. - A **generation** is a span that records an LLM call: model, token usage, and (subject to your privacy controls) prompt and response. - An **agent instance** is one heartbeating process; instances group under an agent name. - **Cost** and **time to first token** are derived server-side, from token usage and the first-token event; you never send the values. Full definitions are in [Concepts](/rius/concepts). ## Documentation - [Quickstart](/rius/quickstart): from zero to your first trace in four steps. - [Concepts](/rius/concepts): the data model in full. - [SDK](/rius/sdk): installation, tracing, integrations, privacy, reliability. - [Platform](/rius/platform): the console, task by task: traces, agents, alerts, usage and cost, settings. - [MCP](/rius/mcp): connect an AI client and query your traces. - [Interoperability](/rius/interoperability): send data without the SDK, via raw OTLP or third-party instrumentation. - [Guides](/rius/guides): longer walkthroughs, including multi-tenant observability and migrating from Langfuse. ## Need something Rius doesn't do yet? Missing integrations, questions, or feedback: email [help@glassflow.ai](mailto:help@glassflow.ai). We're building against real use cases and reply quickly. --- # Quickstart From nothing to a visible trace in one sitting. Rius needs three things: an account, an API key, and two lines of instrumentation. ## 1. Create an account Open [console.rius-glassflow.com](https://console.rius-glassflow.com) and click **Create account**. Sign up with your work email, then **Set up your workspace**: name your first workspace (and, if you like, your organization), and pick the region where its data lives. The region can't be changed later. You land in the new workspace. Already have an account? Click **Sign in** on the same page. Rius opens the workspace you last used, or asks you to pick one under **Choose a workspace**. Accounts are created on console.rius-glassflow.com only. **Create account** on a regional console sends you there. ![The Rius sign-in screen](/assets/ui_signin.png) ## 2. Create an API key The **Get started** page generates an instrumentation prompt you can paste straight into Claude Code, which installs the SDK and wires the key in for you. To do it by hand instead, keep following this page. ![The Get started page](/assets/ui_get_started.png) Click **Create API key** and name the key after the agent or environment that uses it: ![A freshly created API key](/assets/ui_api_key_created.png) The full key is shown exactly once. The server stores only a hash, so copy it into your secret manager now; if you lose it, revoke the key and issue a new one. ## 3. Instrument your agent ```bash pip install "glassflow-rius[anthropic]" anthropic ``` The extra installs the Anthropic instrumentation, not `anthropic` itself, so both are named here for a fresh environment. This is a complete agent, one LLM call included. Save it as `agent.py`, fill in your two keys, and it runs as-is: ```python import anthropic import rius rius.init(api_key="ri_...", service_name="my-agent") claude = anthropic.Anthropic() # reads ANTHROPIC_API_KEY @rius.observe def handle(query: str) -> str: response = claude.messages.create( model="claude-haiku-4-5-20251001", max_tokens=200, messages=[{"role": "user", "content": query}], ) return response.content[0].text handle("What should I check when a collector drops spans?") ``` ```bash npm install @glassflow-ai/rius @opentelemetry/api @anthropic-ai/sdk \ @arizeai/openinference-instrumentation-anthropic ``` `@opentelemetry/api` is a peer dependency, and the last package is the Anthropic instrumentation rather than the Anthropic client itself. The same agent in TypeScript. Save it as `agent.ts` and run it with your usual TypeScript runner: ```typescript const rius = init({ apiKey: 'ri_...', serviceName: 'my-agent' }) await rius.ready // auto-instrumentation is attached before the first call const claude = new Anthropic() // reads ANTHROPIC_API_KEY const handle = observe(async function handle(query: string) { const message = await claude.messages.create({ model: 'claude-haiku-4-5-20251001', max_tokens: 200, messages: [{ role: 'user', content: query }], }) const [block] = message.content return block.type === 'text' ? block.text : '' }) await handle('What should I check when a collector drops spans?') ``` Name the wrapped function, as above, rather than passing an arrow function: `observe` takes the span name from the function, and an anonymous one traces as `anonymous`. `init` once at startup, then wrap the functions that make up your agent's steps: `@rius.observe` in Python, `observe()` in TypeScript. The Anthropic call needs nothing at the call site: [auto-instrumentation](/rius/sdk/integrations) picks it up and emits the generation span, so the trace you are about to see carries the model, token counts, and cost. The [configuration reference](/rius/sdk/installation#configuration-reference) covers everything `init` accepts. ## 4. Run it and watch the trace arrive Run your agent once, any run counts. The **Traces** view checks for new traces automatically, no reload needed: ![The trace list with fresh traces](/assets/ui_traces_list.png) Open the trace to see every step on the waterfall, including token counts, cost, and any errors along the way: ![A trace waterfall](/assets/ui_trace_waterfall.png) ## Next steps - [Exploring traces](/rius/platform/exploring-traces): the waterfall, the map view, and span detail in depth. - [MCP](/rius/mcp): connect Claude, Cursor, or your editor and query the traces you just sent in plain language. - [SDK](/rius/sdk): instrumentation beyond the basics, privacy controls, sampling. - [Monitoring live agents](/rius/platform/agents): your agent is already reporting a heartbeat, so the Agents view shows whether it is alive between runs. --- # Guides Task-oriented walkthroughs. Where the [SDK](/rius/sdk) and [interoperability](/rius/interoperability) sections document one surface at a time, a guide cuts across them to get a specific job done end to end. - [Claude Code plugin](/rius/guides/claude-code-plugin): trace your own Claude Code sessions in Rius with four commands, and query them from the same terminal. - [Codex (beta)](/rius/guides/codex): the same plugin for the Codex CLI. - [Cursor (beta)](/rius/guides/cursor): the same plugin for the Cursor agent, without token or cost data. - [OpenHands](/rius/guides/openhands): send OpenHands SDK and web-app conversations to Rius with three environment variables, and catch stuck agents with the Tool Loop alert. - [Multi-tenant observability](/rius/guides/multi-tenant-observability): the workspace-per-customer pattern for teams selling agents to their own customers, from onboarding runbook to per-customer cost and visibility. - [Migrate from Langfuse](/rius/guides/migrate-from-langfuse): map the concepts, keep your instrumentation or swap the SDK, run both backends side by side, then cut over. More migration guides (Phoenix, LangSmith) follow the same shape and are on the way. --- # Claude Code plugin The Rius plugin for Claude Code turns each Claude Code session into a trace in Rius. The trace holds your prompts, every model call with its tokens and cost, every tool call, and the subagents Claude Code started, laid out as a waterfall. The plugin also connects the [Rius MCP server](/rius/mcp), so you can ask Claude about those sessions without leaving the terminal. Setup takes four commands: two to install, one to sign in, and one to pick a folder to trace. The [5-minute walkthrough](#try-it-in-5-minutes) runs the whole loop. By default the plugin sends **full session content** for the folders you enable, including the contents of files Claude Code reads and the output of commands it runs. Everyone with access to the workspace can read it. Read [what gets captured](#what-gets-captured) before you enable a folder, or [turn content capture off](#turn-content-capture-off) first. ## Try it in 5 minutes The whole loop, end to end. Each step links to the section with the details. 1. **Install.** In a terminal, run `claude plugin marketplace add glassflow/rius-coding-agents && claude plugin install rius@rius-coding-agents`. See [Install](#install) to install from inside Claude Code instead. 2. **Sign in.** Run `/rius:login`. In the browser, sign in (or sign up), pick a workspace or create one, and click **Connect**. See [Sign in](#sign-in). 3. **Turn tracing on.** `cd` into a repo, then run `/rius:enable-here` and `/rius:status`. The first line should read `Rius tracing: on`. See [Choose which folders are traced](#choose-which-folders-are-traced). 4. **Work as usual.** Ask Claude Code to do something real in that repo. Then open the trace list at `console.rius-glassflow.com` and find the session. See [What you see in the console](#what-you-see-in-the-console). 5. **Ask about it.** Reconnect `rius` in `/mcp`, then ask Claude "list my recent Claude Code sessions in Rius". See [Query your sessions](#query-your-sessions-from-claude-code). 6. **Turn it off for a folder.** Run `/rius:disable-here`. Nothing more from that folder reaches Rius; a session already running just closes its trace when it ends. See [Disabling a folder mid-session](#disabling-a-folder-mid-session). 7. **Sign out.** Run `/rius:logout`. The key is revoked, and it stops working everywhere within about a minute. See [Sign out](#sign-out). Steps 2 and 3 in a real terminal, signing in, enabling a folder, and checking the state: ![Claude Code after /rius:login, /rius:enable-here and /rius:status: connected to a workspace, tracing on for the folder, production endpoints, key from /rius:login](/assets/cc_plugin_login_status.png) ## Requirements - Claude Code with plugin support. - Python 3.9 or later on your `PATH`. The plugin uses only the standard library and installs nothing from PyPI. - macOS, Linux, or Windows. On Windows the hooks run through Git Bash, which Claude Code already uses for its Bash tool. You don't need a Rius account yet. You can sign up during `/rius:login`. ## Install Run this in a terminal: ```bash claude plugin marketplace add glassflow/rius-coding-agents && claude plugin install rius@rius-coding-agents ``` Or install from inside Claude Code. Run the two commands one at a time: pasting both together fails, because Claude Code reads the whole paste as one command. 1. Add the marketplace: ```text /plugin marketplace add glassflow/rius-coding-agents ``` 2. Install the plugin: ```text /plugin install rius@rius-coding-agents ``` 3. Load it into the running session: ```text /reload-plugins ``` Installing sends nothing. Tracing stays off for every folder until you [enable one](#choose-which-folders-are-traced). ## Sign in ```text /rius:login ``` Claude Code repeats the content warning above, prints a link and a short code, and opens the Rius portal at `console.rius-glassflow.com` in your browser: 1. Sign in, or sign up if you don't have an account yet. 2. Check that the page shows the same code, and the name of the machine you ran the command on. The page reads **Claude Code on `` wants to connect**. Only continue if you just ran `/rius:login` yourself. 3. Choose the workspace this machine sends sessions to. It can be a workspace you own, or one you are only a member of. 4. Click **Connect**. The text above the button spells out what you are granting: Claude Code can send sessions to that workspace and read all traces in it. Back in Claude Code, the plugin reports where it landed: ```text Connected as you@example.com → eng-shared (Acme). Trace this folder (/Users/you/code/app)? Run /rius:enable-here. Reconnect "rius" in /mcp to query your traces. ``` The sign-in link expires after 15 minutes. If it does, run `/rius:login` again. ### The key the plugin stores Signing in mints one API key for this machine and the workspace you chose: - It carries the `ingest` and `read` scopes, so one key both sends traces and queries them over MCP. - It expires after 90 days. Run `/rius:login` again to get a new one. - It is stored in `~/.claude/rius/credentials.json`, readable only by you (mode 0600). It never goes into Claude Code's settings files, which tend to get committed and shared. - It is listed under **Settings → API keys** in the console as `Claude Code: ()`. A workspace admin can revoke it there like any other key. Running `/rius:login` again replaces the key and revokes the old one. If you pick a different workspace the second time, every folder you have enabled sends to the new workspace from then on, and the plugin says so. Traces sent with this key show you in the **Sent by** column of the trace list, so teammates sharing a workspace can tell whose sessions are whose. ## Choose which folders are traced Tracing is off everywhere until you turn it on for a folder. In the folder you want traced: ```text /rius:enable-here ``` That folder and everything under it is traced. A session that is already open when you enable its folder is traced from its start: everything said earlier in that session is sent too, with content unless [capture is off](#turn-content-capture-off). To trace only from now on, start a new session after enabling. To stop tracing a folder, including one inside an enabled parent: ```text /rius:disable-here ``` The rules live in `~/.claude/rius/config.json` and apply to every Claude Code session on the machine. A disabled folder always wins, at any depth: you can enable `~/code` and still keep `~/code/client-secrets` out. The reverse doesn't work. Enabling a folder inside a disabled one leaves it off, and the plugin tells you which folder to enable instead. ### Disabling a folder mid-session If you run `/rius:disable-here` while a traced session is open, nothing that happens after that point is sent. When the session ends, the plugin still closes its trace, sending only the structure of what was open (no prompts, replies, or tool content), so the trace is complete and counts on the Agents and Users pages. The stop is final for that session: enabling the folder again doesn't resume it. The next session in the folder follows the folder rules as usual. `/rius:status` shows a `Stopped:` line for a session in this state. For a one-off exception that doesn't touch the folder rules, `/rius:off` stops tracing for the current session only. Like disabling the folder, it is final once the session's trace has started: `/rius:on` only helps if you ran `/rius:off` before the first prompt. A new session starts without the override. ### Check the state ```text /rius:status ``` `/rius:status` shows whether this folder is traced and which rule decided it, along with the account, the workspace, and how many spans this session has sent so far: ```text Rius tracing: on Reason: on: path rule '/Users/you/code/app' enables /Users/you/code/app cwd: /Users/you/code/app session: 0f1d9c2e-… Platform: darwin (locking: fcntl.flock, liveness: os.kill(pid, 0)) Endpoint: https://ingest.eu.console.rius-glassflow.com MCP: https://mcp.eu.console.rius-glassflow.com/mcp MCP key: /rius:login Reconnect "rius" in /mcp to query your traces with this key. API key: ri_… Key from: /rius:login Rule: `/Users/you/code/app` enables this folder Signed in as: you@example.com Workspace: eng-shared (Acme) Key expires: 2026-12-29 Spans exported this session: 12 ``` If you disabled this folder earlier in the session, the first line reads `Rius tracing: off` and a `Stopped:` line follows `Reason`; see [Disabling a folder mid-session](#disabling-a-folder-mid-session). Send a prompt or two, then open the [trace list](/rius/platform/exploring-traces) in the console. The session's spans show up there while it is still running. The counts on other pages wait for the session to end; see [What you see in the console](#what-you-see-in-the-console). ![A Claude Code session in the console: the span tree with model calls and a failed Bash tool call, and one model call's output](/assets/ui_cc_plugin_trace.png) ## What you see in the console - **Traces.** Each session appears in the [trace list](/rius/platform/exploring-traces) while it runs, and its spans fill in as Claude Code works. The session itself shows as in progress until you exit Claude Code, which closes it. From plugin 0.4.3, the trace is named after the session: the name you gave it with `/rename` or `--name`, or else the title Claude Code generates from your first prompt. Rename a session while it runs and the trace name follows. Earlier versions, and every session with [content capture off](#turn-content-capture-off), name the trace `claude-code session`. - **Agents.** While a session is open, the [Agents](/rius/platform/agents) page shows it as a live instance of an agent named `claude-code` (or your `RIUS_SERVICE_NAME`), from the plugin's heartbeat. The agent's trace, error, and cost figures only count a session once it has ended. A session that never ends cleanly, because Claude Code crashed or was killed, never counts there. A session started before its folder was enabled sends no heartbeat, so it doesn't appear under Instances. A session whose folder you disabled while it was running still counts once it ends: see [disabling mid-session](#disabling-a-folder-mid-session). - **Users.** The plugin doesn't set an end user, so its sessions land in the **anonymous** row of the [Users](/rius/platform/users) page. To see who ran a session, use the **Sent by** column in the trace list, which names the owner of the key. ![The Agents page with the claude-code agent: one ready and two stopped instances from the plugin's heartbeat, and the window's traces and cost](/assets/ui_cc_plugin_agents.png) ## What gets captured One Claude Code session is one trace, with the same session id throughout. If you resume a session, it continues the same trace. ```text AGENT the session └─ CHAIN a turn: one prompt and everything it caused └─ LLM a model call: model, input and output tokens, cache reads ├─ TOOL a tool call: Bash, Read, Edit, and so on └─ TOOL Agent: the call that started a subagent └─ AGENT the subagent, named by its type └─ LLM the subagent's own model calls and tools ``` Subagents get their own spans with their own tokens. That matters on cost: in long sessions, subagents can account for more than half of all tokens. Turns that Claude Code injected itself, such as a slash command's output or a background task's report, are kept but marked as system turns, so you can tell them apart from what you typed. | Captured | With content capture on (default) | With content capture off | |---|---|---| | Span tree, timing, status | ✓ | ✓ | | Model names, tokens, cache reads, cost | ✓ | ✓ | | Tool names and subagent types | ✓ | ✓ | | Your prompts and Claude's replies | ✓ | ✗ | | The session's name, as the trace name (0.4.3 and later) | ✓ | ✗ | | Tool inputs, such as commands and file paths | ✓ | ✗ | | Tool outputs, such as file contents and command output | ✓ | ✗ | | Error details of a failed tool call | ✓ | ✗ | With content on, each captured value is capped at 32 KB and marked where it was cut, so one large file read doesn't break the export. Content capture is decided on your machine, before anything is sent. The plugin contacts three hosts and nothing else: the ingest endpoint `ingest.eu.console.rius-glassflow.com`, the MCP server `mcp.eu.console.rius-glassflow.com`, and the sign-in host `connect.console.rius-glassflow.com`, which `/rius:login` and `/rius:logout` use. Model-call durations are approximate. Claude Code's transcript records when a reply finished but not when the request went out, so a model span's duration can include time you spent reading or approving a permission prompt. Tool durations are exact. ### Turn content capture off Set `RIUS_CAPTURE_CONTENT` to `false` in the `env` block of a Claude Code settings file. For every project on the machine, use `~/.claude/settings.json`: ```json filename="~/.claude/settings.json" { "env": { "RIUS_CAPTURE_CONTENT": "false" } } ``` For one project only, put the same block in that project's `.claude/settings.local.json`. Restart Claude Code after the change. You keep the full structure, models, tokens, cost, and timing, and lose the text of prompts, replies, and tool inputs and outputs. Turning capture off applies to what is sent from then on. Traces already in the workspace keep their content. ## Query your sessions from Claude Code The plugin brings the Rius MCP server with it, registered as `rius` and pointed at `https://mcp.eu.console.rius-glassflow.com/mcp`. It signs in with the key `/rius:login` stored, so there is no second login. After `/rius:login`, reconnect `rius` in `/mcp`, or restart Claude Code. If you set `RIUS_API_KEY` instead of signing in, see [Use an existing API key](#use-an-existing-api-key). ![/mcp in Claude Code: the plugin's rius server connected and authenticated against the production MCP URL](/assets/cc_plugin_mcp.png) Then ask in plain language: - "Which of my Claude Code sessions in the last 24 hours cost the most, and what did the tokens go on?" - "Show me my last failed session and which tool call went wrong." - "How much did subagents cost me this week compared with the main session?" The [tools reference](/rius/mcp/tools) lists everything the server can answer. If you already added the server by hand from the [MCP page](/rius/mcp) as `glassflow`, both entries work; remove one in `/mcp` if you only want one. ## Sign out ```text /rius:logout ``` This revokes the key on the server and then deletes it from your machine. Rius services cache keys briefly, so a revoked key keeps working for up to about a minute. If Rius can't be reached, the plugin still signs you out locally and tells you the key stays valid until it expires. Ask a workspace admin to revoke it under **Settings → API keys**. Signing out doesn't delete traces already sent, and doesn't remove your folder rules. With no key, tracing is off everywhere. Signing out while a session is running removes the key that session was using, so the plugin can't close its trace when it ends. That session stays in the trace list as in progress, and never counts on the Agents or Users pages. To remove the plugin: ```text /plugin uninstall rius ``` Folder rules, logs, and the stored key live in `~/.claude/rius/` and survive an uninstall. Delete that directory for a clean slate: ```bash rm -rf ~/.claude/rius/ ``` ## Use an existing API key If you would rather manage the key yourself, for example on a machine without a browser, set `RIUS_API_KEY` instead of running `/rius:login`. Create the key under **Settings → API keys** with **Send telemetry** (`ingest`). Put it in the project's `.claude/settings.local.json`, which is usually gitignored: ```json filename=".claude/settings.local.json" { "env": { "RIUS_API_KEY": "ri_..." } } ``` `RIUS_API_KEY` wins over a key stored by `/rius:login` for tracing, and `/rius:status` says which one is in use on its `Key from:` line. `RIUS_API_KEY` covers tracing only. Claude Code does not pass environment variables whose names look like credentials to a plugin's MCP servers, so the bundled `rius` server never sees it. To query your traces from Claude Code, either run `/rius:login` as well, or add the MCP server yourself under its own name, `glassflow`, with a key that carries **Query data** (`read`), as on the [MCP page](/rius/mcp): ```bash claude mcp add --transport http glassflow https://mcp.eu.console.rius-glassflow.com/mcp \ --header "Authorization: Bearer ri_..." ``` Query through `glassflow`. The bundled `rius` entry keeps answering 401 without a `/rius:login` key; you can disable it in `/mcp`. Other settings, all optional and set the same way: | Variable | Default | What it does | |---|---|---| | `RIUS_CAPTURE_CONTENT` | `true` | `false` sends structure only. See [above](#turn-content-capture-off). | | `RIUS_SERVICE_NAME` | `claude-code` | The service name on every trace. | | `RIUS_CLAUDE_MAX_ATTR_BYTES` | `32768` | The size cap for each captured value. | | `RIUS_CLAUDE_DEBUG` | `false` | Verbose logs in `~/.claude/rius/log/`. | ## Troubleshooting Start with `/rius:status`. A plugin that is installed but not enabled for this folder looks the same from the outside as a broken one, and the `Reason` line tells them apart: | `Reason` line | What to do | |---|---| | `off: no path rule matches , and the default is off` | Run `/rius:enable-here` in this folder. | | ``off: no API key: run `/rius:login` (or set RIUS_API_KEY)`` | The folder is enabled but there is no key. Run `/rius:login`, or set `RIUS_API_KEY`. | | `off: session override` | You ran `/rius:off` in this session. If the session had already started tracing, it stays off; start a new session. | | `on: path rule '' enables ` | Tracing is working, unless a `Stopped:` line follows (see below). | When tracing is off for another reason and there is no key either, the line names both, for example ``off: no path rule matches , and the default is off; also no API key: run `/rius:login` (or set RIUS_API_KEY)``. Fix both before expecting traces. A `Stopped:` line under `Reason` means tracing was turned off for this session while it was running: a folder disable, `/rius:off`, or `RIUS_CLAUDE_ENABLED=false`. That session sends nothing more, even if the folder is enabled again, and `Rius tracing` reads `off` for it whatever the rules say. Its trace is still closed when it ends. Start a new session to trace again. The line reads: ```text Stopped: this session stopped tracing when its folder was disabled, and stays stopped even if the folder is enabled again. New sessions in this folder are traced as usual. ``` If tracing is on but `Spans exported this session` stays at 0, look for a `Last export error` line in the same output: - **HTTP 401 right after signing in.** A new key can take up to about 30 seconds to reach the ingest endpoint. Send another prompt after a short wait. - **HTTP 401 or 403 later on.** The key was revoked or has expired. Run `/rius:login` again. - **The MCP server answers with 401 right after `/rius:login`.** Reconnect `rius` in `/mcp`, so it picks up the new key. - **The MCP server answers with 401 and you use `RIUS_API_KEY`.** Claude Code doesn't pass that variable to the bundled server, and `/rius:status` says so: `MCP key: none. Claude Code does not pass RIUS_API_KEY to the bundled MCP server; run /rius:login to query your traces.` Run `/rius:login`, or add the server yourself as shown in [Use an existing API key](#use-an-existing-api-key). If the plugin seems not to change after an update, Claude Code is still running its cached copy. Refresh it, one command at a time: ```text /plugin marketplace update rius-coding-agents ``` ```text /reload-plugins ``` If the plugin can't find a Python interpreter, `/rius:status` says so and names the ones it tried: `Rius: no Python interpreter found on PATH`. For the tracing hooks, `~/.claude/rius/log/bootstrap.log` records the same. --- # Codex (beta) The Rius plugin also runs in the [Codex](https://developers.openai.com/codex) CLI. Each Codex session becomes one trace in Rius, with your prompts, every model call with its tokens, every tool call, and the subagents Codex started. The plugin also brings the [Rius MCP server](/rius/mcp), so you can ask Codex about those sessions. **Beta.** Codex support needs version 0.6.0 or later of the Rius plugin. It is tested with codex-cli 0.144.1. The same plugin traces [Claude Code](/rius/guides/claude-code-plugin) and [Cursor](/rius/guides/cursor); each one keeps its own sign-in, key, and folder rules. ## Try it in 5 minutes 1. **Install.** In a terminal, run `codex plugin marketplace add glassflow/rius-coding-agents`, then `codex plugin add rius@rius-coding-agents`. See [Install](#install). 2. **Trust the hooks.** In Codex, open `/hooks` and trust the five `rius` hooks. See [Trust the hooks](#trust-the-hooks). 3. **Sign in.** Type `$rius:rius-login`, approve the sandbox escalation, then pick a workspace in the browser and click **Connect**. See [Sign in](#sign-in). 4. **Turn tracing on.** In a repo, run `$rius:rius-enable-here`, then `$rius:rius-status`. See [Choose which folders are traced](#choose-which-folders-are-traced). 5. **Work as usual**, then find the session in the trace list at `console.rius-glassflow.com`. 6. **Ask about it.** Run `codex mcp login rius` once, then ask Codex "list my recent Codex sessions in Rius". See [Query your sessions](#query-your-sessions-from-codex). ## Requirements - The Codex CLI with plugin support. - Python 3.9 or later on your `PATH`. The plugin uses only the standard library. - macOS or Linux. Windows is untested for Codex. ## Install ```bash codex plugin marketplace add glassflow/rius-coding-agents codex plugin add rius@rius-coding-agents ``` Installing sends nothing. Tracing stays off for every folder until you enable one. ### Trust the hooks Codex runs no plugin hook until you approve it. Open `/hooks` in Codex and trust the five `rius` hooks: SessionStart, UserPromptSubmit, PostToolUse, Stop, and SubagentStop. Until you do, nothing is traced and Codex doesn't tell you. The `Hooks:` line of `$rius:rius-status` counts the approved ones, so check it if a session doesn't show up. Codex keeps the approval across plugin updates, and asks again if a new version changes the hooks. ## Sign in The plugin's commands are Codex skills. Type `$` and pick one. Codex never runs them on its own, so only you can start one, and it may ask before running the command behind it. ```text $rius:rius-login ``` Login writes to `~/.codex/rius/` and needs the network, so in the default sandbox Codex asks you to approve an escalation. Then, in the browser: 1. Sign in, or sign up if you don't have an account yet. 2. Check that the page shows the same code, and the name of your machine. Only continue if you just started the sign-in yourself. 3. Choose the workspace this machine sends sessions to. 4. Click **Connect**. If the sandbox won't allow it, run the same command from a terminal: ```bash bash ~/.codex/plugins/cache/rius-coding-agents/rius//scripts/rius_ctl.sh login --agent codex ``` It prints a link and a code. Approve in the browser, then run the same command again with `login-wait` in place of `login`. Signing in stores one key for this machine in `~/.codex/rius/credentials.json`, readable only by you. It is separate from the Claude Code key: signing out of one doesn't sign out the other. Rius always keeps it under your own home folder, even if `CODEX_HOME` points somewhere else. The key is listed under **Settings → API keys** in the console, where a workspace admin can revoke it. ## Choose which folders are traced Tracing is off everywhere until you turn it on for a folder. The enable and disable skills write to `~/.codex/rius/`, so Codex asks you to approve them. | Skill | What it does | |---|---| | `$rius:rius-enable-here` | Trace this folder and everything under it, structure only | | `$rius:rius-enable-content-here` | The same, plus prompts, replies, and tool output, with secrets removed | | `$rius:rius-disable-here` | Stop tracing this folder. A disabled folder beats any enabled parent. | | `$rius:rius-on`, `$rius:rius-off` | Turn tracing on or off for this session only | | `$rius:rius-status` | Whether this folder is traced and why, the account, the key, and the hooks | | `$rius:rius-logout` | Revoke the key and delete it from this machine | The rules apply to every Codex session on the machine, and are separate from the Claude Code ones. ## What you see in the console - **Traces.** Each session is one trace. Resuming it, with `codex resume` or `codex exec resume`, continues the same trace. - **Agents.** Sessions show up as an agent named `codex` on the [Agents](/rius/platform/agents) page. An open session is a live instance. The agent's trace, error, and cost figures count a session once its trace is closed. - **Users.** The plugin doesn't set an end user, so sessions land in the **anonymous** row of the [Users](/rius/platform/users) page. The **Sent by** column in the trace list shows whose key sent each one. ### When a trace closes Codex doesn't tell plugins when a session ends. So a Codex trace is closed by the next Codex session you start on the same key, once the old session's Codex process has exited and it has been idle for about an hour. The trace ends at the last thing the session did. Until then it shows as in progress. `codex exec --ephemeral` sessions aren't traced, because Codex keeps no record of them for the plugin to read. ## What gets captured ```text AGENT codex session └─ CHAIN a turn: one prompt and everything it caused └─ LLM a model call: model, input, cached, output, and reasoning tokens ├─ TOOL a tool call. A command that exits non-zero is an error. └─ TOOL spawn_agent: the call that started a subagent └─ AGENT the subagent, with its own turns and calls ``` | Captured | Structure only (default) | With content | |---|---|---| | Span tree, timing, status | ✓ | ✓ | | Model names, tokens, cost | ✓ | ✓ | | Tool names, error types, subagents | ✓ | ✓ | | Your prompts and Codex's replies | ✗ | ✓ | | Tool inputs and outputs | ✗ | ✓ | With content on, the plugin replaces the secrets it recognizes, such as cloud and API keys, tokens, and private keys, with a marker before anything is sent, and caps each value at 32 KB. This is best effort: a secret in a format it doesn't know is sent. Cost is worked out from token counts at API rates, so it isn't what you pay on a ChatGPT plan. The plugin contacts three hosts and nothing else: `ingest.eu.console.rius-glassflow.com` for traces, `connect.console.rius-glassflow.com` for sign-in and sign-out, and `mcp.eu.console.rius-glassflow.com` when you use the MCP tools. ## Query your sessions from Codex The plugin registers the Rius MCP server as `rius`. It signs in on its own, through your Rius account, so run this once: ```bash codex mcp login rius ``` This is a second sign-in, separate from `$rius:rius-login`. Then ask in plain language: - "Which of my Codex sessions this week used the most tokens?" - "Show me my last failed session and which command went wrong." The [tools reference](/rius/mcp/tools) lists everything the server can answer. ## Use a key you made in the console To trace with a key you created under **Settings → API keys** (with **Send telemetry**), store it from a terminal. The command reads the key from standard input (here, the clipboard on macOS), so it never lands in your shell history: ```bash pbpaste | bash ~/.codex/plugins/cache/rius-coding-agents/rius//scripts/rius_ctl.sh use-key --agent codex ``` Setting `RIUS_API_KEY` or `RIUS_ENDPOINT` in the environment does nothing. A repository can set environment variables for Codex, so the plugin only uses a key you stored yourself. ## Settings These are environment variables. They can only turn things off. | Variable | What it does | |---|---| | `RIUS_CAPTURE_CONTENT` | `false` sends structure only from every folder | | `RIUS_CODEX_ENABLED` | `false` turns tracing off everywhere | | `RIUS_CODEX_MAX_ATTR_BYTES` | Lowers the 32 KB cap on each captured value | | `RIUS_CODEX_DEBUG` | `true` writes verbose logs to `~/.codex/rius/log/` | ## Sign out and uninstall Run `$rius:rius-logout` first. It revokes the key and deletes it from this machine; if you skip it, the key stays valid until it expires. Then remove the plugin, and delete `~/.codex/rius/` to remove folder rules, logs, and session state: ```bash rm -rf ~/.codex/rius/ ``` ## Troubleshooting Start with `$rius:rius-status`. - **`Hooks:` shows fewer than 5 approved.** Open `/hooks` and trust the `rius` hooks. - **The `Reason` line says no path rule matches.** Run `$rius:rius-enable-here` in this folder. - **The `Reason` line says there is no key.** Run `$rius:rius-login`. - **A session stays in progress.** That's expected for about an hour after you exit Codex. It closes when you start your next Codex session. - **The MCP tools answer 401.** Run `codex mcp login rius`. ## Known gaps - Model-call start times are approximate. - OpenAI doesn't report cache-write tokens, so none are shown. - A failed tool call is marked as an error only when a command exits non-zero or an MCP tool fails. Other failures look like success. --- # Cursor (beta) The Rius plugin for Cursor turns each Cursor agent chat into a trace in Rius: your prompts, the agent's answers, every tool call, and the subagents it started. It works with the agent in the Cursor editor and with `cursor-agent` in the terminal. The plugin also brings the [Rius MCP server](/rius/mcp), so you can ask Cursor about those chats. **Beta.** Cursor support needs version 0.6.0 or later of the Rius plugin. It is tested against Cursor's documented hooks, not yet against a live Cursor session, so some details may change. The same plugin traces [Claude Code](/rius/guides/claude-code-plugin) and [Codex](/rius/guides/codex); each one keeps its own sign-in, key, and folder rules. **No tokens or cost.** Cursor doesn't give plugins token counts, so Cursor traces show no token usage and no cost. You still get the full span tree, timing, models, tools, and errors. ## Try it in 5 minutes 1. **Install.** In Cursor's plugin settings, choose **Import from Repo** and enter `glassflow/rius-coding-agents`. See [Install](#install). 2. **Sign in.** In the agent chat, run `/rius-login`, then pick a workspace in the browser and click **Connect**. See [Sign in](#sign-in). 3. **Turn tracing on.** In a repo, run `/rius-enable-here`, then `/rius-status`. See [Choose which folders are traced](#choose-which-folders-are-traced). 4. **Work as usual**, then find the chat in the trace list at `console.rius-glassflow.com`. 5. **Ask about it.** Click **Connect** next to `rius` in Cursor's MCP settings, then ask "list my recent Cursor chats in Rius". See [Query your chats](#query-your-chats-from-cursor). ## Requirements - Cursor with plugin support, or `cursor-agent`. - Python 3.9 or later on your `PATH`, and `bash`. The plugin uses only the Python standard library. - macOS or Linux. Windows is untested for Cursor. ## Install In Cursor's plugin settings, choose **Import from Repo** and enter `glassflow/rius-coding-agents`. Or clone the repo into `~/.cursor/plugins/local/rius`. Installing sends nothing. Tracing stays off for every folder until you enable one. If you also have the Rius plugin for Claude Code, keep it. Cursor runs Claude Code plugin hooks too, but the Claude Code side recognizes a Cursor chat and does nothing, so nothing is traced twice. ### Older cursor-agent versions `cursor-agent` releases before 2026-08-27 ignore hooks that come from a plugin. For those, add the same hooks to your own `~/.cursor/hooks.json`. `` is the folder the plugin is installed in: ```bash bash /scripts/rius_ctl.sh install-hooks --agent cursor ``` It leaves your other hooks alone, and running it again changes nothing. Run it again after you update the plugin, so the hooks point at the new version. Add `--path ` to write a project's `.cursor/hooks.json` instead. `uninstall-hooks --agent cursor` takes the Rius hooks back out. ## Sign in In the agent chat: ```text /rius-login ``` The commands only run when you type them; the agent never starts one on its own. Each runs a script through the agent's shell tool, so Cursor may ask you to approve the command. Then, in the browser: 1. Sign in, or sign up if you don't have an account yet. 2. Check that the page shows the same code, and the name of your machine. Only continue if you just started the sign-in yourself. 3. Choose the workspace this machine sends chats to. 4. Click **Connect**. Signing in stores one key for this machine in `~/.cursor/rius/credentials.json`, readable only by you. It is separate from the Claude Code key: signing out of one doesn't sign out the other. The key is listed under **Settings → API keys** in the console, where a workspace admin can revoke it. ## Choose which folders are traced Tracing is off everywhere until you turn it on for a folder. | Command | What it does | |---|---| | `/rius-enable-here` | Trace this folder and everything under it, structure only | | `/rius-enable-content-here` | The same, plus prompts, answers, and tool input and output, with secrets removed | | `/rius-disable-here` | Stop tracing this folder. A disabled folder beats any enabled parent. | | `/rius-on`, `/rius-off` | Turn tracing on or off for this chat only | | `/rius-status` | Whether this folder is traced, and why | | `/rius-logout` | Revoke the key and delete it from this machine | If a command can't find the plugin, start a new chat and try again. ## What you see in the console - **Traces.** Each chat is one trace, and its spans arrive while you work: when the chat starts, after each answer, and every 20 tool calls. - **Agents.** Chats show up as an agent named `cursor` on the [Agents](/rius/platform/agents) page. The plugin sends no heartbeat, so Cursor chats don't appear under **Instances**. A chat counts in the agent's figures once its trace is closed. - **Users.** The plugin doesn't set an end user, so chats land in the **anonymous** row of the [Users](/rius/platform/users) page. The **Sent by** column in the trace list shows whose key sent each one. A chat's trace closes when Cursor ends the session. If Cursor never says so, the trace is closed by your next chat once it has been idle for 12 hours. ## What gets captured ```text AGENT cursor session └─ CHAIN a turn: one prompt and everything it caused └─ LLM the answer, with its model └─ TOOL a tool call. A shell command that exits non-zero is an error. └─ AGENT a subagent, under the Task call that started it ``` | Captured | Structure only (default) | With content | |---|---|---| | Span tree, timing, status | ✓ | ✓ | | Model names | ✓ | ✓ | | Tool names, error types, subagents | ✓ | ✓ | | Tokens and cost | ✗ | ✗ | | Your prompts and the agent's answers | ✗ | ✓ | | Tool inputs and outputs | ✗ | ✓ | With content on, the plugin replaces the secrets it recognizes, such as cloud and API keys, tokens, and private keys, with a marker before anything is sent, and caps each value at 32 KB. This is best effort: a secret in a format it doesn't know is sent. Each event is first written to a local file under `~/.cursor/rius/spool/`, readable only by you. With content off, no content is written there. A chat's file is deleted once the chat has been idle for 7 days and its trace is closed. Not traced: Cursor's cloud and background agents, and Tab completions. Span times are when Cursor reported each step, not when the model call started. The plugin contacts three hosts and nothing else: `ingest.eu.console.rius-glassflow.com` for traces, `connect.console.rius-glassflow.com` for sign-in and sign-out, and `mcp.eu.console.rius-glassflow.com` when you use the MCP tools. ## Query your chats from Cursor The plugin registers the Rius MCP server as `rius`. It signs in on its own, through your Rius account: click **Connect** next to `rius` in Cursor's MCP settings, or run `cursor-agent mcp login rius`. This is a second sign-in, separate from `/rius-login`. Then ask in plain language: - "Show me my last failed Cursor chat and which tool call went wrong." - "Which tools did my Cursor chats call most this week?" The [tools reference](/rius/mcp/tools) lists everything the server can answer. ## Use a key you made in the console To trace with a key you created under **Settings → API keys** (with **Send telemetry**), store it from a terminal. The command reads the key from standard input (here, the clipboard on macOS), so it never lands in your shell history: ```bash pbpaste | bash /scripts/rius_ctl.sh use-key --agent cursor ``` Setting `RIUS_API_KEY` or `RIUS_ENDPOINT` in the environment does nothing: a repository can set environment variables for the agent, so the plugin only uses a key you stored yourself. ## Settings These are environment variables. They can only turn things off. | Variable | What it does | |---|---| | `RIUS_CAPTURE_CONTENT` | `false` sends structure only from every folder | | `RIUS_CURSOR_ENABLED` | `false` turns tracing off everywhere | | `RIUS_CURSOR_MAX_ATTR_BYTES` | Lowers the 32 KB cap on each captured value | | `RIUS_CURSOR_DEBUG` | `true` writes verbose logs to `~/.cursor/rius/log/` | ## Sign out and uninstall Run `/rius-logout` first. It revokes the key and deletes it from this machine; if you skip it, the key stays valid until it expires. Then remove the plugin in Cursor's plugin settings, and run `uninstall-hooks` if you used `install-hooks`. Delete `~/.cursor/rius/` to remove folder rules, logs, and the local event files: ```bash rm -rf ~/.cursor/rius/ ``` ## Troubleshooting Start with `/rius-status`. - **The `Reason` line says no path rule matches.** Run `/rius-enable-here` in this folder. - **The `Reason` line says there is no key.** Run `/rius-login`. - **Nothing arrives from `cursor-agent`.** Older versions ignore plugin hooks. See [Older cursor-agent versions](#older-cursor-agent-versions). - **A command says it can't find the plugin.** Start a new chat, or run the same script from a terminal. - **The MCP tools answer 401.** Click **Connect** next to `rius` in the MCP settings again. --- # OpenHands [OpenHands](https://github.com/OpenHands/OpenHands) is an open-source platform for AI agents that write code, run commands and edit files. Its [Software Agent SDK](https://github.com/OpenHands/software-agent-sdk) traces every conversation with OpenTelemetry, through the open-source `lmnr` library. With no Laminar key set, that library sends plain OTLP to whatever endpoint you configure. Point it at Rius and every OpenHands conversation shows up as a trace, with no code changes and no extra package. A runnable version of this guide is in [glassflow/openhands-rius](https://github.com/glassflow/openhands-rius). It was tested with `openhands-sdk` 1.49.6 and Python 3.12. ![An OpenHands conversation in Rius, one terminal call selected](/assets/ui_openhands_trace.png) ## What Rius captures - The whole conversation as one [trace](/rius/platform/exploring-traces): the conversation, each `agent.step`, and the model and tool calls inside it. - Every model call, with its model, input and output tokens, cache reads and writes, cost, prompt and answer. - Every tool call (`terminal`, `file_editor`, `finish`, …) with its input and output, including a terminal command and its exit code. - The conversation id as the Rius session, so a multi-turn conversation groups together. - The agent name, from the script name or from `agent.name` metadata. ## Getting started ### Install the OpenHands SDK The SDK needs Python 3.12 or newer. ```bash python3.12 -m venv .venv .venv/bin/pip install openhands-sdk openhands-tools ``` ### Create a Rius API key In the [Rius console](https://console.rius-glassflow.com), open **Settings → API keys** and create a key with the **Send telemetry** scope. The key is shown once. No account yet? See the [Quickstart](/rius/quickstart). ### Set the environment variables ```bash export OTEL_EXPORTER_OTLP_TRACES_ENDPOINT=https://ingest.eu.console.rius-glassflow.com/v1/traces export OTEL_EXPORTER_OTLP_TRACES_PROTOCOL=http/protobuf export OTEL_EXPORTER_OTLP_TRACES_HEADERS="Authorization=Bearer%20ri_..." export LLM_API_KEY=sk-ant-... unset $(env | grep -o '^LMNR_[A-Z_]*') ``` Get these exactly right. When one is off, Rius never sees the spans and the agent runs on as if nothing happened. - **Protocol:** the exporter defaults to gRPC. Rius takes `http/protobuf`. - **Path:** write out the full `/v1/traces` path. `lmnr` only appends it when the URL has no path at all. - **Header encoding:** the value is URL-encoded, so the space after `Bearer` is `%20`. - **Laminar variables:** any `LMNR_*` variable, a Laminar project key in particular, takes precedence over the OTEL settings. ### Run your agent OpenHands turns tracing on by itself when it finds the OTEL variables. There is no Rius code in the script: ```python import os from openhands.sdk import LLM, Agent, Conversation, Tool from openhands.tools.file_editor import FileEditorTool from openhands.tools.terminal import TerminalTool llm = LLM( model=os.getenv("LLM_MODEL", "anthropic/claude-haiku-4-5-20251001"), api_key=os.environ["LLM_API_KEY"], base_url=os.getenv("LLM_BASE_URL"), ) agent = Agent(llm=llm, tools=[Tool(name=TerminalTool.name), Tool(name=FileEditorTool.name)]) conversation = Conversation( agent=agent, workspace=".", observability_metadata={"agent.name": "fib-writer"}, ) conversation.send_message("Write fib.py that prints the 10th Fibonacci number, run it, then finish.") conversation.run() ``` ```bash .venv/bin/python agent.py ``` Open the trace list in the console. The conversation appears under the agent `fib-writer` within a few seconds. ## Trace hierarchy One OpenHands conversation is one trace: ```text conversation ├── conversation.send_message └── conversation.run ├── agent.step │ ├── llm.anthropic/claude-haiku-4-5-20251001 │ │ └── litellm.completion LLM: model, tokens, cost, messages │ └── FileEditorAction TOOL: file_editor ├── agent.step │ ├── llm.anthropic/claude-haiku-4-5-20251001 │ │ └── litellm.completion │ └── TerminalAction TOOL: terminal └── agent.step ├── … └── FinishAction TOOL: finish ``` On production, a Claude Haiku 4.5 run of this task made four model calls: 31,091 input tokens, 966 output tokens and $0.0175 in all. Click any `litellm.completion` span to see its share. ![One model call in Rius, with its tokens and cost](/assets/ui_openhands_cost_per_call.png) ## Name the agent `lmnr` sets `service.name` to the script's filename and ignores `OTEL_SERVICE_NAME`. Without `agent.name` metadata, Rius names the agent after the script (`agent.py` becomes `agent`). Pass `observability_metadata={"agent.name": "..."}` when you create the `Conversation`, as above. It reaches every span. Start the script from its own directory. `python /abs/path/agent.py` puts the full path in the service column. ## The local web app The OpenHands web app runs each agent in its own sandbox container and forwards only `LLM_*` and `LMNR_*` variables into it, so `OTEL_*` set on the app container never reaches the agent. Pass the three values in `OH_AGENT_SERVER_ENV` instead, a JSON object of extra variables for every sandbox: ```bash docker run -it --rm --pull=always \ -e OH_AGENT_SERVER_ENV='{"OTEL_EXPORTER_OTLP_TRACES_ENDPOINT":"https://ingest.eu.console.rius-glassflow.com/v1/traces","OTEL_EXPORTER_OTLP_TRACES_PROTOCOL":"http/protobuf","OTEL_EXPORTER_OTLP_TRACES_HEADERS":"Authorization=Bearer%20ri_..."}' \ -v /var/run/docker.sock:/var/run/docker.sock \ -v ~/.openhands:/.openhands \ -p 3000:3000 \ --add-host host.docker.internal:host-gateway \ --name openhands-app \ docker.openhands.dev/openhands/openhands:latest ``` Web-app conversations show under the agent `openhands-agent-server`. The example repo has this as `deploy/docker-run.sh`. The web app's agent server streams model responses, and `lmnr` records no token usage for streamed calls. Web-app traces have every model call with its prompt and answer, and every tool call, but no tokens or cost. | How you run OpenHands | Where the variables go | | --- | --- | | SDK script | the process environment | | Local web app (Docker) | `OH_AGENT_SERVER_ENV` on the app container | | OpenHands Enterprise | the runtime pod's environment, with bundled analytics off | | OpenHands Cloud | not supported: Cloud agents take no custom environment variables | ## OpenHands Enterprise OpenHands Enterprise sends traces to its bundled Laminar by default, and while that's on, the `OTEL_*` variables are ignored. To send traces to Rius instead, follow OpenHands' [External Observability Platforms](https://docs.openhands.dev/enterprise/integrations/observability-platforms) guide with the three values above: - **Helm:** set `laminar.enabled: false`, set the `LMNR_*` variables to empty strings, and add the three `OTEL_EXPORTER_OTLP_TRACES_*` variables under `env`. Keep the key in a Kubernetes secret. - **VM install (Admin Console):** uncheck **Enable Analytics**, then add the three variables under **Custom Environment Variables**. Redeploy, and restart the runtime pod so it picks up the new environment. ## Catch stuck agents OpenHands' own stuck detector stops a conversation after four identical action/observation pairs, or when the same action fails more than three times in a row. It's a good safeguard, but it tells no one, and it lets shorter loops finish. The pre-defined [Tool Loop](/rius/platform/alerts/pre-defined#tool-loop) alert is on in every workspace. It fires when the same tool is called with the same arguments at least twice in one trace, including a loop OpenHands finished normally. Attach a [channel](/rius/platform/alerts/channels) to get the firing in Slack, email or a webhook. ![The Tool Loop alert on an OpenHands conversation](/assets/ui_openhands_tool_loop.png) To see it without spending tokens, the example repo has a scripted model that repeats the same failing command: ```bash git clone https://github.com/glassflow/openhands-rius && cd openhands-rius python3.12 -m venv .venv && .venv/bin/pip install -r requirements.txt .venv/bin/python demo/stuck_llm.py 9901 & LLM_MODEL=openai/stuck LLM_BASE_URL=http://127.0.0.1:9901/v1 LLM_API_KEY=unused \ AGENT_NAME=openhands-stuck-demo .venv/bin/python run_agent.py "List the files in missing-dir." ``` - **Four repeats** (the default): OpenHands' stuck detector stops the run. The trace still reads **Ok**, because a non-zero exit code isn't a span error. A Tool Loop alert `terminal × 4` opens a few minutes later. - **Two repeats** (`REPEAT=2` in front of `demo/stuck_llm.py`): OpenHands finishes normally, and Rius still opens `terminal × 2`. If [root-cause analysis](/rius/platform/alerts) is on for the workspace, each firing also gets a written finding. For a real agent told to poll a health check "until it answers", it named the unbounded prompt as the cause and suggested a retry limit: ![The root-cause analysis on a Tool Loop alert](/assets/ui_openhands_root_cause.png) ## Catch a rotated model key A rotated or expired model key makes every conversation fail at its first model call. The pre-defined [Consistent Error Pattern](/rius/platform/alerts/pre-defined#consistent-error-pattern) alert fires when the same error shows up at least 3 times across at least 2 runs within 5 minutes. Like Tool Loop, it reaches whatever [channels](/rius/platform/alerts/channels) you attach to it: ![The Consistent Error Pattern alert in Slack: AuthenticationError, API key is invalid, 3 occurrences across 3 runs](/assets/ui_openhands_slack_alert.png) ![The same alert as an email](/assets/ui_openhands_email_alert.png) To try it, run the example agent three times with a key that doesn't work. Each run exits 1, and its trace still reaches Rius: ```bash for i in 1 2 3; do LLM_API_KEY=sk-ant-invalid AGENT_NAME=openhands-key-rotated-demo .venv/bin/python run_agent.py done ``` With root-cause analysis on for the workspace, the firing names the invalid key as the cause: ![The root-cause analysis on a Consistent Error Pattern alert: the Anthropic API key is invalid](/assets/ui_openhands_error_pattern_rca.png) ## Query OpenHands traces from an MCP client With the [Rius MCP server](/rius/mcp) connected to Claude, Cursor or any MCP client, ask things like "show the last `openhands-stuck-demo` conversation and the command it kept running". The answer comes from the same spans. In Claude Code, the [Rius plugin](/rius/guides/claude-code-plugin) connects the MCP server for you. ## More in Rius The same OpenHands traces feed the rest of Rius: - [Usage and cost](/rius/platform/monitoring): cost, tokens and errors over time, broken down by model and agent. - [Exploring traces](/rius/platform/exploring-traces): find any conversation by agent, status, cost or error, and filter by span attributes. - [Agents](/rius/platform/agents): each OpenHands agent's failed traces, errors and cost on one page. - [Custom alerts](/rius/platform/alerts/custom): your own thresholds, for example average cost per conversation above $0.50 for one agent. - [MCP workflows](/rius/mcp/workflows): ready-made prompts for Claude or Cursor, such as what your agents cost this week and which one spends the most. ## Limits - **OpenHands Cloud** can't be pointed at Rius: it takes no custom environment variables. - **No token data** for OpenAI Responses API models (GPT-4.1, GPT-5) or for the web app's streamed calls. `lmnr` doesn't record usage there. Claude and GPT-4o in SDK scripts come through in full. - **Failed commands aren't error spans.** A non-zero exit code is in the tool output, not the span status, so error-rate alerts don't count it. ## Troubleshooting - **No traces at all.** Check the protocol (`http/protobuf`), the full `/v1/traces` path, and `%20` in the header. Then run `env | grep LMNR_`: it should print nothing. - **Web-app traces are missing.** The variables have to go in `OH_AGENT_SERVER_ENV`, not in `-e OTEL_...` on the app container. - **The agent name is a file path.** Start the script from its own directory, or set `agent.name`. ## Related - [Example repo](https://github.com/glassflow/openhands-rius): the SDK script, the scripted looping model and the web-app launcher. - [Pre-defined alerts](/rius/platform/alerts/pre-defined): what Tool Loop and the other detectors look for. - [Vanilla OTel SDKs](/rius/interoperability/otel-sdks): the same OTLP settings for any other framework. - [Claude Code plugin](/rius/guides/claude-code-plugin): trace Claude Code sessions the same way. --- # Multi-tenant agent observability: one workspace per customer You build agents and sell them: an agent product, an agency running agents per client, a platform with agent features. Each of your customers needs their telemetry isolated from every other customer's, and you need to see cost and health per customer. With Rius, you do that by treating each customer as its own workspace: the security and observability boundary for multi-tenant deployments. This guide is the opinionated way to set that up. **TL;DR:** Give every customer their own workspace. The workspace is the boundary Rius actually enforces, so isolation, per-customer cost, alerts, and customer-facing visibility all fall out of that one decision.
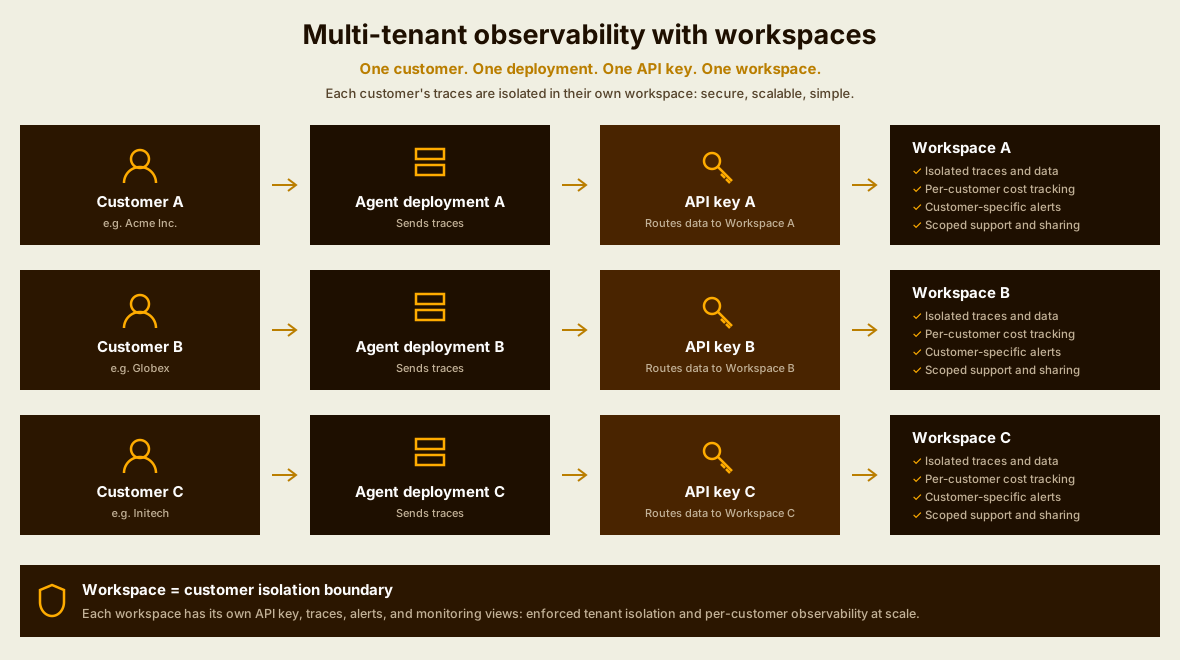
Workspace = customer isolation boundary: three customers, each with an agent deployment sending traces through its own API key into its own isolated Rius workspace with per-customer cost tracking, alerts, and scoped access
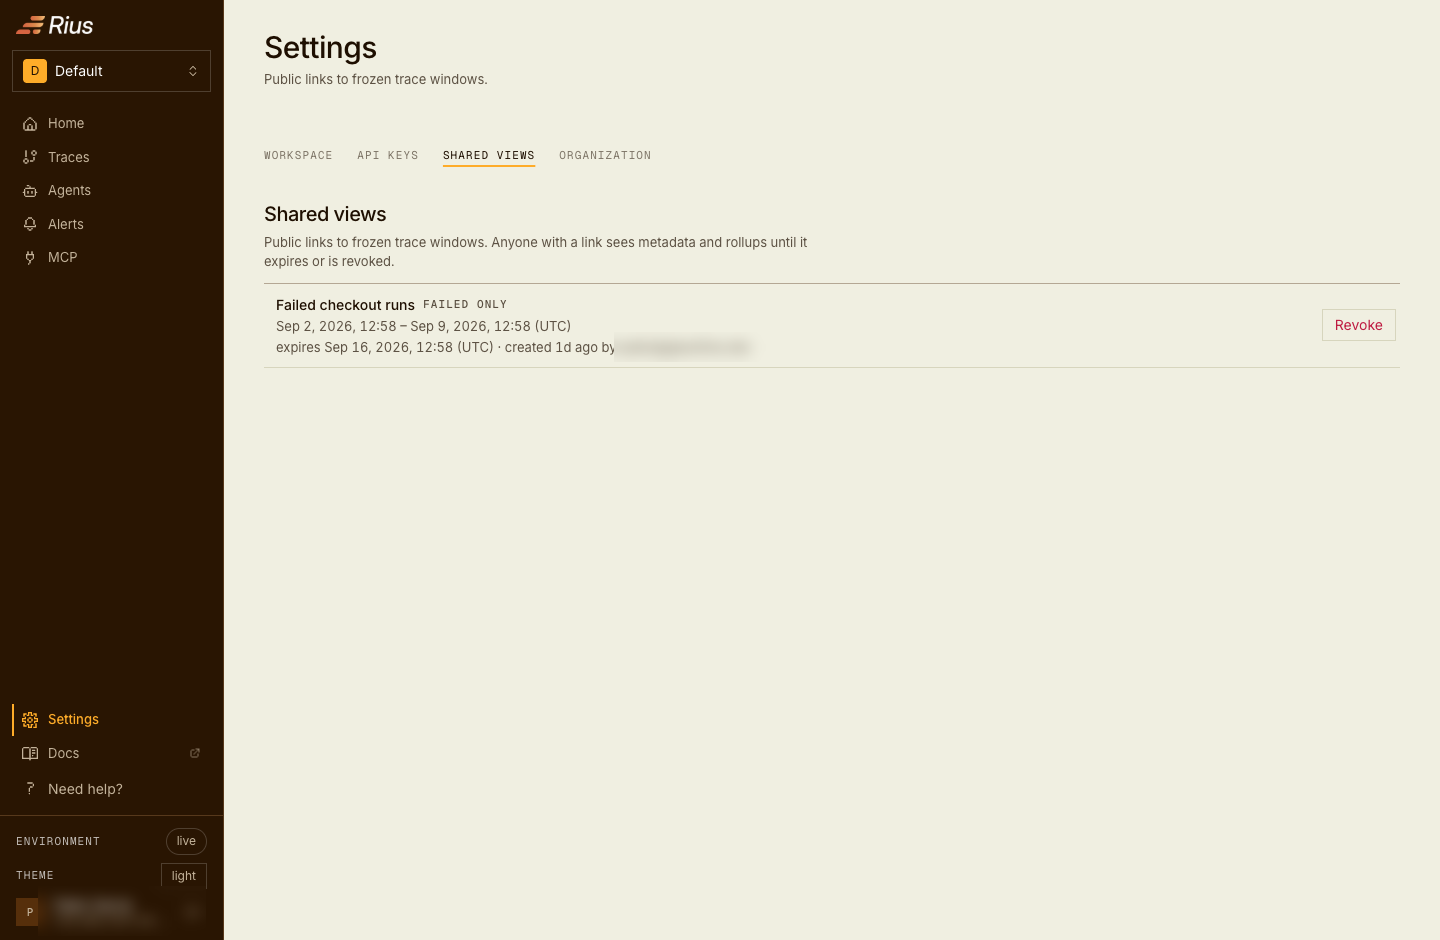
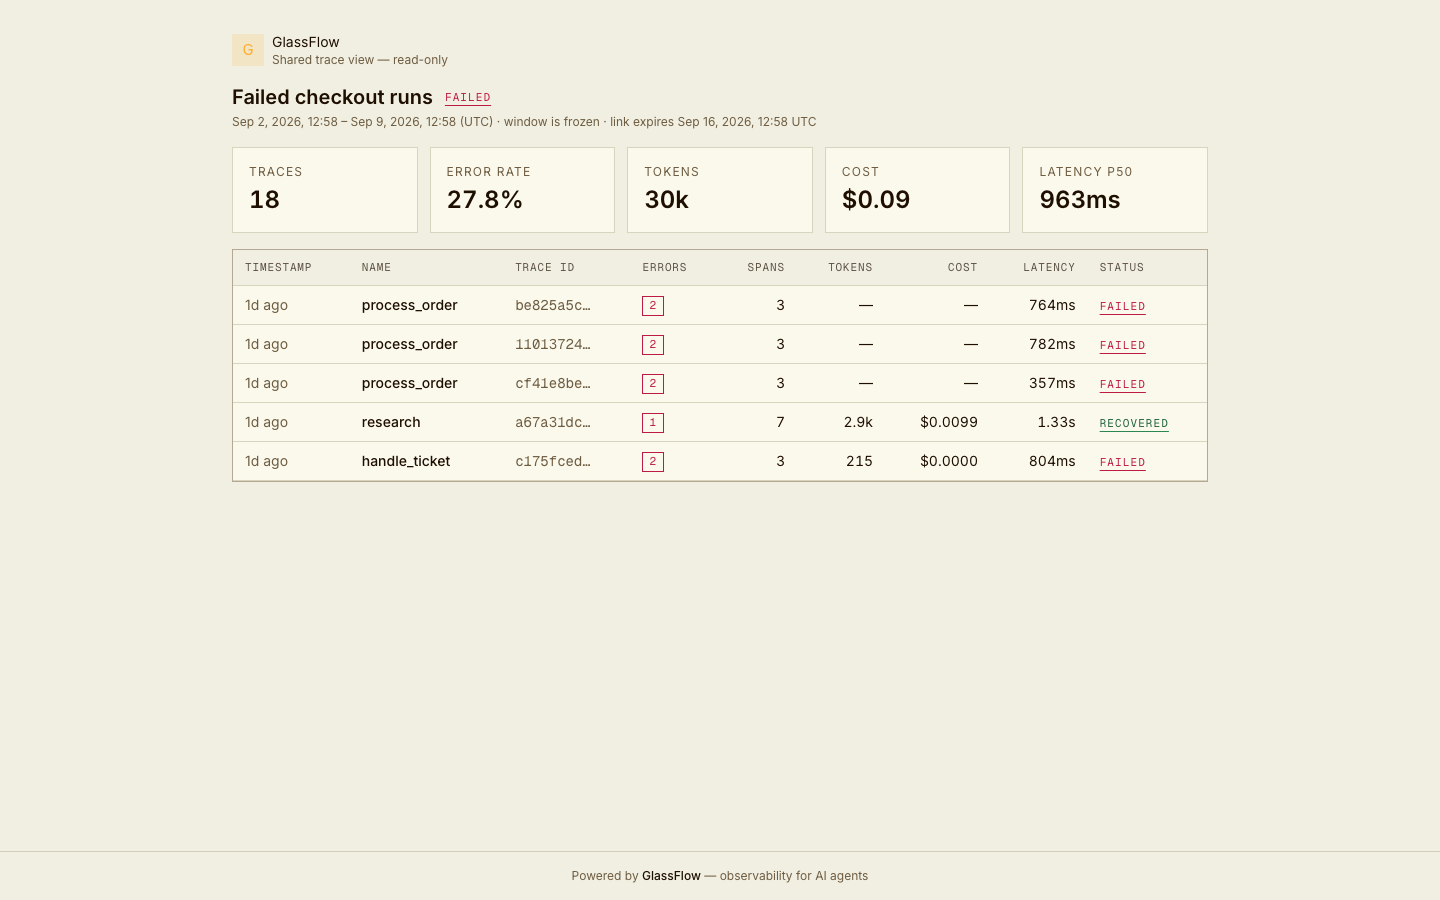
## The mapping | Your world | In Rius | | --- | --- | | You, the vendor | The [organization](/rius/platform/settings#organization-and-members) | | One of your customers | One workspace | | The agents you run for that customer | Agents (services) inside the workspace | | One conversation or task run | A [session](/rius/sdk/tracing#sessions) | | Your customer's end users | A `user_id` span attribute | ## Workspace-based tenant isolation For multi-tenant observability, treat each customer as a separate workspace: the workspace provides the isolation boundary for that customer's traces, cost, alerts, and support access. This pattern is not a naming convention; it lines up with what the platform enforces: - **Every trace belongs to exactly one workspace**, determined by the [API key](/rius/platform/settings#api-keys) it was sent with. The server derives the workspace from the verified key, never from anything the request claims. - **A leaked key exposes one customer, never the fleet.** Keys, MCP agent keys, alert settings, and shared views are all scoped per workspace. - **Per-customer cost needs no tagging discipline.** Token and cost rollups are per workspace, so "what does customer X cost us" is the workspace's own [monitoring view](/rius/platform/monitoring), not a query you have to maintain. There is no limit on the number of workspaces in an organization, so the pattern holds whether you have five customers or five hundred. ## When a single workspace is enough **A single workspace can work when customer isolation is not required.** You can identify customers with a `customer_id` span attribute (`span.set_attribute("customer_id", ...)`), but that gives you logical rather than enforced isolation. Be aware of what else you give up: attributes are stored and inspectable on traces, but they do not drive analytics, so there are no per-customer cost or error rollups; and one API key covers everyone. What each approach gets you: | | `customer_id` attribute | Workspace per customer | | --- | --- | --- | | Identify the customer on a trace | ✓ | ✓ | | Isolated API keys | ✗ | ✓ | | Per-customer cost rollups | ✗ | ✓ | | Per-customer alerts | ✗ | ✓ | | Scoped support access | ✗ | ✓ | | Customer-facing trace access | ✗ | ✓ | Teams that start with the attribute and grow tend to migrate to workspaces later, with a mixed history that straddles the cutover. If customers are your business model, start with the workspace pattern. ## Onboarding a customer Repeat this runbook for each new customer. The steps are in the console. 1. **Create the workspace.** From the workspace switcher at the top of the sidebar, choose **Create workspace…** (organization admins only). Name it after the customer and pick its region. 2. **Create its API key** in **Settings → API keys** inside the new workspace. The key is shown once; put it straight into your secret store, keyed by customer. 3. **Deploy the customer's agents with that key.** With one deployment per customer, configuration is two environment variables: ```bash export RIUS_API_KEY="ri_..." # this customer's workspace key export RIUS_SERVICE_NAME="support-agent" # the agent, same name across customers ``` Use the same service name for the same agent across customers: the workspace already says whose it is, and keeping names stable lets you compare the same agent's behavior between customers. 4. **Verify the first trace.** Run one task and check the workspace's trace list, the same check as the [quickstart](/rius/quickstart). 5. **Optional: connect support tooling.** Create an [MCP agent key](/rius/mcp) in the workspace so a coding agent or support engineer can query exactly that customer's traces and nothing else. ## Routing traces to the right workspace One key per workspace means each customer's traces must be sent with that customer's key. A shared runtime serving many customers does this with workspace scopes (`glassflow-rius` 0.13.0, `@glassflow-ai/rius` 0.4.0): register the keys once, then wrap each request in its customer's scope. ```python import rius rius.init( api_key=ops_key, # spans outside any scope go to your own workspace service_name="support-agent", workspaces={"acme": key_acme, "globex": key_globex}, ) with rius.workspace("acme"): handle(request) # every span of the request lands in acme's workspace ``` ```typescript init({ apiKey: opsKey, // spans outside any scope go to your own workspace serviceName: 'support-agent', workspaces: { acme: keyAcme, globex: keyGlobex }, }) await withWorkspace('acme', async () => { await handle(request) // every span of the request lands in acme's workspace }) ``` Everything started inside the scope routes together: `observe` wrappers, generations, sessions, and the spans auto-instrumentation creates, because the scope rides OpenTelemetry context the same way sessions do. For keys fetched at runtime (a new customer signs up, a key rotates), call `rius.register_workspace(alias, key)` / `registerWorkspace(alias, key)`; passing `workspaces={}` at init opts into routing with no static routes. Two rules to build around: - **One trace, one workspace.** The backend derives the workspace from the key, so a trace split across scopes would come apart. Enter the scope at the request boundary, before the root span starts; the SDK warns if a span starts under a different workspace than its parent. - **Instance liveness reports under your default workspace.** The [Agents view](/rius/platform/agents) heartbeat authenticates with the default key, so a shared runtime appears as one instance in your own workspace, not one per customer. The simpler shape remains available: **one process (or deployment) per customer**, each calling plain `init()` with the customer's key from an environment variable, as in the onboarding runbook above. If you already isolate customer runtimes for other reasons, that gives you routing with no scopes at all; workspace scopes are for when one runtime genuinely serves many customers. ## Operating per customer With customers as workspaces, the per-workspace surfaces become per-customer surfaces: - **Cost**: each workspace's [monitoring view](/rius/platform/monitoring) shows spend, cost by model, and token totals for that customer, the input to your own pricing. - **Alerts**: alerting is configured per workspace, so detection runs and fires per customer, and acknowledging one customer's alert never touches another's. - **Support access**: an MCP agent key per workspace scopes any tooling to one customer's traces. - **Customer-facing visibility**: [shared views](/rius/platform/settings#shared-views) hand a customer a read-only, frozen window of their own traces, optionally failed-only, with an expiry, and without a Rius account. A weekly shared view is a lightweight "here is how your agent behaved" report. ## Current limitations of workspace-based multi-tenancy Stated plainly, so you can plan around it: - **Provisioning is manual.** Workspaces and API keys are created in the console, so onboarding a customer is the runbook above. - **No cross-workspace rollup in the console.** You see one customer at a time; an organization-level usage view is planned as part of billing. Meanwhile, the [MCP server](/rius/mcp) can list your workspaces and fetch each one's metrics, which is enough to script a weekly all-customers summary. - **No per-customer end-user analytics.** A `user_id` span attribute is carried and inspectable per trace, but there are no per-user rollups. ## Next steps - [Settings](/rius/platform/settings): workspaces, API keys, and shared views in detail. - [Installation and configuration](/rius/sdk/installation): `init()`, environment variables, and scoped clients. - [Working with sessions](/rius/sdk/tracing#sessions): scoping one conversation or task run. - [MCP server](/rius/mcp): querying a workspace's traces from an agent. --- # Migrate from Langfuse to Rius Langfuse and Rius are both OpenTelemetry-based, which makes migrating from Langfuse mostly a routing change: your traces are already spans, and in many setups Rius can receive them without touching your instrumentation. This guide maps the concepts, walks the two migration paths, and ends with a cutover checklist. Run both backends in parallel during the evaluation; nothing here requires a hard switch. **TL;DR:** Migration is a routing change, not a re-instrumentation. Keep your setup and re-point your OTLP exporter (Path A), or swap the Langfuse SDK for the Rius SDK (Path B). Run both in parallel, then cut over. ## Why migrate from Langfuse to Rius Rius is agent observability built for long-running agents, so the same traces you send Langfuse today gain a live view of runs in progress, session grouping, and server-side cost, with an [MCP server](/rius/mcp) so your coding agent can query them. What Langfuse offers beyond tracing is covered honestly in [what does not carry over](#what-does-not-carry-over-from-langfuse). ## Concept mapping: Langfuse vs Rius | Langfuse | Rius | Notes | | --- | --- | --- | | Trace | Trace | Same OpenTelemetry trace, same tree view. | | Observation (span) | Span | The Rius SDK still names the handle `Observation`, so the terminology matches Langfuse. | | Observation (generation) | Generation | Same idea: a span with LLM semantics (model, tokens, cost). Rius reads OTel GenAI `gen_ai.*` attributes. | | Session | Session | Group traces into a conversation or task. | | User (`user_id`) | Span attribute | No native user dimension today. Set `user_id` as a span attribute; it is stored and inspectable on the trace, but does not drive analytics. | | Scores | Not available | See [what does not carry over](#what-does-not-carry-over-from-langfuse). | | Prompt management | Not available | See [what does not carry over](#what-does-not-carry-over-from-langfuse). | | Datasets and evals | Not available | See [what does not carry over](#what-does-not-carry-over-from-langfuse). | ## Choose your path - **You send OTLP to Langfuse** (OpenLLMetry, OpenInference, a vanilla OTel SDK, or a Collector pointing at Langfuse's OTLP endpoint): keep your instrumentation and [re-point the exporter](#path-a-keep-your-instrumentation-re-point-the-otlp-exporter). - **You use the Langfuse SDK** (`@observe`, `start_as_current_observation`): [swap to the Rius SDK](#path-b-swap-the-langfuse-sdk-for-the-rius-sdk). The APIs are close relatives, the swap is mechanical. ## Path A: keep your instrumentation (re-point the OTLP exporter) Langfuse's OTLP endpoint authenticates with Basic auth built from your public and secret keys. Rius takes a single API key as a Bearer token, and the endpoint is plain OTLP/HTTP: ```bash # Before: pointing at Langfuse export OTEL_EXPORTER_OTLP_ENDPOINT="https://cloud.langfuse.com/api/public/otel" export OTEL_EXPORTER_OTLP_HEADERS="Authorization=Basic " # After: pointing at Rius export OTEL_EXPORTER_OTLP_ENDPOINT="https://ingest.eu.console.rius-glassflow.com" export OTEL_EXPORTER_OTLP_PROTOCOL="http/protobuf" export OTEL_EXPORTER_OTLP_HEADERS="authorization=Bearer " ``` That is the whole change. Instrumentation-specific setup lives on the existing pages, use the one that matches yours: - [OpenLLMetry](/rius/interoperability/openllmetry) (Traceloop SDK) - [OpenInference](/rius/interoperability/openinference) (Arize instrumentors) - [Vanilla OTel SDKs](/rius/interoperability/otel-sdks) for any language What analytics you get depends on the attribute convention your instrumentation emits; check the [supported-conventions matrix](/rius/interoperability/attributes#supported-conventions). Recent OpenLLMetry and OpenInference releases emit `gen_ai.*` attributes and get full model and cost analytics. ### Side by side through a Collector For an evaluation period, keep sending to Langfuse and add Rius as a second exporter. If you already route through an OpenTelemetry Collector this is one list entry: ```yaml exporters: otlphttp/langfuse: endpoint: https://cloud.langfuse.com/api/public/otel headers: authorization: Basic ${env:LANGFUSE_BASIC_AUTH} otlphttp/rius: endpoint: https://ingest.eu.console.rius-glassflow.com encoding: proto compression: gzip headers: authorization: Bearer ${env:RIUS_API_KEY} service: pipelines: traces: receivers: [otlp] processors: [batch] exporters: [otlphttp/langfuse, otlphttp/rius] ``` Both backends now see identical spans, so you can compare trace trees, token counts, and cost on the same traffic before deciding. The [Collector page](/rius/interoperability/collector) covers the exporter details, including why it must be `otlphttp` and not `otlp`. No Collector in your stack? Adding one just for the evaluation is a small, reversible step: run it as a sidecar or single deployment, point your app's OTLP exporter at it, and fan out from there. Remove it after cutover or keep it as your single egress point. ## Path B: swap the Langfuse SDK for the Rius SDK For code instrumented with the Langfuse SDK, the Rius SDK ([Python and TypeScript](/rius/sdk)) has the same shape: a decorator for functions, context managers for spans and generations, and a session scope. | Langfuse (Python) | Rius (Python) | | --- | --- | | `Langfuse(public_key=..., secret_key=..., base_url=...)` / `get_client()` | `rius.init(api_key="ri_...", service_name="my-agent")` | | `@observe()` | `@rius.observe` | | `@observe(capture_input=False)` | `@rius.observe(capture_input=False)` | | `@observe(as_type="generation")` | Use `rius.start_as_current_generation(...)` inside the function; the decorator has no generation mode. | | `start_as_current_observation(as_type="span", name=...)` | `rius.start_as_current_span(name)` | | `start_as_current_observation(as_type="generation", model=...)` | `rius.start_as_current_generation(model=..., provider=...)`; the name is optional and defaults to `chat ` | | `span.update(input=..., output=...)` | `span.set_input(...)` / `span.set_output(...)` | | `gen.update(usage_details={"input_tokens": i, "output_tokens": o})` | `gen.set_usage(input_tokens=i, output_tokens=o)` | | `propagate_attributes(session_id=...)` | `with rius.session(session_id):` | | `propagate_attributes(user_id=...)` | `with rius.user(user_id):`, which stamps `user.id` on every span in scope. | A generation, before and after: ```python # Langfuse with langfuse.start_as_current_observation( as_type="generation", name="chat gpt-4o", model="gpt-4o", ) as gen: response = client.chat.completions.create(model="gpt-4o", messages=messages) gen.update( output=response.choices[0].message.content, usage_details={ "input_tokens": response.usage.prompt_tokens, "output_tokens": response.usage.completion_tokens, }, ) ``` ```python # Rius with rius.start_as_current_generation( "chat gpt-4o", model="gpt-4o", provider="openai", ) as gen: gen.set_input(messages) response = client.chat.completions.create(model="gpt-4o", messages=messages) gen.set_output(response.choices[0].message.content) gen.set_usage( input_tokens=response.usage.prompt_tokens, output_tokens=response.usage.completion_tokens, ) ``` Two differences worth knowing before you start: - **Auth and config**: one `RIUS_API_KEY` replaces the Langfuse key pair, and the endpoint defaults to EU ingest so most setups configure nothing else. See [installation](/rius/sdk/installation). - **Instrumentation is automatic where possible**: if you call OpenAI, Anthropic, or another [supported library](/rius/sdk/integrations), `rius.init()` instruments it and you may not need manual generations at all. Check the integrations list before porting generation blocks one by one. The full API surface, including manual (non-context-manager) span control, is in the [tracing guide](/rius/sdk/tracing) and the [SDK reference](/rius/sdk/reference/python). ## What does not carry over from Langfuse Rius is an agent observability platform, not a Langfuse clone, and today it has no equivalent for: - **Scores**: no score objects on traces or observations, and no annotation queues. - **Evals**: no LLM-as-judge or eval runs. If you run evals through Langfuse today, keep that workflow there or in a dedicated eval tool during the transition. - **Prompt management**: no versioned prompts or prompt deployment. Prompt content on spans is captured and inspectable, but there is no registry. - **User-level analytics**: no native `user_id` dimension. A `user_id` span attribute is carried over and visible in trace inspection, but there are no per-user views or rollups. What you keep, and in some places gain: trace inspection, sessions, token and server-side cost analytics, a live view of running [agents](/rius/concepts) including long-running ones, and an [MCP server](/rius/mcp) so your coding agent can query production traces. If scores, evals, or prompt management are load-bearing in your workflow, run the side-by-side setup and keep Langfuse for those pieces rather than cutting over completely. Traces are cheap to duplicate; workflows are not. ## Langfuse to Rius cutover checklist 1. Create a Rius workspace and API key ([quickstart](/rius/quickstart)). 2. Pick your path: [re-point OTLP](#path-a-keep-your-instrumentation-re-point-the-otlp-exporter) or [swap the SDK](#path-b-swap-the-langfuse-sdk-for-the-rius-sdk). 3. Start with fan-out, not a switch: send the same traces to both backends ([Collector fan-out](#side-by-side-through-a-collector)), or run the swapped SDK in one service while the rest still report to Langfuse. 4. Verify one traced request end to end: the trace tree looks right, the generation shows model and token counts, and cost appears. If analytics fields are empty, check your attribute convention against the [matrix](/rius/interoperability/attributes#supported-conventions). 5. Compare both backends on real traffic for a few days: trace counts, token totals, cost. 6. Move anything that reads from Langfuse (dashboards, alerts, internal tools) to their Rius equivalents, or deliberately leave them behind. 7. Remove the Langfuse exporter or SDK, and revoke the Langfuse keys once nothing sends to them. ## Frequently asked questions
Do I have to re-instrument my code to migrate from Langfuse? No. Because both are OpenTelemetry-based, in most setups you re-point your OTLP exporter to Rius and your existing spans arrive unchanged.
Can I run Langfuse and Rius at the same time? Yes. Add Rius as a second exporter and fan out to both during evaluation. The migration is reversible until you revoke your Langfuse keys.
Is Rius compatible with the Langfuse SDK? Not directly. You cannot point the Langfuse SDK at Rius, because its exporter and auth are Langfuse's own. The Rius SDK mirrors the Langfuse SDK's shape (decorators, context managers, sessions), so swapping one for the other is rather mechanical.
--- # Concepts The Rius data model in one page: what a trace is, what spans and generations are made of, and which parts the platform computes for you. ## The model at a glance Five nouns cover everything Rius shows you: - An **agent** is the program you built and named, like `support-agent`. It is the unit you monitor: health, cost, errors. - An **instance** is one running copy of an agent. Run three replicas and you have three instances; every process start (or restart) mints a fresh instance id. Instances are what heartbeats track. - A **trace** is one complete unit of work an agent did, from request to answer, with a duration and a status. - A **span** is one step inside a trace: a model call, a tool call, a retrieval. A trace is the tree of its spans. - A **session** is one conversation or job as your users see it. You assign the id, and it groups traces across turns. An agent runs as one or more instances; each instance produces traces made of spans. Sessions cut across that hierarchy: one instance serves many sessions over its lifetime, and one session can be served by several instances, so the two relate only through the traces they share. Typical proportions, for scale: an agent with 3 instances might see hundreds of sessions, thousands of traces, and tens of thousands of spans in a day. The rest of this page defines each part precisely, from traces down. ## Traces A **trace** is one end-to-end agent run. It begins when your agent starts handling a piece of work (a request, a job, a conversation turn) and ends when that work is done. Everything the run did along the way lives inside the trace, so the trace list is effectively a list of agent runs. Every trace has exactly one **root span**. The root's name, duration, and status are what run-level views show: a failed root means a failed run, the root's duration is the run's latency. Traces belong to exactly one [workspace](/rius/platform/settings), determined by the API key they were sent with, and are grouped by the `service.name` your SDK or exporter sets. ## Spans A **span** is one step inside a run: a tool call, a retrieval, a chain stage, an LLM call. Spans nest the standard OpenTelemetry way (parent context), which is what produces the waterfall. Each span carries a **kind** that classifies it in trace views and per-kind analytics: | Kind | Meaning | |---|---| | `AGENT` | An agent invocation or run | | `LLM` | A model call (generations use this) | | `TOOL` | A tool execution | | `RETRIEVER` | A retrieval or search step | | `EMBEDDING` | An embedding computation | | `CHAIN` | A generic processing step (the default) | On the wire the kind is the `openinference.span.kind` attribute, paired with the OpenTelemetry GenAI operation (`gen_ai.operation.name`: `chat`, `execute_tool`, `invoke_agent`, and so on). The SDKs set both, from their `kind=` arguments and on auto-instrumented spans, and the platform derives whichever one a third-party span leaves out. Spans are named after their operation and what it acted on, such as `execute_tool get_weather`, unless you name them yourself. Exceptions are recorded as standard OpenTelemetry span events and, in the SDK's scoped forms, give the span ERROR status and an `error.type`; the waterfall highlights the path from the root to the failing span. ## Partial spans A span normally leaves your process exactly once, when it ends. That is fine for work that finishes in a second, and poor for an agent: while a run is in flight there is nothing to look at, and if the process dies mid-run the span is never exported at all, so the run you most want to see is the one that leaves no trace. **Partial spans** fix that by exporting a second, content-free copy of every sampled span at the moment it *starts*. The platform stores that snapshot as an unfinished span, and the real span replaces it on completion. The replacement is silent: the two carry the same trace id, span id and start time, which is the identity the storage layer matches on, so a finished run looks exactly as it would have without the feature. What makes them worth enabling is the snapshot that never gets replaced. A process that crashes, is OOM-killed, or is shut down mid-run leaves its snapshot behind, and that snapshot is the durable record of what the agent was doing when it died. A snapshot carries identity and taxonomy only, never content, whatever your instrumentation recorded. Inputs, outputs and prompts appear when the real span lands. That is deliberate: a pending span is a "this is happening" signal, not an early peek at data. Trace status follows from this directly. A trace whose spans have all ended reads as `completed`, or `failed` if any span errored; a trace with a span still open reads as **running…** (the filter value is `incomplete`). [Exploring traces](/rius/platform/exploring-traces#trace-status) has the full status semantics, and partial spans are off by default: see [export behavior](/rius/sdk/reliability#partial-spans) for the two settings and what they cost. ## Generations A **generation** is an LLM span with model semantics: the requested and response model, the provider, token usage, request parameters, finish reasons, and optionally the input and output messages. On the wire these are OpenTelemetry GenAI (`gen_ai.*`) attributes; in the console they power the span's **Model** section and the model analytics. Wherever the console and alerts count **LLM calls**, they count inference calls: spans of kind `LLM`. An agent or tool span is never an LLM call, even when it carries the model its agent uses, and an embedding call is not one either, although its tokens and cost still count toward the totals. For streamed calls, a generation can carry a `gen_ai.first_token` span event marking the moment the first chunk arrived. Time to first token is derived from it, which is the latency number streaming users actually feel. ## Sessions A **session** groups the traces of one conversation or job. Where a trace is a causal unit and stays short, a session is a correlation unit your application assigns, open ended and spanning turns: each turn of a chat is its own trace, and the session is what ties them together. Because the grouping rides on traces, a session is independent of the process serving it: a conversation that outlives a deploy or moves between replicas stays one session. The application mints the id and the SDK stamps it as the `session.id` attribute on every span in scope, so a session can correlate with an id you already have, such as a conversation id or a job id. [Tracing your code](/rius/sdk/tracing#sessions) shows the two ways to set it, per scope or process-wide. A trace without a session id is grouped as its own single-trace session. That keeps ungrouped traces visible, and it has a reading worth knowing: when an agent's session count equals its trace count, nothing is setting `session.id`, and those sessions are not meaningful groupings. ## Users A **user** is the person a request served. Sessions group the turns of one conversation; the user is the identity that persists across conversations, agents, and days, which is what lets you answer "what happened to this person" rather than "what happened in this chat". The application supplies the identifier and the SDK stamps it as the `user.id` attribute on every span in scope. That key is the one OpenInference defines and the OpenTelemetry registry lists, so traces from other instrumentations carry it the same way; the platform also reads OpenTelemetry's `enduser.id` and `enduser.pseudo.id` from third-party spans. [Tracing your code](/rius/sdk/tracing#users) shows how to set it. A span with no user is anonymous, not a member of some synthetic user: unlike sessions, nothing falls back to the trace. Prefer an opaque id over an email, since the value is stored on every span and shown in the console. ## Content and metadata Span data splits into two families with different privacy treatment: - **Content**: prompts, completions, tool arguments and results (`gen_ai.input.messages`, `gen_ai.output.messages`, `input.value`, `output.value`). Content is what the **Input / Output** tab renders, and it is what the SDK's [privacy controls](/rius/sdk/advanced#privacy-controls) strip or mask at export time. - **Metadata**: everything else, including names, timings, kinds, models, token counts, and statuses. Metadata always flows, so a span with stripped content still gets full timing, token, and cost analytics. ## Computed server-side Two things you never send because the platform derives them: - **Cost** is computed from `gen_ai.request.model` plus the two `gen_ai.usage.*` token counts, using model pricing maintained server-side. Send token usage, never cost; your instrumentation stays free of pricing tables. - **Time to first token** is derived from the `gen_ai.first_token` event's timestamp minus the span start. ## Agent instances and liveness Traces tell you what an agent did, [partial spans](#partial-spans) tell you what it is doing right now, and heartbeats tell you whether the process is alive at all. With the heartbeat enabled, every instrumented process pings the platform on a fixed interval for its whole lifetime, and each process is one **instance** with a fresh identity per start. Instances group under an **agent name** (by default the service name; see [Naming your agent](/rius/sdk/installation#naming-your-agent)), so three replicas of one agent show as three instances under one name. The same instance id also rides every span the process exports, as the `service.instance.id` resource attribute. That is the join between the two halves of the model: from an instance you can find the traces it produced, and from a trace you can tell which process ran it, including one that is no longer alive. Liveness is another server-side computation: the platform classifies each instance from its last ping (`running`, `ready`, `stale`, `gone`, `stopped`) and never trusts the client's clock or claims. The distinction doing the real work is `stopped` versus `gone`: a clean shutdown announces itself with a final ping, so an instance that just vanishes reads as a crash. [Monitoring live agents](/rius/platform/agents) has the full status semantics. ## Convention-native by design The model above is not a proprietary schema. Rius reads established OpenTelemetry conventions directly (OTel GenAI for generations, OpenInference for span kinds and generic I/O), so traces from third-party instrumentation land with the same analytics as SDK-emitted ones. The [span attribute reference](/rius/interoperability/attributes) is the full wire contract. ## Next steps - [Tracing your code](/rius/sdk/tracing): tracing functions with `observe`, spans, and generations in the SDK. - [Span attribute reference](/rius/interoperability/attributes): every attribute the platform reads, for sending without the SDK. - [Exploring traces](/rius/platform/exploring-traces): the trace list, waterfall, and span detail in the console. - [Monitoring live agents](/rius/platform/agents): instances, heartbeats, and the full status semantics. --- # SDK The Rius SDK is OpenTelemetry-native tracing for AI agents: non-blocking by design, privacy-aware at export time, and speaking the OpenTelemetry GenAI conventions. **Python** ships as `glassflow-rius` and **TypeScript** as `@glassflow-ai/rius`; every page here shows both side by side. Because the SDK emits standard OpenTelemetry, any other language can send traces through [interoperability](/rius/interoperability) without a native SDK. ```bash pip install glassflow-rius ``` ```python import rius rius.init(api_key="ri_...", service_name="my-agent") @rius.observe def handle(query: str) -> str: ... ``` ```bash npm install @glassflow-ai/rius @opentelemetry/api ``` ```typescript init({ apiKey: 'ri_...', serviceName: 'my-agent' }) // A named function expression, so the span is named "handle". export const handle = observe(async function handle(query: string) { return await callModel(query) }) ``` ## Find what you need | Task | Go to | |---|---| | Trace a function with one line | [`observe`](/rius/sdk/tracing#tracing-functions-with-observe) | | Record an LLM call with model, tokens, and cost | [Generations](/rius/sdk/tracing#generations-llm-calls) | | Measure time to first token when streaming | [Streaming responses](/rius/sdk/tracing#streaming-responses) | | Group the traces of one conversation or job | [Sessions](/rius/sdk/tracing#sessions) | | Attribute every span of a request to the person it served | [Users](/rius/sdk/tracing#users) | | Name tool, agent, and retrieval spans and link tool calls | [Span names and identity](/rius/sdk/tracing#span-names-and-identity) | | Serve several customers' workspaces from one process | [Workspace scopes](/rius/sdk/tracing#workspace-scopes) | | Instrument OpenAI, Anthropic, LangChain, ... automatically | [Integrations](/rius/sdk/integrations) | | Set the API key, endpoint, or any option | [Configuration](/rius/sdk/installation#configuration-reference) | | Keep long agent spans from losing attributes | [Span attribute limit](/rius/sdk/installation#span-attribute-limit) | | Reduce trace volume in production | [Sampling](/rius/sdk/advanced#sampling) | | Keep prompts or PII from leaving my process | [Privacy controls](/rius/sdk/advanced#privacy-controls) | | Flush traces in a Lambda, CLI, or batch job | [Short-lived processes](/rius/sdk/reliability#short-lived-processes) | | Find out why traces are not appearing | [Troubleshooting](/rius/sdk/troubleshooting) | | Move a 0.x integration to 1.0 | [Upgrading to 1.0](/rius/sdk/upgrading) | | Look up a signature | [Python reference](/rius/sdk/reference/python), [TypeScript reference](/rius/sdk/reference/typescript) | Both references are generated from the SDKs' doc comments, so they always match the pinned release of each package. --- # Installation and configuration The Rius SDK for Python is published as `glassflow-rius` and imported as `rius`; it requires Python 3.10 or newer. The TypeScript SDK is published as `@glassflow-ai/rius` and requires Node 18 or newer. ```bash pip install glassflow-rius ``` To auto-instrument the LLM libraries you use, install their extras (see [Integrations](/rius/sdk/integrations)): ```bash pip install "glassflow-rius[openai]" # one library pip install "glassflow-rius[instruments]" # everything ``` ```bash npm install @glassflow-ai/rius @opentelemetry/api ``` `@opentelemetry/api` is a peer dependency and is never bundled, so install it alongside the SDK at a version satisfying `^1.9.0`. Node 18 or newer is required. Integrations ship as optional peer dependencies rather than extras: install the packages you use and `init()` enables whatever it finds (see [Integrations](/rius/sdk/integrations)). ```bash npm install @arizeai/openinference-instrumentation-openai # OpenAI npm install @modelcontextprotocol/sdk # MCP tool calls npm install @arizeai/openinference-vercel @ai-sdk/otel # Vercel AI SDK ``` An extra installs the **instrumentation for** a library, never the library itself: `glassflow-rius[anthropic]` brings in the Anthropic instrumentation and expects `anthropic` to already be in your environment, which it is in any project that calls Anthropic. Rius deliberately does not depend on provider SDKs, so it never pins or upgrades the versions your code runs against. If an extra is installed without its library, `init()` logs a `DependencyConflict` from OpenTelemetry and that integration stays off; see [Troubleshooting](/rius/sdk/troubleshooting#init-logs-a-dependencyconflict). MCP needs no extra: Rius instruments it directly rather than through a separate package, so that integration turns itself on whenever `mcp` is importable. ## Initializing Call `init()` once, as early as possible in your process: ```python import rius client = rius.init( api_key="ri_...", service_name="my-agent", ) ``` ```typescript const client = init({ apiKey: 'ri_...', serviceName: 'my-agent', }) // init() is synchronous. Auto-instrumentation attaches asynchronously, so await // `ready` if you need it in place before your first span. It resolves with the // names that attached, and never rejects. const attached = await client.ready ``` Every argument is optional and can also come from an environment variable. Explicit arguments win over environment variables, which win over defaults. ## Naming your agent Set `service_name` (`RIUS_SERVICE_NAME`) explicitly. It is the `service.name` resource attribute stamped on every span and how you find your agent in trace filters, analytics, and cost breakdowns. It defaults to `unknown_service`. Optionally set `agent_name` (`RIUS_AGENT_NAME`) to control how instances group in the [Agents view](/rius/platform/agents). It defaults to `service_name`; set it separately only when several services form one logical agent. Keep the name constant across replicas and deploys. Each process start is a fresh **instance** under the same name, so three replicas show as three instances of one agent. Keep version numbers out of the name and put them where they belong instead: - `service_version` (`RIUS_SERVICE_VERSION`) is the build or release this process runs, stamped as `service.version`. Unset, it falls back to a `service.version` in `OTEL_RESOURCE_ATTRIBUTES`, and otherwise the attribute is left off rather than filled with a placeholder. - `main_agent_version` (`RIUS_MAIN_AGENT_VERSION`) is the version of the agent definition, meaning its prompt, tools, and policy, stamped as `rius.main_agent.version`. It moves independently of the build, so the SDK never derives one from the other. Two more optional identity settings describe the agent itself: `main_agent_id` (`RIUS_MAIN_AGENT_ID`) is a stable identifier such as a registry id, and `main_agent_description` (`RIUS_MAIN_AGENT_DESCRIPTION`) says what the agent does. Use an id that survives restarts and deploys: an id minted at process start would turn every restart into a new agent, and `service.instance.id` already identifies the process. Renaming does not re-key history: stored spans keep the old `service.name` and stay filterable under it, while the new name starts empty. In the Agents view the old name's instances report `gone` and linger until their heartbeat records are garbage-collected. Treat the name as an identifier, not a label. ## Configuration reference | Argument | Environment variable | Default | What it does | |---|---|---|---| | `endpoint` | `RIUS_ENDPOINT` | `https://ingest.eu.console.rius-glassflow.com` | Base OTLP endpoint. Traces post to `{endpoint}/v1/traces`. | | `api_key` | `RIUS_API_KEY` | `None` | Sent as `Authorization: Bearer `. If you pass your own `Authorization` header via `headers`, it wins. `None` is valid for OTLP backends that need no auth. | | `service_name` | `RIUS_SERVICE_NAME` | `unknown_service` | The `service.name` resource attribute on every span. Set it; it is how you find your agent later. See [Naming your agent](#naming-your-agent). | | `service_version` | `RIUS_SERVICE_VERSION` | `None` | The `service.version` resource attribute, for example your release or image tag. Unset, a `service.version` in `OTEL_RESOURCE_ATTRIBUTES` applies; otherwise the attribute is omitted. | | `headers` | none | `{}` | Extra headers for the exporter. | | `disabled` | `RIUS_DISABLED` | `False` | Kill switch. When true, no exporter is attached and spans are dropped in-process. | | `sample_rate` | `RIUS_SAMPLE_RATE` | `1.0` | Head sampling rate for root traces. See [Sampling](/rius/sdk/advanced#sampling). | | `capture_content` | `RIUS_CAPTURE_CONTENT` | `True` | When false, prompt and response content is stripped at export; metadata still flows. See [Privacy controls](/rius/sdk/advanced#privacy-controls). | | `mask` | none | `None` | Redaction callable applied to content attributes at export. See [Privacy controls](/rius/sdk/advanced#privacy-controls). | | `instruments` | none | `None` | Which integrations to enable: `None` enables all installed, `[]` disables, `["openai"]` restricts. See [Integrations](/rius/sdk/integrations). | | `span_exporter` | none | `None` | Override the OTLP exporter (mostly for tests). | | `heartbeat` | `RIUS_HEARTBEAT` | `True` | The agent-lifetime heartbeat thread: pings `{endpoint}/v1/heartbeat` from `init()` until process exit, powering the [Agents view](/rius/platform/agents). On by default since 0.10.0; set `False` (or `RIUS_HEARTBEAT=false`) to opt out. Delivery semantics in [Reliability](/rius/sdk/reliability#heartbeat-delivery). | | `heartbeat_interval` | `RIUS_HEARTBEAT_INTERVAL` | `15` | Seconds between pings, clamped to 5-300. Staleness detection derives from it, so a slower interval also slows `stale`/`gone` detection. | | `agent_name` | `RIUS_AGENT_NAME` | `service_name` | The identity heartbeat instances and spans group under in the Agents view, stamped on the resource as `rius.main_agent.name` and `gen_ai.agent.name`. Set it when several services are one logical agent. See [Naming your agent](#naming-your-agent). | | `main_agent_id` | `RIUS_MAIN_AGENT_ID` | `None` | A stable identifier for the agent this process runs, stamped as `rius.main_agent.id`. Never a per-process id. | | `main_agent_description` | `RIUS_MAIN_AGENT_DESCRIPTION` | `None` | What the agent does, stamped as `rius.main_agent.description`. | | `main_agent_version` | `RIUS_MAIN_AGENT_VERSION` | `None` | The version of the agent definition (prompt, tools, policy), stamped as `rius.main_agent.version`. Independent of `service_version`. | | `heartbeat_transport` | none | `None` | Override the heartbeat HTTP transport (mostly for tests, like `span_exporter`). | | `partial_spans` | `RIUS_PARTIAL_SPANS` | `False` | Export a content-free snapshot of every span at start, so in-flight and crashed work is visible. See [Partial spans](/rius/sdk/reliability#partial-spans). | | `partial_spans_delay` | `RIUS_PARTIAL_SPANS_DELAY` | `0.0` | Seconds to hold a snapshot before sending it, clamped to 0-60. A span that finishes within the delay sends no snapshot at all. | | `session_id` | `RIUS_SESSION_ID` | `None` | Process-wide `session.id` for every span, for an agent that handles one session per process. A [session scope](/rius/sdk/tracing#sessions) overrides it; do not set it in a server handling many users. | | `bridge_foreign_provider` | `RIUS_BRIDGE_FOREIGN_PROVIDER` | `False` | When another OpenTelemetry SDK (Langfuse, Traceloop, Logfire, MLflow, OpenLIT, Laminar) already owns the global tracer provider, also send that provider's spans to Rius, so your LLM calls keep their parents. Spans whose parent Rius never received are flagged `rius.parent.foreign` either way. | | `workspaces` | none | `None` | Multi-workspace routing: a mapping of alias to API key. Spans inside `rius.workspace(alias)` export with that workspace's key; `{}` opts in with routes added later via `register_workspace()`. See [routing traces to the right workspace](/rius/guides/multi-tenant-observability#routing-traces-to-the-right-workspace). | | `workspace_exporter_factory` | none | `None` | Override how per-workspace exporters are built from an API key (mostly for tests, like `span_exporter`). | | `set_global` | none | `True` | Register the provider as the global OpenTelemetry provider. | Boolean environment variables accept `1`, `true`, `yes`, or `on` in any case. Out-of-range `sample_rate` values are clamped to `[0.0, 1.0]` with a warning. Only the `RIUS_*` names are read. Releases before 1.0.0 also accepted the older `GLASSFLOW_*` spellings with a deprecation warning; from 1.0.0 those are ignored, so rename any that remain in your environment. Option names are camelCase, and every environment variable uses the `RIUS_` prefix. | Option | Environment variable | Default | What it does | |---|---|---|---| | `endpoint` | `RIUS_ENDPOINT` | `https://ingest.eu.console.rius-glassflow.com` | Base OTLP endpoint. Traces post to `{endpoint}/v1/traces`. Trailing slashes are trimmed. | | `apiKey` | `RIUS_API_KEY` | none | Sent as `Authorization: Bearer `. Leaving it unset is valid for OTLP backends that need no auth. | | `serviceName` | `RIUS_SERVICE_NAME` | `unknown_service` | The `service.name` resource attribute on every span. Set it; it is how you find your agent later. See [Naming your agent](#naming-your-agent). | | `serviceVersion` | `RIUS_SERVICE_VERSION` | none | The `service.version` resource attribute, for example your release or image tag. Unset, a `service.version` in `OTEL_RESOURCE_ATTRIBUTES` applies; otherwise the attribute is omitted. | | `disabled` | `RIUS_DISABLED` | `false` | Kill switch. No exporter is attached, no optional integration is imported, and `client.ready` resolves to `[]`. | | `sampleRate` | `RIUS_SAMPLE_RATE` | `1.0` | Head sampling rate for root traces. See [Sampling](/rius/sdk/advanced#sampling). | | `captureContent` | `RIUS_CAPTURE_CONTENT` | `true` | When false, content attributes are stripped at export; metadata still flows. See [Privacy controls](/rius/sdk/advanced#privacy-controls). | | `mask` | none | none | Redaction callback applied to content attributes at export. See [Privacy controls](/rius/sdk/advanced#privacy-controls). | | `spanExporter` | none | none | Override the OTLP exporter (mostly for tests). | | `heartbeat` | `RIUS_HEARTBEAT` | `true` | The agent-lifetime heartbeat: pings `{endpoint}/v1/heartbeat` from `init()` for the life of the process, powering the [Agents view](/rius/platform/agents). Set `false` (or `RIUS_HEARTBEAT=false`) to opt out. Delivery semantics in [Reliability](/rius/sdk/reliability#heartbeat-delivery). | | `heartbeatInterval` | `RIUS_HEARTBEAT_INTERVAL` | `15` | Seconds between pings, clamped to 5-300. Staleness detection derives from it, so a slower interval also slows `stale` and `gone` detection. | | `agentName` | `RIUS_AGENT_NAME` | `serviceName` | The identity heartbeat instances and spans group under in the Agents view, stamped on the resource as `rius.main_agent.name` and `gen_ai.agent.name`. Set it when several services are one logical agent. See [Naming your agent](#naming-your-agent). | | `mainAgentId` | `RIUS_MAIN_AGENT_ID` | none | A stable identifier for the agent this process runs, stamped as `rius.main_agent.id`. Never a per-process id. | | `mainAgentDescription` | `RIUS_MAIN_AGENT_DESCRIPTION` | none | What the agent does, stamped as `rius.main_agent.description`. | | `mainAgentVersion` | `RIUS_MAIN_AGENT_VERSION` | none | The version of the agent definition (prompt, tools, policy), stamped as `rius.main_agent.version`. Independent of `serviceVersion`. | | `partialSpans` | `RIUS_PARTIAL_SPANS` | `false` | Export a content-free snapshot of every span at start, so in-flight and crashed work is visible. See [Partial spans](/rius/sdk/reliability#partial-spans). | | `partialSpansDelay` | `RIUS_PARTIAL_SPANS_DELAY` | `0` | Seconds to hold a snapshot before sending it, clamped to 0-60. A span that finishes within the delay sends no snapshot at all. | | `sessionId` | `RIUS_SESSION_ID` | none | Process-wide `session.id` for every span, for an agent that handles one session per process. A [session scope](/rius/sdk/tracing#sessions) overrides it; do not set it in a server handling many users. | | `bridgeForeignProvider` | `RIUS_BRIDGE_FOREIGN_PROVIDER` | `false` | When another OpenTelemetry SDK (Langfuse, Traceloop, Logfire, MLflow, OpenLIT, Laminar) already owns the global tracer provider, also send that provider's spans to Rius, so your LLM calls keep their parents. Spans whose parent Rius never received are flagged `rius.parent.foreign` either way. | | `heartbeatTransport` | none | none | Override the heartbeat HTTP transport (mostly for tests, like `spanExporter`). | | `workspaces` | none | none | Multi-workspace routing: a map of alias to API key. Spans inside `withWorkspace(alias, fn)` export with that workspace's key; `{}` opts in with routes added later via `registerWorkspace()`. See [routing traces to the right workspace](/rius/guides/multi-tenant-observability#routing-traces-to-the-right-workspace). | | `workspaceExporterFactory` | none | none | Override how per-workspace exporters are built from an API key (mostly for tests, like `spanExporter`). | Boolean environment variables accept `1`, `true`, `yes`, or `on`, and `0`, `false`, `no`, or `off`, in any case. An unrecognized value logs a warning and falls back to the default rather than being read as false. Out-of-range `sampleRate` values are clamped to `[0.0, 1.0]`. There are no `GLASSFLOW_*` aliases: this package never shipped under that prefix, so only the `RIUS_*` names are read. ## Calling init() twice The OpenTelemetry global provider is write-once, so a second global `init()` while a client is active logs a warning and returns the existing client unchanged. To reconfigure, call `client.shutdown()` first, which drains pending spans and releases the slot. With heartbeats enabled, `shutdown()` also sends the final `stopped` ping, which is how the platform tells a clean exit from a crash (see [status semantics](/rius/platform/agents#instances)). If your process needs an isolated pipeline next to an existing one, use a scoped client instead: ```python client = rius.init(set_global=False, service_name="side-pipeline") tracer = client.get_tracer() ``` The TypeScript SDK has no scoped-client equivalent. `init()` always registers the global OpenTelemetry provider, and a second call logs a warning and returns the existing client. To reconfigure, `await client.shutdown()` first, which drains pending spans and releases the global registration. ```typescript await client.shutdown() const next = init({ serviceName: 'side-pipeline' }) ``` A scoped client does not claim the global slot, and it does not enable auto-instrumentation unless you pass `instruments=[...]` explicitly, because instrumentors patch libraries process-wide. ## What every span carries The SDK stamps these resource attributes on all spans it exports: - `service.name`, from your configuration, and `service.version` when you set one - `service.instance.id`, minted once per `init()`, which is the id the heartbeat reports too, so a trace can be joined to the process that ran it - `gen_ai.agent.name` and `rius.main_agent.name`, both the resolved agent name. `rius.main_agent.name` is left off when no service or agent name was configured, rather than claiming `unknown_service` as an identity. - `rius.main_agent.id`, `rius.main_agent.description`, and `rius.main_agent.version`, each only when set - `telemetry.distro.name: glassflow-rius` and `telemetry.distro.version` Spans created by the SDK itself use the tracer scope name `rius` (`glassflow` in releases before 1.0.0 of both SDKs). ## Span attribute limit OpenTelemetry keeps at most 128 attributes per span by default and silently drops the rest. That is too few for an auto-instrumented agent: the OpenInference instrumentors write one attribute per message field and per tool field, so a tool-calling loop with around ten tools passes 128 after roughly six to nine turns. The spans that matter most then lose data without any error. In Python the oldest keys go first, which are the model, the request parameters, the tool definitions, and the system prompt; in TypeScript the span stops accepting new keys, which are the usage, the output messages, and the finish reason. `init()` therefore raises the per-span attribute count limit to 4096. If you set `OTEL_SPAN_ATTRIBUTE_COUNT_LIMIT` or `OTEL_ATTRIBUTE_COUNT_LIMIT` to a value OpenTelemetry can use, your value wins and OpenTelemetry applies its usual precedence between the two. A blank or unusable value (not a number, or in Python not a non-negative integer) is not treated as a choice: the SDK applies 4096 instead, and the Python SDK logs a warning saying so. One exception in Python: a non-integer `OTEL_SPAN_ATTRIBUTE_COUNT_LIMIT` makes OpenTelemetry itself raise when its tracing module is imported. The attribute value length is not limited; the SDK caps its own JSON attributes at 32 KB. If you run OpenInference instrumentors without the SDK, nothing raises the limit for you; see [OpenInference](/rius/interoperability/openinference#raise-the-span-attribute-limit). ## Next steps - [Tracing your code](/rius/sdk/tracing): tracing functions with `observe`, spans, and generations. - [Integrations](/rius/sdk/integrations): tracing OpenAI, Anthropic, LangChain, and friends without manual spans. - [Monitoring live agents](/rius/platform/agents): what the heartbeat powers, including the status semantics. --- # Tracing your code The Rius SDK gives you three levels of control: `observe` for whole functions, generic spans for arbitrary steps, and generations for LLM calls. ## Tracing functions with observe Apply `observe` to any function, as a decorator in Python or a wrapper in TypeScript, to trace each call as a span: ```python import rius from rius import SpanKind @rius.observe def plan(query: str) -> str: ... @rius.observe(name="rerank", kind=SpanKind.RETRIEVER, capture_output=False) def rerank(docs: list[str]) -> list[str]: ... ``` TypeScript has no `@observe` decorator: decorators apply only to class members, so `observe` is a higher-order function that wraps any function. ```typescript // Use a named function expression. An arrow function has no inferrable name, // and its spans would fall back to "anonymous". const plan = observe(async function plan(query: string) { return await draft(query) }) // An arrow function needs an explicit name instead. const rerank = observe((docs: string[]) => reorder(docs), { name: 'rerank', kind: SpanKind.RETRIEVER, captureOutput: false, }) // The wrapper always returns a promise, even around a synchronous function, // so every call site awaits. const ranked = await rerank(docs) ``` - `name` sets the span name. Left out, a `CHAIN` span (the default kind) takes the function's qualified name, and every other kind is named the way the OpenTelemetry GenAI conventions ask, such as `execute_tool search_orders` or `invoke_agent support-agent`; see [Span names and identity](#span-names-and-identity). - `kind` defaults to `SpanKind.CHAIN`; it sets the span taxonomy (`AGENT`, `LLM`, `TOOL`, `RETRIEVER`, `EMBEDDING`, `CHAIN`) and, for every kind except `CHAIN`, the matching `gen_ai.operation.name`. - `capture_input` / `capture_output` (default true) record the arguments and return value as JSON in `input.value` / `output.value`. Values are serialized with a `repr` fallback and truncated at 32 KB, the same cap the TypeScript SDK applies. - Exceptions are recorded on the span with ERROR status and `error.type` set to the exception class, and always re-raised. Sync functions, `async def` functions, generators, and async generators are all supported. For generators the span covers the whole iteration, from first call to exhaustion, and the tracing context is attached only around each step, so it never leaks into the code consuming the generator between yields. In TypeScript the options are `name`, `kind`, `captureInput`, and `captureOutput`, plus the identity options in [Span names and identity](#span-names-and-identity). Without a `name`, a `CHAIN` span falls back to the wrapped function's `name` property, then to `"anonymous"`, and other kinds get the composed name. The wrapper awaits the return value, so a synchronous function is traced as one completed call and there is no per-step generator handling. ## Generic spans For steps that are not a single function, open spans directly. There are two lifecycles: ```python # Context manager: becomes the current span, children nest under it, # exceptions are recorded, and it ends automatically. Unnamed, this span is # called "retrieval product-kb". with rius.start_as_current_span( kind=SpanKind.RETRIEVER, data_source_id="product-kb", top_k=5 ) as obs: obs.set_input(query) docs = search(query) obs.set_retrieved_documents([{"id": d.id, "score": d.score} for d in docs]) # Manual: parented to the current span at creation, but NOT made current. # You own the lifetime and must call end(); exceptions are not auto-recorded, # so record them yourself to match what the context manager does. obs = rius.start_span("background-job") try: obs.set_attribute("job.id", job_id) ... except Exception as exc: obs.record_exception(exc) raise finally: obs.end() ``` There is no context-manager form: `startAsCurrentSpan` takes the block as a callback and the span is current for its duration, including across `await`. ```typescript // Scoped: becomes the current span, children nest under it, exceptions are // recorded, and it ends when the callback settles. Unnamed, this span is // called "retrieval product-kb". await startAsCurrentSpan( { kind: SpanKind.RETRIEVER, dataSourceId: 'product-kb', topK: 5, input: query }, async (obs) => { const docs = await search(query) obs.setRetrievedDocuments(docs.map((d) => ({ id: d.id, score: d.score }))) }, ) // Manual: parented to the current span at creation, but NOT made current. // You own the lifetime and must call end(); exceptions are not auto-recorded, // so record them yourself to match what the scoped form does. const obs = startSpan('background-job') try { obs.setAttribute('job.id', jobId) } catch (error) { obs.recordException(error) throw error } finally { obs.end() } // Or let `using` end it at the close of the block (TypeScript 5.2 or newer). { using job = startSpan('background-job') job.setAttribute('job.id', jobId) } ``` Both return an `Observation` handle with `set_input()`, `set_output()`, `set_retrieved_documents()`, `set_attribute()`, `update(input=..., output=...)`, `record_exception()`, and `end()`. The TypeScript handle has `setInput()`, `setOutput()`, `setRetrievedDocuments()`, `setAttribute()`, `recordException()`, and `end()`; its setters are chainable and `end()` is idempotent. `record_exception()` / `recordException()` records the exception event, the ERROR status, and `error.type` together, so a manually recorded failure groups with every other error span. `set_retrieved_documents()` records `gen_ai.retrieval.documents`, a list of `{"id", "score"}` objects. It carries identifiers and scores, not document text, so it is metadata and survives content stripping; put retrieved text in `set_output()` if you want it captured as content. Use the manual form when the span outlives a lexical scope, for example a span that ends in a callback. Use the context-manager form for everything else. ## Span names and identity The span name is optional on `observe`, the span helpers, and the generation helpers. Left out, the span is named the way the OpenTelemetry GenAI conventions ask: the operation, then the one identifier saying what it acted on, or the bare operation when that identifier is unknown. A name you pass always wins. | Kind | Operation | Name without an explicit one | |---|---|---| | `LLM` (generations) | `chat`, or the `operation` you pass | `chat gpt-4o`, from the requested model | | `TOOL` | `execute_tool` | `execute_tool get_weather`, from the tool name | | `AGENT` | `invoke_agent` | `invoke_agent planner`, from the invoked agent's name | | `RETRIEVER` | `retrieval` | `retrieval product-kb`, from the data source id | | `EMBEDDING` | `embeddings` | `embeddings` | | `CHAIN` | none | the function's name with `observe`, `chain` for an unnamed manual span | Span names changed in 1.0.0. Before it, an unnamed `observe` span of any kind took the function's name; now only `CHAIN` does. Saved searches and alert filters that match on the old span name of a `TOOL`, `AGENT`, `RETRIEVER`, `LLM`, or `EMBEDDING` span need updating, or pass `name` explicitly to keep the old one. The identifiers come from arguments you pass at span creation, so a [partial span](/rius/sdk/reliability#partial-spans) of a still-running step already carries them. Each applies to one kind and is ignored on the others: | Python | TypeScript | Kind | Attribute | |---|---|---|---| | `tool_name` | `toolName` | `TOOL` | `gen_ai.tool.name`, the tool's own name | | `tool_call_id` | `toolCallId` | `TOOL` | `gen_ai.tool.call.id`, the id the model put on the tool call this span answers, which joins the tool span back to the generation that asked for it | | `tool_type` | `toolType` | `TOOL` | `gen_ai.tool.type`, such as `function`, `extension`, or `datastore` | | `agent_name` | `agentName` | `AGENT` | `gen_ai.agent.name`, the agent this span invokes. Defaults to the configured agent name, never to the function name | | `agent_id` | `agentId` | `AGENT` | `gen_ai.agent.id`, for a hosted agent resource such as a Bedrock agent ARN. Leave it unset for an in-process agent | | `agent_version` | `agentVersion` | `AGENT` | `gen_ai.agent.version`, the invoked agent definition's version, recorded as given | | `data_source_id` | `dataSourceId` | `RETRIEVER` | `gen_ai.data_source.id`, the index, collection, or knowledge base searched | | `top_k` | `topK` | `RETRIEVER` | `gen_ai.retrieval.top_k`, how many documents were asked for | A `TOOL` span also carries `gen_ai.agent.name`, and there it means the agent **executing** the tool: the innermost enclosing `AGENT` span opened with `observe` or the scoped span helper, else the configured agent name. MCP tool calls get it the same way. A manual `start_span` / `startSpan` never becomes current, so an `AGENT` span opened that way does not name the tools that run while it is open. Without `tool_name`, `observe` uses the function's name as the tool name. When you pass a span `name` on a `TOOL` span but no tool name, the span name doubles as the tool name and the SDK warns about it (a `DeprecationWarning` from Python's `observe`, a one-time console warning from TypeScript's span helpers); a future major release stops deriving one from the other, so pass `tool_name` / `toolName` when the two should differ. ## Generations (LLM calls) Generations are spans with LLM semantics. They emit OpenTelemetry GenAI attributes that Rius uses for model analytics and cost computation: ```python # Unnamed, the span is called "chat gpt-4o". with rius.start_as_current_generation( model="gpt-4o", provider="openai", model_parameters={"temperature": 0.2, "max_completion_tokens": 512}, ) as gen: gen.set_input(messages) response = client.chat.completions.create(model="gpt-4o", messages=messages) gen.set_output(response.choices[0].message.content) gen.set_response_model(response.model) gen.set_response_id(response.id) gen.set_usage( input_tokens=response.usage.prompt_tokens, output_tokens=response.usage.completion_tokens, ) gen.set_finish_reasons(response.choices[0].finish_reason) ``` ```typescript // Unnamed, the span is called "chat gpt-4o". await startAsCurrentGeneration( { model: 'gpt-4o', provider: 'openai', modelParameters: { temperature: 0.2, max_completion_tokens: 512 }, input: messages, }, async (gen) => { const response = await client.chat.completions.create({ model: 'gpt-4o', messages }) gen.setOutput(response.choices[0]?.message.content) // setModel() is the TypeScript name for gen_ai.response.model. gen.setModel(response.model) gen.setResponseId(response.id) gen.setUsage({ inputTokens: response.usage?.prompt_tokens, outputTokens: response.usage?.completion_tokens, }) gen.setFinishReasons(response.choices[0]?.finish_reason ?? 'stop') }, ) ``` `start_generation()` is the manual-lifecycle twin, with the same semantics as `start_span()`, including `record_exception()` for failures you catch. The attributes emitted: | Attribute | Source | |---|---| | `gen_ai.request.model` | `model=` argument | | `gen_ai.provider.name` | `provider=` argument | | `gen_ai.request.*` / `rius.request.*` | `model_parameters`, see [Request parameters](#request-parameters) | | `gen_ai.request.reasoning.level` | `reasoning_level=` argument | | `gen_ai.output.type` | `output_type=` argument, the requested output modality such as `text` or `json` | | `gen_ai.tool.definitions` | `tools=` argument or `set_tool_definitions()`, recorded verbatim in the provider's shape | | `gen_ai.input.messages` / `gen_ai.output.messages` | `set_input()` / `set_output()` | | `gen_ai.usage.input_tokens` / `gen_ai.usage.output_tokens` | `set_usage()` | | `gen_ai.usage.cache_read.input_tokens` / `gen_ai.usage.cache_write.input_tokens` | `set_usage()` | | `gen_ai.usage.reasoning.output_tokens` | `set_usage()` | | `gen_ai.response.model` | `set_response_model()` | | `gen_ai.response.id` | `set_response_id()`, the provider's completion id | | `gen_ai.response.finish_reasons` | `set_finish_reasons()` | | `gen_ai.operation.name` | `operation=` argument (default `chat`) | | `rius.context.sizes` | computed by the SDK when the span ends, see below | In TypeScript the same attributes come from the `model`, `provider`, `modelParameters`, `reasoningLevel`, `outputType`, `tools`, and `operation` options, and from `setToolDefinitions()`, `setInput()` / `setOutput()`, `setUsage()`, `setModel()`, `setResponseId()`, and `setFinishReasons()`. Every generation span also carries `rius.context.sizes`: a compact JSON breakdown of the byte size of each tool definition and each input and output message part, measured before content is truncated. Rius uses it to divide the call's input tokens across the parts of the context. It holds sizes, not content, so it survives `capture_content=False` and is never masked. ### Request parameters `model_parameters` (`modelParameters`) takes the parameters you sent the model, and each lands under the attribute its meaning calls for: - A parameter the GenAI conventions define is recorded under its canonical `gen_ai.request.*` key, whichever spelling you pass: `max_tokens`, `max_completion_tokens`, `max_output_tokens`, and `maxOutputTokens` all become `gen_ai.request.max_tokens`; `stop` and `stop_sequences` become `gen_ai.request.stop_sequences`; `n` becomes `gen_ai.request.choice.count`; `reasoning_effort` becomes `gen_ai.request.reasoning.level`. - Anything else keeps its key under `rius.request.`, for example `rius.request.tool_choice` or `rius.request.response_format`. The conventions reserve `gen_ai.request.*` for the keys they define, so a parameter of your own does not go there. - Each canonical key only takes a value of its own type: a lone `stop` string becomes a one-element list, and a value of the wrong type (a temperature passed as a string, say) is kept under `rius.request.` instead of being dropped. - When two spellings of one parameter arrive together, a fixed precedence decides which one gets the canonical key, whatever order you wrote them in, and the other is kept under `rius.request.`. - Values that are not scalars or lists of one scalar type are JSON-encoded. `None` / `null` / `undefined` means "not set" and is skipped. The `model` and `reasoning_level` arguments win over a parameter that maps to the same key. This changed in 1.0.0. Earlier releases wrote every key as `gen_ai.request.` verbatim, so a query on `gen_ai.request.max_completion_tokens` or on a custom parameter under `gen_ai.request.` stops matching new spans. Query the canonical key, or `rius.request.` for your own parameters. A `tools` or `functions` array passed through `model_parameters` is treated as content, like `gen_ai.tool.definitions`, and stripped when content capture is off. Pass tool definitions with `tools=` instead. Send token usage, never cost: Rius computes cost server-side from model pricing, so your instrumentation stays free of pricing tables. When the provider uses prompt caching, pass the cache counts too. Since `glassflow-rius` 0.13.0 and `@glassflow-ai/rius` 0.4.0, `set_usage()` also takes `cache_read_input_tokens` and `cache_write_input_tokens` (`cacheReadInputTokens` / `cacheWriteInputTokens` in TypeScript; Anthropic calls the write count "cache creation" in its payloads). Pass provider-reported values as-is, whatever their shape. Per the GenAI conventions `input_tokens` is the total including cached tokens, and OpenAI's `cached_tokens` is already a subset of `prompt_tokens`; Anthropic instead reports an `input_tokens` that excludes cache reads and writes. Rius detects the exclusive shape and normalizes it server-side, so no client arithmetic is needed either way. Skipping the cache fields makes cost badly undercount cache-heavy workloads such as agent loops. ### Streaming responses When you stream, total duration stops being a useful latency signal: a long generation usually just means a long answer. The number streaming users feel is time to first token, and the SDK records it with one call from your streaming loop: ```python gen = rius.start_generation(model="gpt-4o", provider="openai") gen.set_input(messages) chunks = [] stream = client.chat.completions.create(model="gpt-4o", messages=messages, stream=True) for chunk in stream: gen.record_first_token() # idempotent; call it unconditionally per chunk if chunk.choices and chunk.choices[0].delta.content: chunks.append(chunk.choices[0].delta.content) gen.set_output("".join(chunks)) gen.end() ``` ```typescript const gen = startGeneration({ model: 'gpt-4o', provider: 'openai' }) gen.setInput(messages) const chunks: string[] = [] try { const stream = await client.chat.completions.create({ model: 'gpt-4o', messages, stream: true, }) for await (const chunk of stream) { gen.recordFirstToken() // idempotent; call it unconditionally per chunk const delta = chunk.choices[0]?.delta.content if (delta) chunks.push(delta) } gen.setOutput(chunks.join('')) } catch (error) { gen.recordException(error) throw error } finally { gen.end() } ``` `record_first_token()` / `recordFirstToken()` marks the moment the first chunk arrives (as a `gen_ai.first_token` span event) and also sets `gen_ai.response.time_to_first_chunk` (seconds since the span started) and `gen_ai.request.stream: true`. Only the first call records anything in either SDK, so guarding it yourself is unnecessary. Rius derives time to first token from the event, which unlocks per-model TTFT percentiles and inter-token latency in your analytics. If you use the Python `openai` [auto-instrumentation](/rius/sdk/integrations) instead of manual generations, streamed OpenAI calls get a first-token marker automatically. Auto-instrumented Anthropic streams and TypeScript OpenAI streams do not; see the [OpenAI](/rius/sdk/integrations/openai#streaming-and-token-usage) and [Anthropic](/rius/sdk/integrations/anthropic#streaming) pages. ### Message formats `set_input()` and `set_output()` normalize whatever you pass into the GenAI message shape (`{"role", "parts": [...]}`): - a bare string becomes a single text part (role `user` on input, `assistant` on output) - OpenAI-style dicts (`{"role", "content"}`) are converted, including `tool_calls` arrays and `role: "tool"` responses - multimodal content lists are converted part by part - anything else is serialized to a JSON text part You do not need to pre-shape messages; pass what your client library gives you. Both SDKs normalize the same way and write the same JSON, so spans from Python and TypeScript agents read alike in the console and in saved queries. ## Sessions A trace covers one causal unit of work and stays short. A [session](/rius/concepts#sessions) is a correlation unit your application assigns: one conversation, one agent run, anything that spans several turns and therefore several traces. You mint the id, and the SDK stamps it as the `session.id` attribute on every span started in scope. Scope a session around each unit of work, passing your own id (a conversation id, a job id) to correlate with it: ```python import rius with rius.session(conversation_id): handle_turn(message) # every span of the turn carries session.id ``` Call `rius.session()` with no argument to mint a fresh UUID for the scope. Either way the block yields the id, so you can log it or hand it to the next turn: ```python with rius.session() as session_id: run_agent(task) ``` ```typescript await withSession(conversationId, async () => { await handleTurn(message) // every span of the turn carries session.id }) ``` Call `withSession` with only a callback to mint a fresh UUID for the scope. Either way the scope's id is passed to the callback, so you can log it or hand it to the next turn: ```typescript await withSession(async (sessionId) => { await runAgent(task) }) ``` Scopes ride OpenTelemetry context, not a global: they nest (the innermost wins), unwind with the block even on an error, and follow async work the same way the active span does. ### A process-wide default For an agent that handles exactly one session per process, a CLI run or a batch job, set the id once at startup instead of scoping every call, with `init(session_id=...)` in Python, `init({ sessionId })` in TypeScript, or the `RIUS_SESSION_ID` environment variable in either language. An active session scope overrides the default. Do not set a process-wide default in a server that handles many users: every user's traces would merge into one session. Scope each request instead. With neither a scope nor a default, spans carry no `session.id` and the platform groups each trace as its own session, which is the right behavior when you have not claimed anything spans turns. The SDK deliberately never auto-generates a process-wide id for the same reason. ## Users A [user](/rius/concepts#users) is the person a request served. Where a session groups the turns of one conversation, the user ties together everything that person did across conversations, agents, and days. You supply the identifier your application already has for them, and the SDK stamps it as the `user.id` attribute on every span started in scope, including spans created by auto-instrumentation. Scope the user around each request: ```python import rius with rius.user(request.user_id): handle(request) # every span of the request carries user.id ``` For a single span with no children of its own, `user_id=` on `start_span`, `start_as_current_span`, `start_generation`, and `start_as_current_generation` is sugar for the same thing. The block-scoped variants also enter the scope, so their children inherit the user. ```typescript await withUser(request.userId, async () => { await handle(request) // every span of the request carries user.id }) ``` For a single span with no children of its own, `userId` in the options of `startSpan`, `startAsCurrentSpan`, `startGeneration`, and `startAsCurrentGeneration` is sugar for the same thing. The scoped variants also enter the scope, so their children inherit the user. User scopes ride OpenTelemetry context exactly like sessions: they nest (the innermost wins), unwind with the block, follow async work, and combine freely with a session scope. `observe` deliberately takes no user argument, because a decorator is bound once at import time and a user is a property of each request. Two things differ from sessions on purpose. There is no process-wide default and no environment variable: a global user would attribute every request a process handles to one person. And nothing is minted when you pass nothing: a span outside any user scope is simply anonymous, and the platform treats an empty user as exactly that. Prefer an opaque identifier over an email or a name. The value is stored on every span and shown in the console, so send what you would be comfortable seeing in a trace. When only sensitive identifiers exist, hash them first; OpenTelemetry's `user.hash` and `enduser.pseudo.id` describe that practice. ## Workspace scopes Sessions and users have a sibling scope for multi-tenant runtimes: `rius.workspace(alias)` / `withWorkspace(alias, fn)` routes every span started inside it to another workspace's destination, registered via `init(workspaces={...})`. It rides OpenTelemetry context exactly like sessions, so the two nest together, but a trace must stay inside one workspace. The full pattern lives in the [multi-tenant observability guide](/rius/guides/multi-tenant-observability#routing-traces-to-the-right-workspace). ## Next steps - [Integrations](/rius/sdk/integrations): let the SDK create generations for you. - [Advanced features](/rius/sdk/advanced): sampling and privacy controls over what you just captured. --- # Integrations Rius integrates with the client libraries, agent frameworks, and protocols agents are built on: model calls arrive as generations with tokens and cost, and run structure arrives from the framework's own spans or a thin layer of [`observe`](/rius/sdk/tracing) wrappers. Each integration's page covers setup, what lands in the trace, and the blind spots. ## Support matrix | Integration | Type | Model calls captured by | Python | TypeScript | |---|---|---|---|---| | [OpenAI](/rius/sdk/integrations/openai) | Client library | the `openai` instrumentation | ✓ | ✓ | | [Anthropic](/rius/sdk/integrations/anthropic) | Client library | the `anthropic` instrumentation | ✓ | ✓ | | [LangChain](/rius/sdk/integrations/langchain) | Framework | its callbacks, hooked by the `langchain` instrumentation | ✓ | ✓ | | [LlamaIndex](/rius/sdk/integrations/llama-index) | Framework | the `llama-index` instrumentation | ✓ | N/A | | [LiteLLM](/rius/sdk/integrations/litellm) | Router | the `litellm` instrumentation | ✓ | N/A | | [MCP](/rius/sdk/integrations/mcp) | Protocol | instrumentation bundled in the SDK | ✓ | ✓ | | [Vercel AI SDK](/rius/sdk/integrations/vercel-ai) | Framework | its OpenTelemetry telemetry | N/A | ✓ | | [OpenAI Agents SDK](/rius/sdk/integrations/openai-agents) | Agent framework | the `openai` instrumentation underneath | ✓ | N/A | | [Pydantic AI](/rius/sdk/integrations/pydantic-ai) | Agent framework | its native OpenTelemetry spans | ✓ | N/A | | [CrewAI](/rius/sdk/integrations/crewai) | Agent framework | the `openai` instrumentation (`litellm` when LiteLLM is installed) | ✓ | N/A | | [AutoGen](/rius/sdk/integrations/autogen) | Agent framework | its native OpenTelemetry spans plus the `openai` instrumentation | ✓ | N/A | | [Claude Agent SDK](/rius/sdk/integrations/claude-agent-sdk) | Agent framework | manual tracing: an `observe` root plus a generation filled from the run result | ✓ | N/A | "N/A" means no integration in that language today; trace those calls with [manual generations](/rius/sdk/tracing#generations-llm-calls). Install commands and package names live on each integration's page. ## Installing Each integration is an optional extra, and extras can be combined: ```bash pip install "glassflow-rius[openai]" pip install "glassflow-rius[anthropic,langchain]" pip install "glassflow-rius[instruments]" # all of them ``` Each extra installs the **instrumentation for** a library, never the library itself. `glassflow-rius[anthropic]` expects `anthropic` to be in your environment already, which it is in any project that calls Anthropic: Rius deliberately takes no dependency on provider SDKs, so it never pins or upgrades the versions your code runs against. An extra installed without its library makes `init()` log a `DependencyConflict` from OpenTelemetry and leaves that integration off, which is the one failure worth recognizing here; see [Troubleshooting](/rius/sdk/troubleshooting#init-logs-a-dependencyconflict). `mcp` needs no extra at all. Its instrumentation ships inside the SDK rather than as a separate package, so there is nothing for an extra to add: it turns itself on whenever the `mcp` package is importable, which it is in any agent that calls MCP tools. There are no extras. Each bundled integration is an optional peer dependency that you install yourself, and `init()` enables whichever of them it finds: ```bash npm install @arizeai/openinference-instrumentation-openai npm install @modelcontextprotocol/sdk npm install @ai-sdk/otel ``` A plain `npm install @glassflow-ai/rius` patches nothing, since none of these is pulled in for you. The Vercel AI SDK integration additionally requires Node 22 or newer; on `ai` 7 install `@ai-sdk/otel` and `init()` registers it for you, while `ai` 5 and 6 use `@arizeai/openinference-vercel` and per-call telemetry (see [its recipe](/rius/sdk/integrations/vercel-ai)). The client-library integrations are powered by [OpenInference](https://github.com/Arize-ai/openinference), the open source (Apache-2.0) instrumentation project from Arize AI; the SDK bundles its instrumentors and wires them into the Rius pipeline. The MCP integration is built into the SDK itself. ## Enabling With a default (global) `init()`, every installed integration is enabled automatically: ```python rius.init() # everything installed rius.init(instruments=["openai"]) # only OpenAI rius.init(instruments=[]) # none ``` There is no `instruments` option. `init()` always attempts every bundled integration, so which ones attach is decided entirely by which optional peer dependencies are installed. ```typescript const client = init() // `ready` resolves with the names that attached, for example ['openai', 'mcp']. // It never rejects, even if every peer is missing or one fails to load. console.log(await client.ready) // The only way to attach nothing is to turn the SDK off. Then no optional // package is even imported, and `ready` resolves to an empty array. init({ disabled: true }) ``` Details worth knowing: - Requesting an integration whose package is not installed logs a warning and continues; a broken instrumentor never blocks `init()`. - If a library is already instrumented by other OpenTelemetry code (not by this SDK), it is left alone. - Scoped clients (`set_global=False`) do **not** auto-instrument, because instrumentors patch libraries process-wide; pass `instruments=[...]` explicitly to opt in. In TypeScript the loud and quiet cases are deliberately split: a package you did not install stays silent, while a package that is installed but fails to load logs a warning naming the integration and the underlying error. Either way `init()` continues, and the remaining integrations still attach. ## What the SDK normalizes Each bundled instrumentor writes its own attribute dialect, mostly OpenInference's `llm.*` keys. Since 1.0.0 both SDKs rewrite those spans onto the same OpenTelemetry GenAI keys a [manual generation](/rius/sdk/tracing#generations-llm-calls) carries, inside your process and before the [privacy controls](/rius/sdk/advanced#privacy-controls) run: - **Taxonomy.** Every span carries both `openinference.span.kind` and `gen_ai.operation.name`, whichever one the instrumentor set. - **The model call.** `gen_ai.provider.name`, `gen_ai.request.model`, the request parameters the SDK recognizes (as `gen_ai.request.*`, plus `rius.request.tool_choice`), `gen_ai.response.finish_reasons` (the provider's own values, not rewritten), and `gen_ai.response.id`. - **Usage.** Input and output tokens, cache reads and writes, and reasoning tokens, under the `gen_ai.usage.*` keys. - **Messages.** The flattened `llm.input_messages.*` and `llm.output_messages.*` keys are reassembled into `gen_ai.input.messages` and `gen_ai.output.messages`, including Anthropic's multi-part contents. An Anthropic system prompt arrives as the leading system message. - **Tools.** `gen_ai.tool.name` on tool spans, and the request's tool list as `gen_ai.tool.definitions`. - **Errors.** `error.type`, taken from the recorded exception. In TypeScript, provider SDK errors are named by class and package, such as `anthropic.NotFoundError`, the same spelling Python reports. - **Streaming.** The instrumentor's own first-token event, where it records one, becomes `gen_ai.first_token` with the time to first chunk. - **Embeddings.** The embedding model becomes `gen_ai.request.model`, and embedding vectors are dropped rather than exported. A mapped source key is removed once its value has moved, so each fact is stored once. A key the instrumentation already writes in the canonical spelling is never overwritten, and a key with no canonical equivalent passes through unchanged. ## Known limitations - **Nested model spans are counted twice.** Trace and workspace totals add up tokens and cost over every span that carries them, so when two layers both record the same model call, its usage is counted twice: - LangChain together with a client instrumentation such as `openai`: the LangChain LLM span and the client span underneath it both carry the call's tokens. - LiteLLM together with the `openai` instrumentation: LiteLLM calls OpenAI-compatible providers through the `openai` client library, so both instrumentors record the call. - The Vercel AI SDK on `ai` 7: the `invoke_agent` span for a `generateText` or `streamText` call carries the usage of the whole call, and each `chat` step span under it carries its own. In Python, enable one layer with `init(instruments=[...])`, for example `instruments=["langchain"]`. The Vercel case has no switch today. - **No time to first token on auto-instrumented Anthropic streams, or on TypeScript OpenAI streams.** Of the client instrumentations, only the Python `openai` one records a first-token event. Where TTFT matters for those calls, trace them as a [manual generation](/rius/sdk/tracing#streaming-responses). - **TypeScript OpenAI streams carry no token usage**, so they get no cost. See [OpenAI](/rius/sdk/integrations/openai#streaming-and-token-usage). --- # OpenAI Trace every OpenAI client call with Rius without touching your call sites. ## Setup ```bash pip install "glassflow-rius[openai]" openai ``` The extra installs the instrumentation, not `openai` itself, so the package is named here for a fresh environment. A project that already calls OpenAI has it, and pip leaves it untouched. Without it, `init()` logs a `DependencyConflict` and this integration stays off. ```python import rius from openai import OpenAI rius.init(api_key="ri_...", service_name="my-agent") client = OpenAI() # use the client exactly as before ``` `init()` detects the installed extra and instruments the client library process-wide; every call from anywhere in your process is traced. ```bash npm install @arizeai/openinference-instrumentation-openai ``` ```typescript const rius = init({ apiKey: 'ri_...', serviceName: 'my-agent' }) const client = new OpenAI() // use the client exactly as before ``` `init()` enables the integration if the package above is installed, and instruments the client library process-wide. Call it before you create the client, so the patch is in place by the time you make a request. `await rius.ready` resolves with the integrations that attached, so it tells you whether `openai` is among them. Works in CommonJS and pure-ESM applications alike: the SDK patches the build of `openai` your process actually uses. One ordering rule for CommonJS apps: require `openai` before `init()`. A require that only happens after `init()` stays untraced even though `client.ready` lists `openai`. See [Troubleshooting](/rius/sdk/troubleshooting#an-instrumentation-is-not-producing-spans). ## What gets captured Each chat completion becomes an LLM-kind span carrying the model, token usage, and input/output messages; cost is computed server-side from the model and tokens. The SDK maps the instrumentor's keys onto the canonical GenAI ones, including the request parameters, finish reasons, the completion id, and the tool definitions; see [what the SDK normalizes](/rius/sdk/integrations#what-the-sdk-normalizes). On **streamed** calls the Python instrumentor also records a first-token event, so time to first token works without any manual code. A call OpenAI rejects, such as a 404 for an unknown model, a 429, or a timeout, is recorded as an ERROR span with `error.type` naming the error class (`openai.NotFoundError`, for example). In TypeScript the SDK ends that span itself, because the upstream instrumentation leaves a rejected call's span open. ## Streaming and token usage Streamed responses do not include usage by default; ask OpenAI to send it with the final chunk: ```python stream = client.chat.completions.create( model="gpt-4o-mini", messages=messages, stream=True, stream_options={"include_usage": True}, ) ``` ```typescript const stream = await client.chat.completions.create({ model: 'gpt-4o-mini', messages, stream: true, stream_options: { include_usage: true }, }) ``` Without it, streamed spans have no token counts, and no tokens means no cost. In TypeScript, streamed chat completions carry no token usage and no first-token event even with `include_usage`: the OpenInference OpenAI instrumentation for Node (checked at 4.2.1) does not read either from the stream. Streamed calls therefore get no cost and no time to first token. Where either matters, trace the streamed call as a [manual generation](/rius/sdk/tracing#streaming-responses) and pass the final chunk's usage to `setUsage()`. Non-streamed calls are unaffected. ## Verify Run one call, then open the trace in the console: the span shows the resolved model (for example `gpt-4o-mini-2024-07-18`), input/output token counts, and a cost. Wrap the call in [`observe`](/rius/sdk/tracing#tracing-functions-with-observe) to see it nested inside your agent's run instead of as a standalone trace. Prompt and response content is subject to your [privacy controls](/rius/sdk/advanced#privacy-controls): `capture_content=False` (`captureContent: false` in TypeScript) and masking apply to instrumented calls exactly like manual ones. --- # Anthropic Trace every Anthropic client call with Rius without touching your call sites. ## Setup ```bash pip install "glassflow-rius[anthropic]" anthropic ``` The extra installs the instrumentation, not `anthropic` itself, so the package is named here for a fresh environment. A project that already calls Anthropic has it, and pip leaves it untouched. Without it, `init()` logs a `DependencyConflict` and this integration stays off. ```python import rius from anthropic import Anthropic rius.init(api_key="ri_...", service_name="my-agent") client = Anthropic() # use the client exactly as before ``` ```bash npm install @arizeai/openinference-instrumentation-anthropic ``` The SDK requires version 0.2.7 or newer of this package. Earlier versions report Anthropic's cache-exclusive input count and drop both cache counts, which makes cost undercount any call that uses prompt caching. ```typescript const rius = init({ apiKey: 'ri_...', serviceName: 'my-agent' }) const client = new Anthropic() // use the client exactly as before ``` `init()` enables the integration if the package above is installed, and instruments the client library process-wide. `await rius.ready` resolves with the integrations that attached, so it tells you whether `anthropic` is among them. Works in CommonJS and pure-ESM applications alike: the SDK patches the build of `@anthropic-ai/sdk` your process actually uses. One ordering rule for CommonJS apps: require `@anthropic-ai/sdk` before `init()`. A require that only happens after `init()` stays untraced even though `client.ready` lists `anthropic`. See [Troubleshooting](/rius/sdk/troubleshooting#an-instrumentation-is-not-producing-spans). ## What gets captured Each `messages.create` call becomes an LLM-kind span carrying the model (for example `claude-haiku-4-5-20251001`), input/output token usage from the response including cache reads and writes, and the request/response messages; cost is computed server-side from the model and tokens. The SDK reassembles the messages into the GenAI message shape: text blocks become text parts, tool calls become `tool_call` parts, and any other block (an image or a reasoning block, say) is kept as a text part holding the block serialized, so nothing is lost. Anthropic takes the system prompt as a separate `system` parameter rather than as a message; it lands as the leading `system` message of `gen_ai.input.messages`, where the console and context attribution read it. A failed call records `error.type` as the error class, such as `anthropic.NotFoundError`. See [what the SDK normalizes](/rius/sdk/integrations#what-the-sdk-normalizes). ## Streaming Token usage is captured on streamed calls too (Anthropic reports it in the message lifecycle events). One gap to know about: unlike the Python OpenAI instrumentor, the underlying [OpenInference](https://github.com/Arize-ai/openinference) Anthropic instrumentors, Python and TypeScript alike, emit **no first-token event**, so time to first token is not available for auto-instrumented Anthropic streams. If TTFT matters for a call, trace it as a [manual generation](/rius/sdk/tracing#streaming-responses) with `record_first_token()` instead. ## Verify Run one call, then open the trace in the console: the span shows the model, token counts, and a cost. Wrap the call in [`observe`](/rius/sdk/tracing#tracing-functions-with-observe) to see it nested inside your agent's run. Prompt and response content is subject to your [privacy controls](/rius/sdk/advanced#privacy-controls), exactly like manual generations. --- # LangChain Trace LangChain (and LangGraph) runs with Rius: chains, tools, retrievers, and model calls arrive as a nested trace mirroring your graph. ## Setup ```bash pip install "glassflow-rius[langchain]" langchain ``` The extra installs the instrumentation, not `langchain` itself, so the package is named here for a fresh environment. A project that already calls LangChain has it, and pip leaves it untouched. Without it, `init()` logs a `DependencyConflict` and this integration stays off. ```python import rius rius.init(api_key="ri_...", service_name="my-agent") # build and run your chains exactly as before ``` The instrumentor hooks LangChain's callback system, so anything that runs through it is traced: LCEL chains, agents, LangGraph nodes. ```bash npm install @arizeai/openinference-instrumentation-langchain ``` This integration also needs `@langchain/core`, which a LangChain.js application already has. `@langchain/core` 1.x requires Node 20 or newer. ```typescript const rius = init({ apiKey: 'ri_...', serviceName: 'my-agent' }) // build and run your chains exactly as before ``` `init()` resolves `@langchain/core`'s callback manager for you and patches it, so nothing has to be passed in at `init()`. `await rius.ready` resolves with the integrations that attached, so it tells you whether `langchain` is among them. This integration does not use OpenTelemetry's CommonJS module hook, so it works the same in a pure-ESM application as in CommonJS. ## What gets captured One span per step, typed by what the step is: chains as CHAIN spans, tool invocations as TOOL, retrievers as RETRIEVER, and model calls as LLM spans with model, token usage, and messages (cost computed server-side). The nesting follows your chain structure, so a trace reads like the execution graph. ## Combining with client instrumentation Installing `langchain` alongside a client extra (say `openai`) works: LangChain's LLM span wraps the client library's span, so you get framework context and client-level detail, nested. Both spans carry the same call's token usage, though, and trace and workspace totals add up every span that carries tokens, so each model call is counted twice in tokens and cost. If the totals matter more than the second layer, keep one of the two: in Python with `rius.init(instruments=["langchain"])`, in TypeScript by not installing the client instrumentation package, since `init()` attaches whatever is installed. ## Verify Run one chain that calls a model, then open the trace in the console: you should see the chain's structure as nested spans, with the LLM leaf carrying model, tokens, and cost. All step inputs/outputs and messages are content attributes; [privacy controls](/rius/sdk/advanced#privacy-controls) apply to the whole tree. --- # LlamaIndex Trace LlamaIndex pipelines with Rius: query engines, retrievers, embeddings, and the model calls inside them. This integration is Python only. There is no LlamaIndex integration in TypeScript, so query-engine and retriever structure is not captured for LlamaIndex.TS. The [OpenAI integration](/rius/sdk/integrations/openai) still traces the provider calls it makes through the OpenAI client, and [manual generations](/rius/sdk/tracing#generations-llm-calls) cover the pipeline around them. ## Setup ```bash pip install "glassflow-rius[llama-index]" llama-index ``` The extra installs the instrumentation, not `llama-index` itself, so the package is named here for a fresh environment. A project that already calls LlamaIndex has it, and pip leaves it untouched. Without it, `init()` logs a `DependencyConflict` and this integration stays off. ```python import rius rius.init(api_key="ri_...", service_name="my-agent") # build indexes and query engines exactly as before ``` ## What gets captured A query becomes a nested trace of typed spans: retrieval steps as RETRIEVER spans, embedding calls as EMBEDDING, synthesis model calls as LLM spans with model, token usage, and messages (cost computed server-side). RAG debugging usually starts here: the retriever span's output shows what the model was given to work with. ## Verify Run one query against an index, then open the trace in the console: the pipeline appears as nested spans with the LLM leaf carrying model, tokens, and cost. Retrieved document content and messages are content attributes; [privacy controls](/rius/sdk/advanced#privacy-controls) cover them, while document ids and scores stay visible even with content stripped. --- # LiteLLM Trace calls routed through LiteLLM with Rius: one integration covers every provider behind the router. This integration is Python only, as is the LiteLLM library itself. From TypeScript, calls to a LiteLLM proxy over its OpenAI-compatible endpoint are traced by the [OpenAI integration](/rius/sdk/integrations/openai), since you make them with the OpenAI client. The model recorded is the one you ask the proxy for, not whichever provider it routes to. ## Setup ```bash pip install "glassflow-rius[litellm]" litellm ``` The extra installs the instrumentation, not `litellm` itself, so the package is named here for a fresh environment. A project that already calls LiteLLM has it, and pip leaves it untouched. Without it, `init()` logs a `DependencyConflict` and this integration stays off. ```python import rius import litellm rius.init(api_key="ri_...", service_name="my-agent") response = litellm.completion( model="gpt-4o-mini", # or any provider LiteLLM routes to messages=[{"role": "user", "content": "hi"}], ) ``` ## What gets captured Each routed completion becomes an LLM-kind span with the model, token usage, and messages; cost is computed server-side from the model and tokens. Because LiteLLM normalizes providers behind one API, this single extra gives you model analytics across every provider you route to, and switching providers keeps your tracing unchanged. LiteLLM calls OpenAI and OpenAI-compatible providers through the `openai` client library. If the `openai` extra is installed too, that client call is traced as a second LLM span, and trace totals then count its tokens and cost twice. Enable only the LiteLLM layer with `rius.init(instruments=["litellm"])` when both extras are present, for example through `glassflow-rius[instruments]`. ## Verify Run one completion, then open the trace in the console: the span shows the model, token counts, and a cost. Route the same call to a different provider and the comparison shows up in model analytics. If you use LiteLLM as a proxy server rather than the Python library, the proxy is a separate process: instrument the proxy itself or send its OTel traces via the [interoperability path](/rius/interoperability). --- # MCP Trace your agent's outgoing MCP tool calls with Rius, and connect them to the server's own traces where the protocol allows it. Two different things share the MCP name. **This integration instruments your agent's own outgoing MCP tool calls** so they show up in your traces. The [Rius MCP server](/rius/mcp) is the opposite direction: an endpoint that lets AI clients query your telemetry. Instrumenting your agent does not require the MCP server, and vice versa. ## Setup There is nothing to install. Unlike the client-library integrations, which are powered by OpenInference and come from extras, the MCP instrumentation ships inside the SDK, and it enables itself whenever the [`mcp`](https://pypi.org/project/mcp/) package is importable, which it already is in any agent that calls MCP tools. ```python import rius rius.init(api_key="ri_...", service_name="my-agent") # use mcp.ClientSession exactly as before ``` There is nothing to install. The MCP instrumentation ships inside the SDK, and it enables itself whenever [`@modelcontextprotocol/sdk`](https://www.npmjs.com/package/@modelcontextprotocol/sdk) is resolvable, which it already is in any agent that calls MCP tools. ```typescript init({ apiKey: 'ri_...', serviceName: 'my-agent' }) // use the MCP SDK's Client exactly as before ``` `init()` patches the MCP SDK's `Client` class itself, so every client you construct afterwards is traced. Call it before you make tool calls. In a CommonJS application, require the MCP SDK before `init()`: the SDK patches the copies of the `Client` class already in your process, and one that is first required later stays untraced. ## What gets captured Calls made through `mcp.ClientSession.call_tool()` are traced as TOOL spans named `execute_tool `, carrying: - `gen_ai.tool.name`: the tool being called - `input.value`: the tool arguments (JSON) - `output.value`: the tool result, preferring structured content, falling back to text blocks Failures are recorded with ERROR status, both when the call raises and when the MCP result itself is flagged as an error (`is_error` on the `mcp` 2.x package, `isError` on 1.x; both majors are supported). Calls made through the MCP SDK's `Client.callTool()` are traced as TOOL spans named `execute_tool `, carrying: - `gen_ai.tool.name`: the tool being called - `input.value`: the tool arguments - `output.value`: the tool result Failures are recorded with ERROR status, both when `callTool()` rejects and when the MCP result itself is flagged as an error (`is_error` on the MCP SDK's 2.x results, `isError` on 1.x; both spellings are read). An error-flagged result keeps its output, since the error content is what you need to see. A tool call that comes back asking for more input records `mcp.result_type: input_required` and no output, because an input request carries conversation content that does not belong on a tool span. The final round of the same call records its output as usual. In both SDKs the span also follows the OpenTelemetry MCP conventions: its OpenTelemetry span kind is CLIENT, `mcp.method.name` is `tools/call`, and `mcp.protocol.version` carries the negotiated protocol version when the session exposes it. A result flagged as an error sets `error.type` to `tool_error`. `gen_ai.agent.name` names the agent that made the call: the innermost enclosing `AGENT` span opened with `observe` or the scoped span helper, else your configured agent name (see [Span names and identity](/rius/sdk/tracing#span-names-and-identity)). Argument and result values are content attributes, so [privacy controls](/rius/sdk/advanced#privacy-controls) apply to them like everything else. ## Connecting agent and MCP server traces With the `mcp` package at 2.x, trace context propagates through tool calls. That connects both sides of a call into one trace, if two things are true: 1. The MCP server you call is itself instrumented (with the Rius SDK or any OpenTelemetry SDK). 2. The server exports its traces to the Rius receiver, using an API key for the same workspace as your agent. The server's spans then appear under your agent's `execute_tool` span, one waterfall covering the agent's side and the server's side of the same call. On `mcp` 1.x there is no context propagation: an instrumented server's spans still arrive, but as separate traces. The TypeScript integration does not propagate trace context into the tool call, so an instrumented server's spans arrive as separate traces rather than nested under your agent's tool span. Both sides are still queryable, and the timestamps line up, but there is no single waterfall across the call. --- # Vercel AI SDK Trace Vercel AI SDK calls in Rius, with prompts, responses, models, tool definitions, and token usage. This integration is TypeScript only. The Python SDK has no Vercel AI SDK integration, because the library itself is JavaScript only. ## Setup on `ai` 7 ```bash npm install @ai-sdk/otel ``` Since `ai` 7 the AI SDK no longer emits OpenTelemetry spans itself: they come from the official `@ai-sdk/otel` telemetry integration, and something has to register it. With `@glassflow-ai/rius` 0.6.0 or newer, `init()` does that for you. Install the package, initialize Rius, and every AI SDK call is traced, with no telemetry code in your application: ```typescript init({ apiKey: 'ri_...', serviceName: 'my-agent' }) const { text } = await generateText({ model: openai('gpt-4o-mini'), prompt: 'Summarise this ticket', }) ``` `@ai-sdk/otel` requires Node 22 or newer, the same floor as `ai` 7 itself. The spans it produces follow the OpenTelemetry GenAI semantic conventions, which is Rius's native format: input and output messages, the request's tool definitions, the resolved model, and token usage including cache reads, plus an agent span wrapping the steps of a tool-calling loop. Cost is computed server-side from the model and tokens. `@arizeai/openinference-vercel` is no longer required on `ai` 7. If it is installed, Rius runs its attribute transform only on spans in the AI SDK's own `ai.*` dialect, recognized by their `ai.operationId`. The GenAI-native spans of `@ai-sdk/otel`, your own spans, and other instrumentations' spans are exported exactly as they would be without it. The `invoke_agent` span carries the token usage of the whole call, and each `chat` step under it carries its own. Trace and workspace totals add up every span that carries tokens, so a call's tokens and cost are counted twice in those totals. The per-step `chat` spans hold the accurate per-call numbers. ## Setup on `ai` 5 and 6 ```bash npm install @arizeai/openinference-vercel ``` These versions have OpenTelemetry built in but emit nothing unless a call opts in, and their spans use the AI SDK's own attribute names, which `@arizeai/openinference-vercel` translates for Rius. Enable telemetry per call: ```typescript const { text } = await generateText({ model: openai('gpt-4o-mini'), prompt: 'Summarise this ticket', experimental_telemetry: { isEnabled: true }, }) ``` ## Ordering and privacy Everything the integration produces is covered by your [privacy controls](/rius/sdk/advanced#privacy-controls): `captureContent: false` and a `mask` apply to prompts, responses, tool definitions, the system prompt (`gen_ai.system_instructions`), and each tool call's arguments and result (`gen_ai.tool.call.arguments`, `gen_ai.tool.call.result`) exactly as they apply to manual spans, on both the GenAI-native spans of `ai` 7 and the translated spans of earlier versions. Requires `@glassflow-ai/rius` 0.6.0 or later; earlier versions did not list the `ai` 7 system-prompt and tool-call keys as content. ## Verify Run one `generateText` call, then open the trace in the console. The span shows the resolved model, input and output token counts, and a cost, nested under an agent span for the call. Wrap the call in [`observe`](/rius/sdk/tracing#tracing-functions-with-observe) to see it inside your agent's run instead of as a standalone trace. If no spans appear on `ai` 7, check the process log: Rius warns at `init()` when it finds `ai` 7 without `@ai-sdk/otel`, because that combination produces no spans at all. On `ai` 5 and 6, the usual cause is a call without `experimental_telemetry: { isEnabled: true }`. In both cases `await client.ready` lists `vercel-ai` when the integration attached. --- # OpenAI Agents SDK Trace agents built with the [OpenAI Agents SDK](https://openai.github.io/openai-agents-python/) with Rius: every model call the framework makes arrives as a generation with tokens and cost, and a thin layer of `observe` wrappers gives the run and its tools their shape. This guide covers the Python SDK; the runnable example behind it lives in [agent-observability-examples](https://github.com/glassflow/agent-observability-examples/tree/main/frameworks/openai-agents). ## How coverage works The framework drives the OpenAI client underneath, so the [`openai` integration](/rius/sdk/integrations/openai) captures its model calls without any framework-specific code. Two things the framework keeps to itself need one line each: - **The run structure.** The agent loop, tool executions, and handoffs run inside the framework; auto-instrumentation only sees the client calls that come out of it. Wrapping the entrypoint and the tool bodies with [`observe`](/rius/sdk/tracing) puts that structure in the trace. - **The built-in tracing.** The framework ships its own tracing, which uploads to the OpenAI platform and is independent of OpenTelemetry. Disable it with `set_tracing_disabled(True)` if Rius should be the single telemetry path; leaving it on double-reports to two backends but does not interfere with Rius. ## Setup ```bash pip install "glassflow-rius[openai]" openai-agents ``` ```python import rius from agents import Agent, Runner, function_tool, set_tracing_disabled from rius import SpanKind rius.init(api_key="ri_...", service_name="my-agent") set_tracing_disabled(True) @function_tool @rius.observe(kind=SpanKind.TOOL) def account_status(email: str) -> str: """Fetch a customer's account standing by email.""" return lookup(email) support_agent = Agent( name="support_agent", instructions="Answer support questions; check accounts with the tool.", tools=[account_status], model="gpt-5-mini", ) @rius.observe(name="handle-ticket", kind=SpanKind.AGENT) def handle_ticket(ticket: str) -> str: result = Runner.run_sync(support_agent, ticket) return str(result.final_output) ``` The decorator order on tools matters: `@function_tool` outermost, `observe` on the function body. The framework reads the function signature for its tool schema, and the TOOL span parents under the run through ambient context. ## What lands where | In the framework | In the trace | |---|---| | Your entrypoint around `Runner.run()` | The root `AGENT` span (your `observe` wrapper) | | A model call | An `LLM` generation with model, tokens, cost, TTFT | | A function tool | A `TOOL` span (your `observe` wrapper on the body) | | A handoff | No span of its own; see blind spots | A run that crosses a handoff looks like this (real trace from the example, `openai-agents` 0.22.0): ```text handle-ticket AGENT 9.8s ├─ Response LLM 2.3s triage decides to hand off ├─ Response LLM 2.8s billing agent decides to call the tool ├─ account_status TOOL 0ms └─ Response LLM 4.6s billing agent answers ``` ## Blind spots Verified against `openai-agents` 0.22.0: - **Handoffs produce no span.** A handoff is visible only as consecutive generations belonging to different agents. If handoff boundaries matter to you, add an `observe` wrapper per agent entry or use the framework's `RunHooks` to open spans at agent boundaries. - **Generation span names are generic.** Responses API calls are all named `Response`; which agent spoke is not visible from the span name. - **Hyphens in agent names** get rewritten in the generated handoff tool name and the framework warns on every run; use underscores. ## Sessions One conversation is one session: scope each run with [`rius.session()`](/rius/sdk/tracing#sessions), reusing your conversation or ticket id, so every turn on the same conversation groups together. ## Verify Run one request that calls a tool, then open the trace in the console: the root `AGENT` span, the `LLM` generations with model, tokens, and cost, and your named `TOOL` spans should all be there. Streamed runs need usage enabled on the underlying client to carry token counts; see the [OpenAI integration](/rius/sdk/integrations/openai) for the `include_usage` note that applies here too. --- # Pydantic AI Trace agents built with [Pydantic AI](https://ai.pydantic.dev/) with Rius: the framework is OpenTelemetry-native and emits its own spans for agent runs, model requests, and tool calls, so the whole structure arrives with no wrappers at all. This guide covers the Python framework; the runnable example behind it lives in [agent-observability-examples](https://github.com/glassflow/agent-observability-examples/tree/main/frameworks/pydantic-ai). ## How coverage works This integration works the other way around from the client-library ones: no auto-instrumentation extra is involved. `rius.init()` installs the global OpenTelemetry tracer provider, and `Agent.instrument_all(True)` tells Pydantic AI to emit its spans through it. The framework provides the run root, the generations, and the tool spans itself; Rius reads its OpenTelemetry GenAI attributes natively and computes cost server-side. ## Setup ```bash pip install glassflow-rius pydantic-ai ``` No extra is needed. If your project uses the base SDK only, that is enough. ```python import rius from pydantic_ai import Agent rius.init(api_key="ri_...", service_name="my-agent") Agent.instrument_all(True) support_agent = Agent( "openai:gpt-5-mini", instructions="Answer support questions; check accounts with the tool.", ) @support_agent.tool_plain def account_status(email: str) -> str: """Fetch a customer's account standing by email.""" return lookup(email) with rius.session(conversation_id): result = support_agent.run_sync(ticket) ``` `instrument_all` switches instrumentation on for every agent; per-agent control and content settings live on the framework's `InstrumentationSettings`. ## What lands where | In the framework | In the trace | |---|---| | An agent run | The root span, named `invoke_agent ` | | A model request | A generation named `chat `, with tokens and cost | | A tool call | A span named `execute_tool ` | A run that calls a tool looks like this (real trace from the example, `pydantic-ai-slim` 2.36.0): ```text invoke_agent support_agent 6.0s ├─ chat gpt-5-mini 3.3s decides to call the tool ├─ execute_tool search_knowledge_base 0ms └─ chat gpt-5-mini 2.7s answers ``` Compared to frameworks covered through a client-library integration, this is the richer default: spans are named after your agents, models, and tools, and tool calls appear without any wrapping. ## Quirks Verified against `pydantic-ai-slim` 2.36.0: - **Span statuses arrive UNSET** rather than OK on successful spans; the trace status still reads Ok. - **Content capture is framework-side.** What the spans carry (prompts, completions, tool arguments) is controlled by Pydantic AI's `InstrumentationSettings` (for example `include_content`), on top of the SDK's own [privacy controls](/rius/sdk/advanced#privacy-controls) at export time. ## Sessions One conversation is one session: scope each run with [`rius.session()`](/rius/sdk/tracing#sessions), reusing your conversation id. The framework's spans inherit the scope like any other span. ## Verify Run one request that calls a tool, then open the trace in the console: the `invoke_agent` root, `chat` generations with model, tokens, and cost, and `execute_tool` spans should all be there. Using Pydantic AI without the Rius SDK works too: point any OTel setup at the ingest endpoint per [vanilla OpenTelemetry SDKs](/rius/interoperability/otel-sdks). The SDK path above adds the exporter wiring, sessions, heartbeats, and privacy controls for free. --- # CrewAI Trace crews built with [CrewAI](https://docs.crewai.com/) with Rius: the model calls the framework makes arrive as generations with tokens and cost, and `observe` wrappers give the run and its tools their shape. This guide covers the Python framework; the runnable example behind it lives in [agent-observability-examples](https://github.com/glassflow/agent-observability-examples/tree/main/frameworks/crewai). ## How coverage works CrewAI 1.x drives the OpenAI client natively (it is a hard dependency), so the [`openai` integration](/rius/sdk/integrations/openai) captures its model calls. LiteLLM is an optional fallback the framework uses only when it is installed; in that setup, use the [`litellm` integration](/rius/sdk/integrations/litellm) instead. As with other frameworks covered through a client-library integration, the crew structure runs inside the framework where auto-instrumentation cannot see it: wrap the entrypoint and the tool bodies with [`observe`](/rius/sdk/tracing). CrewAI also ships its own tracing product and asks about it interactively on first run; set `CREWAI_TRACING_ENABLED=false` to keep it off non-interactively (CI, containers). ## Setup ```bash pip install "glassflow-rius[openai]" crewai ``` ```python import rius from crewai import Agent, Crew, Task from crewai.tools import tool from rius import SpanKind rius.init(api_key="ri_...", service_name="my-agent") @tool("account_status") @rius.observe(kind=SpanKind.TOOL) def account_status(email: str) -> str: """Fetch a customer's account standing by email.""" return lookup(email) support_agent = Agent( role="Support specialist", goal="Answer support tickets accurately and concisely.", backstory="You resolve product and account questions.", tools=[account_status], llm="gpt-5-mini", ) @rius.observe(name="handle-ticket", kind=SpanKind.AGENT) def handle_ticket(ticket: str) -> str: task = Task( description=f"Resolve this support ticket: {ticket}", expected_output="A short, direct answer.", agent=support_agent, ) return str(Crew(agents=[support_agent], tasks=[task]).kickoff()) ``` The decorator order on tools matters: `@tool` outermost, `observe` on the function body. The TOOL span parents under the run through ambient context. ## What lands where | In the framework | In the trace | |---|---| | Your entrypoint around `crew.kickoff()` | The root `AGENT` span (your `observe` wrapper) | | A model call | An `LLM` generation with model, tokens, cost, TTFT | | A tool | A `TOOL` span (your `observe` wrapper on the body) | | Crews and tasks | No spans of their own; see blind spots | A run that calls a tool looks like this (real trace from the example, `crewai` 1.15.18): ```text handle-ticket AGENT 8.4s ├─ ChatCompletion LLM 3.9s agent decides to call the tool ├─ search_knowledge_base TOOL 0ms └─ ChatCompletion LLM 4.3s agent answers ``` ## Blind spots Verified against `crewai` 1.15.18: - **Crew and task structure produces no spans.** Which task a generation belongs to is not visible from the trace; wrap per-task entrypoints with `observe` if that matters to you. - **Generation span names are generic** (`ChatCompletion`). - **First run prompts interactively** about CrewAI's own tracing; set `CREWAI_TRACING_ENABLED=false` where no terminal is attached. ## Sessions One conversation or job is one session: scope each kickoff with [`rius.session()`](/rius/sdk/tracing#sessions), reusing your own id. ## Verify Run one ticket that calls a tool, then open the trace in the console: the root `AGENT` span, the `LLM` generations with model, tokens, and cost, and your named `TOOL` spans should all be there. Streamed calls need usage enabled on the underlying client to carry token counts; see the [OpenAI integration](/rius/sdk/integrations/openai) for the `include_usage` note. --- # AutoGen Trace agents built with [AutoGen](https://microsoft.github.io/autogen/) (AgentChat) with Rius: the framework emits its own OpenTelemetry spans for agents and tools, and the `openai` integration adds the generations with tokens and cost. This guide covers the Python framework; the runnable example behind it lives in [agent-observability-examples](https://github.com/glassflow/agent-observability-examples/tree/main/frameworks/autogen). ## How coverage works AutoGen combines both coverage paths: - **Framework spans.** AutoGen natively emits `create_agent`, `invoke_agent`, and `execute_tool` spans through the global tracer provider, which `rius.init()` installs. Agent and tool structure arrives with no wrappers. - **Generations.** Model calls go through the OpenAI client (`autogen-ext[openai]`), so the [`openai` integration](/rius/sdk/integrations/openai) captures them with model, tokens, and cost. One `observe` wrapper on the entrypoint groups agent creation and invocation into a single trace per unit of work. Do not wrap AutoGen tool functions with `observe`. The framework executes tools in a detached context, so the wrapper's span cannot find the run and splits off as its own single-span trace. The framework's `execute_tool` spans already cover tools. ## Setup ```bash pip install "glassflow-rius[openai]" "autogen-agentchat" "autogen-ext[openai]" ``` ```python import rius from autogen_agentchat.agents import AssistantAgent from autogen_ext.models.openai import OpenAIChatCompletionClient from rius import SpanKind rius.init(api_key="ri_...", service_name="my-agent") def account_status(email: str) -> str: """Fetch a customer's account standing by email.""" return lookup(email) @rius.observe(name="handle-ticket", kind=SpanKind.AGENT) async def handle_ticket(ticket: str) -> str: agent = AssistantAgent( name="support_agent", model_client=OpenAIChatCompletionClient(model="gpt-5-mini"), tools=[account_status], system_message="Answer support questions; check accounts with the tool.", ) result = await agent.run(task=ticket) return str(result.messages[-1].content) ``` ## What lands where | In the framework | In the trace | |---|---| | Your entrypoint | The root `AGENT` span (your `observe` wrapper) | | Agent construction | A `create_agent ` span (framework) | | An agent run | An `invoke_agent ` span (framework) | | A model call | A `ChatCompletion` generation with tokens and cost | | A tool call | An `execute_tool ` span (framework) | A run that calls a tool looks like this (real trace from the example, `autogen-agentchat` 0.7.5): ```text handle-ticket AGENT 2.8s ├─ create_agent support_agent 0ms └─ invoke_agent support_agent 2.8s ├─ ChatCompletion LLM 2.6s └─ execute_tool search_knowledge_base 0ms ``` ## Quirks Verified against `autogen-agentchat` 0.7.5: - **Tool wrappers split traces** (see the callout above). - **Framework span statuses arrive UNSET** rather than OK on success; the trace status still reads Ok. - **Generation span names are generic** (`ChatCompletion`). ## Sessions One conversation is one session: scope each run with [`rius.session()`](/rius/sdk/tracing#sessions), reusing your conversation id. ## Verify Run one request that calls a tool, then open the trace in the console: the root span, the framework's `invoke_agent` and `execute_tool` spans, and the `ChatCompletion` generation with model, tokens, and cost should all be there. --- # Claude Agent SDK Trace agents built with the [Claude Agent SDK](https://docs.claude.com/en/api/agent-sdk/overview) with Rius. This framework is different from the others on this page's siblings: it drives the Claude Code runtime in a separate process, so no model client runs in your process and auto-instrumentation has nothing to hook. Coverage is manual, and still gives you per-task traces with tokens and cost. The runnable example behind this guide lives in [agent-observability-examples](https://github.com/glassflow/agent-observability-examples/tree/main/frameworks/claude-agent-sdk). ## How coverage works Two pieces, both explicit: - An [`observe`](/rius/sdk/tracing) wrapper makes each task the root `AGENT` span. - A [manual generation](/rius/sdk/tracing#generations-llm-calls) wraps the `query()` loop and is filled from the run's `ResultMessage`: token usage, the real model id, and the collected answer. Cost is then computed server-side as for any generation. ## Setup ```bash pip install glassflow-rius claude-agent-sdk ``` The base SDK is enough; no extra applies. The `claude` CLI must be installed and authenticated. ```python import rius from claude_agent_sdk import ( AssistantMessage, ClaudeAgentOptions, ResultMessage, TextBlock, query, ) from rius import SpanKind rius.init(api_key="ri_...", service_name="my-agent") MODEL = "claude-haiku-4-5" @rius.observe(name="handle-task", kind=SpanKind.AGENT) async def handle_task(task: str) -> str: options = ClaudeAgentOptions(model=MODEL, max_turns=1) parts = [] with rius.start_as_current_generation( "claude_agent_turn", model=MODEL, provider="anthropic", input=task ) as gen: async for message in query(prompt=task, options=options): if isinstance(message, AssistantMessage): parts.extend( b.text for b in message.content if isinstance(b, TextBlock) ) elif isinstance(message, ResultMessage): usage = message.usage or {} gen.set_usage( input_tokens=usage.get("input_tokens"), output_tokens=usage.get("output_tokens"), cache_read_input_tokens=usage.get("cache_read_input_tokens"), # Anthropic's payload still calls the write count "cache creation" cache_write_input_tokens=usage.get("cache_creation_input_tokens"), ) models = list((message.model_usage or {}).keys()) if models: gen.set_response_model(models[0]) answer = "".join(parts) gen.set_output(answer) return answer ``` Use a full model id (`claude-haiku-4-5`), not an alias (`haiku`), for both the CLI option and the generation. Cost is computed from the requested model, and the pricing table matches real model ids only; the alias produces a costless generation. Pass the ResultMessage's cache counts as-is, as the snippet does. Anthropic reports an `input_tokens` that excludes cache reads and writes; Rius detects the exclusive shape and normalizes it server-side, so no client arithmetic is needed and computed cost tracks the ResultMessage's own `total_cost_usd`. Cache-heavy runs (most agent loops) would undercount badly without the two cache fields: a trivial one-turn run can report 10 input tokens next to 24,000 cache tokens. ## What lands where | In the framework | In the trace | |---|---| | A task | The root `AGENT` span (your `observe` wrapper) | | The whole runtime turn | One generation with model, tokens, cost | | The runtime's internal steps | Nothing; see blind spots | A task looks like this (real trace from the example, `claude-agent-sdk` 0.2.148): ```text handle-task AGENT 5.0s └─ claude_agent_turn LLM 5.0s claude-haiku-4-5, tokens + cost ``` ## Blind spots Verified against `claude-agent-sdk` 0.2.148: - **The runtime's inner work is invisible.** Tool calls, sub-turns, and file operations happen inside the Claude Code process and produce no spans; the generation records the turn's totals only. - **Auth is the CLI's.** The runtime uses whatever auth Claude Code has; an exported `ANTHROPIC_API_KEY` takes precedence over a claude.ai login. ## Sessions One conversation is one session: scope each task with [`rius.session()`](/rius/sdk/tracing#sessions). The SDK's own `session_id` (resumable conversations) makes a natural Rius session id. ## Verify Run one task, then open the trace in the console: the root `AGENT` span and the generation with a full model id, tokens, and cost should be there. A generation without cost means an alias was used as the model id. --- # Advanced features Volume and privacy controls for production deployments of the Rius SDK: head sampling to reduce trace volume, and two independent controls over what content leaves your process. All of them are `init()` arguments; none require code changes in your agent. ## Sampling By default the SDK exports every trace. To reduce volume, set a head-sampling rate: ```python rius.init(sample_rate=0.25) # keep ~25% of traces ``` ```typescript init({ sampleRate: 0.25 }) // keep ~25% of traces ``` or via the environment: ```bash export RIUS_SAMPLE_RATE=0.25 ``` ### How it samples The SDK installs a `ParentBased(TraceIdRatioBased(rate))` sampler: - **Whole traces, not individual spans.** The decision is made once per trace, from the trace ID, at the root span. Every child span follows the root's decision, so you never get fragments of a trace. - **Parent decisions are respected.** If a span arrives with tracing context from an upstream service or another instrumentation layer, its sampled flag is inherited rather than re-rolled. The rate only governs traces that start inside your process. - **Head sampling only.** The decision happens at trace start; there is no tail sampling based on errors or latency in the SDK. Values outside `[0.0, 1.0]` are clamped, with a warning log. `0.0` drops everything; `1.0` (the default) keeps everything. ### When to sample Sampling trades visibility for volume. Two rules of thumb: - Keep `1.0` in development and staging; you want every trace while iterating. - In high-traffic production, prefer lowering the rate over disabling tracing: a 10% sample still shows latency and cost distributions, and error spans in sampled traces remain fully detailed. If you need to drop content but keep every trace, use the [privacy controls](#privacy-controls) below instead of sampling. ## Privacy controls The SDK has two independent controls over what content leaves your process: a switch that strips content entirely, and a masking hook that transforms it. Both run at export time, inside your process, before anything is sent. ### capture_content: the content switch ```python rius.init(capture_content=False) # or: export RIUS_CAPTURE_CONTENT=false ``` ```typescript init({ captureContent: false }) // or: export RIUS_CAPTURE_CONTENT=false ``` The default is `True` (content is captured). With `False`, prompt and response content is stripped from spans at export while metadata still flows: model names, token counts, span taxonomy, finish reasons, latencies. You keep cost and performance analytics and give up content-level debugging. The same span in the console, with the switch in each position:
Span Input / Output tab with content captured: the input and output panels show the full request and response
Default (`capture_content=True`): Input / Output carries the full content.
The same span with capture_content off: the input and output panels are empty, while duration, spans, and status remain
`capture_content=False`: the panels are empty; timings, taxonomy, and status still flow.
#### Exactly which attributes are covered The switch (and masking, below) applies to the content attribute families of the SDK itself and of the third-party instrumentation it ships: | Family | Attributes | |---|---| | Rius spans | `input.value`, `output.value` | | Rius generations | `gen_ai.input.messages`, `gen_ai.output.messages` | | Tool definitions | `gen_ai.tool.definitions`, `gen_ai.tool.description`, and the OpenInference `tool.description` / `tool.parameters` (the conventions mark these sensitive: definitions carry prompt engineering, and sometimes credentials in parameter defaults). `gen_ai.tool.name` is identity, not content, and always flows | | GenAI tool calls and system prompt | `gen_ai.system_instructions`, `gen_ai.tool.call.arguments`, `gen_ai.tool.call.result`, as emitted by OpenTelemetry-native instrumentations such as the Vercel AI SDK's `@ai-sdk/otel`. `gen_ai.tool.call.id` is identity and always flows | | GenAI (third-party) | `gen_ai.prompt`, `gen_ai.completion`, and any `gen_ai.prompt.*` / `gen_ai.completion.*` | | Vercel AI SDK | `ai.prompt` and `ai.prompt.*`, `ai.response.text` / `object` / `reasoning` / `toolCalls` / `files`, `ai.toolCall.args` / `result`, `ai.value` / `values`, `ai.documents`, `ai.schema` / `ai.schema.description`. Names, ids, and models (`ai.toolCall.name`, `ai.model.id`) are identity and always flow | | OpenInference | `llm.input_messages`, `llm.output_messages`, and any `llm.input_messages.*` / `llm.output_messages.*` / `llm.prompts.*` / `llm.prompt_template.*`; the tool definitions under `llm.tools` / `llm.tools.*` | | OpenInference request parameters | `llm.invocation_parameters`, whole. The SDK first lifts out the parameters it recognizes (model, temperature, max tokens, stop sequences, `tool_choice`, and the rest of the canonical set), so those survive as `gen_ai.request.*` and `rius.request.tool_choice`; whatever is left in the bag is unclassified and treated as content | | Tool arrays passed as request parameters | `gen_ai.request.tools`, `gen_ai.request.functions`, `rius.request.tools`, `rius.request.functions`. Every other `gen_ai.request.*` and `rius.request.*` key is metadata | | Documents and embeddings | any attribute ending `.document.content` or `.embedding.text` | | MLflow / Traceloop | `mlflow.spanInputs` / `mlflow.spanOutputs`, `traceloop.entity.input` / `traceloop.entity.output` | | Other tracing SDKs (Python) | Langfuse `langfuse.observation.*` and `langfuse.trace.*` input, output, and metadata; Logfire `logfire.msg`; MLflow `mlflow.chat.tools`, `mlflow.trace.intermediate_outputs`, `mlflow.chunk.value`; Traceloop `traceloop.prompt.template` / `template_variables` | | Laminar (both SDKs) | `lmnr.span.input`, `lmnr.span.output`, `lmnr.sdk.raw.response`, and `lmnr.association.properties.metadata` with its members. `metadata.tool_call_id`, `metadata.agent.name`, and `metadata.service.name` are identity and always flow | Indexed keys are matched by prefix, so `llm.input_messages.0.message.content` is covered. Metadata siblings such as `.document.id` and `.document.score` are deliberately not covered, so retrieval analytics survive content stripping. Attributes outside these families (your own `set_attribute()` keys, for example) are never touched; treat custom attributes as content you control. Both controls run after the SDK has normalized auto-instrumented spans onto the canonical keys (see [what the SDK normalizes](/rius/sdk/integrations#what-the-sdk-normalizes)). So a key-aware mask sees an OpenAI or Anthropic call's messages as `gen_ai.input.messages` and `gen_ai.output.messages`, the same keys as a manual generation, rather than the flattened `llm.input_messages.*` keys the instrumentor wrote. If you wrote a mask that matches on `llm.*` keys before 1.0.0, match the canonical keys instead. ### Masking: transform instead of strip When you need content but not the sensitive parts of it, pass a mask callable. It runs on every covered content attribute: ```python def mask(value): return my_pii_scrubber(value) rius.init(mask=mask) ``` ```typescript const mask: Mask = (value) => myPiiScrubber(value) init({ mask }) ``` If the callable accepts a `key` keyword argument (or `**kwargs`), it also receives the attribute name, so you can mask selectively: ```python def mask(value, *, key: str): if key.startswith("gen_ai.input"): return scrub(value) return value rius.init(mask=mask) ``` ```typescript // The second parameter is optional, so a one-parameter mask is also valid. const mask: Mask = (value, context) => { if (context?.key.startsWith('gen_ai.input')) return scrub(value) return value } init({ mask }) ``` #### Semantics you can rely on - **Runs at export, off the hot path.** Masking executes in the background batch thread, on copies of span data, so it never mutates what other processors see and never slows your agent's code. - **Fail closed.** If the mask raises, or returns `None`, or returns something that cannot be serialized, the affected attribute is dropped entirely and a warning is logged. The original value never leaks on any failure path, and the rest of the batch still exports. - **Return types.** Primitives pass through as-is; other objects are serialized to JSON (truncated at 32 KB, the SDK's attribute cap). - **Composition.** `capture_content=False` is applied first; the mask then runs on whatever content attributes remain. The TypeScript SDK covers the same attribute families and composes the two controls the same way, and its mask also runs in the exporter chain rather than on your agent's hot path. It differs on one point: when a mask throws, the affected attribute value becomes the literal string `[mask error]` instead of being dropped, so a broken mask is visible in the trace and the original value still never leaves the process. ### Exceptions, stacktraces, and status messages Errors carry content too, and it matters: a provider error routinely echoes the offending request back in its message, and a stacktrace can carry it in a frame argument. Both SDKs treat the three places that text lands the same way. With content capture off (`capture_content=False` in Python, `captureContent: false` in TypeScript): - The exception event's `exception.message` and `exception.stacktrace` are stripped. The event itself and `exception.type` are kept, so failures stay visible and countable. - The ERROR status description, which `record_exception` and the SDK's own helpers fill with the error text, is dropped. The ERROR status code remains. With a `mask` and content capture on: - The mask runs over the status description in both SDKs. It sees the key `status.description`, so a key-aware mask can treat it specially. - In Python the mask also runs over `exception.message` and `exception.stacktrace` on the exception event. - In TypeScript the mask does **not** reach the exception event: exception messages and stacktraces pass through unmasked. Where error text is as sensitive as the prompt itself, set `captureContent: false`; masking alone will not cover it there. ### Choosing between them - Regulated environment, content must never leave: `capture_content=False`. - Content is useful but contains PII: a mask with your scrubber. - Different rules per attribute family: a key-aware mask. ## Next steps - [Reliability](/rius/sdk/reliability): the export pipeline both controls run inside. - [Troubleshooting](/rius/sdk/troubleshooting): when content or traces go missing unexpectedly. --- # Reliability The design promise of the Rius SDK: **tracing never blocks and never breaks your application**. This page explains the machinery behind that and the knobs you can tune. ## The export pipeline Spans are queued in-process and exported in batches from a background thread (OpenTelemetry's `BatchSpanProcessor` with an OTLP/HTTP exporter). Span creation is an in-memory operation; the network never sits on your agent's hot path. Standard OpenTelemetry environment variables tune the batching: | Variable | Default | Meaning | |---|---|---| | `OTEL_BSP_MAX_QUEUE_SIZE` | `2048` | Spans buffered in memory. When full, new spans are dropped with a warning. | | `OTEL_BSP_SCHEDULE_DELAY` | `5000` (ms) | How often a batch is flushed. | | `OTEL_BSP_MAX_EXPORT_BATCH_SIZE` | `512` | Spans per HTTP request. | | `OTEL_BSP_EXPORT_TIMEOUT` | `30000` (ms) | Timeout per export attempt. | For very chatty agents, raise the queue size before lowering the sample rate; for latency-sensitive shutdowns, lower the schedule delay. ## Retries and failure behavior - Transient failures (connection errors, HTTP 429, 5xx) are retried with exponential backoff and jitter, bounded by the export timeout. - Non-transient failures (other 4xx) are not retried; the batch is dropped and the error logged. - If the backend stays unreachable, spans are dropped and errors are logged. Your application continues normally; exporter exceptions never propagate into application code. ## Flushing and shutdown Pending spans are flushed automatically at interpreter exit. For short-lived scripts and batch jobs, or before a hard kill, flush explicitly: ```python client = rius.init(...) ... client.flush(timeout_millis=30_000) # force an export client.shutdown() # drain, stop the thread, release init() ``` The TypeScript SDK registers no process-exit hook, so flushing is not optional: call it before your process ends. ```typescript const client = init({ /* ... */ }) // ... const delivered = await client.flush() // force an export if (!delivered) console.warn('the most recent span export failed') await client.shutdown() // drain, tear down, release init() ``` Since 0.9.0, `flush()` reports delivery, not just queue drain: it returns `False` on timeout or when the most recent export was rejected (for example a 401 on a bad API key), so `True` means your spans actually left. Earlier releases returned `True` whenever the queue drained, even while every batch was failing. `shutdown()` also releases the global `init()` slot, which is what allows a later `init()` to reconfigure the SDK. The TypeScript pipeline is the same `BatchSpanProcessor` driven by a background timer rather than a thread, tuned by the same `OTEL_BSP_*` variables, and it retries transient failures the same way. Two differences matter in practice: it installs no exit hook, so nothing is flushed for you, and only the first export failure in a process is logged, naming `RIUS_API_KEY` and `RIUS_ENDPOINT` as the likely cause. `flush()` resolving `false` is how you detect later failures. ## Short-lived processes Export happens on a background thread, so what you need to do depends on how your process ends: | Where your code runs | What to do | Why | |---|---|---| | Long-running server (FastAPI, worker, ...) | Nothing | Batches export continuously; the exit hook drains the rest on clean shutdown. | | CLI or batch job | `client.flush()` before exiting (or rely on the exit hook) | Short processes can finish before the first scheduled batch export fires. | | Serverless (Lambda, Cloud Functions, ...) | `client.flush()` at the end of **every** invocation | The runtime freezes the process between invocations; a frozen background thread exports nothing, and the exit hook may never run. | | Fork-based workers (gunicorn, multiprocessing) | Nothing at fork time; `flush()` only if workers are killed hard | The exporter re-creates its background thread in each forked child automatically; only an unclean worker shutdown can lose the last batch. | Never call `flush()` inside request handlers or other hot paths: it blocks until the export completes, which is exactly the stall the background exporter exists to avoid. Flush at process or invocation boundaries only. ## Disabled mode `disabled=True` (or `RIUS_DISABLED=1`) attaches no exporter at all: spans are created and dropped in-process. Instrumented code runs unchanged, which makes it the right kill switch for tests and incident response. ## Heartbeat delivery With the [heartbeat enabled](/rius/sdk/installation#configuration-reference) (the default in both SDKs), the SDK pings the platform for the process's whole lifetime, completely independent of the trace pipeline above. Python uses a daemon thread, TypeScript an unreferenced timer, and neither keeps your process alive. The delivery rules are deliberately the opposite of the exporter's: - **Never queued, never retried.** Liveness is only true fresh; delivering a heartbeat late would be misinformation. A failed ping is dropped, the next interval tries again, and delivery problems warn once and then stay quiet. Like everything in the SDK, failures never raise into your code. - **The first ping is immediate**, so the agent appears in the [Agents view](/rius/platform/agents) at `init()` rather than one interval later. - **A clean stop means calling `shutdown()`.** That sends the final `stopped` ping, which is how the platform tells a clean exit from a crash. Both SDKs also send it when the process ends naturally, and neither installs signal handlers, because a library must not own process signals. An unhandled `SIGTERM` or a `SIGKILL` therefore sends no `stopped` ping and the instance reports `gone`. That is the design: `gone` is the crash signal. In TypeScript the same applies to any abrupt exit, including `process.exit()`, so call `client.shutdown()` if you want the distinction to show up. - **Each process has its own identity.** In Python a forked child re-arms the heartbeat with a new instance ID, so a gunicorn app shows one instance per worker. In TypeScript each process that calls `init()` gets its own instance ID for the same reason: one identity never speaks for two processes. - **Serverless freezes the process.** Between invocations the runtime suspends it, pings stop, and the instance flaps between alive and `stale` or `gone`. Heartbeats are a long-lived-process signal and they are on by default, so set `heartbeat=False` in Python or `heartbeat: false` in TypeScript (or `RIUS_HEARTBEAT=false`) in Lambda-style runtimes. The payload carries no span content: instance ID, agent name, SDK language and version, the IDs of currently open root traces (capped at 32) plus their true count, and the `stopped` flag. `capture_content` and `mask` have nothing to strip here, but note that trace IDs do leave the process in heartbeats, not only in spans. ## Partial spans A span leaves the process when it ends, so a run that is still going is invisible and a run that crashed exports nothing at all. With [`partial_spans`](/rius/sdk/installation#configuration-reference) enabled (`partialSpans` in TypeScript, off by default in both), every sampled span also exports a snapshot at **start**. The platform replaces that snapshot with the real span when the span ends, so a snapshot that is never replaced is the durable record of what a crashed agent was doing. - **Snapshots carry no content, ever.** They are filtered to identity attributes: the span kind and operation, the provider, the tool name, tool call id and tool type, the agent name, id, and version, the data source and `top_k` of a retrieval, the MCP method and protocol version, the session and user ids, the requested output type, and the request settings under `gen_ai.request.*` and `rius.request.*`, such as the model. This is an allowlist rather than a list of things to remove, so content set by third-party instrumentation cannot ride along either. A snapshot is built once at span start and never rebuilt, so content added later in the span's life cannot reach it. - **They share the export pipeline.** Snapshots go through the same batching, retries and masking as finished spans, so nothing about the delivery rules above changes. - **`partial_spans_delay` keeps the volume sane.** Most agent spans live milliseconds, and a snapshot for one of those is superseded almost instantly. With a delay set (`partialSpansDelay` in TypeScript, up to 60 seconds), a snapshot waits and is only sent if the span is still open, so a span that finishes first costs nothing on the wire. Anything worth watching live stays open longer than the delay. - **A snapshot is a zero-duration span.** It carries the same trace and span IDs, parent, name and start time as the final span, with its end time equal to its start time, which is how the platform matches the two. It is marked with the `rius.span.pending` attribute (`glassflow.span.pending` before 1.0.0; the platform reads both). ## Next steps - [Troubleshooting](/rius/sdk/troubleshooting): symptom-first diagnosis when traces go missing. - [Advanced features](/rius/sdk/advanced): sampling, when the volume rather than the pipeline is the problem. --- # Troubleshooting Symptoms first, causes second. Everything here assumes a current SDK: `glassflow-rius` 1.0.0 or newer for Python, `@glassflow-ai/rius` 1.0.0 or newer for TypeScript. Older releases behave the same on the basics, but some log lines quoted below were worded differently. ## No traces are arriving Check in this order: 1. **Is the SDK disabled?** `RIUS_DISABLED=1` (or `true`/`yes`/`on`) silently drops all spans in-process. Also check `disabled=True` in code. 2. **Is sampling set low?** `RIUS_SAMPLE_RATE=0.1` keeps one trace in ten; `0` keeps none. Sampling decides per whole trace, so a sampled-out trace is completely invisible, not partially. 3. **Did the process exit before the batch flushed?** Batches flush every 5 seconds by default. Short scripts can exit between batches if the interpreter is killed rather than exiting cleanly; call `client.flush()` at the end. Serverless invocations should always flush explicitly. Since 0.9.0, `flush()` returning `True` confirms delivery, not just an empty queue: it returns `False` when the queue drained but the last export was rejected. 4. **Endpoint and key.** Since 0.9.0 the SDK diagnoses these itself, as warnings on the `rius.*` loggers: - `init()` warns immediately when no API key is configured and the SDK would export to the managed platform. - A one-shot background connectivity check at `init()` warns when the endpoint rejects your key (HTTP 401/403, check `RIUS_API_KEY`) or cannot be reached at all (check `RIUS_ENDPOINT`). - The first failed export logs a warning saying traces are not being delivered; repeats log at DEBUG until an export succeeds, and recovery logs at INFO. If you see none of these, raise your log level; the SDK warns but never raises in your code. 5. **Configuration still under `GLASSFLOW_*` names?** From 1.0.0 the Python SDK reads only the `RIUS_*` environment variables (the TypeScript SDK never read the old names). A `GLASSFLOW_API_KEY` or `GLASSFLOW_ENDPOINT` left in your environment is ignored, so the SDK exports without a key or to the default endpoint, and nothing arrives in your workspace. Rename them; see the [configuration reference](/rius/sdk/installation#configuration-reference). ## "init() called again" warning The global OpenTelemetry provider is write-once. A second `init()` returns the existing client unchanged and logs this warning. If you genuinely need to reconfigure, call `client.shutdown()` first; if you need a parallel pipeline, use `init(set_global=False)`. ## An instrumentation is not producing spans - The extra (Python) or optional package (TypeScript) must be installed in the same environment (`pip install "glassflow-rius[openai]"`, or `npm install @arizeai/openinference-instrumentation-openai`). A requested-but-missing integration logs a warning at `init()` time. - The instrumented library must be installed too. In Python a missing one logs a `DependencyConflict`, see [init() logs a DependencyConflict](#init-logs-a-dependencyconflict). - Scoped clients (`set_global=False`) do not auto-instrument; pass `instruments=[...]` explicitly. - If another OpenTelemetry setup already instrumented the library, the SDK leaves it alone by design; its spans go wherever that setup exports. - **TypeScript, CommonJS apps: require the traced package before `init()`.** The SDK patches the build of a provider or MCP SDK your process actually uses, so CommonJS and pure-ESM applications both get spans. The one pattern it cannot repair is a CommonJS `require` of `openai`, `@anthropic-ai/sdk`, or `@modelcontextprotocol/sdk` that happens only after `init()`: those calls stay untraced even though `await client.ready` lists the integration. Move the require above `init()`, where applications naturally place it, or trace the affected calls with [manual generations](/rius/sdk/tracing#generations-llm-calls). The `langchain` and `vercel-ai` integrations do not patch the package and have no ordering rule. ## init() logs a DependencyConflict ```text DependencyConflict: requested: "anthropic >= 0.84.0" but found: "None" ``` The extra is installed but the library it instruments is not. Extras carry the instrumentation only, so `glassflow-rius[anthropic]` does not install `anthropic`. Rius takes no dependency on provider SDKs on purpose: pinning them would let an observability library dictate the version your model calls run against. Install the library alongside the extra, and that integration starts working on the next `init()`: ```bash pip install "glassflow-rius[anthropic]" anthropic ``` The message comes from OpenTelemetry's instrumentation base class, so it names the version range the instrumentation supports and `None` for what it found. Nothing else breaks: tracing continues, and only the integration whose library is missing stays off. If you meant not to have that library, drop the extra as well, or list the ones you want with `init(instruments=[...])` so the SDK never tries the others. ## Content is missing from spans - `capture_content=False` (or `RIUS_CAPTURE_CONTENT=false`) strips prompt/response content at export while keeping metadata. See [Privacy controls](/rius/sdk/advanced#privacy-controls) for exactly which attributes are covered. - A masking callable that raises or returns `None` drops the affected attribute entirely, by design (fail closed), with a warning log. ## Long agent spans lose their model, tools, or usage An auto-instrumented agent span that looks complete for the first few turns and then loses its model, request parameters, tool definitions, system prompt, token usage, or output has hit OpenTelemetry's per-span attribute count limit. `init()` raises it to 4096, so check whether `OTEL_SPAN_ATTRIBUTE_COUNT_LIMIT` or `OTEL_ATTRIBUTE_COUNT_LIMIT` is set in your environment to something lower: a value you set wins. See [Span attribute limit](/rius/sdk/installation#span-attribute-limit). ## Queries or alerts stopped matching after upgrading to 1.0.0 1.0.0 changed four things a saved search, dashboard filter, or alert can match on: - **Span names.** Unnamed `TOOL`, `AGENT`, `RETRIEVER`, `LLM`, and `EMBEDDING` spans are now named after their operation and target, such as `execute_tool search_orders`, instead of after the function. An alert filtered on **Step** (the span name) needs the new name, or pass `name` explicitly to keep the old one. See [Span names and identity](/rius/sdk/tracing#span-names-and-identity). - **Request parameters.** `model_parameters` keys land on their canonical `gen_ai.request.*` key, or under `rius.request.*` when the conventions do not define them. For example, `response_format` is now `rius.request.response_format`. See [Request parameters](/rius/sdk/tracing#request-parameters). - **Retrieval operation.** `RETRIEVER` spans carry `gen_ai.operation.name` `retrieval`, so update filters on the old operation name. - **JSON spacing (Python).** JSON-valued attributes are written compact, `{"type":"json_object"}` rather than `{"type": "json_object"}`, so a text match on the old spacing stops matching. Auto-instrumented spans also leave the SDK with the canonical GenAI keys in place of the instrumentor's `llm.*` keys, so query the canonical ones, for example `gen_ai.usage.input_tokens` rather than `llm.token_count.prompt`. ## Token or cost totals look doubled Trace and workspace totals add up tokens and cost over every span that carries them. When two instrumentation layers both record one model call, such as LangChain over the `openai` client, LiteLLM over the `openai` client, or the Vercel AI SDK's `invoke_agent` span over its `chat` steps, that call is counted twice. See [Known limitations](/rius/sdk/integrations#known-limitations) for which layer to keep. ## Values look truncated Inputs, outputs, messages, tool results, and serialized objects are capped at 32 KB in both SDKs, with an explicit `…(truncated)` suffix. This is a fixed safety limit on attribute size: a multi-megabyte tool result would otherwise become a multi-megabyte span. The cap applies to the serialized text, so a large object is cut once it is rendered to JSON. ## Spans are dropped under load The in-memory queue holds 2048 spans by default; overflow is dropped with a warning. Raise `OTEL_BSP_MAX_QUEUE_SIZE`, or lower the volume with [sampling](/rius/sdk/advanced#sampling). See [Reliability](/rius/sdk/reliability) for all batching knobs. ## Next steps - [Reliability](/rius/sdk/reliability): the export pipeline these symptoms come from, and every knob on it. - [Installation and configuration](/rius/sdk/installation): the full configuration reference. --- # Upgrading to 1.0 Version 1.0.0 of both SDKs, `glassflow-rius` for Python and `@glassflow-ai/rius` for TypeScript, finishes the move from the GlassFlow name to Rius and brings span names in line with the OpenTelemetry GenAI conventions. The package names, the Python import (`rius`), and the supported runtimes (Python 3.10+, Node 18+) are unchanged. 1.0.0 needs the Rius platform release of 2026-09-29 or later, which reads the new `rius.span.pending` attribute. The hosted platform already runs it. **Python: rename your `GLASSFLOW_*` environment variables first.** 1.0.0 reads only `RIUS_*` names. A `GLASSFLOW_API_KEY` or `GLASSFLOW_ENDPOINT` left in the environment is ignored, and with no API key the SDK exports nothing. The TypeScript SDK never read the old names. ## Upgrade checklist 1. Rename environment variables from `GLASSFLOW_*` to `RIUS_*`, for example `GLASSFLOW_API_KEY` to `RIUS_API_KEY` and `GLASSFLOW_ENDPOINT` to `RIUS_ENDPOINT` (Python only). 2. Upgrade the package: ```bash pip install --upgrade "glassflow-rius>=1.0.0" npm install @glassflow-ai/rius@^1.0.0 ``` 3. TypeScript with the Anthropic OpenInference instrumentation: upgrade `@arizeai/openinference-instrumentation-anthropic` to `^0.2.7` or later, the first version that reports prompt-cache tokens. 4. Review saved searches, alerts, and dashboards that match on span names, operation names, or `gen_ai.request.*` keys. The tables below list what moved. 5. If you run Langfuse, Traceloop, Logfire, MLflow, OpenLIT, or Laminar in the same process, decide whether to turn on the [foreign provider bridge](#other-opentelemetry-sdks-in-the-same-process). ## Breaking changes | What changed | What to do | |---|---| | Python no longer reads `GLASSFLOW_*` environment variables. | Rename them to `RIUS_*`. | | The pending-span attribute is `rius.span.pending`, not `glassflow.span.pending`. | Update any code that imports the constant. | | The tracer scope is `rius`, not `glassflow`. | Update collector or processor rules that filter on the instrumentation scope. | | Unnamed spans follow the GenAI conventions: `chat {model}`, `embeddings {model}`, `execute_tool {tool}`, `invoke_agent {agent}`, `retrieval {data_source}`. `CHAIN` spans keep the function name, and an explicit name still wins. | Update saved searches, alerts, and dashboards keyed on span name, or pass an explicit name. | | `RETRIEVER` spans carry `gen_ai.operation.name="retrieval"` and accept `data_source_id=` (`dataSourceId` in TypeScript). | Update filters on the old operation name. | | `model_parameters` (`modelParameters`) maps 43 aliases onto 15 standard `gen_ai.request.*` keys. Other keys go under `rius.request.*`. | Filter on the standard keys, or on `rius.request.` for the rest. | | TypeScript: the `@arizeai/openinference-instrumentation-anthropic` peer needs `^0.2.7`. | Upgrade that peer dependency. | ### Request parameters that moved A parameter the GenAI conventions do not define no longer lands under `gen_ai.request.*`. The most common one is `response_format`: | 0.x | 1.0 | |---|---| | `gen_ai.request.response_format` | `rius.request.response_format`, as compact JSON | | `gen_ai.request.tool_choice` | `rius.request.tool_choice` | | `gen_ai.request.max_completion_tokens` | `gen_ai.request.max_tokens` | | `gen_ai.request.stop` | `gen_ai.request.stop_sequences` | See [Request parameters](/rius/sdk/tracing#request-parameters) for the full mapping rules. ## Behaviour changes - **Tool names.** Python `TOOL` spans take `tool_name=`, and the TypeScript span helpers take `toolName`, so the tool name no longer comes from the span name. In Python the old form still works but emits a `DeprecationWarning`. - **Attribute limit.** A span can carry up to 4096 attributes, up from 128, so long agent spans keep their model, tools, usage, and system prompt. An `OTEL_*` attribute-count limit you set yourself still wins. See [Span attribute limit](/rius/sdk/installation#span-attribute-limit). - **Content capture.** With content capture off, the OpenInference request-parameter bag (`llm.invocation_parameters`) is treated as content and is not sent. Embedding vectors are no longer exported by the Python SDK. - **OpenInference spans** are normalized to the GenAI conventions inside the SDK, so query the canonical keys, for example `gen_ai.usage.input_tokens` rather than `llm.token_count.prompt`. ### Other OpenTelemetry SDKs in the same process When Langfuse, Traceloop, Logfire, MLflow, OpenLIT, or Laminar owns the global tracer provider, Rius can bridge it, so that their spans, often the parents of your LLM calls, reach Rius too. The bridge is off by default. Turn it on with: ```bash export RIUS_BRIDGE_FOREIGN_PROVIDER=1 ``` or in code with `bridge_foreign_provider=True` (Python) or `bridgeForeignProvider: true` (TypeScript). Spans whose parent Rius never saw are flagged `rius.parent.foreign` either way. With content capture off, the content keys those SDKs write are stripped too: Langfuse, Traceloop, Logfire, MLflow, and OpenLIT in Python, and Laminar's `lmnr.*` keys in both SDKs. ## Also new in 1.0 - Context-size attribution on LLM spans, which feeds the context usage view. - `record_exception`, `agent_name` and `agent_id`, the `RIUS_MAIN_AGENT_*` environment variables, a first-token event, the response id, and `service.version`. The full list is in each SDK's changelog on GitHub: [Python](https://github.com/glassflow/rius-sdk-python/releases) and [TypeScript](https://github.com/glassflow/rius-sdk-typescript/releases). ## Next steps - [Troubleshooting](/rius/sdk/troubleshooting#queries-or-alerts-stopped-matching-after-upgrading-to-100): queries or alerts that stopped matching after the upgrade. - [Span names and identity](/rius/sdk/tracing#span-names-and-identity): the naming rules in full. - [Installation and configuration](/rius/sdk/installation): the `RIUS_*` configuration reference. --- # TypeScript reference Generated from the `@glassflow-ai/rius` 1.2.0 type declarations, covering the TypeScript SDK's public API surface. Wording fixes happen upstream in the SDK repository, never here. Most code starts with [`init()`](#init), then [`observe()`](#observe) or the [`startSpan`](#startspan) / [`startGeneration`](#startgeneration) helpers. [`RiusClient`](#riusclient) is the handle `init()` returns; the rest are the option shapes those take. ## getTracer() ```ts function getTracer(): Tracer; ``` The SDK tracer. Scope name is wire-visible; do not parameterize it. ### Returns `Tracer` *** ## init() ```ts function init(options?): RiusClient; ``` Initialize the SDK: build a tracer pipeline that exports OTLP traces and enable every bundled auto-instrumentation whose package is installed. Call it once, as early as possible in your process. A second call while a client is active logs a warning and returns the existing client unchanged; `shutdown()` releases the slot. `init()` is synchronous; await [RiusClient.ready](#ready) if instrumentation must be attached before your first span. The SDK installs no exit hook for SPANS: short-lived processes must call [RiusClient.flush](#flush) before exiting or spans still in the batch queue are lost. (The heartbeat does register a `beforeExit` listener, only to send its final `stopped` ping; it flushes nothing.) ### Parameters | Parameter | Type | | ------ | ------ | | `options?` | [`InitOptions`](#initoptions) | ### Returns [`RiusClient`](#riusclient) *** ## observe() ```ts function observe(fn, options?): (...args) => Promise>>; ``` Wrap a function so each call becomes a span. The returned function takes the same parameters and always returns a Promise of the original's result (a synchronous function becomes asynchronous), so call sites need an `await` but no other change. A wrapper rather than a decorator on purpose: TypeScript decorators apply only to class members, and most agent code is plain functions. ### Type Parameters | Type Parameter | | ------ | | `F` *extends* (...`args`) => `unknown` | ### Parameters | Parameter | Type | | ------ | ------ | | `fn` | `F` | | `options?` | [`ObserveOptions`](#observeoptions) | ### Returns ```ts (...args): Promise>>; ``` #### Parameters | Parameter | Type | | ------ | ------ | | ...`args` | `Parameters`\<`F`\> | #### Returns `Promise`\<`Awaited`\<`ReturnType`\<`F`\>\>\> *** ## registerWorkspace() ```ts function registerWorkspace(alias, apiKey): void; ``` Add (or rotate the key of) a workspace destination on the global client. Requires `init({ workspaces })` to have opted into routing (an empty object opts in with no static routes). Spans started inside `withWorkspace(alias, ...)` are then exported with `apiKey`. ### Parameters | Parameter | Type | | ------ | ------ | | `alias` | `string` | | `apiKey` | `string` | ### Returns `void` *** ## startAsCurrentGeneration() ### Call Signature ```ts function startAsCurrentGeneration(name, fn): Promise; ``` Run `fn` with a generation span active. Auto-ends, records exceptions. Both the name and `options` are optional and the callback stays last, so `startAsCurrentGeneration({ model: "gpt-4o" }, fn)` names the span `chat gpt-4o` for you. #### Type Parameters | Type Parameter | | ------ | | `T` | #### Parameters | Parameter | Type | | ------ | ------ | | `name` | `string` | | `fn` | [`GenerationBody`](#generationbody)\<`T`\> | #### Returns `Promise`\<`T`\> ### Call Signature ```ts function startAsCurrentGeneration( name, options, fn): Promise; ``` Run `fn` with a generation span active. Auto-ends, records exceptions. Both the name and `options` are optional and the callback stays last, so `startAsCurrentGeneration({ model: "gpt-4o" }, fn)` names the span `chat gpt-4o` for you. #### Type Parameters | Type Parameter | | ------ | | `T` | #### Parameters | Parameter | Type | | ------ | ------ | | `name` | `string` | | `options` | [`GenerationOptions`](#generationoptions) | | `fn` | [`GenerationBody`](#generationbody)\<`T`\> | #### Returns `Promise`\<`T`\> ### Call Signature ```ts function startAsCurrentGeneration(options, fn): Promise; ``` Run `fn` with a generation span active. Auto-ends, records exceptions. Both the name and `options` are optional and the callback stays last, so `startAsCurrentGeneration({ model: "gpt-4o" }, fn)` names the span `chat gpt-4o` for you. #### Type Parameters | Type Parameter | | ------ | | `T` | #### Parameters | Parameter | Type | | ------ | ------ | | `options` | [`GenerationOptions`](#generationoptions) | | `fn` | [`GenerationBody`](#generationbody)\<`T`\> | #### Returns `Promise`\<`T`\> ### Call Signature ```ts function startAsCurrentGeneration(fn): Promise; ``` Run `fn` with a generation span active. Auto-ends, records exceptions. Both the name and `options` are optional and the callback stays last, so `startAsCurrentGeneration({ model: "gpt-4o" }, fn)` names the span `chat gpt-4o` for you. #### Type Parameters | Type Parameter | | ------ | | `T` | #### Parameters | Parameter | Type | | ------ | ------ | | `fn` | [`GenerationBody`](#generationbody)\<`T`\> | #### Returns `Promise`\<`T`\> *** ## startAsCurrentSpan() ### Call Signature ```ts function startAsCurrentSpan(name, fn): Promise; ``` Run `fn` with a new span active, so spans created inside it nest under this one across async boundaries. Auto-ends, records exceptions, rethrows. Both the name and `options` are optional, and the callback always comes last: `startAsCurrentSpan(name, fn)`, `startAsCurrentSpan(options, fn)` and `startAsCurrentSpan(fn)` all work, as does the full three-argument form. Omitting the name asks for the conventions' `{operation} {target}` name; see [startSpan](#startspan). #### Type Parameters | Type Parameter | | ------ | | `T` | #### Parameters | Parameter | Type | | ------ | ------ | | `name` | `string` | | `fn` | [`SpanBody`](#spanbody)\<`T`\> | #### Returns `Promise`\<`T`\> ### Call Signature ```ts function startAsCurrentSpan( name, options, fn): Promise; ``` Run `fn` with a new span active, so spans created inside it nest under this one across async boundaries. Auto-ends, records exceptions, rethrows. Both the name and `options` are optional, and the callback always comes last: `startAsCurrentSpan(name, fn)`, `startAsCurrentSpan(options, fn)` and `startAsCurrentSpan(fn)` all work, as does the full three-argument form. Omitting the name asks for the conventions' `{operation} {target}` name; see [startSpan](#startspan). #### Type Parameters | Type Parameter | | ------ | | `T` | #### Parameters | Parameter | Type | | ------ | ------ | | `name` | `string` | | `options` | [`SpanOptions`](#spanoptions) | | `fn` | [`SpanBody`](#spanbody)\<`T`\> | #### Returns `Promise`\<`T`\> ### Call Signature ```ts function startAsCurrentSpan(options, fn): Promise; ``` Run `fn` with a new span active, so spans created inside it nest under this one across async boundaries. Auto-ends, records exceptions, rethrows. Both the name and `options` are optional, and the callback always comes last: `startAsCurrentSpan(name, fn)`, `startAsCurrentSpan(options, fn)` and `startAsCurrentSpan(fn)` all work, as does the full three-argument form. Omitting the name asks for the conventions' `{operation} {target}` name; see [startSpan](#startspan). #### Type Parameters | Type Parameter | | ------ | | `T` | #### Parameters | Parameter | Type | | ------ | ------ | | `options` | [`SpanOptions`](#spanoptions) | | `fn` | [`SpanBody`](#spanbody)\<`T`\> | #### Returns `Promise`\<`T`\> ### Call Signature ```ts function startAsCurrentSpan(fn): Promise; ``` Run `fn` with a new span active, so spans created inside it nest under this one across async boundaries. Auto-ends, records exceptions, rethrows. Both the name and `options` are optional, and the callback always comes last: `startAsCurrentSpan(name, fn)`, `startAsCurrentSpan(options, fn)` and `startAsCurrentSpan(fn)` all work, as does the full three-argument form. Omitting the name asks for the conventions' `{operation} {target}` name; see [startSpan](#startspan). #### Type Parameters | Type Parameter | | ------ | | `T` | #### Parameters | Parameter | Type | | ------ | ------ | | `fn` | [`SpanBody`](#spanbody)\<`T`\> | #### Returns `Promise`\<`T`\> *** ## startGeneration() ### Call Signature ```ts function startGeneration(name, options?): Generation; ``` Create a generation span and return a handle. You MUST call end(). The name is optional; omitted, the span is named `{operation} {model}`. #### Parameters | Parameter | Type | | ------ | ------ | | `name` | `string` | | `options?` | [`GenerationOptions`](#generationoptions) | #### Returns [`Generation`](#generation) ### Call Signature ```ts function startGeneration(options?): Generation; ``` Create a generation span and return a handle. You MUST call end(). The name is optional; omitted, the span is named `{operation} {model}`. #### Parameters | Parameter | Type | | ------ | ------ | | `options?` | [`GenerationOptions`](#generationoptions) | #### Returns [`Generation`](#generation) *** ## startSpan() ### Call Signature ```ts function startSpan(name, options?): Observation; ``` Create a span and return a handle. You MUST call end() (or use `using`). The span is parented to whatever is current but does NOT become current. Because it never becomes current, an AGENT span created here opens no agent scope: a TOOL span started while it is open falls back to the configured agent name for `gen_ai.agent.name` rather than naming this one. Use [startAsCurrentSpan](#startascurrentspan) (or `observe`) where that matters. The name is optional: omit it and the span is named the way the GenAI conventions say to, `{operation} {target}` — `execute_tool get_weather`, `invoke_agent planner`, `retrieval docs-index` — from the attributes it is being created with. A name you pass always wins. #### Parameters | Parameter | Type | | ------ | ------ | | `name` | `string` | | `options?` | [`SpanOptions`](#spanoptions) | #### Returns [`Observation`](#observation) ### Call Signature ```ts function startSpan(options?): Observation; ``` Create a span and return a handle. You MUST call end() (or use `using`). The span is parented to whatever is current but does NOT become current. Because it never becomes current, an AGENT span created here opens no agent scope: a TOOL span started while it is open falls back to the configured agent name for `gen_ai.agent.name` rather than naming this one. Use [startAsCurrentSpan](#startascurrentspan) (or `observe`) where that matters. The name is optional: omit it and the span is named the way the GenAI conventions say to, `{operation} {target}` — `execute_tool get_weather`, `invoke_agent planner`, `retrieval docs-index` — from the attributes it is being created with. A name you pass always wins. #### Parameters | Parameter | Type | | ------ | ------ | | `options?` | [`SpanOptions`](#spanoptions) | #### Returns [`Observation`](#observation) *** ## withSession() ### Call Signature ```ts function withSession(fn): T; ``` Scope every span started inside `fn` to one session id. Pass the application's own id (a conversation id, a job id) to correlate with it; omit it to mint a fresh UUID for the scope. Either way the scope's id is passed to the callback, so it can be logged or handed to the next turn. Nested scopes override outer ones, and an active scope overrides the `init({ sessionId })` default. There is deliberately no process-wide auto-generation: without an id the backend groups each trace as its own session, which stays true in a server handling many users, while an auto-minted global id would merge every user into one. A generated id is only ever scoped to an explicit callback, where "this is one session" is the caller's own claim. ```typescript await withSession(conversationId, async () => { await handleTurn(message) // every span of the turn carries session.id }) ``` #### Type Parameters | Type Parameter | | ------ | | `T` | #### Parameters | Parameter | Type | | ------ | ------ | | `fn` | (`sessionId`) => `T` | #### Returns `T` ### Call Signature ```ts function withSession(sessionId, fn): T; ``` Scope every span started inside `fn` to one session id. Pass the application's own id (a conversation id, a job id) to correlate with it; omit it to mint a fresh UUID for the scope. Either way the scope's id is passed to the callback, so it can be logged or handed to the next turn. Nested scopes override outer ones, and an active scope overrides the `init({ sessionId })` default. There is deliberately no process-wide auto-generation: without an id the backend groups each trace as its own session, which stays true in a server handling many users, while an auto-minted global id would merge every user into one. A generated id is only ever scoped to an explicit callback, where "this is one session" is the caller's own claim. ```typescript await withSession(conversationId, async () => { await handleTurn(message) // every span of the turn carries session.id }) ``` #### Type Parameters | Type Parameter | | ------ | | `T` | #### Parameters | Parameter | Type | | ------ | ------ | | `sessionId` | `string` | | `fn` | (`sessionId`) => `T` | #### Returns `T` *** ## withUser() ```ts function withUser(userId, fn): T; ``` Scope every span started inside `fn` to one end user. Pass the application's own identifier for the person the request serves. Prefer an opaque id over an email: it is stored on every span and shown in the console. When only sensitive identifiers exist, hash them first (OTel's `user.hash` / `enduser.pseudo.id` guidance). Nested scopes override outer ones. The id is passed to the callback so it can be logged alongside the work. ```typescript await withUser(request.userId, async () => { await handle(request) // every span of the request carries user.id }) ``` ### Type Parameters | Type Parameter | | ------ | | `T` | ### Parameters | Parameter | Type | | ------ | ------ | | `userId` | `string` | | `fn` | (`userId`) => `T` | ### Returns `T` *** ## withWorkspace() ```ts function withWorkspace(alias, fn): T; ``` Scope every span started inside `fn` to one workspace destination. `alias` names a workspace registered via `init({ workspaces })` or `registerWorkspace()`; the scope's spans are exported with that workspace's API key. Scopes nest and follow async continuations the way all OTel context does, but a trace must stay inside one workspace: enter the scope at a request boundary, before the root span starts. ```typescript await withWorkspace("acme", async () => { await handle(request) // every span of the request lands in acme's workspace }) ``` ### Type Parameters | Type Parameter | | ------ | | `T` | ### Parameters | Parameter | Type | | ------ | ------ | | `alias` | `string` | | `fn` | (`alias`) => `T` | ### Returns `T` *** ## Generation An LLM call. Content uses gen_ai message keys, never input.value. ### Extends - [`Observation`](#observation) ### Constructors #### Constructor ```ts new Generation(span, provider?): Generation; ``` The provider passed at creation; drives the Anthropic input-token summing in [setUsage](#setusage). A bare `new Generation(span)` has none and never sums. ##### Parameters | Parameter | Type | | ------ | ------ | | `span` | `Span` | | `provider?` | `string` | ##### Returns [`Generation`](#generation) ##### Overrides [`Observation`](#observation).[`constructor`](#constructor-1) ### Methods #### \[dispose\]() ```ts dispose: void; ``` Lets callers write `using obs = startSpan(...)`. Sugar over end(). ##### Returns `void` ##### Inherited from [`Observation`](#observation).[`[dispose]`](#dispose-2) #### end() ```ts end(): void; ``` Ends the span after recording the context sizes; idempotent like the base. ##### Returns `void` ##### Overrides [`Observation`](#observation).[`end`](#end-2) #### recordException() ```ts recordException(error): this; ``` Record an error on the span, set ERROR status and `error.type`. This is exactly what the `startAsCurrent*` helpers do on a thrown error, exposed so the manual `start*` path does not have to reach through `.span` to match it. `error.type` is Conditionally Required by the GenAI conventions on every span that ends in an error, and every helper's throw path funnels through here, so this is the one place that sets it. The error's name or class (see errorType), never the message: it must stay low-cardinality and free of echoed content. Accepts `unknown` because that is what a `catch` binding is; a non-Error throwable is wrapped so `recordException` still gets a real Error. ##### Parameters | Parameter | Type | | ------ | ------ | | `error` | `unknown` | ##### Returns `this` ##### Inherited from [`Observation`](#observation).[`recordException`](#recordexception-2) #### recordFirstToken() ```ts recordFirstToken(): this; ``` Mark the arrival of the first streamed token. Records the `gen_ai.first_token` event (the timestamp the backend derives TTFT from) and, per the GenAI conventions, the derived `gen_ai.response.time_to_first_chunk` (seconds since span creation) plus `gen_ai.request.stream = true`: a first chunk arriving is what tells the SDK the request streamed. Idempotent: only the first call records, so a streaming loop can call this unconditionally on every chunk without inflating the span. A no-op after the span has ended. ##### Returns `this` #### setAttribute() ```ts setAttribute(key, value): this; ``` Set an arbitrary attribute. Primitives and homogeneous primitive arrays are passed through as the OTel values they are; objects are JSON-encoded and bounded; `undefined` and `null` set nothing, since "no value" is not an empty string. ##### Parameters | Parameter | Type | | ------ | ------ | | `key` | `string` | | `value` | `unknown` | ##### Returns `this` ##### Inherited from [`Observation`](#observation).[`setAttribute`](#setattribute-2) #### setFinishReasons() ```ts setFinishReasons(reasons): this; ``` Why generation stopped (`gen_ai.response.finish_reasons`), e.g. `"stop"`, `"length"`, `"tool_calls"`. The convention is a list; a single reason is wrapped so callers do not have to. ##### Parameters | Parameter | Type | | ------ | ------ | | `reasons` | `string` \| `string`[] | ##### Returns `this` #### setInput() ```ts setInput(value): this; ``` Record the request messages (`gen_ai.input.messages`), normalised to the GenAI `{role, parts}` shape like the Python SDK does: bare strings, OpenAI dicts (including `tool_calls` and tool responses) and multimodal content lists are all accepted. Bare strings default to the `user` role. ##### Parameters | Parameter | Type | | ------ | ------ | | `value` | `unknown` | ##### Returns `this` ##### Overrides [`Observation`](#observation).[`setInput`](#setinput-2) #### setModel() ```ts setModel(model): this; ``` ##### Parameters | Parameter | Type | | ------ | ------ | | `model` | `string` | ##### Returns `this` #### setOutput() ```ts setOutput(value): this; ``` Record the response messages (`gen_ai.output.messages`); bare strings default to `assistant`. ##### Parameters | Parameter | Type | | ------ | ------ | | `value` | `unknown` | ##### Returns `this` ##### Overrides [`Observation`](#observation).[`setOutput`](#setoutput-2) #### setResponseId() ```ts setResponseId(id): this; ``` The provider's identifier for this completion (`gen_ai.response.id`) — OpenAI's `id`, Anthropic's `id`, and so on. A post-call setter and not a creation option for the reason `setModel` is one: the value arrives WITH the response, so no span can carry it at creation and no pending snapshot can either. Recorded verbatim; it is an opaque provider string, and it is not content, so it survives `captureContent: false`. ##### Parameters | Parameter | Type | | ------ | ------ | | `id` | `string` | ##### Returns `this` #### setRetrievedDocuments() ```ts setRetrievedDocuments(documents): this; ``` Record what a retrieval returned, as `gen_ai.retrieval.documents`. The conventions define this as an array of objects, each with an optional `id` and an optional `score`. Identifiers and relevance, never document text, which is why it is not treated as content: it survives `captureContent: false` the way token counts do. Put the retrieved text in `setOutput` if you want it captured, and masking applies to it there. Unlike `dataSourceId` and `topK`, which describe the request and are passed at span creation, this is only knowable once the search has run, so it never reaches a pending snapshot. ##### Parameters | Parameter | Type | | ------ | ------ | | `documents` | `unknown` | ##### Returns `this` ##### Inherited from [`Observation`](#observation).[`setRetrievedDocuments`](#setretrieveddocuments-2) #### setToolDefinitions() ```ts setToolDefinitions(tools): this; ``` The request's tool/function definitions (`gen_ai.tool.definitions`). Serialized verbatim, in whatever shape the provider request used (OpenAI nests each tool under `function`, Anthropic uses top-level `name`/`input_schema`) — no normalization, so what is recorded is exactly what the model was shown. Definitions are content, not identity: they are masked/stripped under `captureContent: false` like messages are. ##### Parameters | Parameter | Type | | ------ | ------ | | `tools` | `unknown`[] | ##### Returns `this` #### setUsage() ```ts setUsage(usage): this; ``` Token usage (`gen_ai.usage.*`). Pass provider-reported values as-is; never pre-add anything. Per the GenAI conventions, `inputTokens` is the total including cached tokens (the cache counts are subsets of it). Anthropic's API reports `input_tokens` excluding the cache counts, and the conventions require the instrumentation to do the summing, so when the generation's provider is `"anthropic"` the emitted total is `inputTokens` plus both cache counts. Every other provider is recorded verbatim. ##### Parameters | Parameter | Type | Description | | ------ | ------ | ------ | | `usage` | \{ `cacheReadInputTokens?`: `number`; `cacheWriteInputTokens?`: `number`; `inputTokens?`: `number`; `outputTokens?`: `number`; `reasoningOutputTokens?`: `number`; \} | - | | `usage.cacheReadInputTokens?` | `number` | Input tokens served from a provider-managed prompt cache. | | `usage.cacheWriteInputTokens?` | `number` | Input tokens written to a provider-managed prompt cache (called "cache creation" by Anthropic). | | `usage.inputTokens?` | `number` | - | | `usage.outputTokens?` | `number` | - | | `usage.reasoningOutputTokens?` | `number` | Output tokens spent on reasoning / extended thinking. A subset of `outputTokens`, never in addition to it: providers already include reasoning tokens in the output total, so pass both as reported and do no arithmetic. | ##### Returns `this` ### Properties | Property | Modifier | Type | Inherited from | | ------ | ------ | ------ | ------ | | `span` | `readonly` | `Span` | [`Observation`](#observation).[`span`](#span-1) | *** ## Observation A handle over a span. Chainable setters; `end()` is idempotent. ### Extended by - [`Generation`](#generation) ### Constructors #### Constructor ```ts new Observation(span): Observation; ``` ##### Parameters | Parameter | Type | | ------ | ------ | | `span` | `Span` | ##### Returns [`Observation`](#observation) ### Methods #### \[dispose\]() ```ts dispose: void; ``` Lets callers write `using obs = startSpan(...)`. Sugar over end(). ##### Returns `void` #### end() ```ts end(): void; ``` ##### Returns `void` #### recordException() ```ts recordException(error): this; ``` Record an error on the span, set ERROR status and `error.type`. This is exactly what the `startAsCurrent*` helpers do on a thrown error, exposed so the manual `start*` path does not have to reach through `.span` to match it. `error.type` is Conditionally Required by the GenAI conventions on every span that ends in an error, and every helper's throw path funnels through here, so this is the one place that sets it. The error's name or class (see errorType), never the message: it must stay low-cardinality and free of echoed content. Accepts `unknown` because that is what a `catch` binding is; a non-Error throwable is wrapped so `recordException` still gets a real Error. ##### Parameters | Parameter | Type | | ------ | ------ | | `error` | `unknown` | ##### Returns `this` #### setAttribute() ```ts setAttribute(key, value): this; ``` Set an arbitrary attribute. Primitives and homogeneous primitive arrays are passed through as the OTel values they are; objects are JSON-encoded and bounded; `undefined` and `null` set nothing, since "no value" is not an empty string. ##### Parameters | Parameter | Type | | ------ | ------ | | `key` | `string` | | `value` | `unknown` | ##### Returns `this` #### setInput() ```ts setInput(value): this; ``` ##### Parameters | Parameter | Type | | ------ | ------ | | `value` | `unknown` | ##### Returns `this` #### setOutput() ```ts setOutput(value): this; ``` ##### Parameters | Parameter | Type | | ------ | ------ | | `value` | `unknown` | ##### Returns `this` #### setRetrievedDocuments() ```ts setRetrievedDocuments(documents): this; ``` Record what a retrieval returned, as `gen_ai.retrieval.documents`. The conventions define this as an array of objects, each with an optional `id` and an optional `score`. Identifiers and relevance, never document text, which is why it is not treated as content: it survives `captureContent: false` the way token counts do. Put the retrieved text in `setOutput` if you want it captured, and masking applies to it there. Unlike `dataSourceId` and `topK`, which describe the request and are passed at span creation, this is only knowable once the search has run, so it never reaches a pending snapshot. ##### Parameters | Parameter | Type | | ------ | ------ | | `documents` | `unknown` | ##### Returns `this` ### Properties | Property | Modifier | Type | | ------ | ------ | ------ | | `span` | `readonly` | `Span` | *** ## RiusClient Handle over a configured tracer pipeline, returned by [init](#init). Exposes the lifecycle operations (`flush`, `shutdown`) and `ready`, which resolves with the auto-instrumentations that attached. ### Methods #### flush() ```ts flush(): Promise; ``` Drains the queue. Resolves false if the most recent export failed. ##### Returns `Promise`\<`boolean`\> #### shutdown() ```ts shutdown(): Promise; ``` Drains and tears down the provider, then releases the global registration so a later init() can reconfigure the SDK. The heartbeat's final `stopped: true` ping is sent before the provider shuts down, so the backend hears "stopped" while the trace pipeline can still export it. Idempotent: `sender.stop()` no-ops on a second call, and the `beforeExit` listener is removed here so repeated init/shutdown cycles never leak listeners. ##### Returns `Promise`\<`void`\> ### Properties | Property | Modifier | Type | Description | | ------ | ------ | ------ | ------ | | `ready` | `readonly` | `Promise`\<`string`[]\> | Resolves with the names of the auto-instrumentations that attached. | *** ## GenerationOptions Options for [startGeneration](#startgeneration) and [startAsCurrentGeneration](#startascurrentgeneration): the model identity and request parameters an LLM span carries. ### Properties | Property | Type | Description | | ------ | ------ | ------ | | `input?` | `unknown` | - | | `model?` | `string` | - | | `modelParameters?` | `Record`\<`string`, `unknown`\> | Request parameters, for example `{ temperature: 0.2, max_tokens: 512 }`, recorded at span creation so they ride pending snapshots. A parameter the GenAI conventions define, under its canonical name or a recognised provider spelling (OpenAI's `max_completion_tokens`, Google's `maxOutputTokens`, a camelCase `topP`), is recorded under its canonical `gen_ai.request.*` key and only that one. Everything else is recorded under `rius.request.`, this SDK's own namespace, with the key otherwise untouched. Values that are not scalars or homogeneous scalar arrays are JSON-encoded; `null` and `undefined` mean "not set" and are skipped. The `model` and `reasoningLevel` options win over a parameter that maps to the same key. | | `operation?` | `string` | Operation name (`gen_ai.operation.name`); default `"chat"`. Set it for `text_completion`, `embeddings` or `generate_content` calls, as the Python SDK's `operation=` allows. | | `outputType?` | `string` | The output modality requested of the model (`gen_ai.output.type`) — `"text"`, `"json"`, `"image"` or `"speech"` per the conventions, which make it Conditionally Required when the request asks for a specific output format. An option rather than a setter because it is a property of the REQUEST: known before the call, so it is set at span creation and reaches pending snapshots. The string is recorded verbatim, not validated against the four members: the enum is open, and a provider's own spelling is still what the caller asked for. | | `provider?` | `string` | - | | `reasoningLevel?` | `string` | Requested reasoning/thinking effort level (`gen_ai.request.reasoning.level`), e.g. OpenAI's `reasoning.effort` values. Provider-defined string, recorded verbatim. Passing `reasoning_effort` through `modelParameters` lands on the same key; this option wins when both are given. | | `tools?` | `unknown`[] | The request's tool/function definitions, recorded immediately via [Generation.setToolDefinitions](#settooldefinitions) — verbatim, any provider shape. | | `userId?` | `string` | End-user identity (`user.id`). Sugar for `withUser`: set on this span at creation and, for the scoped variant, on every span opened inside it. | *** ## InitOptions Options accepted by [init](#init), extending the shared configuration. ### Extends - [`RiusOptions`](#riusoptions) ### Properties | Property | Type | Description | Inherited from | | ------ | ------ | ------ | ------ | | `agentName?` | `string` | - | [`RiusOptions`](#riusoptions).[`agentName`](#agentname-2) | | `apiKey?` | `string` | - | [`RiusOptions`](#riusoptions).[`apiKey`](#apikey-1) | | `bridgeForeignProvider?` | `boolean` | What to do when another SDK already holds the OpenTelemetry global tracer provider at `init()` (`RIUS_BRIDGE_FOREIGN_PROVIDER`; off by default). Off, Rius keeps to its own provider: LLM spans started inside the other SDK's spans arrive without their parent, flagged `rius.parent.foreign`, counted in the heartbeat, and the first one logs a warning. On, Rius also exports the other SDK's spans (the parents), under Rius's resource identity and subject to Rius's sampling and content settings, and it never modifies what the other SDK exports. Either way the resource records the conflict as `rius.sdk.global_provider`. Off by default: exporting another SDK's spans is consent the caller gives explicitly. | [`RiusOptions`](#riusoptions).[`bridgeForeignProvider`](#bridgeforeignprovider-1) | | `captureContent?` | `boolean` | - | [`RiusOptions`](#riusoptions).[`captureContent`](#capturecontent-1) | | `disabled?` | `boolean` | - | [`RiusOptions`](#riusoptions).[`disabled`](#disabled-1) | | `endpoint?` | `string` | - | [`RiusOptions`](#riusoptions).[`endpoint`](#endpoint-1) | | `heartbeat?` | `boolean` | - | [`RiusOptions`](#riusoptions).[`heartbeat`](#heartbeat-1) | | `heartbeatInterval?` | `number` | Seconds between agent-lifetime heartbeat pings. | [`RiusOptions`](#riusoptions).[`heartbeatInterval`](#heartbeatinterval-1) | | `heartbeatTransport?` | `HeartbeatTransport` | Override the heartbeat HTTP transport. The test seam; prefer this to mocking fetch. | - | | `instrumentModules?` | [`InstrumentModules`](#instrumentmodules-1) | Modules your app imported itself, for the `anthropic` and `openai` integrations: `{ anthropic: { instrumentation, sdk } }`, each field an `import * as` namespace of `@arizeai/openinference-instrumentation-anthropic` and `@anthropic-ai/sdk` (or their `openai` counterparts). An integration given here is enabled from these modules and nothing is resolved for it. For deployments where the SDK cannot load its optional peers itself, such as a pnpm app on a file-tracing host. The `sdk` must be the copy your own client calls use. A module of the wrong shape logs one warning and leaves that integration off. | - | | `mainAgentDescription?` | `string` | A human-readable description of the agent this process is, stamped as `rius.main_agent.description`. This option, then `RIUS_MAIN_AGENT_DESCRIPTION`, then unset. | [`RiusOptions`](#riusoptions).[`mainAgentDescription`](#mainagentdescription-1) | | `mainAgentId?` | `string` | A STABLE identifier for the agent this process is, stamped on the resource as `rius.main_agent.id`. A registry id or a hosted agent's ARN, NOT a transient in-memory or process-local id: a uuid minted at startup identifies a run, not an agent, and would split one agent into a fresh bucket per restart. `service.instance.id` already answers "which process". Absent by default and never defaulted. Resolution: this option, then `RIUS_MAIN_AGENT_ID`, then unset. | [`RiusOptions`](#riusoptions).[`mainAgentId`](#mainagentid-1) | | `mainAgentVersion?` | `string` | The version of the AGENT DEFINITION this process runs — its prompt, tools and policy — stamped as `rius.main_agent.version`. Deliberately NOT `serviceVersion`, which is the version of the build hosting it: the two move independently, and neither is ever derived from the other. Resolution: this option, then `RIUS_MAIN_AGENT_VERSION`, then unset. The OTel environment is not consulted, unlike `serviceVersion`: no convention defines this key, so `OTEL_RESOURCE_ATTRIBUTES` cannot be carrying it. | [`RiusOptions`](#riusoptions).[`mainAgentVersion`](#mainagentversion-1) | | `mask?` | [`Mask`](#mask-2) | - | [`RiusOptions`](#riusoptions).[`mask`](#mask-1) | | `partialSpans?` | `boolean` | - | [`RiusOptions`](#riusoptions).[`partialSpans`](#partialspans-1) | | `partialSpansDelay?` | `number` | Seconds to debounce a pending-span snapshot after span start. | [`RiusOptions`](#riusoptions).[`partialSpansDelay`](#partialspansdelay-1) | | `sampleRate?` | `number` | - | [`RiusOptions`](#riusoptions).[`sampleRate`](#samplerate-1) | | `serviceName?` | `string` | - | [`RiusOptions`](#riusoptions).[`serviceName`](#servicename-1) | | `serviceVersion?` | `string` | The running build's version, stamped on the resource as `service.version`. There is deliberately NO default: `service.name` already shows what a missing value costs, where the `unknown_service` placeholder merges every unconfigured process into one bucket. An absent version is a visibly absent version, so the resource simply omits the key. Resolution: this option, then `RIUS_SERVICE_VERSION`, then `service.version` inside `OTEL_RESOURCE_ATTRIBUTES`, then unset. | [`RiusOptions`](#riusoptions).[`serviceVersion`](#serviceversion-1) | | `sessionId?` | `string` | Process-wide session id, stamped as `session.id` on every span. For one-run-per-process agents; a server handling many sessions scopes each one with `withSession()` instead, which overrides this default. | [`RiusOptions`](#riusoptions).[`sessionId`](#sessionid-1) | | `spanExporter?` | `SpanExporter` | Inject an exporter instead of OTLP. The test seam; prefer this to mocking. | - | | `workspaceExporterFactory?` | [`WorkspaceExporterFactory`](#workspaceexporterfactory-1) | Override how per-workspace exporters are built from an API key. The test seam, like `spanExporter`; defaults to the standard OTLP exporter against the configured endpoint. | - | | `workspaces?` | `Record`\<`string`, `string`\> | Enable multi-workspace routing: a map of alias to API key. Spans started inside `withWorkspace(alias, fn)` are exported with that workspace's key; spans outside any scope use the default `apiKey`. Pass `{}` to opt in with no static routes and register destinations later via `registerWorkspace()`. One trace must stay inside one workspace. | - | *** ## InjectedIntegration One provider integration, handed over by the app rather than resolved by the SDK. Both fields are module namespaces, as produced by `import * as`. ### Properties | Property | Type | Description | | ------ | ------ | ------ | | `instrumentation` | `object` | The module namespace of the OpenInference instrumentation package for this provider (`import * as instrumentation from "@arizeai/openinference-instrumentation-anthropic"`). | | `sdk` | `object` | The module namespace of the provider SDK (`import * as sdk from "@anthropic-ai/sdk"`). It must be the copy the app's own client calls go through, since that is the one that gets patched. | *** ## InstrumentModules The integrations an app can hand to `init()` directly. Only the provider SDK integrations take part; the others are always resolved by the SDK. ### Properties | Property | Type | | ------ | ------ | | `anthropic?` | [`InjectedIntegration`](#injectedintegration) | | `openai?` | [`InjectedIntegration`](#injectedintegration) | *** ## ObserveOptions Options for [observe](#observe). ### Properties | Property | Type | Description | | ------ | ------ | ------ | | `agentId?` | `string` | The invoked agent's identifier (`gen_ai.agent.id`). For a HOSTED agent resource such as a Bedrock agent ARN; an in-process agent leaves it unset. | | `agentName?` | `string` | The agent an AGENT-kind wrapper invokes, set as `gen_ai.agent.name`. Unset, it falls back to the agent name `init()` was given; it is never taken from the wrapped function's name. Ignored on every other kind. It also scopes the call: TOOL spans opened while the wrapped function runs carry this name as the agent that EXECUTED them, which is what the same key means on an execute-tool span. | | `agentVersion?` | `string` | The invoked agent's version (`gen_ai.agent.version`): the version of the agent definition, taken verbatim and never derived from the service version or from the version of the agent this process is. | | `captureInput?` | `boolean` | - | | `captureOutput?` | `boolean` | - | | `dataSourceId?` | `string` | The index, collection or knowledge base a RETRIEVER-kind wrapper searched, set as `gen_ai.data_source.id`. Ignored on every other kind. | | `kind?` | [`SpanKind`](#spankind) | - | | `name?` | `string` | - | | `toolCallId?` | `string` | The id of the model tool-call a TOOL-kind wrapper answers, set as `gen_ai.tool.call.id`. Only the caller has it — a wrapper sees the arguments, never the assistant message that produced them — so it is passed or omitted, never derived. Ignored on every other kind. | | `toolName?` | `string` | The tool name a TOOL-kind wrapper carries as `gen_ai.tool.name`. Defaults to the span name, so a wrapped function whose name IS the tool name needs nothing; pass it when the two differ. | | `toolType?` | `string` | What kind of tool a TOOL-kind wrapper runs, set as `gen_ai.tool.type` (`"function"`, `"extension"`, `"datastore"`). Recorded verbatim and never inferred from the wrapped callable: the wrapper shape says nothing about where the tool actually executes. Ignored on every other kind. | | `topK?` | `number` | How many documents a RETRIEVER-kind wrapper asked for, set as `gen_ai.retrieval.top_k`. Ignored on every other kind. | *** ## RiusOptions Configuration shared by every client. Each option can also come from a `RIUS_*` environment variable; explicit options win over the environment, which wins over defaults. ### Extended by - [`InitOptions`](#initoptions) ### Properties | Property | Type | Description | | ------ | ------ | ------ | | `agentName?` | `string` | - | | `apiKey?` | `string` | - | | `bridgeForeignProvider?` | `boolean` | What to do when another SDK already holds the OpenTelemetry global tracer provider at `init()` (`RIUS_BRIDGE_FOREIGN_PROVIDER`; off by default). Off, Rius keeps to its own provider: LLM spans started inside the other SDK's spans arrive without their parent, flagged `rius.parent.foreign`, counted in the heartbeat, and the first one logs a warning. On, Rius also exports the other SDK's spans (the parents), under Rius's resource identity and subject to Rius's sampling and content settings, and it never modifies what the other SDK exports. Either way the resource records the conflict as `rius.sdk.global_provider`. Off by default: exporting another SDK's spans is consent the caller gives explicitly. | | `captureContent?` | `boolean` | - | | `disabled?` | `boolean` | - | | `endpoint?` | `string` | - | | `heartbeat?` | `boolean` | - | | `heartbeatInterval?` | `number` | Seconds between agent-lifetime heartbeat pings. | | `mainAgentDescription?` | `string` | A human-readable description of the agent this process is, stamped as `rius.main_agent.description`. This option, then `RIUS_MAIN_AGENT_DESCRIPTION`, then unset. | | `mainAgentId?` | `string` | A STABLE identifier for the agent this process is, stamped on the resource as `rius.main_agent.id`. A registry id or a hosted agent's ARN, NOT a transient in-memory or process-local id: a uuid minted at startup identifies a run, not an agent, and would split one agent into a fresh bucket per restart. `service.instance.id` already answers "which process". Absent by default and never defaulted. Resolution: this option, then `RIUS_MAIN_AGENT_ID`, then unset. | | `mainAgentVersion?` | `string` | The version of the AGENT DEFINITION this process runs — its prompt, tools and policy — stamped as `rius.main_agent.version`. Deliberately NOT `serviceVersion`, which is the version of the build hosting it: the two move independently, and neither is ever derived from the other. Resolution: this option, then `RIUS_MAIN_AGENT_VERSION`, then unset. The OTel environment is not consulted, unlike `serviceVersion`: no convention defines this key, so `OTEL_RESOURCE_ATTRIBUTES` cannot be carrying it. | | `mask?` | [`Mask`](#mask-2) | - | | `partialSpans?` | `boolean` | - | | `partialSpansDelay?` | `number` | Seconds to debounce a pending-span snapshot after span start. | | `sampleRate?` | `number` | - | | `serviceName?` | `string` | - | | `serviceVersion?` | `string` | The running build's version, stamped on the resource as `service.version`. There is deliberately NO default: `service.name` already shows what a missing value costs, where the `unknown_service` placeholder merges every unconfigured process into one bucket. An absent version is a visibly absent version, so the resource simply omits the key. Resolution: this option, then `RIUS_SERVICE_VERSION`, then `service.version` inside `OTEL_RESOURCE_ATTRIBUTES`, then unset. | | `sessionId?` | `string` | Process-wide session id, stamped as `session.id` on every span. For one-run-per-process agents; a server handling many sessions scopes each one with `withSession()` instead, which overrides this default. | *** ## SpanOptions Options for [startSpan](#startspan) and [startAsCurrentSpan](#startascurrentspan). ### Properties | Property | Type | Description | | ------ | ------ | ------ | | `agentId?` | `string` | The invoked agent's identifier, set as `gen_ai.agent.id`. This key is for a HOSTED agent resource, such as a Bedrock agent ARN; the conventions advise against recording a transient in-memory instance id there, so an in-process agent leaves it unset. Ignored on every other kind. | | `agentName?` | `string` | The agent an AGENT span INVOKES, set as `gen_ai.agent.name`. That is what the key means on an invoke-agent span, where the conventions make it Conditionally Required; on an execute-tool span the same key means the agent DOING the call, which is why this is scoped to AGENT here. Unset, it falls back to the agent name `init()` was given. It is never taken from the span name, unlike the tool name: that fallback exists only because a tool's name and its span name were historically one string, and a wrong agent name mislabels every span beneath it. Ignored on every other kind, where the key would read as "the agent that produced this span" — which is what the resource attribute of the same name says. On the scoped surface this name also becomes the enclosing agent scope, so TOOL spans opened inside the callback carry it as the agent that EXECUTED them. See [startAsCurrentSpan](#startascurrentspan). | | `agentVersion?` | `string` | The invoked agent's version, set as `gen_ai.agent.version`: the version of the agent DEFINITION this span invoked — its prompt, tools and policy. Taken verbatim; the conventions' own examples are `1.0.0` and `2025-05-01`, so there is no one format to hold callers to. Never derived from `service.version` (the build running this process) nor from the main-agent version (the agent this process IS): a process at one version can invoke agents at several others. Ignored on every other kind, like the name and the id it accompanies. | | `attributes?` | `Record`\<`string`, `string`\> | Identity attributes to set at span CREATION rather than after it. Pending snapshots are built at start, so anything a caller would otherwise `setAttribute` first thing (a tool name, say) belongs here to reach them. Content never does: it is not known at start and would bypass masking's assumptions about where content lives. | | `dataSourceId?` | `string` | The index, collection or knowledge base a RETRIEVER span searched, set as `gen_ai.data_source.id`. Ignored on every other kind: the key means the target of a retrieval, and putting it elsewhere would make the attribute mean something different depending on the span. Omitted when not passed, never guessed. | | `input?` | `unknown` | - | | `kind?` | [`SpanKind`](#spankind) | - | | `otelKind?` | `SpanKind` | The OpenTelemetry `SpanKind` FIELD (INTERNAL, CLIENT, …), orthogonal to `kind` above, which is our taxonomy attribute. Conventions set it per operation, so by default it is derived from `kind` (see `otelSpanKind`); set this to override, as the MCP wrapper does for a remote tool call. | | `toolCallId?` | `string` | The id of the model's tool-call message this TOOL span answers, set as `gen_ai.tool.call.id`. Caller-supplied and nothing else: the id belongs to the assistant turn that requested the call, which the SDK never sees, so there is nothing to derive it from and it is omitted rather than invented. Scoped to TOOL, like `toolName`: on any other kind the key would claim a tool call that is not there. | | `toolName?` | `string` | The tool name a TOOL span carries as `gen_ai.tool.name`. Defaults to the span name, which is what a caller who passes nothing meant back when the two were necessarily the same string. Pass it explicitly whenever the span name is not the bare tool name — and prefer passing it INSTEAD of a span name, which gets you the conventions' `execute_tool {tool}` name for free. With neither, the span is named `execute_tool` and carries no tool name: nothing is invented. | | `toolType?` | `string` | What kind of tool this TOOL span ran, set as `gen_ai.tool.type` — the conventions' examples are `"function"`, `"extension"` and `"datastore"`. Caller-supplied, recorded verbatim, never guessed from the callable: a wrapped function is not automatically a `function` tool, since the same wrapper is what an agent-side extension call goes through. Scoped to TOOL, like `toolCallId`. | | `topK?` | `number` | How many documents a RETRIEVER span asked for, set as `gen_ai.retrieval.top_k`. Ignored on every other kind. What came back is not an option here: it is unknown at span creation, so it is recorded afterwards with `Observation.setRetrievedDocuments`. | | `userId?` | `string` | End-user identity (`user.id`). Sugar for `withUser`: set on this span at creation and, for the scoped variant, on every span opened inside it. To attribute a whole request, including auto-instrumented spans, prefer `withUser` around the handler. | *** ## GenerationBody() ```ts type GenerationBody = (generation) => Promise | T; ``` The body of a scoped generation. ### Type Parameters | Type Parameter | | ------ | | `T` | ### Parameters | Parameter | Type | | ------ | ------ | | `generation` | [`Generation`](#generation) | ### Returns `Promise`\<`T`\> \| `T` *** ## Mask() ```ts type Mask = (value, context?) => unknown; ``` Redacts content attribute values at export. Receives the key when it accepts one. ### Parameters | Parameter | Type | | ------ | ------ | | `value` | `unknown` | | `context?` | \{ `key`: `string`; \} | | `context.key?` | `string` | ### Returns `unknown` *** ## SpanBody() ```ts type SpanBody = (observation) => Promise | T; ``` The body of a scoped span. ### Type Parameters | Type Parameter | | ------ | | `T` | ### Parameters | Parameter | Type | | ------ | ------ | | `observation` | [`Observation`](#observation) | ### Returns `Promise`\<`T`\> \| `T` *** ## WorkspaceExporterFactory() ```ts type WorkspaceExporterFactory = (apiKey) => SpanExporter; ``` Workspaces: route spans from one process to per-customer destinations. One client, one provider, one batch pipeline; the *destination* is a context-scoped property. `withWorkspace(alias, fn)` sets an OTel context key (exactly like `withSession`), `WorkspaceSpanProcessor` stamps it as a transient attribute at span start, and `RoutingSpanExporter` partitions each export batch by that attribute, strips it, and forwards every partition to the exporter registered for its alias. Spans started outside any scope go to the default destination. Because the alias rides OTel context, everything started in scope routes together: `observe` wrappers, generations, sessions, and spans created by auto-instrumentation. That is the property a second client could never give, which is why this SDK has no scoped-client mode at all. Two rules the design enforces or warns about: - The routing attribute never reaches the wire. The destination's API key is what tells the backend which workspace a span belongs to; the alias is process-local configuration, so the exporter strips it before delegating. - One trace, one workspace. The backend derives the workspace from the API key per request, so a trace split across scopes would come apart. Starting a span under a different alias than its parent's logs a warning; switch workspaces at request boundaries, not inside a trace. ### Parameters | Parameter | Type | | ------ | ------ | | `apiKey` | `string` | ### Returns `SpanExporter` *** ## SpanKind Observation kind. Values are OpenInference `openinference.span.kind` values, the taxonomy the platform's agent analytics group by. ### Enumeration Members | Enumeration Member | Value | | ------ | ------ | | `AGENT` | `"AGENT"` | | `CHAIN` | `"CHAIN"` | | `EMBEDDING` | `"EMBEDDING"` | | `LLM` | `"LLM"` | | `RERANKER` | `"RERANKER"` | | `RETRIEVER` | `"RETRIEVER"` | | `TOOL` | `"TOOL"` | *** ## VERSION ```ts const VERSION: "1.2.0" = "1.2.0"; ``` --- # Platform Working with the Rius console at [console.rius-glassflow.com](https://console.rius-glassflow.com), task by task: - [Exploring traces](/rius/platform/exploring-traces): the trace list, the Spans tab, search and filters, saved searches, the waterfall, the map view, and span detail. - [Agents](/rius/platform/agents): every agent you run, which of its processes are alive, and the agent page with context, versions, drift, and errors. - [Users](/rius/platform/users): the end users your agents serve, with traces, failures, and cost per user. - [Alerts](/rius/platform/alerts): pre-defined detectors, custom alerts on workspace metrics, the channels firings are delivered to, and the Firings list. - [Monitoring usage and cost](/rius/platform/monitoring): the Home page, with volume, cost, tokens, and errors per period. - [Settings](/rius/platform/settings): switching and creating workspaces, the keys your SDK and collectors authenticate with, members and roles, root-cause analysis, shared views, declared attributes, and data and privacy. - [Plans and billing](/rius/platform/billing): the trial, the plans, and subscribing. Connecting a client, including the **Connect an agent** dialog for headless clients, is covered in the [MCP server docs](/rius/mcp). The console's **MCP** page, with who calls the server, their sessions, the tools they use, the call log, and the keys they connect with, is covered in [Usage and access](/rius/mcp/usage-and-access). --- # Exploring traces The **Traces** page shows every run your agents produce, from the list view down to a single span's attributes. This page walks through finding a trace, reading its status, and inspecting it in the tree and map views. ## Find the trace **Traces** lists every trace in the workspace, newest first, refreshing automatically (the interval selector sits top right). Each row shows the time, status, the root span's name, the agent that produced it, trace ID, span count, error count, token total, computed cost, and latency. Four more columns appear when the traces carry them: **User** (the [end user](/rius/platform/users)), **Sent by** (who owns the API key that sent the trace), **Instance**, and **Version** (the agent version, or the build when there is none). Clicking a user, sender, or agent cell filters the list to it. The **Spans** tab is the same list at span granularity. ![The trace list](/assets/ui_traces_list.png) The time range presets are 15m, 1h, 1d, 7d (the default), 30d, and a custom range. The strip above the list sums up the traces that match your filters: count, error rate, latency percentiles, tokens, and cost. ### The Spans tab **Spans** lists individual spans instead of whole traces, which is quicker when you are after one kind of step, say every tool call or every LLM call to a given model. Filter by kind with the **All kinds** menu (Agent, LLM, Tool, Retriever, Embedding, Chain, Other), by status, or with the same filters as the trace list. Click the Time, Tokens, Cost, or Duration header to sort. The search box matches span names, span IDs, and trace IDs. ![The Spans tab, filtered to the last 7 days](/assets/ui_spans.png) Clicking a trace ID opens that trace with the span highlighted. The **Session** link in a trace's header opens Spans filtered to that session. ## Search and filter The search box matches trace names and IDs (on **Spans**, span IDs too) within the traces already loaded, so load more pages to search further back. For anything else, build filters: 1. Click **Add filter** and pick a **Field**: a trace column, or any span or resource attribute your agents send. Each attribute shows how many spans carry it in the current window. 2. Pick an **Operator**: `is`, `is not`, `is any of`, `is none of`, `exists`, `does not exist`, and for numbers `>`, `≥`, `<`, `≤`, and `between`. 3. Pick a **Value** from the suggestions, or type one and use it as typed. ![Adding a filter: field, operator, and value](/assets/ui_traces_filter_builder.png) Each filter becomes a chip that you can edit or remove, and filters combine with AND. Attribute filters match exact values only; there is no partial match on attributes. Suggested values leave out payload attributes, such as prompts, completions, and tool input and output, and very long values, so type those if you need them. Filters live in the URL, so a copied link opens the same filtered list. An attribute you have not [declared](/rius/platform/settings#attributes) is filtered as text and offers the equality and existence operators; declare it with a type to get the numeric operators and a readable label. ### Filter from a span In a span's **Raw** tab, every attribute has a menu: **Filter traces by this**, **Exclude this value**, **Copy key**, and **Copy value**. Admins also get **Declare this attribute…**, which declares the key for the workspace with a type and a label guessed from the value. ### Saved searches **Saved** on the Traces filter bar keeps searches you come back to. **Save current search…** stores the filters, the search text, the status and agent selections, and the time range. A relative range such as the last 7 days moves with you rather than freezing to the day you saved it. Each saved search is visible to **Only me**, the default, or to **Everyone in this workspace**. Delete one from the same menu. ![Saving a search](/assets/ui_save_search_dialog.png) ## Trace status Status is derived from the spans themselves rather than reported by your agent, and it has three values: | Status | Meaning | Filter value | |---|---|---| | `completed` | The run finished and no span failed. | `completed` | | `failed` | At least one span carries an OpenTelemetry `ERROR` status, normally a recorded exception. | `failed` | | `running…` | The run has started and has no end yet. | `incomplete` | The third state goes by more than one name: the badge reads **running…**, the filter bar calls it `incomplete`, and the MCP trace tools report it as `Incomplete`. All three are the same thing, a span that has started and not ended. ### Recovered runs A `failed` trace whose root span finished without an error of its own is badged **recovered**: child spans errored, the agent retried or fell back, and the run itself completed clean. The errors are still counted, only the verdict changes. The MCP trace tools expose this as `root_status`, the root span's own verdict, alongside `status`; `status=Error` with `root_status=Ok` is the recovered reading, and `root_status=Error` selects the genuine failures. A trace whose root span never arrived has no `root_status`, and the badge reads **recovered?** to say the verdict is a guess. A run only ever reads as **running…** when [partial spans](/rius/concepts#partial-spans) are enabled. Without them a span reaches the platform once, at the moment it ends, so a run is invisible while it is in flight and a crashed run never arrives at all. With them enabled you see the run while it is still going, and if the process dies mid-run the last state it reported stays behind as **running…** rather than disappearing. That makes the status a useful filter in its own right: a trace still showing **running…** long after the work should have finished is a crash, a hang, or a process that was killed before it could report. ## Waterfall view Open a trace to see its spans as a tree on a timeline. Spans are badged by kind (chain, llm, tool), LLM spans show their token counts inline, and failed spans are highlighted along the path from the root to the error. The header summarizes the whole trace: duration, span and error counts, total tokens, and cost, plus the end user, who sent it, the session, the agent version, and the build when the trace carries them. The session links to every span in that session. For an error span, the detail panel leads with the exception and traceback: ![A trace waterfall with an error](/assets/ui_trace_waterfall.png) ## Map view The **Map** tab lays the same trace out as a graph, one node per span, with selectable lenses for latency, cost, tokens, and errors. Use it when the tree gets deep and you want to see where the time or money went at a glance: ![The trace map view](/assets/ui_trace_map.png) Clicking a node in the map lands you on the tree filtered to that node's spans, so the two views work as one: find the hot spot on the map, read its spans in the tree. ## Tools on a trace The trace page carries a few tools for the questions that come up once a trace is open: - **Retry chains.** Back-to-back calls of the same tool or step collapse into one row, `fetch_article · 3 attempts · recovered`, so a retry loop reads as one event instead of a wall of identical spans. Expand the row for the individual attempts. - **Context growth.** For a trace with several LLM calls, a strip above the tree plots input tokens per call in order, which is where a runaway prompt or an unbounded history shows up first. - **Compare runs.** Compare the open trace against another run of the same agent, side by side, to see which steps changed, which were added or dropped, and where the cost or latency moved. - **Export.** Download the loaded trace, or a single span, as JSON for a bug report, a test fixture, or offline analysis. ## Inspect a span Select any span to inspect it. LLM spans get a **Model** section computed from their OpenTelemetry GenAI attributes: provider, requested and response model, input and output tokens, and cost: ![LLM span detail](/assets/ui_span_detail.png) A call that reported no token usage shows a blank cost rather than $0, so it does not look free. When the model's context window is known, the trace and the span also show how much of it was used, including reasoning tokens and the provider preamble. The **Input / Output** tab renders the prompt and completion when the span carries content attributes; see [attribute interoperability](/rius/interoperability/attributes) for the message shape. Content capture is opt-in end to end: if the SDK's [privacy controls](/rius/sdk/advanced#privacy-controls) strip content, or your instrumentation never records it, the tab says so and the rest of the span (timings, tokens, cost) still works. **Raw** shows the span exactly as ingested. ## Share what you found **Share** on the trace list creates a public, read-only link to a frozen window of the current view, useful for handing a failure to a teammate without adding them to the workspace. The link captures the time range, the status filter, and your filter chips at the moment you click, and the page it opens lists the filters it applies. The search text and the agent selection are not part of a shared view. The dialog takes an optional name and an expiry of 24 hours, 7 days, or 30 days, with 7 days as the default. The link is shown once, at creation; copy it then. Links are listed and revoked in [Settings](/rius/platform/settings#shared-views). A shared view carries summary tiles and trace metadata only, never span content: no input or output previews, end user ids, instance ids, session ids, or the API key that sent a trace. ## Next steps - [Monitoring usage and cost](/rius/platform/monitoring): the aggregate view of everything the traces show individually. - [Span attribute reference](/rius/interoperability/attributes): the attributes behind the Model section and the Input / Output tab. --- # Agents The **Agents** page lists every agent sending traces to your workspace. Open an agent to see how it is doing: whether its processes are alive, its failed traces and cost, how full its context window gets, and whether the latest version changed anything. You don't register agents. Rius finds them in your traces and heartbeats. Sessions from the Rius plugin show up as an agent named after the coding agent: `claude-code` for the [Claude Code plugin](/rius/guides/claude-code-plugin), `codex` for [Codex](/rius/guides/codex), and `cursor` for [Cursor](/rius/guides/cursor). ![The Agents list: each agent with its instances, heartbeats, traces, errors, cost, and when it was last seen](/assets/ui_agents.png) Trace figures (Traces, Failed traces, Error rate, Cost, and the rest) count only **finished** traces, so a run shows up in them once every span of it has ended. Running work shows in **Open traces**, on **Instances**, and as **running…** under **Recent traces**. ## What you can answer here ### Which agent is getting worse? Scan the **Errors** and **Cost** columns of the agents list, then open the agent. Check **Drift** for a rising failed rate, TTFT, or cost per trace, and **Exceptions** to see whether it is one cause or several. When one agent is clearly behind the others, that is the one to fix first. ### Did the last release help or hurt? Tag runs with `RIUS_MAIN_AGENT_VERSION`, then compare versions in **Versions** and **Drift**. If the new prompt or model raised the failed rate or cost per trace, you see it from the day it shipped. ### Is this agent on the right model? Put **Cost** and **TTFT p50** next to **Peak usage** in **Context**. An agent that uses a small share of its context window, starts answering slowly, and costs a lot is a candidate for a smaller, faster model. An agent close to 100% peak usage needs a larger window, or less history in each prompt. ### Did it crash, or did it shut down? Check **Instances**. `stopped` means the process exited and sent its final heartbeat. `gone` means it stopped sending heartbeats without one, which usually points to a crash, an out-of-memory kill, or a deploy that sent SIGTERM. ### Are errors actually hurting runs? Compare **Error rate** with **Failed traces**. A high error rate with few failed traces means the agent recovers, for example with retries or fallbacks. That costs time and money but doesn't break the result. A failed trace is a run whose root span ended in error. ## The agents list Each row is one agent: its instances and how many are live, its open traces, and its traces, errors, time to first token, and cost over the selected window, with when it was last seen. Rows with problems come first. An agent that sends traces but no heartbeat is marked **no heartbeat**. Search by agent name, instance ID, or the ID of a trace a live instance has open, then click a row to open the agent's page. ## The agent page The agent page shows one agent from top to bottom: a summary, then instances, context, versions and drift, recent traces, errored traces, exceptions, and lifecycle events. - The **time window** (15m, 1h, 1d, 7d, 30d) in the top right scopes everything except Instances and Open traces, which always show the latest heartbeat. - **Auto-refresh** runs every 10 seconds by default. - Click an instance ID anywhere on the page to show only that instance. ![An agent page](/assets/ui_agent_page.png) ### Summary | Tile | What it shows | |---|---| | **Instances** | Heartbeat instances on record, with how many are live. | | **Open traces** | Traces still running, as of the last heartbeat. | | **Traces** | Finished traces whose root agent is this agent. | | **Failed traces** | Traces whose root span ended in error. | | **Error rate** | Share of traces with at least one errored span, including runs that recovered. | | **TTFT p50** | Median time to first token over the streaming LLM calls, and how many LLM calls were measured ("42 of 55 LLM calls measured"). A dash for an agent that never streams. | | **Sessions** | Sessions these traces belong to. A trace with no session of its own counts as one. | | **Cost** | Total cost and average cost per trace. | **Error rate** and **Failed traces** measure different things. A trace where a span errored but the agent recovered counts toward the error rate, not toward failed traces. For example, 18 traces with 3 recovered and 1 failed give 1 failed trace and a 22% error rate. The tiles and every table below use the same filter, so the numbers match the rows. Embedding calls don't count as LLM calls. ### Instances Instances are the live side of an agent. Every process with heartbeats on reports in regularly, and Rius lists it as one instance: a fresh instance ID per process start, so three replicas of the same agent show as three instances under one name. A long list shows the worst ten first, with a search by instance ID. Status is computed server-side from the last heartbeat; the client is never trusted for it. | Status | Meaning | When | |---|---|---| | `running` | Alive and working | Recent heartbeat, at least one open trace | | `ready` | Alive and idle | Recent heartbeat, no open traces | | `stale` | Missing heartbeats | No heartbeat for 30s | | `gone` | Presumed dead | No heartbeat for 60s, and no final heartbeat | | `stopped` | Shut down | The process sent its final heartbeat before exiting | The difference between `stopped` and `gone` is the one to watch. The SDKs send the final heartbeat on a normal exit, and when you call `shutdown()`. An instance ends as `gone` when the process is killed (SIGTERM from a deploy, SIGKILL, an out-of-memory kill) or exits with `process.exit()` or `os._exit()`. Records age out a week after the last heartbeat, so a `gone` instance stays visible long enough to investigate. Heartbeats tell you whether a process is alive, not whether the agent is stuck. A process that is hung but still sending heartbeats shows as `running`. If this section says **"No heartbeat instances are reporting for this agent"**, Rius is receiving traces but no heartbeats. The rest of the page still works. See [Troubleshooting](#troubleshooting). ### Context **Peak usage** is how much of the model's context window the largest call used. Use it to tell whether the agent is getting close to truncation. Next to it, Rius breaks the prompt into buckets, such as the system prompt, tool definitions, tool calls and results, the tool-use preamble, user and assistant history, the current turn, and **unattributed**. Unattributed covers message framing, text the provider injects, and cached prefixes Rius can't place. Each bucket is the estimated tokens summed over every LLM call in the window. If you see **"nothing attributed"**, no LLM call in the window carried the data needed for the breakdown. Peak usage is still shown. ### Versions **Versions** shows which versions ran in the window, from `RIUS_MAIN_AGENT_VERSION` (the agent definition) or `RIUS_SERVICE_VERSION` (the build). If the agent reports no version, the page says so and tells you which variable to set; see [Set up](#set-up). With two or more versions, **Compare** puts a base version next to another, by default the two most recently introduced with the older as the base. It shows traces, failed rate, cost per trace, latency and time to first token (p50), and tokens per trace side by side, with the change. It warns when either side has fewer than 20 traces, since the difference can be noise. When traces carry both, switch between **Agent version** and **Build**. ### Drift Three charts show how the agent changes over time: **TTFT p50**, **cost per trace**, and **failed rate**. There is one point per minute, hour, or UTC day, depending on the window (per day at the 7d default), and each trace counts in the bucket it started in. Each chart lists its peak and low, and how many buckets are without a value. ### Recent traces The agent's latest traces, newest first, with state, trace name, ID, span count, errors, and duration. Click a trace to open it. **View all in Traces** opens the full list, filtered to this agent. | State | Meaning | |---|---| | **completed** | Finished with no errored spans. | | **recovered** | At least one span errored, but the run's root finished cleanly. | | **failed** | The run's root span ended in error. | | **running…** | Still running. | | **frozen?** | Still running, but the instance running it has gone stale. | ### Errored traces The six newest traces with at least one errored span. That includes recovered and failed traces. **View all in Traces** opens the full list with the matching status filter. ### Exceptions Errored spans grouped by failure type, such as `llm request failed` or `downstream span failed`. Each group shows when it last happened and how many traces and spans it affected. Use it to tell whether many errors come from one cause or from several. Click an instance chip to show only that instance. ### Lifecycle events When each instance started, finished, went quiet, or came back in the window, newest first. It stays empty for agents without heartbeats. ## Set up Heartbeats are on by default in both SDKs, in Python since 0.10.0 and in TypeScript since 0.2.0. If you followed the [Quickstart](/rius/quickstart), your agent is already on this page. These settings fill in the rest: ```python import rius client = rius.init( api_key="ri_...", service_name="checkout-agent", agent_name="checkout-agent", heartbeat_interval=15, ) # ... run your agent ... client.shutdown() # sends the final `stopped` heartbeat ``` A normal interpreter exit sends the final heartbeat too. The SDK installs no signal handlers, so if your process is stopped with SIGTERM, call `client.shutdown()` from your own handler. ```typescript const client = init({ apiKey: 'ri_...', serviceName: 'checkout-agent', agentName: 'checkout-agent', }) // ... run your agent ... await client.shutdown() // sends the final `stopped` heartbeat ``` Node sends the final heartbeat when the event loop empties (`beforeExit`). `process.exit()` and signals skip that, so call `await client.shutdown()` first. Heartbeats need an API key, from `apiKey` or `RIUS_API_KEY`. A client without one, for example one that only sends through your own exporter, sends no heartbeats. | To get | Set | |---|---| | The right agent name | `agent_name` or `RIUS_AGENT_NAME`. Defaults to the service name. See [Naming your agent](/rius/sdk/installation#naming-your-agent). | | `stopped` instead of `gone` when the process is killed | Call `shutdown()` from your signal handler. | | Fewer heartbeats | `heartbeat_interval` (`RIUS_HEARTBEAT_INTERVAL`), 5 to 300 seconds, default 15. Keep it at 15 or below: `stale` (30s) and `gone` (60s) are fixed by Rius, so a longer interval makes a live instance show as stale between heartbeats. | | Versions and version comparison | `RIUS_MAIN_AGENT_VERSION` (the agent definition) and `RIUS_SERVICE_VERSION` (the build). | | No heartbeats | `heartbeat=False` or `RIUS_HEARTBEAT=false`. Disabling the SDK (`disabled=True`) also stops them. | To fill **Versions** and **Drift**, set the versions in the environment: ```bash RIUS_MAIN_AGENT_VERSION=prompt-v12 # the agent definition: prompt, tools, policy RIUS_SERVICE_VERSION=2026.09.29-a41f3c # the build or deploy ``` Rius names an agent from the `rius.main_agent.name` or `gen_ai.agent.name` attribute, and the SDKs set both. Without either, the service name (`service.name`) is the agent name. With a plain OpenTelemetry SDK, set the name as a resource attribute. Heartbeats need the Rius SDK, so everything except Instances and Lifecycle events works: ```bash OTEL_RESOURCE_ATTRIBUTES=rius.main_agent.name=checkout-agent ``` A trace that arrives without a root span gets an inferred root, so it still counts toward the right agent. **Verify in one minute:** start your agent, open **Agents**, and check that it has an instance in `running` or `ready`. Let the process exit and it moves to `stopped`. If it goes to `stale` and then `gone` instead, the process was killed before it could send its final heartbeat. ## Troubleshooting **My agent isn't in the list.** The process sends no agent name and no service name of its own (OpenTelemetry's `unknown_service` placeholder doesn't count). Set a service name or agent name, or set the resource attribute if you use a plain OpenTelemetry SDK. **My run isn't counted yet.** The trace figures count only finished traces. A run appears in them once every span of it has ended; until then it is under **Open traces** and **Recent traces**. **"No heartbeat instances are reporting for this agent."** Traces are arriving but heartbeats aren't. The cause is one of: an SDK older than Python 0.10.0 or TypeScript 0.2.0, `RIUS_HEARTBEAT=false`, the TypeScript SDK started without an API key, or traces coming from something other than the Rius SDK. **Instances end as `gone` after every deploy.** The deploy sends SIGTERM, which skips the final heartbeat. Call `shutdown()` from your SIGTERM handler. **TTFT is a dash, or only some calls are measured.** TTFT only counts streaming LLM calls where the first token was recorded. The tile shows how many that is. **"This agent reports no version."** Set `RIUS_MAIN_AGENT_VERSION` or `RIUS_SERVICE_VERSION`. ## Next steps - [Users](/rius/platform/users): the same traces, grouped by the end user each agent served. - [Exploring traces](/rius/platform/exploring-traces): follow a running instance's open trace. - [Installation and configuration](/rius/sdk/installation): every `init` option, including the heartbeat settings. - [Claude Code plugin](/rius/guides/claude-code-plugin): trace your own Claude Code sessions; each open session is a live instance of `claude-code`. - [Codex (beta)](/rius/guides/codex) and [Cursor (beta)](/rius/guides/cursor): the same plugin for those agents. Open Codex sessions are live instances of `codex`; Cursor sends no heartbeat, so it has no instances. - [MCP tool reference](/rius/mcp/tools): `list_agents`, `agent_lifecycle_events`, `agent_error_groups`, `agent_versions`, and `compare_agent_versions` let an agent query all of this itself. --- # Users The **Users** page is a register of the end users your agents serve: the people or accounts a request was made for, not the members of your Rius organization. Use it to see who is hitting failures, who drives cost, and what one user's recent runs looked like. Like [Agents](/rius/platform/agents), the figures count only **finished** traces: a run appears once every span of it has ended. ## What you can answer here ### What is each customer costing us? Sort the list by **Cost**. The top rows are your most expensive end users for the window. Open one and compare their cost per trace with the agent's average on [Agents](/rius/platform/agents). A user well above average may be asking harder questions, sending longer history, or triggering retries. ### What is a customer's experience like? A user's page shows their **Failed traces**, **Error rate**, and **TTFT p50**: how often they got no result, how often something went wrong behind the scenes, and how quickly the model started answering on their streaming calls. ### A customer says "it didn't work". What happened? Type their exact user ID, click **Find**, then click their row. On their page, check **Failed traces**, then open the trace from the time they wrote in. That gets you from a support ticket to the failing span in a few clicks. ### Is a problem limited to a few users? Sort by **Failed**. If a handful of users account for most of the failures, look at what they have in common, such as account settings, data size, or language, before changing anything that affects everyone. ### Which customers does a change affect? The **Agents** column shows which agents served each user. Check it before you roll out a new prompt or model to one agent, so you know which customers will notice. ### How much of my traffic can I attribute? The line above the list shows how many traces in the window carry an end user, for example "400 of 471 traces carry an end user". Everything else is in the anonymous row. If that row is large, some code paths run outside a user scope; see [Users](/rius/sdk/tracing#users) in the SDK guide. ## How Rius knows the end user A span names its end user with `user.id`, `enduser.id`, or `enduser.pseudo.id`; Rius takes the first one that is set. The SDKs set `user.id` for every span of a request with a user scope; see [Users](/rius/sdk/tracing#users) in the SDK guide. A trace with no end user on any span counts as **anonymous**. Sessions from the Rius plugin for [Claude Code](/rius/guides/claude-code-plugin), [Codex](/rius/guides/codex), and [Cursor](/rius/guides/cursor) carry no end user, so they count as anonymous. To see whose session a trace is, use the **Sent by** column in the trace list. ## The users list ![The Users page](/assets/ui_users.png) The list covers a window of 15m, 1h, 1d, 7d (the default), or 30d and shows, per user, their traces, failed traces, and cost in that window, the agents that served them, and when they were last seen. Sort by traces, failed traces, or cost. The list shows the top 50 users for the chosen sort; to reach anyone else, search by the exact user ID. The **anonymous** row always comes first, and a line above the list says how many of the window's traces carry an end user at all. A row opens that user's page. The **anonymous** row opens the trace list filtered to traces with no end user. ## A user's page Click a user in the list (search for their exact ID to find them) to open their page. It shows how one end user experienced your agents: how many runs they had, whether any failed, what they cost, and which agents served them. ### Header The user ID, with when Rius **first saw** and **last saw** them in the selected window. Like the rest of the console, the page has a time window (15m, 1h, 1d, 7d, 30d) and auto-refresh. **Traces →** opens the full trace list filtered to this user. ### Summary | Tile | What it shows | |---|---| | Traces | This user's finished traces in the window. | | Failed traces | Traces whose root span ended in error. | | Error rate | Share of this user's traces with at least one errored span, including runs that recovered. | | Cost | Total cost, and average cost per trace. | | Sessions | Sessions this user's traces belong to. A trace with no session of its own counts as one. | | TTFT p50 | Median time to first token over this user's streaming LLM calls. In a multi-step agent this is how quickly the model started answering, not the whole wait the user felt. | Compare these with the agent's own numbers on [Agents](/rius/platform/agents). If a user's error rate or cost per trace is well above the agent's, the problem is probably specific to that user: their data, their account settings, or the kind of questions they ask. ### Agents that served this user Up to three agents that handled this user's traces in the window, most first. Click an agent to open its page. Per-agent counts for one user aren't shown yet. ### Recent traces The 8 most recent traces for this user in the window, newest first. Each row shows the time, state (**completed**, **recovered**, **failed**, or **running…**), trace name, ID, agent, span count, errors, and duration. Click a row to open the trace. **View all in Traces** opens the full list, filtered to this user. ### Failed traces The 6 latest traces for this user with at least one errored span, recovered runs included, so this list can be longer than the **Failed traces** tile. **View all in Traces** opens the trace list filtered to this user's errored traces. **Verify in one minute:** run one request inside a user scope with a test ID such as `test-user-1`. Open **Users**, type `test-user-1`, click **Find**, and open the row. Once the trace has finished, the page shows 1 trace, your agent under **Agents that served this user**, and the trace under **Recent traces**. ## Filter traces by user The trace list has a **User** column, and clicking a user filters the list to them. The same filter is available in the filter builder as the `user_id` field, and on the MCP server as the `user_id` argument of the trace tools and in `list_users` and `user_activity_summary`. ## Next steps - [Users](/rius/sdk/tracing#users): attribute spans to the end user in the SDK. - [Exploring traces](/rius/platform/exploring-traces): read one user's traces. --- # Alerts Alerts watch your workspace and notify you when something needs attention: a recurring error, a run that silently failed, an agent stuck in a loop, or a metric crossing a threshold you set. You configure what to watch and where to deliver; Rius evaluates continuously and records every firing until you acknowledge it. Configuring alerting is an admin action: creating, editing, enabling, or disabling alerts, the workspace-wide alerting switch, and everything about distribution channels. Members see the alerts and their firings, and can acknowledge a firing. See [Roles and permissions](/rius/platform/settings#roles-and-permissions). ![The Alerts page](/assets/ui_alerts.png) ## The Alerts page The page has four sections: - **Pre-defined alerts**: curated detectors Rius ships, including [Consistent Error Pattern, Silent Failure, and Tool Loop](/rius/platform/alerts/pre-defined). Enable or disable each one and tune its thresholds on its details page. - **Custom alerts**: rules you [build yourself](/rius/platform/alerts/custom) on workspace metrics, scoped by filters. - **Distribution channels**: where firings get [delivered](/rius/platform/alerts/channels), including webhook, email, and Slack. - **Recent firings**: the newest firings across every alert, newest first. Clicking one opens the firing's own page, and **View all firings** opens the [Firings](#all-firings) page. ## Firings and acknowledgment A **firing** is one occurrence of an alert's condition. Each alert's details page lists its firings with open ones first. Acknowledging a firing marks it handled with your name and time; acknowledged firings stay in the list, dimmed, so the history remains auditable. Clicking a firing opens its own page with the full picture: when it opened, when the condition was last seen, the affected traces, each linked to the trace view, and the delivery list, one row per channel the firing was sent to with the outcome of each attempt. When root-cause analysis is on, the page also carries the analysis agent's report: what failed, since when, and its reading of the cause, written back as soon as the run completes. **View all in Traces** opens the trace list pre-filtered to the firing's signature and time window. ![A firing page](/assets/ui_alert_firing.png) While an alert is enabled, every firing is delivered to each channel attached to that alert. Disabling an alert stops evaluation; its open firings stay as they are until you enable it again. ### All firings The **Firings** page lists every firing across the workspace's alerts, most recently seen first. **Open** is the default and **Resolved** shows the history; an acknowledged firing stays under **Open** until it resolves. The **Has analysis** toggle narrows either list to firings with a root-cause report. ![The Firings page, Resolved tab](/assets/ui_alert_firings.png) Each row shows the firing and the alert it came from, how many times it matched, when it was first and last seen, its [analysis status](#analysis-status), and sample traces (three shown, the rest behind **+N more**). Open firings can be acknowledged from the row with **Ack**. Click **Load more** at the bottom to go further back. ## Firing lifecycle A firing opens the first time an alert's condition matches and stays open while it keeps matching; **last seen** moves forward with each match. Once the condition has stopped matching for two hours, the firing resolves on its own and drops out of the open list; if the same condition comes back later, that is a new firing, unacknowledged. Acknowledging a firing does not close it: it records who saw it and stops any further notifications for it, and the firing still resolves on its own when the condition clears. Rules are evaluated every minute while they have no open firing, and every five minutes while one is open, so timings are approximate to that cadence. Each alert has a **Renotify** setting for how often to repeat the notification while a firing is open and nobody has acknowledged it: **off**, the default, sends one notification per firing; **every N minutes**, from 5 to 1440, repeats it on that interval until the firing is acknowledged or resolves. Each repeat appears as a row in the firing's delivery list. An open firing with renotify on shows when the next reminder goes out. Saving a change to an alert's configuration resolves its open firings and starts evaluating the rule afresh, so a condition that still holds opens a new firing under the new configuration. A rule that keeps failing to evaluate, for example because its query can no longer run, is detected and stopped automatically, and the failure is recorded. One failing rule never holds up the others. The **Alerting** switch at the top of the page is the workspace-wide master switch. Turning it off pauses detection and notifications for every alert at once, without touching each alert's own enabled state; turn it back on and the alerts resume exactly as they were configured. Use it for a planned migration or a noisy incident, when you want silence without unpicking individual rules. It is an admin action. Each alert also has a **Root-cause analysis** switch. When it is on and the workspace has root-cause analysis enabled, every firing of that alert is handed to the analysis agent; see [Root-cause analysis](/rius/platform/settings#root-cause-analysis) for the workspace-level setting. ## Root-cause analysis on demand Admins can run an analysis for any firing with **Run analysis** on the firing page, whatever the alert's switch says and without waiting for the cooldown. It counts as one analysis against the budget. Analyses draw on a monthly budget, shown in the **Intelligence** section of **Settings → Workspace** as used of allowed, with the date it resets. Past the budget, firings are not analyzed and show **Over budget**. A firing whose analysis was accepted but never reported back shows **No report**. ### Analysis status The Firings list and each firing's page show where its analysis stands: | Status | Meaning | |---|---| | **Off** | Analysis is off for this alert or workspace | | **Queued** | Waiting to run | | **Running** | The analysis agent is working on it | | **Report** | Done; the report is on the firing's page | | **Skipped** | Skipped by the cooldown, at most one analysis per service every 5 minutes | | **Over budget** | The workspace's monthly analysis budget is used up | | **Over allowance** | The organization's analyses for this period are used up | | **Auto paused** | The organization has paused automatic analysis for the rest of the period; you can still run one by hand | | **Failed** | The run failed | | **No report** | Accepted, but no report came back | A firing that was never analyzed shows a dash. **Run analysis** is not offered while an analysis is queued or running, or on a firing that already has a report, is over budget, or is over allowance. ## Next steps - [Pre-defined alerts](/rius/platform/alerts/pre-defined): what each detector fires on, and its knobs. - [Custom alerts](/rius/platform/alerts/custom): build your own rules on workspace metrics. - [Distribution channels](/rius/platform/alerts/channels): webhook payloads, email, and the Slack app. --- # Pre-defined alerts Rius ships curated detectors for the failure shapes agents actually exhibit. Each has a details page with a plain-language description of exactly when it fires, a small set of configuration knobs, its attached channels, and its firing history. You cannot delete a pre-defined alert, only disable it. ![Consistent Error Pattern details](/assets/ui_alert_details.png) ## Consistent Error Pattern Errored spans are grouped by service, step, and normalized error message. A group fires when it reaches the configured number of errored spans across the configured number of distinct traces within the rolling window: the same error, in the same service and step, failing repeatedly across runs. A single trace retrying the same step never fires on its own, and spans with an empty error message never alert. Problems this is built to catch: - An expired or rotated provider credential: every model call in one service starts failing with the same 401, run after run. - A deploy that broke one step: the same `KeyError` from the same tool in every run since the rollout. - A rate-limited or degraded upstream: the same 429 or timeout recurring across runs while everything else stays green. | Knob | Default | Meaning | | --- | --- | --- | | Time window | 5 minutes | The rolling window each group is measured over | | Errored spans | at least 3 | Failures of the same error within the window | | Distinct traces | at least 2 | Separate runs the failures must span | | Renotify | off | Repeat the notification every N minutes while the firing is open and unacknowledged; off sends it once | ## Silent Failure Fires when a run reports success while work inside it failed: the trace's root span finishes OK but at least one child span ended with an error. These are the failures nobody notices, because no error surfaces anywhere: the run looks successful, and the answer quietly got worse. Problems this is built to catch: - A search tool times out and the agent answers from its own knowledge instead of surfacing the gap. - Retries are exhausted and the code falls back to a cached value rather than failing loudly. - A sub-agent in a multi-agent pipeline crashes and the orchestrator ships whatever partial answer it already had. One firing per run. Only finished traces are evaluated, so an in-flight run never fires early. | Knob | Default | Meaning | | --- | --- | --- | | Time window | 5 minutes | The rolling window finished traces are scanned over | | Renotify | off | Repeat the notification every N minutes while the firing is open and unacknowledged; off sends it once | ## Tool Loop Fires when the same tool is called with identical parameters at least the configured number of times inside a single trace within the window. Repeated identical calls are the signature of an agent stuck in a loop: it is no longer making progress, just burning tokens. Calls count as identical when the tool name and normalized arguments match. One firing per trace. Problems this is built to catch: - An agent repeating the same search with the same query because no result ever satisfies its stop condition. - A broken tool schema: the model retries the identical call expecting a different outcome, and never gets one. - A planner and executor cycling on the same lookup, making no progress while the token bill grows. | Knob | Default | Meaning | | --- | --- | --- | | Identical calls | at least 2 | Same tool, same parameters, inside one trace | | Time window | 10 minutes | How far back calls within the trace are counted | | Renotify | off | Repeat the notification every N minutes while the firing is open and unacknowledged; off sends it once | ## Next steps - [Custom alerts](/rius/platform/alerts/custom): thresholds on cost, tokens, latency, and errors that the pre-defined set does not cover. - [Distribution channels](/rius/platform/alerts/channels): route firings to webhook, email, or Slack. --- # Custom alerts Custom alerts put a threshold on workspace metrics, optionally scoped by filters. A custom alert is one or more rules, always combined with AND, all evaluated over one shared rolling window. The builder shows a plain-language preview of exactly when the alert will fire, and that sentence becomes the alert's description on its details page. ![The custom alert builder](/assets/ui_custom_alert_builder.png) ## The rule grammar ```text FILTERS Service = checkout-agent (optional, applied before aggregation) RULES avg(Cost) > $0.50 AND count(Errors) > 10 WINDOW 15 minutes (shared by all rules) ``` Rules combine with AND only. There is no OR and no nesting: if you want either-or semantics, create a second alert. ## Filters Filters select which spans feed the rules, before any aggregation. Text fields offer `=`, `≠`, `in`, and `not_in` (none of the listed values), and values are suggested from your workspace's live data. | Field | Matches | | --- | --- | | Service | `service.name` from your instrumentation | | Agent | The agent identity Rius derives for the trace | | Step | The span name | | Model | `gen_ai.request.model` | | Span kind | LLM, tool, chain, retriever, and so on | | Operation | `gen_ai.operation.name`, such as `chat`, `execute_tool`, or `retrieval` | | Session | `session.id` | | Instance | The process instance (`service.instance.id`) of the trace's root span | A **Step** filter matches span names exactly. The 1.0.0 SDKs name unnamed tool, agent, retrieval, and model spans after their operation and target, such as `execute_tool search_orders`, so an alert written against spans from an earlier SDK needs the new name once your agents upgrade; see [Queries or alerts stopped matching](/rius/sdk/troubleshooting#queries-or-alerts-stopped-matching-after-upgrading-to-100). ## Metrics Metrics are typed, and the type decides which aggregations the builder offers. | Metric | Type | Aggregations | Unit | | --- | --- | --- | --- | | Cost | numeric | avg, min, max, p50, p95, p99 | USD | | Input tokens | numeric | avg, min, max, p50, p95, p99 | tokens | | Output tokens | numeric | avg, min, max, p50, p95, p99 | tokens | | Duration | numeric | avg, min, max, p50, p95, p99 | ms | | Time to first token | numeric | avg, min, max, p50, p95, p99 | ms | | Error rate | ratio | rate (a rate is already an aggregate) | 0 to 1 | | LLM error rate | ratio | rate | 0 to 1 | | Errors | event | count, ucount (distinct traces) | count | | Traces | event | count, ucount | count | | LLM calls | event | count, ucount | count | Numeric aggregations use per-trace semantics: `avg(Cost)` is the average cost per trace in the window, not the workspace total. Time to first token and LLM calls are the exception: they are measured per LLM call, so their aggregations are over calls, not traces. An LLM call is an inference call, a span the trace view badges as LLM; agent, tool, retrieval, and embedding spans never count, even when they carry a model. Error rate and LLM error rate are the share of spans, or of LLM calls, that errored in the window, and you compare them against a value between 0 and 1. Comparison operators are `<`, `<=`, `>`, `>=`, and `==`. An alert takes up to 10 filters with up to 50 values each, up to 10 rules, and a window between 5 minutes and 24 hours. The builder also sets the alert's **Renotify** policy, off or every N minutes, described under [Firing lifecycle](/rius/platform/alerts#firing-lifecycle). Two metrics have coverage caveats. Cost is only as complete as your pricing coverage: spans whose model has no known price carry no cost. Time to first token exists only on LLM spans that recorded a first-token event, which requires streaming instrumentation. Firings on either metric surface the coverage ratio so a low-coverage workspace does not silently under-fire. A `Traces count < 1` rule over a generous window doubles as a dead-man switch: it fires when ingestion stops entirely. ## Managing custom alerts Custom alerts get the same details page as pre-defined ones: the generated description, the editable rule, attached channels, and firings. Firings record the observed value of every rule against its threshold, so you can see which condition tripped. Unlike pre-defined alerts, a custom alert can be deleted; deleting it removes its firing history after an explicit confirmation. ## Next steps - [Distribution channels](/rius/platform/alerts/channels): route firings to webhook, email, or Slack. - [Monitoring usage and cost](/rius/platform/monitoring): the same metrics as a summary on Home instead of as a trigger. --- # Distribution channels Channels are the destinations firings get delivered to. You define them once per workspace on the Alerts page, then attach any of them to any alert from that alert's details page (the **Delivers to** section). While an alert is enabled, every firing goes to each of its attached, enabled channels. Channels are admin-only, including viewing them: a member does not see the Distribution channels section or an alert's **Delivers to** list. ![Distribution channels](/assets/ui_alert_channels.png) ## Webhook A webhook channel POSTs a JSON payload to an HTTPS URL you provide. You can add request headers, for example an `Authorization` token your receiver expects; header values are stored encrypted, are write-only, and are never shown again, in the console or over MCP. Every delivery sends one JSON body per firing: ```json { "text": "Consistent Error Pattern: TimeoutError: model call exceeded 60s", "alert_id": "01J9…", "workspace_id": "01J8…", "kind": "consistent_error_pattern", "service": "support-bot", "step": "llm.call", "error": "TimeoutError: model call exceeded 60s", "title": "TimeoutError: model call exceeded 60s", "labels": { "service": "support-bot", "step": "llm.call" }, "occurrences": 14, "runs": 5, "first_seen": "2026-09-03T14:02:11Z", "last_seen": "2026-09-03T15:27:40Z", "sample_trace_ids": ["9f3a2c81…", "b04e11d9…"], "url": "https://eu.console.rius-glassflow.com/…" } ``` `text` is a render-ready one-liner, so the same payload posts usefully to a generic receiver and to chat webhooks. `service`, `step`, and `error` are present when the detector attaches them, and `labels` carries the same values plus any detector-specific keys such as `tool` or `trace_id`. `sample_trace_ids` is a bounded sample (at most 10), never the complete list; follow `url` for the full firing. Timestamps are RFC3339 in UTC. ## Email An email channel sends each firing to every recipient on the channel: a designed HTML mail with a plain-text fallback, a deep link to the firing, and the firing's age alongside its UTC timestamp. Each recipient gets their own copy of the mail, so recipients don't see each other's addresses. Every mail has an unsubscribe link in its footer, and mail clients such as Gmail show their own **Unsubscribe** button for it. That button unsubscribes from this channel at once, without opening the page. ### Unsubscribing The unsubscribe link removes that address from that channel's recipient list. It stops emails from that channel only: other email channels, other workspaces, and Slack and webhook channels are not affected. The footer says so next to the link. - **No Rius account needed.** The link opens a page that names the address, the channel, and the workspace, and the recipient confirms with a button. Opening the page changes nothing. - **Unsubscribe from all.** When the address is also on other email channels in the same workspace, the page offers **Unsubscribe from all alert emails** for that workspace, which removes it from every email channel there. It shows how many other channels the address is on, not their names. - **Admins stay in control.** A workspace admin sees the address gone from the channel's recipients and can add it back. An address that is added back gets mail again. - **The last recipient.** If the last recipient unsubscribes, the channel is disabled and has no recipients. To turn it back on, an admin adds a recipient and then enables the channel. ## Slack Slack delivery uses the Rius Slack app, which you install into your Slack workspace once per Rius workspace: 1. In the new channel dialog, choose **Slack** and click **Add to Slack**. Slack's authorization page opens; the app requests permission to post messages and to list the channels you can pick from. 2. Once the workspace is connected, name the channel and pick the Slack channel to post into. Public channels work as they are. For a private channel, invite the app in Slack first; Rius refuses a channel the app cannot post to rather than saving a channel that will never deliver. The Slack connection is shared: after the first install, additional Slack channels skip straight to the channel picker. Disconnecting the workspace disables every Slack channel that uses it. Channel deliveries are per firing, not batched. A noisy alert posts once per firing; tune the alert's thresholds rather than muting the channel. ## Next steps - [Pre-defined alerts](/rius/platform/alerts/pre-defined): attach your first channel to Consistent Error Pattern. - [Custom alerts](/rius/platform/alerts/custom): build rules that deliver to the same channels. --- # Usage and cost **Home** is the Rius workspace's summary page: how your agents did this period, in volume, cost, tokens, and errors. ![The Home page for a workspace: trace count against the previous period, a needs-you-now list, KPI tiles for spans, LLM calls, duration, cost and tokens, then charts for volume, errors, latency, cost by model, and top exceptions](/assets/ui_home_full.png) The stat tiles compare the selected window (15m / 1h / 1d / 7d / 30d / custom) against the previous one: total traces, average duration, total cost with per-trace and per-1k-token averages, and total tokens. Below them, panels break the period down by error rate, cost by model, and the most active agents. **LLM calls** counts inference calls: the spans the trace view badges as LLM. Agent, tool, and retrieval spans are not counted, even when they carry a model, and neither are embedding calls, although their cost appears in the cost-by-model breakdown. Token and cost totals, by contrast, add up every span that carries usage, so an instrumentation stack that records one call on two nested spans counts it twice; see [Known limitations](/rius/sdk/integrations#known-limitations). Cost is computed server-side from model pricing and the token usage your spans carry; your instrumentation never ships pricing tables. The view refreshes on the same auto-refresh interval as the trace list, so it doubles as a live wallboard during an agent rollout. ## Next steps - [Exploring traces](/rius/platform/exploring-traces): drill from a number on this page down to the run behind it. - [Alerts](/rius/platform/alerts): turn a number you keep checking into a notification instead. - [Sampling](/rius/sdk/advanced#sampling): reduce volume when the numbers get big. --- # Settings Everything under the console's **Settings** page, one section per tab: the workspace itself, its API keys, the organization and its members, the shared views that leave it, the attributes declared for search, the organization's plan, and where the workspace's data is held. A Rius workspace is where your traces live. Every trace your SDK or collector sends belongs to exactly one workspace, determined by the API key it authenticates with. The workspace switcher sits at the top of the sidebar; everything you see in the console (traces, agents, keys, settings) is scoped to the selected workspace. ## Switching and creating workspaces Click the workspace name at the top of the sidebar to open **Switch workspace**. It lists the workspaces in this console's region; type to find one, and if you belong to more than one organization, the list groups them by organization. Switching keeps you in the same section, so Traces opens the other workspace's Traces; from a single trace you land on its trace list. ![The Switch workspace dialog, with Create workspace… disabled at the plan's workspace limit](/assets/ui_workspace_switcher.png) Admins also get **Create workspace…** at the bottom of the list. A new workspace needs a name and a region. The region decides where its traces are stored and can't be changed later. The entry is disabled once the organization reaches its plan's workspace limit. **All workspaces…** opens **Choose a workspace** at [console.rius-glassflow.com](https://console.rius-glassflow.com), which lists your workspaces in every region. ## Workspace **Settings → Workspace** shows the workspace's name and ID. Admins can rename or delete the workspace; members see the name and ID only. Workspace names are up to 60 characters: ![Workspace settings](/assets/ui_settings.png) ## API keys API keys authenticate ingest, requests to `https://ingest.eu.console.rius-glassflow.com` (the SDK's default endpoint). Each key belongs to one workspace: traces sent with it appear there and nowhere else. Create keys from **Settings → API keys** or from the **Get started** page: ![The API keys settings](/assets/ui_api_keys.png) Only admins create and revoke keys. Members see the key list, which carries names and prefixes but no secret material. A key carries the capabilities you pick when you create it. **Send telemetry** (`ingest`), the default, is what the SDK needs. **Query data** (`read`) lets the key read traces and metrics and connect an MCP client; a key with both scopes serves an agent that ships its own traces and queries them. Two further scopes, `alerts:manage` and `channels:manage`, let a headless agent manage alerting; they are minted only from the MCP page's **Connect an agent** dialog, see [headless connections](/rius/mcp#headless-connections). Keys start with `ri_`. Keys minted before the prefix change start with `gf_` and keep working; there is no need to rotate them for the prefix alone. A key can carry an expiry, chosen when it is created: 30 days, 90 days, one year, or never, which is the default. The key list shows each key's expiry and marks keys that are about to expire and keys that have expired. An expired key fails authentication exactly like a revoked one, so treat expiry as a scheduled rotation: mint the replacement before the date, move your agents over, and let the old key lapse. Admins can **Edit** a key to change its name and scopes without re-issuing it. A change applies to MCP connections on the next request, and to ingest within about 30 seconds. Expired keys cannot be edited. The MCP page's [Access tab](/rius/mcp/usage-and-access#access) shows whether each key is active and when it was last used. A key is shown in full exactly once, when it is created; afterwards the console keeps only its name and prefix, and the server stores only a hash. Lose a key and the path is revoke and reissue, there is no recovery. **Revoke** takes effect immediately: in-flight traffic with a revoked key starts failing authentication right away, so rotate by creating the new key first, moving your agents over, then revoking the old one. The one exception is an MCP client already connected with the key, which can keep working for up to a minute because the MCP server caches key validation briefly. ## Organization and members Workspaces, members, and invitations belong to the organization; it spans every workspace you are a member of. **Settings → Organization** shows the organization's name, your role, and the member list: ![Organization members and invitations](/assets/ui_settings_org.png) Inviting a teammate sends them an email with a one-time link to join. The invitation carries the role the new member will hold. Invitations expire after 7 days; accepted, revoked, and expired invitations leave the pending list. After you send an invitation, the dialog also shows the link once so you can share it another way. If the email couldn't be sent, the dialog says **Invite link created** instead of **Invitation sent**. Copy the link then and send it yourself, because it is not shown again. Inviting, revoking pending invitations, changing a member's role, removing a member, and renaming the organization are admin actions. Members see the member list and their own role. ### Roles and permissions Every member holds one of two roles in the organization. Roles are per organization: a user who belongs to several organizations can be an admin in one and a member in another. - **Admin** manages the organization and its workspaces: members, invitations, API keys, alerting configuration, and the workspaces themselves. Admins always have access to every workspace in the organization. - **Member** works with the telemetry: explores traces and agents, follows usage and cost, acknowledges firings, shares views, and connects MCP clients. Members cannot change how the organization or its workspaces are configured. Roles and workspace access are separate settings. A member reaches either every workspace in the organization, the default, or only the workspaces an admin picks for them; admins change this per member from the member list, with **Specific workspaces**. | Action | Admin | Member | |---|---|---| | View traces, agents, usage and cost, and the MCP call log | ✓ | ✓ | | View alert rules and firings, acknowledge a firing | ✓ | ✓ | | Connect MCP clients | ✓ | ✓ | | Create and revoke shared views | ✓ | ✓ | | List API keys (names and prefixes only) | ✓ | ✓ | | Create, edit, delete, enable, or disable alert rules | ✓ | ✗ | | Turn alerting on or off for the workspace | ✓ | ✗ | | Manage distribution channels, including viewing them | ✓ | ✗ | | Connect or disconnect the Slack integration | ✓ | ✗ | | Turn root-cause analysis on or off per rule | ✓ | ✗ | | Create or revoke API keys | ✓ | ✗ | | Rename or delete a workspace | ✓ | ✗ | | Invite members, list and revoke invitations | ✓ | ✗ | | Change a member's role, remove a member | ✓ | ✗ | | Rename the organization | ✓ | ✗ | The console hides the controls a member cannot use, and the MCP server refuses the same actions for a member. An organization always keeps at least one admin: the last admin cannot be demoted to member or removed. Promote someone else first. To leave an organization as an admin, click **Remove** on your own row, then **Leave organization**. You lose access to all of its workspaces right away, and getting back in takes a new invitation. Members can't leave from the console; an admin removes them. API keys can carry the `alerts:manage` and `channels:manage` scopes, which let an MCP client or automation manage rules and channels the way an admin does. See [headless connections](/rius/mcp#headless-connections) for using a key with an MCP client. ## Root-cause analysis The **Intelligence** section of **Settings → Workspace** controls whether alert firings in this workspace are handed to an analysis agent, powered by [Tares](/tares), that investigates the affected traces and writes a report back onto the firing page. The section shows the state of the workspace's analysis cell and lets an admin pause and resume it. While paused, alert context is still stored, but no analysis runs. Per alert, the **Root-cause analysis** switch on the alert's page decides whether that alert's firings are sent; see [Alerts](/rius/platform/alerts#firings-and-acknowledgment). ## Shared views A shared view is a public link to a frozen window of traces, created with **Share** from the trace list. It freezes the time range, the status filter, and the filter chips that were active, so a link created from a failed-only view stays failed-only, and it expires after 24 hours, 7 days, or 30 days, whichever you picked. Any member can create and revoke shared views, not only admins. Anyone with the link sees metadata and rollups until it expires or you revoke it in **Settings → Shared views**. A shared view never carries span content, input or output previews, end user ids, instance or session ids, or the API key that sent a trace. Links themselves are shown only at creation, the same rule as API keys:
Settings, Shared views: an active link restricted to failed traces, with its frozen window, expiry date, creator, and a Revoke button
Each active link lists its frozen window, expiry, and creator; a link can be restricted to failed traces only.
The recipient opens a read-only page scoped to exactly that window: the rollups, the trace list, the filters the link applies, and nothing else of the workspace.
What the recipient sees: a read-only shared trace view with rollup stats and the frozen trace list, no workspace navigation
The recipient's view of a failed-only link: frozen window, expiry, and rollups, with no access to the rest of the workspace.
## Attributes **Settings → Attributes** lists the attribute keys declared for the workspace. Declaring a key your agents already send gives it a type (string, number, or boolean) and a label: the filter builder then lists it under its label, with the operators its type calls for. An undeclared key stays filterable as text. Declaring changes no trace data. Admins **Declare** a key with its attribute key (letters, digits, dots, dashes, and underscores, up to 256 characters), its scope (span or resource attribute), its type, a label, and an optional description. They can edit the type, label, and description later, or **Undeclare** the key, which returns it to a plain text filter. An admin can also declare a key straight from a span's attribute menu; see [Filter from a span](/rius/platform/exploring-traces#filter-from-a-span). Members see the declared keys. ![Declaring an attribute](/assets/ui_declare_attribute.png) ## Plan and usage **Settings → Plan & usage** shows the organization's plan, its usage against the plan's limits, and, for admins, the way to subscribe. See [Plans and billing](/rius/platform/billing). ## Data and privacy **Settings → Data & privacy** sums up what happens to this workspace's data, with a link to the clause of the Terms or Privacy Policy each statement comes from. Every member can open it. ![The Data & privacy settings](/assets/ui_settings_data_privacy.png) - **Where it is held**: the workspace's region. It is picked when the workspace is created and never changes, and ingested traces stay in that region. Organization, membership, and billing records are held centrally, outside the region. - **How long it is kept**: after you cancel, your data is deleted from active systems within 30 days and from backups within 60 days. It can't be recovered after that, so export what you need first. - **What leaves this workspace**: while the workspace is connected to [root-cause analysis](#root-cause-analysis), paused included, alert context, including the trace content behind it, is sent to an analysis service that runs outside the workspace; admins see whether this workspace is connected. Alert [channels](/rius/platform/alerts/channels) you set up receive trace-derived content when an alert fires. For the list of providers that process data for us, or a Data Processing Agreement, write to [privacy@glassflow.ai](mailto:privacy@glassflow.ai). - **Your rights, and the documents**: how to ask for a copy, correction, or deletion of your personal data, and links to the Terms of Service and Privacy Policy. ## Next steps - [Installation and configuration](/rius/sdk/installation): where the API key goes in the SDK. - [Exploring traces](/rius/platform/exploring-traces): the view a shared link freezes. --- # Plans and billing Billing is per organization. A new organization starts on a free trial and subscribes to a plan from **Settings → Plan & usage**, through Stripe Checkout. Only organization admins manage billing; members see "Only organization admins can manage billing." Organizations created before 2026-09-29 are not affected: nothing changes for them, and their **Plan & usage** tab reads "Plan & usage isn't available yet". ## The trial Every new organization gets a trial on the Core plan's limits. It lasts 30 days or 500,000 spans, whichever comes first, and needs no card. During the trial the organization can have 2 members, 2 workspaces, and 10 alert rules. **Plan & usage** shows the date the trial ends and a meter for each limit, and the sidebar shows how many trial days are left. When the trial ends, subscribe to a plan to keep sending traces. Everything already stored stays readable. ## Plans Prices are in US dollars, billed monthly. | | Core | Growth | Pro | |---|---|---|---| | Price | $19 / month | $79 / month | $199 / month | | Spans included per month | 500,000 | 2,500,000 | 10,000,000 | | Overage per 1M spans | $14 | $12 | $10 | | Members | 2 | Unlimited | Unlimited | | Workspaces | 2 | 5 | 20 | | Alert rules | 10 | 25 | 100 | For larger volumes, an Enterprise plan is arranged with us: write to [help@glassflow.ai](mailto:help@glassflow.ai). ### Overage Spans beyond the plan's monthly allowance are not refused. They are billed at the plan's overage rate, prorated per span rather than rounded up to a whole million, and appear on the next monthly invoice. **Plan & usage** shows the month's spans against the allowance. ### Limits Members, workspaces, and alert rules are hard limits. Inviting a member, creating a workspace, or creating an alert rule past the limit is refused, and the console shows "limit reached" with a link to **Plan & usage**. ## Subscribe 1. Open **Settings → Plan & usage** and click **Choose a plan**. 2. Pick a plan. Each one lists its price, what is included, and its overage rate. 3. Review the summary on **Subscribe to** *plan*. If you have a promo code, enter it under **Promo code** and click **Apply**. The summary shows the discount as its own line. A code only works on a new subscription and covers a set number of monthly charges; your invoice shows the final amount. If you go **Back**, the code is kept and the plans it covers show the discounted price. Click **Continue to payment**. Subscribing during the trial ends the trial: the remaining trial days are not kept. 4. Enter your card on the Stripe Checkout page. 5. Stripe sends you back to **Plan & usage**, which reads "Confirming your payment…" and then "Payment confirmed". The plan is active right away. If the page says "This checkout expired" or "Payment did not go through", choose the plan again. ## Invoices, payment details, and cancelling The console does not yet manage a subscription once it is active: there is no in-app plan change, card update, cancellation, or invoice list. Until there is: - **Invoices and receipts** arrive by email from Stripe each month. - **A failed payment** puts a "Payment failed" banner in the console. Ingest keeps running while Stripe retries the charge, and Stripe's email links to the invoice so you can pay it with another card. If every retry fails, the subscription is cancelled, the organization is locked, and an admin can subscribe again from **Plan & usage**. - **To change plan, update your card, or cancel**, write to [help@glassflow.ai](mailto:help@glassflow.ai) from an admin's address. ## Next steps - [Settings](/rius/platform/settings): members, workspaces, and API keys. - [Alerts](/rius/platform/alerts): the alert rules your plan's limit counts. --- # MCP Connect Claude, Cursor, and other AI clients to Rius and query your agent's traces from where you already work. Ask "what was my agents' error rate yesterday?" in plain language, and your client answers from your real telemetry: trace lists, cost and token summaries, and full span waterfalls. Two different things share the MCP name. This section is about the Rius MCP **server**, an endpoint your AI client connects to for querying your telemetry. The SDK's [`mcp` integration](/rius/sdk/integrations/mcp) is the opposite direction: it traces your agent's own outgoing MCP tool calls. Same protocol, opposite directions. Neither requires the other. ## Quick connect Pick your client. The server key is `glassflow` and the server URL is `https://mcp.eu.console.rius-glassflow.com/mcp`. On a machine where you can open a browser, sign-in is your Rius account over OAuth and your client handles the flow for you. For agents that run without a browser, use a read-scoped API key instead: see [headless connections](#headless-connections). The console's **MCP** page shows these same snippets templated for your deployment. Run in your terminal. The OAuth sign-in opens the first time a session uses the server: ```bash claude mcp add --transport http glassflow https://mcp.eu.console.rius-glassflow.com/mcp ``` Run in your terminal. Keep `--url` before the URL, a bare URL registers a stdio server that cannot authenticate: ```bash codex mcp add glassflow --url https://mcp.eu.console.rius-glassflow.com/mcp ``` Add to `~/.cursor/mcp.json` (global) or `.cursor/mcp.json` (per-project), then approve the server under Settings → MCP: ```json filename="~/.cursor/mcp.json" { "mcpServers": { "glassflow": { "url": "https://mcp.eu.console.rius-glassflow.com/mcp" } } } ``` Add to `claude_desktop_config.json` (Settings → Developer → Edit Config), then restart Claude Desktop: ```json filename="claude_desktop_config.json" { "mcpServers": { "glassflow": { "url": "https://mcp.eu.console.rius-glassflow.com/mcp" } } } ``` Any MCP client that supports remote servers can connect with three facts: - **Transport**: streamable HTTP - **URL**: `https://mcp.eu.console.rius-glassflow.com/mcp` - **Auth**: OAuth 2.1; the server advertises its authorization metadata, so clients implementing the MCP authorization spec discover everything else automatically. Most accept the generic shape: ```json filename=".mcp.json" { "mcpServers": { "glassflow": { "type": "http", "url": "https://mcp.eu.console.rius-glassflow.com/mcp" } } } ``` Clients with their own config file or field names: | Client | Config file | Difference from the generic shape | |---|---|---| | VS Code (Copilot) | `.vscode/mcp.json` | Top-level key is `servers`; select the server in the Copilot Chat Agent view | | opencode | `opencode.json` | `mcp` key with `"type": "remote"` and `"enabled": true`, then run `opencode mcp auth glassflow` | | Windsurf | `~/.codeium/windsurf/mcp_config.json` | `serverUrl` instead of `url`; press Refresh in the MCP panel | | Cline | `cline_mcp_settings.json` | `"type": "streamableHttp"` | | Zed | `settings.json` | Top-level key is `context_servers`, with `"source": "custom"` | | Gemini CLI | `~/.gemini/settings.json` | `httpUrl` instead of `url`; run `/mcp` to trigger auth | Clients that only support stdio servers can bridge to the remote URL with `mcp-remote`: use `npx mcp-remote https://mcp.eu.console.rius-glassflow.com/mcp` as the stdio command. ## Headless connections Agents that run without a browser, including CI jobs, cron schedules, and autonomous coding sessions, authenticate with a read-scoped API key sent as a static `Authorization` header instead of completing the OAuth flow. Both auth paths are accepted side by side, so adding a key changes nothing about your interactive sessions. ### Mint a read-scoped key The quickest route is the console's **MCP** page, which has a **Connect an agent** button under "Headless agents": ![The MCP page in the Rius console, showing how access is scoped and the Connect an agent button](/assets/ui_mcp.png) It mints a read-scoped key and hands you the matching config for your client in one step, so you do not have to assemble the header yourself: ![The Connect an agent dialog, with a client picker, a key name, and telemetry sending left off for read-only access](/assets/ui_mcp_connect_agent.png) Two other routes reach the same place. In **Settings → API keys**, **Create API key** lets you pick capabilities directly, which is also where you go for a key that both queries and ships telemetry: ![The Create API key dialog with the Query data (read) capability selected](/assets/ui_api_key_create.png) Or ask an interactive MCP session to run `create_api_key` with `scopes: ["read"]`. The `read` scope is the one an MCP connection needs. Ingest keys, which is what the SDK uses and what you get when no capability is chosen, can't query through the MCP server. A bare agent key is read-only. To let an agent manage alerting as well, tick **Manage alert rules** (`alerts:manage`) or **Manage notification channels** (`channels:manage`) in the **Connect an agent** dialog. These two scopes are minted only there, and only by an admin; the Create API key dialog in Settings does not offer them. With either scope the MCP server exposes its alert-management tools; without them those tools stay hidden and the connection cannot change anything. A key never acknowledges a firing; that stays a person's action. See [Roles and permissions](/rius/platform/settings#roles-and-permissions). The key is shown exactly once. Store it as a secret, for example a `RIUS_API_KEY` environment variable or a CI secret, and keep it out of committed config files. Prefer your client's environment-variable expansion where it has one. ### Connect with the key Same URL and transport as an interactive connection, with the key as a bearer token: ```bash claude mcp add --transport http glassflow https://mcp.eu.console.rius-glassflow.com/mcp \ --header "Authorization: Bearer ${RIUS_API_KEY}" ``` Recent builds read the token from an environment variable, so the key itself stays out of the file: ```toml filename="~/.codex/config.toml" [mcp_servers.glassflow] url = "https://mcp.eu.console.rius-glassflow.com/mcp" bearer_token_env_var = "RIUS_API_KEY" ``` ```json filename="~/.cursor/mcp.json" { "mcpServers": { "glassflow": { "url": "https://mcp.eu.console.rius-glassflow.com/mcp", "headers": { "Authorization": "Bearer ri_..." } } } } ``` ```json filename="claude_desktop_config.json" { "mcpServers": { "glassflow": { "url": "https://mcp.eu.console.rius-glassflow.com/mcp", "headers": { "Authorization": "Bearer ri_..." } } } } ``` Add a `headers` block carrying the bearer token alongside the server URL. The exact key names follow the same per-client differences as the interactive table above: ```json filename=".mcp.json" { "mcpServers": { "glassflow": { "type": "http", "url": "https://mcp.eu.console.rius-glassflow.com/mcp", "headers": { "Authorization": "Bearer ri_..." } } } } ``` | Client | Difference | |---|---| | VS Code (Copilot) | Top-level key is `servers`; `"Bearer ${input:glassflow-key}"` prompts for the key instead of storing it | | opencode | `"headers": { "Authorization": "Bearer {env:RIUS_API_KEY}" }` | | Windsurf | `serverUrl` instead of `url` | | Gemini CLI | `headers` sits next to `httpUrl` | Stdio-only clients can bridge to the remote URL and pass the header through: ```bash npx mcp-remote https://mcp.eu.console.rius-glassflow.com/mcp \ --header "Authorization: Bearer ${RIUS_API_KEY}" ``` The header path skips OAuth discovery entirely, so a client that only supports a static bearer header works here even though it cannot complete the interactive flow. ### What a key-authenticated connection can do A key without manage scopes reaches every read-only tool: `get_me`, `list_workspaces`, the trace and span tools (`list_agent_traces`, `get_agent_trace`, `list_spans`, `agent_traces_summary`, `describe_search_catalog`), the agent and user tools (`list_agents`, `agent_error_groups`, `agent_lifecycle_events`, `agent_versions`, `compare_agent_versions`, `list_users`, `user_activity_summary`), the metrics tools (`workspace_metrics_overview`, `list_metrics_catalog`), and the alert reads. A key minted with `alerts:manage` or `channels:manage` additionally reaches the alert-management tools for its workspace. Four limits are deliberate rather than bugs: - The key is bound to the single workspace it was created in. Other workspaces report as not found. - `create_api_key` is denied, so a leaked agent key cannot mint more keys. Use an interactive session or the console for key management. - `get_me` reports the accessible workspaces without a user identity, because a key is not a person. - Revoking a key can take up to a minute to be reflected when a client reconnects, since validation results are cached briefly. ### Check a key from CI A `200` response to an `initialize` call proves both the key and the server, with no MCP client involved: ```bash curl -sf -X POST https://mcp.eu.console.rius-glassflow.com/mcp \ -H "Authorization: Bearer ${RIUS_API_KEY}" \ -H "Content-Type: application/json" \ -H "Accept: application/json, text/event-stream" \ -d '{"jsonrpc":"2.0","id":1,"method":"initialize","params":{"protocolVersion":"2025-06-18","capabilities":{},"clientInfo":{"name":"ci-smoke","version":"0"}}}' ``` ## Verify the connection Ask your client: > Who am I in Rius, and which workspaces can I access? The client should call the `get_me` tool and answer with your email and a workspace table. If it does, everything works; head to the [example workflows](/rius/mcp/workflows). ## Troubleshooting - **The browser sign-in loops or the client reports an auth error.** Remove and re-add the server; a stale cached token is the usual cause after a long idle period. - **The client connects but lists no tools.** Check you completed the browser sign-in: most clients show the server as connected before the OAuth flow has finished. - **Your organization uses SSO restrictions.** The MCP server accepts the same accounts as the Rius console; if you can sign in to the console, the MCP sign-in works too. - **A headless connection is rejected with 401.** The key is revoked or mistyped. Mint a fresh one and retry. - **A headless connection works but tools return 403 "API key lacks the required scope".** The key has no `read` scope, which is the default for the ingest keys the SDK uses. Mint one with the read capability. The key itself is valid, so this is a scope problem rather than an auth problem. - **`create_api_key` returns 403 on a headless connection.** Expected. Key-authenticated connections cannot mint keys; use an interactive session or the console. ## What you can ask The server exposes tools over your workspaces, metrics, and traces. Your client picks the right ones for a question like: - "Summarize my agent traffic over the last 24 hours." (KPIs: traces, LLM calls, error rate, cost, tokens, latency percentiles) - "List the failed runs from this week and show me what went wrong in the worst one." (trace list filtered by status, then a span waterfall) - "Which service is spending the most right now?" See the [tool reference](/rius/mcp/tools) for every tool and its arguments, and [example workflows](/rius/mcp/workflows) for complete investigation patterns. ## MCP usage in the console The console's **MCP** page shows how MCP clients use Rius across your organization. Its tabs are covered in [Usage and access](/rius/mcp/usage-and-access). ### Name your agent A client can declare its own agent name with the `X-MCP-Agent-Name` header, set once in the client's server config next to the `Authorization` header: ```json filename=".mcp.json" { "mcpServers": { "glassflow": { "type": "http", "url": "https://mcp.eu.console.rius-glassflow.com/mcp", "headers": { "Authorization": "Bearer ri_...", "X-MCP-Agent-Name": "release-triage-bot" } } } } ``` The name is UTF-8 text of up to 128 characters. A longer name, or one with control or invisible formatting characters, is ignored rather than cut. ### What Rius logs about MCP calls For each MCP call, Rius records the tool, the client and session, the outcome, the latency, the number of rows returned, and the call's arguments under an allow-list: - **Kept:** structural arguments such as the workspace, the time window, limits, statuses and other fixed choices, the agent, service, and instance asked about, and ids such as a trace, session, or alert id. For a filter, only its field and operator are kept, not the values it matches. - **Never kept:** free text such as search terms and error text, webhook URLs, email recipients, and names and configuration you write. An argument the allow-list does not know is dropped. - **Never stored:** tool results. Call-log rows are kept for 30 days. The [Queries tab](/rius/mcp/usage-and-access#queries) shows the log. ## Access and permissions There are two ways to authenticate, and what the tools can reach depends on which one you use and, for keys, on the scopes it was minted with. **An OAuth session** is your Rius account, with the client handling the browser flow automatically. The tools see exactly the workspaces your user can access, and act with your role: reading is open to every member, acknowledging a firing is open to every member, and `create_api_key` and the alert-management tools work only for admins, the same as in the console. **An agent key** reaches the one workspace it belongs to and carries no user identity. A bare key is read-only. A key minted with `alerts:manage` or `channels:manage` can also manage alert rules or distribution channels in that workspace. No key can mint other keys or acknowledge a firing. See [headless connections](#headless-connections). If you belong to several organizations, `get_me` lists all of them with their workspaces. A tool's `workspace` argument takes a name or an ID; when the same workspace name exists in more than one of your organizations, pass it as `org/workspace`, because an ambiguous name returns an error. Nothing the MCP server offers can create, rename, or delete workspaces, or change members; those stay in the console. --- # Usage and access The console's **MCP** page shows everything that calls the Rius MCP server: your coding agents, scripts, CI jobs, and teammates in their editors. Use it to see who is connected, which tools they call, whether the calls come back with anything useful, and what each key is allowed to do. The page covers **every workspace in your organization**, except the Access tab, which shows the workspace you have selected. All times are UTC. It has six tabs: Overview, Clients, Sessions, Tools, Queries, and Access. A **client** here is anything that calls Rius over MCP. That is different from the agents you instrument with the SDK, which are on [Agents](/rius/platform/agents). One agent can be both, if it sends traces and also queries them. To connect a client in the first place, see [Connect](/rius/mcp). ## What you can answer here ### Is my self-improving agent getting useful answers? An agent that reads its own traces to improve is only as good as what it gets back. Check the [Tools](#tools) tab. A high **Empty** rate means the tool often found nothing: either nothing happened, or the agent is passing filters or time windows that miss its data. A high **Asked again** rate means the first answer didn't help. Check the filters and windows the agent passes; if they look right, tell us, because a tool that often answers empty or gets asked again usually needs better defaults or a clearer description. ### Which agent is reading what? [Queries](#queries) lists every tool call with the key, client, tool, and workspace. Use it to confirm a supervisor agent really checks the agents it is responsible for, and nothing else. ### Is an agent trying to do more than it should? **Needs attention** on the Overview flags keys asking for scopes they don't have. For example, an agent denied `channels:manage` is trying to read or change where alerts go. Decide whether it should be able to, then grant the scope or change the agent. See [Fix a denied scope](#fix-a-denied-scope). ### Can I tell my agents apart? The [Clients](#clients) tab shows which clients are **Named**, **Recognised**, or **Anonymous**. In a system with several agents, give every caller its own key and name, or you can't tell which agent made which call. ## Overview ![The MCP page's Overview tab](/assets/ui_mcp_overview.png) **Overview** covers the last 7 days. | Tile | What it shows | |---|---| | Answer rate | Share of measured calls that came back with something, for example "356 of 380 measured calls came back with something". | | Connected | Clients with a live session right now. A session that has been quiet for less than 15 minutes still counts. | | Sessions | Sessions opened in the window. | | Calls | Tool calls in the window. | | Auth failures | Calls rejected because of the key: invalid, revoked, or missing a scope. | Below the tiles: - **Calls per day** over the last 30 days. Days with errors are drawn in the error colour. - **Latest connections**: the most recent sessions, with client, actor, number of calls, and when each ended. **All sessions** opens the Sessions tab. - **Needs attention**: problems that crossed a threshold, such as a client nobody has named, or **a key asked for a scope it does not have**, which names the key, the scope it asked for, and when it last happened. ## Clients **Clients** lists the clients that connected in the last 7 days, most recently seen first. A client is the credential it connects with (your sign-in or an API key) plus the name it reports about itself. Each row shows its sessions, calls, answered rate, and when it was last seen. Every client is in one of three tiers: | Tier | Meaning | |---|---| | Named | A person named it, it is a signed-in user, or it declares a name with the `X-MCP-Agent-Name` header. Every call can be traced to someone. | | Recognised | It reports a name for itself, such as `claude-code`, but nobody has named it yet. All the numbers are there. | | Anonymous | It reported no name. Its key still tells it apart, but nothing says who it is until someone splits its key or it sets `X-MCP-Agent-Name`. | ![The Clients tab: named, recognised, and anonymous clients](/assets/ui_mcp_clients.png) Click **Name it** to give a recognised client a name, or **Rename** to change it. An anonymous client has no reported name to attach a label to: name its key on the [Access](#access) tab, split the key, or have the client set `X-MCP-Agent-Name` (see [Name your agent](/rius/mcp#name-your-agent)). Open a client for its own page: how many sessions it had open at once, the tools it used and how often they answered, what it asked about, and its sessions. When several callers share one key, both the row and the page say so, and the page shows how many held it at once, as a lower bound. Their figures are blended, since Rius can't tell them apart; give each caller its own key to separate them. ![A client's page](/assets/ui_mcp_client_detail.png) ## Sessions **Sessions** lists each MCP session, newest first. | Column | What it shows | |---|---| | Opened | When the session started. | | Session | The session ID. | | Client | Client name and version, with transport and region, for example `claude-code 2.1.284` and `http · eu`. | | Actor | The signed-in user or the API key. | | Calls | Tool calls in the session. | | Answered | Share of measured calls that came back with something. | | State | Whether the session is open, or when it ended. | Filter by client, answer rate, and time. Search by session ID, or by a **trace ID the session asked about**, to go from a trace to every session that looked at it. A session ends when the client disconnects, or when it has been idle long enough for the server to close it. A connection that authenticated but never made a call still shows up, with 0 calls. ![The Sessions tab](/assets/ui_mcp_sessions.png) Open a session to see every call it made, newest first, with the answer, rows returned, and duration. A call marked **asked again** repeated the same tool with a different question within 30 seconds; **looping** means the same question again. The side panel shows the client, the caller, the transport, and the region. ![A session's page](/assets/ui_mcp_session_detail.png) ## Tools **Tools** has one row per MCP tool over the last 7 days, most called first. Everything is measured from the caller's side. | Column | What it counts | |---|---| | Calls | Every call. | | Answered | Calls that returned at least one row, out of the calls that reported a row count. | | Empty | Calls that returned zero rows, out of the calls that reported a row count. | | Errors | Calls that failed, out of every call. Click the count to open those calls in Queries. | | Asked again | Calls where the previous call to the same tool, in the same session, asked a different question within 30 seconds. | | P50 | Median latency. | ![The Tools tab](/assets/ui_mcp_tools.png) What the numbers usually mean: - **High Empty**: callers ask for data Rius doesn't have in that window. That can be correct, when nothing happened, or it can mean the filters and time windows they pass miss the data. - **High Asked again**: the first answer didn't give the caller what it needed, so it asked differently. That points to the tool's defaults or its description. - **High Errors on one tool**: often a key without the right scope. For example, keys can't create other keys, so every `create_api_key` call made with a key fails. Click a tool to see its calls in Queries. ## Queries **Queries** is the call log across every workspace in your organization, newest first: each call with its user or key and client, the tool, the workspace, the status (`SUCCESS` or `ERROR`), and the duration. Tools that aren't tied to a workspace, such as `list_workspaces`, show `—` in the workspace column. Filter by workspace; the Tools tab and a client's page link here with the filter already set. Once a client is connected, **Add other clients** in the header opens the setup step for connecting another one, right above the log. Arguments are kept under an allow-list and results are never stored; see [What Rius logs about MCP calls](/rius/mcp#what-rius-logs-about-mcp-calls). Rows are kept for 30 days. ![The Queries tab: each MCP call with its tool, workspace, status, and duration](/assets/ui_mcp_queries.png) ## Access **Access** lists the API keys in the selected workspace that can query the MCP server, with the callers seen on each key over the last 7 days. | Column | What it shows | |---|---| | Key | The key's name and prefix. | | Callers | The clients using this key. A warning such as "shared by at least 6 callers at once" means several clients use the same key. | | Access | `read only`: can query MCP. `send + read`: can also send telemetry. | | Created / Last used | When the key was created and last used. | | Status | Whether the key is active. | ![The Access tab](/assets/ui_mcp_access.png) Admins can act on each key: - **Split**, on a key that several callers share, issues a second key and shows how to move one of the callers onto it. - **Edit**, on an active key, renames it and switches it between read only and send + read, without issuing a new key. Other scopes are edited under **Settings → API keys**. - **Delete** revokes the key. Revoking can take up to a minute to reach the MCP server. **Connect an agent** creates a new key for a headless client; see [Headless connections](/rius/mcp#headless-connections). A key that can only **send** telemetry can't query the MCP server, so it isn't listed here. Keys created under [Settings → API keys](/rius/platform/settings) are ingest-only unless you add `read`. ### How access is scoped A client connects in one of two ways: - **Signed in as you.** The client sees only the workspaces you belong to, picks one per query, and acts with your role: every member can read and acknowledge alerts, and only admins can manage alerts or create keys. If you lose access to a workspace, the client does too. - **With an agent key.** The key belongs to one workspace, carries no user identity, and can do only what its scopes allow. Keys made with **Connect an agent** always include `read`. | Scope | Allows | Tools | |---|---|---| | `read` | Reading traces, spans, agents, users, summaries, metrics, fired alerts, and alert rules | `list_agent_traces`, `get_agent_trace`, `list_spans`, `agent_traces_summary`, `describe_search_catalog`, `list_agents`, `agent_error_groups`, `agent_lifecycle_events`, `agent_versions`, `compare_agent_versions`, `list_users`, `user_activity_summary`, `workspace_metrics_overview`, `list_metrics_catalog`, `list_alerts`, `get_alert`, `list_alert_rules`, `describe_alert_catalog`, `list_workspaces`, `get_me` | | `alerts:manage` | Creating, changing, enabling, disabling, and deleting alert rules | `create_alert_rule`, `update_alert_rule`, `delete_alert_rule` | | `channels:manage` | Listing, creating, editing, and deleting Slack, email, and webhook destinations, and choosing which ones a rule delivers to | `list_alert_channels`, `create_alert_channel`, `update_alert_channel`, `delete_alert_channel` | Even listing channels needs `channels:manage`, because the list shows each destination's webhook URL, recipients, or Slack channel. Rules and channels are separate scopes on purpose: choosing **where** an alert goes is a different decision from choosing **what** triggers it. No key can acknowledge an alert or create another key. `ack_alert` works only for a signed-in client, because acknowledging records who saw the alert, and a key isn't a person. For the full rules, see [Access and permissions](/rius/mcp#access-and-permissions). ## Common tasks ### Name a client Go to **Clients** and click **Name it** on the row. From then on the client shows as **Named** on the Clients tab. Sessions and Queries still show the name the client reports. To set a name from the client's side instead, send the `X-MCP-Agent-Name` header; see [Name your agent](/rius/mcp#name-your-agent). ### Split a shared key When **Callers** shows a key as shared, click **Split**. Rius issues a second key and shows how to move one caller onto it. Only the key in that caller's configuration changes. After the split, each caller has its own row in every tab. ### Fix a denied scope When **Needs attention** shows that a key asked for a scope it does not have, decide whether that agent should have the scope: 1. **It should:** open **Settings → API keys**, click **Edit** on the key, and add the scope. 2. **It shouldn't:** change the agent's instructions or tool list so it stops trying. The denials do no harm, but they add noise. ### Check a new connection Connect a client (see [Connect](/rius/mcp)) and ask it one question, such as "list my agents". Open **MCP → Sessions**: your session should be there with 1 call and an answered rate. Then open **Queries** to see the `list_agents` call. ## Troubleshooting **Connected is 0, but there are calls.** Those calls came from sessions that have since ended. Connected counts only sessions open right now. **Answer rate shows "Unavailable".** Nothing in the window reported a row count, so there was nothing to measure. A client or session in the same state shows "nothing measured". This is common for sessions that connected but made no calls. **Auth failures are rising.** A client is using a revoked or deleted key, or a key without the scope it needs. **Needs attention** shows which key, and the **Status** column on Access shows whether it is still active. **All my scripts show up as one client.** They share a key. Split it, or give each script its own key. ## Next steps - [Connect](/rius/mcp): add the Rius MCP server to Claude Code, Cursor, and other clients. - [Tool reference](/rius/mcp/tools): every tool, its arguments, and the scope it needs. - [Example workflows](/rius/mcp/workflows): what to ask once a client is connected. - [Alerts](/rius/platform/alerts): the rules and channels that `alerts:manage` and `channels:manage` control. --- # Tool reference Every tool the Rius MCP server exposes, with arguments and example invocations. All tools return Markdown, which your client renders as tables and summaries. Everything is read-only with one exception, `create_api_key`, which is admin-gated. Two conventions apply across the trace tools: - **`workspace`** is optional everywhere: pass a workspace name or ID, or omit it to use your default workspace. Discover workspaces with `list_workspaces`. - **`hours`** is a lookback window ending now (default 24). "This week" is `hours: 168`. You rarely invoke tools by hand. Ask your client a question, and it picks the tools and arguments itself. The examples show what the client sends, which helps when a question is not picking the tool you expect. ## ack_alert Acknowledge an alert: record that a human has seen it, so it stops notifying. Acknowledging is NOT resolving. The alert stays open and keeps counting occurrences; only the detector resolves it, once the condition clears. Nothing in Rius can force an alert closed. Only available on an interactive (OAuth) connection: the acknowledgement records which user saw the alert, and an API key is not a user. | Argument | Type | Default | Description | |---|---|---|---| | `alert_id` | string | required | the alert's id, from list_alerts. | | `workspace` | string | `""` | optional workspace id, name, or `org-name/workspace-name` when the same name occurs in two of your orgs (defaults to your default). | > I've seen that alert, stop pinging me about it. ```json { "name": "ack_alert", "arguments": { "alert_id": "2f9c…" } } ``` ## agent_error_groups Group a window's errored spans by failure class — exception type and a normalised message — so a page of failures reads as its handful of causes. One row per group with its count, distinct traces, last occurrence, the instances it hit and sample trace ids for get_agent_trace. This is the same read the Rius console's Agent page draws its Exceptions figure from. The unit is errored SPANS with this span's own identity: `count` is not agent_traces_summary's `failed_traces` (runs whose ROOT span errored) and the two are labelled, never reconciled or added. The grouping reads span events, so the window is capped like any other unindexed query; a window the server refuses comes back saying so. | Argument | Type | Default | Description | |---|---|---|---| | `workspace` | string | `""` | optional workspace id, name, or `org-name/workspace-name` when the same name occurs in two of your orgs (defaults to your default; use list_workspaces to discover them). | | `hours` | integer | `24` | lookback window in hours (default 24), used for whichever of start/end is not given. | | `start` | string | `""` | optional absolute RFC3339 lower bound (e.g. "2026-08-01T00:00:00Z"); overrides the hours-derived value when given. | | `end` | string | `""` | optional absolute RFC3339 upper bound; overrides the hours-derived value when given. | | `agent` | string | `""` | optional exact agent name — this SPAN's agent identity, the same value `agent=` filters on for list_spans. Read a name off list_agents or off `root_agent` on list_agent_traces rather than guessing one. | | `instance` | string | `""` | optional exact instance id, narrowing to one running copy of `agent`. | | `limit` | integer | `20` | groups per page (default 20, server max 100). The reply says how many errored spans the whole window holds, so a full page is visible as one. | > What is failing for the planner agent today? ```json { "name": "agent_error_groups", "arguments": { "agent": "planner" } } ``` > Group this week's failures across every agent. ```json { "name": "agent_error_groups", "arguments": { "hours": 168, "limit": 50 } } ``` > Is one copy of planner producing the errors? ```json { "name": "agent_error_groups", "arguments": { "agent": "planner", "instance": "inst-planner-01" } } ``` ## agent_lifecycle_events The lifecycle log of a workspace's agent instances — when each copy started, finished, was lost or recovered — newest first, timed when it happened rather than when a page was loaded. This is the same read the Rius console's Agent page draws its timeline from. The kinds are the server's: `started` (first heartbeat), `finished` (clean-shutdown ping), `lost` (silent past the gone threshold, timed at the sweep tick that noticed and carrying `last_seen_at` for the last ping before the silence) and `recovered` (a ping after lost). `stale` is a read-time status on list_agents, never an event. `open_trace_count` and `open_traces` say what was in flight at a lost or recovered moment. | Argument | Type | Default | Description | |---|---|---|---| | `workspace` | string | `""` | optional workspace id, name, or `org-name/workspace-name` when the same name occurs in two of your orgs (defaults to your default; use list_workspaces to discover them). | | `hours` | integer | `24` | lookback window in hours (default 24), used for whichever of start/end is not given. | | `start` | string | `""` | optional absolute RFC3339 lower bound (e.g. "2026-08-01T00:00:00Z"); overrides the hours-derived value when given. | | `end` | string | `""` | optional absolute RFC3339 upper bound; overrides the hours-derived value when given. | | `agent` | string | `""` | optional exact agent name; omit for every agent in the workspace. | | `instance` | string | `""` | optional exact instance id; composes with agent. | | `limit` | integer | `50` | max rows (default 50, server max 200). | | `cursor` | string | `""` | opaque page token from a previous call's next-page hint, to fetch the page after it. | > When did the planner agent's copies die today? ```json { "name": "agent_lifecycle_events", "arguments": { "agent": "planner" } } ``` > Everything that happened to inst-planner-01 this week. ```json { "name": "agent_lifecycle_events", "arguments": { "hours": 168, "instance": "inst-planner-01" } } ``` ## agent_traces_summary Summary KPIs for agent traces over a time window, for the whole workspace or for ONE agent: trace count, LLM calls, error rate, failed vs errored traces, sessions, total/average cost, token usage, and latency and TTFT percentiles. With `group_by="bucket"` it also answers the same figures per time bucket, the read behind the console's Drift figure, so "is this agent getting slower or more expensive over the week" is one call. Scope it with `agent` to get that agent's own numbers. This is the same read, with the same arguments, that the Rius console's agent page makes, so a number you report here and a number a human reads there are the same number — not two measurements that happen to agree. Read the **Failed traces** and **Errored traces** lines as the two different questions they are, and do not add them together or report one as "errors": a run whose ROOT span errored FAILED, while a run that errored somewhere and then recovered did not. The error rate is errored traces over traces. | Argument | Type | Default | Description | |---|---|---|---| | `workspace` | string | `""` | optional workspace id, name, or `org-name/workspace-name` when the same name occurs in two of your orgs (defaults to your default; use list_workspaces to discover them). | | `hours` | integer | `24` | lookback window in hours (default 24), used for whichever of start/end is not given. | | `start` | string | `""` | optional absolute RFC3339 lower bound (e.g. "2026-08-01T00:00:00Z"); overrides the hours-derived value when given. | | `end` | string | `""` | optional absolute RFC3339 upper bound; overrides the hours-derived value when given. | | `service` | string | `""` | optional service-name filter (traces that involve this service). | | `agent` | string | `""` | optional exact agent-name filter, matched against the trace's root span — the same value the `root_agent` column reports on list_agent_traces, so read a name off a listing rather than guessing one. Agent identity is its own field, not the service name: a run that declares no agent falls back to its service name, so equal `root_agent` and `service` are that fallback, not two facts. | | `instance` | string | `""` | optional exact agent-instance filter, narrowing to one running copy of `agent`. | | `filters` | any | `null` | optional list of `{"field": ..., "op": ..., "values": [...]}` clauses, ANDed together and composable with the named parameters above — the same grammar and the same field registry as list_agent_traces, so a slice you listed and the summary of that slice cannot disagree. Call describe_search_catalog before guessing a key; a rejected clause comes back naming itself. | | `group_by` | string | `""` | optional; `"bucket"` adds one row per time bucket under the whole-window figures, with the same definitions and composable with every scope argument above. A trace counts once, whole, in the bucket its first span opened in, so the rows sum to the whole-window figures. Rows are sparse: a bucket no trace opened in has NO row, so never read an absent bucket as zero traces, zero cost or a 0% error rate. | | `bucket` | string | `""` | optional grain for `group_by="bucket"`: `"minute"`, `"hour"` or `"day"`. Omit it and the server picks from the window (minute up to 2h, hour up to 48h, day beyond; day buckets open at UTC midnight, so the first may be partial). A grain that cuts the window into more than 1000 buckets is refused with the count in the message. | > How did my agents do over the last 24 hours? ```json { "name": "agent_traces_summary", "arguments": { "hours": 24 } } ``` > How is the planner agent doing this week? ```json { "name": "agent_traces_summary", "arguments": { "hours": 168, "agent": "planner" } } ``` > Is one copy of planner worse than the others? ```json { "name": "agent_traces_summary", "arguments": { "agent": "planner", "instance": "inst-planner-01" } } ``` > Summarize the checkout-agent service this week. ```json { "name": "agent_traces_summary", "arguments": { "hours": 168, "service": "checkout-agent" } } ``` > What do planner's gpt-4o runs cost? ```json { "name": "agent_traces_summary", "arguments": { "agent": "planner", "filters": [{ "field": "model", "op": "eq", "values": ["gpt-4o"] }] } } ``` > Is planner getting slower or more expensive over the week? ```json { "name": "agent_traces_summary", "arguments": { "hours": 168, "agent": "planner", "group_by": "bucket" } } ``` > Summarize traces between two specific dates. ```json { "name": "agent_traces_summary", "arguments": { "start": "2026-08-01T00:00:00Z", "end": "2026-08-08T00:00:00Z" } } ``` ## agent_versions The versions ONE agent ran in a time window, on two dimensions that are kept apart and must not be read as synonyms: `agent` is the agent definition — prompt, tools, policy — as `rius.main_agent.version` stamps it, and `service` is the build that ran it, as `service.version` stamps it. A prompt edit ships without a deploy and a deploy without touching the agent, so the two move independently. Each row carries its traces, failed traces, failed rate and when it was first and last seen within the window. This is the same read the Rius console's Agent page draws its Versions figure from, and every row is ROOT-scoped like the registry fields, so a row's numbers equal agent_traces_summary with `filters=[{"field": "agent_version" | "service_version", "op": "eq", "values": [version]}]`. Use it to learn which two values to hand compare_agent_versions, or to see when a version appeared. Rows are newest-seen first within a dimension and capped at 50 per dimension; the totals count past the cap. | Argument | Type | Default | Description | |---|---|---|---| | `agent` | string | required | the exact agent name (required: versions are per agent). Read a name off list_agents or off `root_agent` on list_agent_traces rather than guessing one. | | `workspace` | string | `""` | optional workspace id, name, or `org-name/workspace-name` when the same name occurs in two of your orgs (defaults to your default; use list_workspaces to discover them). | | `hours` | integer | `24` | lookback window in hours (default 24), used for whichever of start/end is not given. | | `start` | string | `""` | optional absolute RFC3339 lower bound (e.g. "2026-08-01T00:00:00Z"); overrides the hours-derived value when given. | | `end` | string | `""` | optional absolute RFC3339 upper bound; overrides the hours-derived value when given. | | `instance` | string | `""` | optional exact instance id, narrowing to one running copy of `agent`. | > Which versions of planner ran this week? ```json { "name": "agent_versions", "arguments": { "agent": "planner", "hours": 168 } } ``` > When did planner's new prompt version first show up? ```json { "name": "agent_versions", "arguments": { "agent": "planner", "hours": 720 } } ``` ## compare_agent_versions Two versions of ONE agent side by side over the same window — traces, failed rate, cost per trace, latency p50, TTFT p50 and tokens per trace — with the change between them, so "did v8 make it worse" is one call. It is agent_traces_summary twice, each scoped through the registry filter for one version, and the same six rows and delta rules as the Rius console's compare tiles, so an agent and a human read one change. The change is in percentage points for the failed rate ("+1.0 pp", never "+50%") and a percent of the base otherwise; a dash means a side is unknown or the base is zero, never "no change". Below 20 traces on either side the reply says the differences can be noise; it never claims significance either way. Refuses, rather than answering, where this deployment's filter registry does not advertise the version field: an older core would ignore the filter and return the whole agent's numbers on both sides, which would read as a confident "no change". | Argument | Type | Default | Description | |---|---|---|---| | `agent` | string | required | the exact agent name (required). Read it off list_agents or off `root_agent` on list_agent_traces. | | `dimension` | string | required | which version identity to compare — `agent` (the agent definition, `rius.main_agent.version`) or `service` (the build, `service.version`; `build` is accepted as a synonym). The two are not interchangeable: read the values off agent_versions, which labels each. | | `base` | string | required | the older version's exact value, as agent_versions lists it. | | `head` | string | required | the newer version's exact value; the change is head against base. | | `workspace` | string | `""` | optional workspace id, name, or `org-name/workspace-name` when the same name occurs in two of your orgs (defaults to your default; use list_workspaces to discover them). | | `hours` | integer | `24` | lookback window in hours (default 24), used for whichever of start/end is not given. | | `start` | string | `""` | optional absolute RFC3339 lower bound (e.g. "2026-08-01T00:00:00Z"); overrides the hours-derived value when given. | | `end` | string | `""` | optional absolute RFC3339 upper bound; overrides the hours-derived value when given. | | `instance` | string | `""` | optional exact instance id, narrowing both sides to one running copy of `agent`. | > Did planner's version 8 make things worse than 7 this week? ```json { "name": "compare_agent_versions", "arguments": { "agent": "planner", "dimension": "agent", "base": "7", "head": "8", "hours": 168 } } ``` > Compare the last two builds of planner. ```json { "name": "compare_agent_versions", "arguments": { "agent": "planner", "dimension": "service", "base": "2.3.1", "head": "2.4.0" } } ``` ## create_alert_channel Create a place for alerts to be delivered: a webhook, an email list, or Slack. This provisions a real outbound effect. Once a rule points at this channel, alert content leaves the platform to wherever you named — for a webhook, an HTTP POST to that URL. The payload carries the alert title (which is a span's error message, so it can contain model output), its labels, counts, and a sample of trace ids. Needs the `channels:manage` capability. | Argument | Type | Default | Description | |---|---|---|---| | `name` | string | required | a label for the channel, 1 to 120 characters. | | `channel_type` | string | required | `webhook`, `email`, or `slack`. | | `url` | string | `""` | for a webhook — the https URL to POST to. | | `recipients` | any | `null` | for email — 1 to 20 addresses. | | `slack_channel_id` | string | `""` | for Slack — a channel id from the connected Slack workspace. Slack must be connected in the console first. | | `workspace` | string | `""` | optional workspace id, name, or `org-name/workspace-name` when the same name occurs in two of your orgs (defaults to your default). | | `enabled` | boolean | `true` | whether it starts receiving deliveries. Defaults to true. | > Send my alerts to this webhook. ```json { "name": "create_alert_channel", "arguments": { "name": "ops webhook", "channel_type": "webhook", "url": "https://hooks.example.com/rius" } } ``` ## create_alert_rule Create a custom alert rule. Call describe_alert_catalog first. The rule fires when every threshold in `rules` holds at once, over the same rolling window, for the traffic left after every filter in `filters`. There is no OR: for alternatives, create a second rule. Predefined rules cannot be created — they already exist per workspace. Use update_alert_rule to configure one. | Argument | Type | Default | Description | |---|---|---|---| | `name` | string | required | what to call the rule, 1 to 120 characters. | | `rules` | array | required | the thresholds, each `{"metric":…, "aggregation":…, "operator":…, "value":…}`. At least one, at most 10, and each (metric, aggregation) pair only once. Operators: lt, lte, gt, gte, eq. | | `window_minutes` | integer | `15` | the rolling window every threshold is measured over, 5 to 1440. | | `filters` | any | `null` | optional narrowing, each `{"field":…, "operator":…, "values":[…]}`. ANDed. Omit to watch the whole workspace. eq and ne take exactly one value; in and not_in take one or more. Which operators a field admits is per field — describe_alert_catalog lists them. Values bind verbatim, so pass them exactly as the data spells them: `span_kind` is the raw OpenInference `LLM`, not `llm`, and a lowercased value creates a rule that saves and then never fires. | | `channel_ids` | any | `null` | where firings are delivered, from list_alert_channels. Supplying this needs the `channels:manage` capability, because choosing a destination is a destination decision. Omitting it leaves the rule on the region's default webhook. | | `enabled` | boolean | `true` | whether detection starts immediately. Defaults to true. | | `workspace` | string | `""` | optional workspace id, name, or `org-name/workspace-name` when the same name occurs in two of your orgs (defaults to your default). | > Alert me when the checkout agent starts erroring. ```json { "name": "create_alert_rule", "arguments": { "name": "checkout errors", "filters": [{"field": "service", "operator": "eq", "values": ["checkout"]}], "rules": [{"metric": "errors", "aggregation": "count", "operator": "gte", "value": 5}] } } ``` > Tell me if p95 cost per trace goes over two dollars. ```json { "name": "create_alert_rule", "arguments": { "name": "cost spike", "window_minutes": 60, "rules": [{"metric": "cost", "aggregation": "p95", "operator": "gt", "value": 2.0}] } } ``` ## create_api_key Create a new API key in one of your workspaces. Requires admin access in that workspace. The plaintext key is shown exactly once in the response. It is never retrievable again after this call, so save it immediately. Not available when this MCP connection is itself authenticated with an API key (headless mode): a leaked agent key must not be able to mint more keys. Mint keys from an interactive (OAuth) session or the console instead. | Argument | Type | Default | Description | |---|---|---|---| | `workspace` | string | `""` | optional workspace id, workspace name, or `org-name/workspace-name` when the same name occurs in two of your orgs (defaults to your default; use list_workspaces to discover them). | | `name` | string | `glassflow-connect-agent` | a label for the key, shown in the workspace's key list later. | | `scopes` | any | `null` | key capabilities: ["ingest"] (default) to send telemetry, add "read" (["ingest", "read"] or ["read"]) for a key that can also be used as the Authorization bearer for headless MCP connections. The alert-management capabilities (alerts:manage, channels:manage) are deliberately NOT mintable here — an admin issues those in the console, because a key minted by an agent never expires by default and would be an unbounded credential to leak. | > Create an API key so this agent can send traces. ```json { "name": "create_api_key", "arguments": { "name": "my-agent" } } ``` > Give it a key that can also read traces over MCP. ```json { "name": "create_api_key", "arguments": { "scopes": ["ingest", "read"] } } ``` ## delete_alert_channel Delete a notification channel. Irreversible. Takes two calls, like delete_alert_rule: once to preview, once with the phrase. Any rule still pointing at this channel loses that destination silently and falls back to the region's default webhook — it does not start failing loudly. Consider update_alert_channel with enabled false instead, which is reversible. Needs the `channels:manage` capability. | Argument | Type | Default | Description | |---|---|---|---| | `channel_id` | string | required | the channel's id, from list_alert_channels. | | `confirm` | string | `""` | the phrase from the first call's output. | | `workspace` | string | `""` | optional workspace id, name, or `org-name/workspace-name` when the same name occurs in two of your orgs (defaults to your default). | > Remove the old ops webhook. ```json { "name": "delete_alert_channel", "arguments": { "channel_id": "8a1…" } } ``` ## delete_alert_rule Delete a custom alert rule AND its entire firing history. Irreversible. Takes two calls. Call it without `confirm` to see what would be destroyed and get the phrase to pass back; call it again with that phrase to go ahead. Prefer update_alert_rule with enabled false: that stops detection and keeps the history, and can be undone. Predefined rules cannot be deleted at all. | Argument | Type | Default | Description | |---|---|---|---| | `ref` | string | required | the custom rule's uuid, from list_alert_rules. | | `confirm` | string | `""` | the phrase from the first call's output. | | `workspace` | string | `""` | optional workspace id, name, or `org-name/workspace-name` when the same name occurs in two of your orgs (defaults to your default). | > Delete the cost spike alert. ```json { "name": "delete_alert_rule", "arguments": { "ref": "9c2…" } } ``` ## describe_alert_catalog Describe what you can alert on: the fields, metrics and limits for a custom rule. Read this before calling create_alert_rule. It returns the filter fields, the metrics with the aggregations each one actually supports, the comparison operators, and the allowed window — plus the constraints the catalog itself does not advertise. | Argument | Type | Default | Description | |---|---|---|---| | `workspace` | string | `""` | optional workspace id, name, or `org-name/workspace-name` when the same name occurs in two of your orgs (defaults to your default). | | `field` | string | `""` | optionally a filter field id (for example "service"), to list the values actually seen in this workspace over the last 24h. | > What can I alert on? ```json { "name": "describe_alert_catalog", "arguments": {} } ``` > Which services could I filter an alert to? ```json { "name": "describe_alert_catalog", "arguments": { "field": "service" } } ``` ## describe_search_catalog Describe what you can filter traces and spans on, before you guess a key. Returns the filter grammar — every field, its type, the operators it admits, and what a filter on it means for a TRACE — merged with the keys this workspace has actually produced. Read it before composing `filters` for list_agent_traces or list_spans; a guessed key is a rejected call. Cost model, in the order worth trying: promoted columns (`source: column`) are cheap over any window; `attr.` and `resource.` reach the customer's own attributes, cost roughly 10x more, and are accepted only over windows of 31 days or less — so narrow with a column first, then add one. | Argument | Type | Default | Description | |---|---|---|---| | `workspace` | string | `""` | optional workspace id, name, or `org-name/workspace-name` (defaults to your default). | | `field` | string | `""` | optionally a key, to list the values seen in this workspace. Accepts either spelling — "tool.name" or "attr.tool.name". | | `prefix` | string | `""` | optionally narrow the key list, e.g. "tool." to find a customer's own tool attributes. | | `hours` | integer | `24` | lookback for the key and value lists (default 24). | > What can I filter traces on? ```json { "name": "describe_search_catalog", "arguments": {} } ``` > What tool attributes does this workspace set? ```json { "name": "describe_search_catalog", "arguments": { "prefix": "tool." } } ``` > Which models could I filter to? ```json { "name": "describe_search_catalog", "arguments": { "field": "model" } } ``` ## get_agent_trace Get one agent trace's span waterfall (spans in time order, indented by depth). The header names the root span's agent and each row carries its own, so a multi-agent run shows which agent owned which span; pass either name back to list_agent_traces or list_spans as `agent` to see that agent's other work. The header also names who sent the trace — the sending ingest key's own email, which a console-made key usually carries too (it falls back to its creator's own email). Blank only when the key could not be resolved or the trace predates attribution. The header also names the root span's session; pass it to `list_spans(session_id=...)` for the rest of that conversation. A session equal to the trace id means the run carried no session of its own. A trace whose spans carry more than one session gets a per-span `session` column. Captured content is subject to the workspace's privacy controls: spans exported with capture_content=False or a mask have nothing extra to show. | Argument | Type | Default | Description | |---|---|---|---| | `trace_id` | string | required | the trace id (from list_agent_traces). | | `workspace` | string | `""` | optional workspace id, name, or `org-name/workspace-name` when the same name occurs in two of your orgs (defaults to your default; use list_workspaces to discover them). | | `include_content` | boolean | `false` | when true, also return each span's captured content: LLM input/output messages, agent/tool input/output values, status messages and events. Off by default because full message content can be very large; pass true when you need to see what an LLM, agent, or tool span actually said, received, or returned (e.g. to inspect prompts, completions, or tool I/O). | > Break down trace 4bf92f3577b34da6a3ce929d0e0e4736 for me. ```json { "name": "get_agent_trace", "arguments": { "trace_id": "4bf92f3577b34da6a3ce929d0e0e4736" } } ``` > What did the LLM actually say in that failed span? ```json { "name": "get_agent_trace", "arguments": { "trace_id": "4bf92f3577b34da6a3ce929d0e0e4736", "include_content": true } } ``` ## get_alert Read one fired alert in full, with its root-cause finding when one exists. Use this after list_alerts to understand a single alert: its labels, the sample trace ids behind it, and — if root-cause analysis ran for it — the investigation's written finding. | Argument | Type | Default | Description | |---|---|---|---| | `alert_id` | string | required | the alert's id, from list_alerts. | | `workspace` | string | `""` | optional workspace id, name, or `org-name/workspace-name` when the same name occurs in two of your orgs (defaults to your default). | > Why did that alert fire? ```json { "name": "get_alert", "arguments": { "alert_id": "2f9c…" } } ``` ## get_me Get your own identity and access context. Returns your user (id, external id, email), every organization you belong to with your role in each ("admin" or "member"), and the workspaces you can access — an interactive (OAuth) connection spans every one of those orgs, so workspaces are grouped by org when you belong to more than one. If you have not yet joined an organization (for example, a pending invite that has not been accepted), the organizations are reported as "none". On a connection authenticated with an API key rather than a login, only the one workspace the key is bound to is reported — a key has no user or organization of its own. No arguments. > Who am I in Rius? ```json { "name": "get_me", "arguments": {} } ``` ## list_agent_traces List recent agent traces (one row per trace) newest-first, as a Markdown table. The trace_id column feeds get_agent_trace. When more traces match than limit, the reply carries a next-page cursor: pass it back as `cursor` to fetch the next page, rather than raising limit past what a chat can usefully display. The `session` column is the ROOT span's session id; pass it to `list_spans(session_id=...)` to see every span of that conversation across the traces it touched. A span with no session of its own is stamped with its trace id, so a session equal to the row's trace_id means "no session", not a one-trace conversation. Blank where this deployment does not report it yet. The `sent_by` column names the developer whose ingest key sent the trace (their stable email — a console-made key falls back to its creator's own email, so it usually carries one too). Blank only when the key could not be resolved (unknown, another workspace's, or a failed lookup), or the trace predates attribution. | Argument | Type | Default | Description | |---|---|---|---| | `workspace` | string | `""` | optional workspace id, name, or `org-name/workspace-name` when the same name occurs in two of your orgs (defaults to your default; use list_workspaces to discover them). | | `hours` | integer | `24` | lookback window in hours (default 24), used for whichever of start/end is not given. | | `start` | string | `""` | optional absolute RFC3339 lower bound; overrides the hours-derived value when given. | | `end` | string | `""` | optional absolute RFC3339 upper bound; overrides the hours-derived value when given. | | `service` | string | `""` | optional service-name filter (traces that involve this service). | | `status` | string | `""` | optional trace status filter, "Ok", "Error", or "Incomplete". Note a trace reads Error when ANY of its spans errored, so a run that retried a failing step and then succeeded is in here too — read root_status to tell those apart. | | `root_status` | string | `""` | optional filter on the ROOT span's own verdict, "Ok", "Error", or "Incomplete". Composes with status rather than replacing it: status="Error" with root_status="Ok" is the recovered slice (children errored, the run itself finished clean), and root_status="Error" alone is the genuine failures. A trace whose root_status column is blank matches neither — the server made no claim about its root. | | `agent` | string | `""` | optional exact agent-name filter, matched against the trace's root span — the same value the `root_agent` column reports, so read a name off a listing rather than guessing one, and pass it back to get every other run of that agent. Agent identity is its own field, not the service name: a run that declares no agent falls back to its service name, so equal `root_agent` and `service` columns are that fallback, not two facts. | | `instance` | string | `""` | optional exact agent-instance filter, narrowing to one running copy of `agent`. | | `user_id` | string | `""` | optional end-user scope — the exact id, as the `user_id` column reports it. The END USER is the person your agents served (the `user.id` your SDK stamps), not a console login. Matched against ANY span of the trace, so a run counts if the user scope was open anywhere inside it. The column, though, is the ROOT span's user, so the two need not agree: a trace whose scope opened after its root matches the filter and still shows a BLANK cell. That gap is the any-span rule working as specified, not a filter that missed — read the trace's spans to see where the scope opened. | | `anonymous` | boolean | `false` | list the traffic carrying NO end user on any span, instead of one user's. A real subject rather than an error case: it is where un-instrumented traffic goes, and its error rate is worth knowing. The console's `?user=anonymous`. Pass either `user_id` or `anonymous`, never both — they are disjoint by construction. | | `filters` | any | `null` | optional list of `{"field": ..., "op": ..., "values": [...]}` clauses, ANDed together and composable with the named parameters above. Cheapest first: `status`, `agent`, `service`, `model`, `span_kind`, `operation`, `session_id` are promoted columns and cost the same over any window. `attr.` and `resource.` reach a customer's own attributes and are ~10x dearer, so narrow with a column first; they are accepted only over windows of 31 days or less. Ops: eq, ne, in, not_in, gt, gte, lt, lte, exists, not_exists. Substring on an attribute value is refused — use error_text or search instead. Call describe_search_catalog before guessing a key; a rejected clause comes back naming itself. | | `search` | string | `""` | optional case-insensitive contains match on span name, span id, trace id, or session id. A session id alone — e.g. a coding-agent session's — finds every trace of that session in one call; on a core that predates session-id search it matches nothing, so fall back to `filters=[{"field": "session_id", "op": "eq", "values": [...]}]`. | | `error_text` | string | `""` | optional free text over the failure itself — the status message and any recorded exception. This is how you find a failure by what it said ("rate limit", "connection reset") rather than by where it was. | | `limit` | integer | `20` | max rows (default 20). | | `cursor` | string | `""` | opaque page token from a previous call's next-page cursor, to fetch the page after it. | > Why did checkout-agent start failing at 14:00? ```json { "name": "list_agent_traces", "arguments": { "agent": "checkout-agent", "status": "Error", "root_status": "Error", "start": "2026-09-16T14:00:00Z", "end": "2026-09-16T15:00:00Z", "error_text": "rate limit" } } ``` > Failed runs that used gpt-4o and called the send_email tool. ```json { "name": "list_agent_traces", "arguments": { "status": "Error", "filters": [ {"field": "model", "op": "eq", "values": ["gpt-4o"]}, {"field": "attr.tool.name", "op": "eq", "values": ["send_email"]} ] } } ``` > Show me the failed runs from the last two days. ```json { "name": "list_agent_traces", "arguments": { "hours": 48, "status": "Error" } } ``` > Which runs actually failed, ignoring the ones that retried and recovered? ```json { "name": "list_agent_traces", "arguments": { "hours": 48, "root_status": "Error" } } ``` > Show me the runs that hit errors but finished cleanly anyway. ```json { "name": "list_agent_traces", "arguments": { "hours": 48, "status": "Error", "root_status": "Ok" } } ``` > checkout-agent's traces between two dates. ```json { "name": "list_agent_traces", "arguments": { "agent": "checkout-agent", "start": "2026-08-01T00:00:00Z", "end": "2026-08-08T00:00:00Z" } } ``` ## list_agents List a workspace's agent instances with their live status — which agents exist, how many copies of each are running, and which copies are stale, gone or stopped. One row per instance, straight from the heartbeat store. This is the same read the Rius console's Agents page makes, with the server's own status words: `running`, `ready`, `stale`, `gone`, `stopped`. The status is computed on the server from the last heartbeat; do not re-derive it from `last_seen_at`. `open_trace_count` is the true number of open traces and the running/ready signal; `first_seen_at` and `stopped_at` appear when the core serves them, and a blank `first_seen_at` means the start is unknown, not that it started now. Every row here is a live instance; a trace-only agent (one that sends traces but no heartbeat) does not appear. If an agent you expect is missing, the reply says why that happens. | Argument | Type | Default | Description | |---|---|---|---| | `workspace` | string | `""` | optional workspace id, name, or `org-name/workspace-name` when the same name occurs in two of your orgs (defaults to your default; use list_workspaces to discover them). | | `agent` | string | `""` | optional exact agent name, to list only that agent's instances. The server has no filter for it, so this narrows the reply here and names the agents that do have instances when nothing matches. | > Which of my agents are running right now? ```json { "name": "list_agents", "arguments": {} } ``` > Are any copies of planner lost? ```json { "name": "list_agents", "arguments": { "agent": "planner" } } ``` ## list_alert_channels List where this workspace's alerts can be delivered. Use it to find a channel id for create_alert_rule or update_alert_rule. Needs the `channels:manage` capability rather than plain read, because the target column shows the actual destination — a webhook URL, an email recipient list, a Slack channel. | Argument | Type | Default | Description | |---|---|---|---| | `workspace` | string | `""` | optional workspace id, name, or `org-name/workspace-name` when the same name occurs in two of your orgs (defaults to your default). | > Where do my alerts go? ```json { "name": "list_alert_channels", "arguments": {} } ``` ## list_alert_rules List every alert rule in the workspace — predefined and custom together. Predefined rules are the built-in detectors, one per kind, which you can configure and toggle but not create or delete. Custom rules are ones someone built from the metric catalog; there can be many. The `ref` column is what update_alert_rule and delete_alert_rule take: a kind name for a predefined rule, a uuid for a custom one. A predefined rule only appears once alert-manager has reached this workspace, so an empty list can simply mean detection has not started yet. | Argument | Type | Default | Description | |---|---|---|---| | `workspace` | string | `""` | optional workspace id, name, or `org-name/workspace-name` when the same name occurs in two of your orgs (defaults to your default). | > What alerts are configured? ```json { "name": "list_alert_rules", "arguments": {} } ``` ## list_alerts List alerts that have fired, newest first. This is the "what is broken" tool. An alert is opened by a detector and stays open, accumulating occurrences, until the detector resolves it — so an open alert with a recent `last_seen` is still happening. | Argument | Type | Default | Description | |---|---|---|---| | `workspace` | string | `""` | optional workspace id, name, or `org-name/workspace-name` when the same name occurs in two of your orgs (defaults to your default). | | `status` | string | `""` | `open` or `resolved`; omit for both. | | `kind` | string | `""` | narrow to one detector — consistent_error_pattern, silent_failure, tool_loop, or custom. Every custom rule shares the kind "custom", so use rule_id to isolate one custom rule. | | `rule_id` | string | `""` | narrow to the firings of one specific rule (from list_alert_rules). | | `service` | string | `""` | exact service name. | | `step` | string | `""` | exact step (span) name. | | `search` | string | `""` | case-insensitive match on the alert title. | | `acknowledged` | string | `""` | `true` or `false`; omit for both. | | `hours` | integer | `24` | how far back to look, on last_seen. Defaults to 24. The server itself is unbounded if no window is given, which would scan all history. | | `limit` | integer | `50` | rows to return, at most 200. | > What alerts are open right now? ```json { "name": "list_alerts", "arguments": { "status": "open" } } ``` > Show me the errors alert for the checkout service this week. ```json { "name": "list_alerts", "arguments": { "service": "checkout", "hours": 168 } } ``` ## list_metrics_catalog List every metric the platform knows how to compute, with its unit, nullability, which read serves it, and its `companions` (the extra response keys it contributes: coverage keys for scalars, row/point value keys for breakdowns and series). Use it to discover exact field names instead of guessing them. | Argument | Type | Default | Description | |---|---|---|---| | `workspace` | string | `""` | optional workspace name or id (the catalog is identical for every caller; this only fills the request path). | | `group` | string | `""` | optional group filter, e.g. "cost", "volume", "tokens", "latency", "ttft", "reliability". | | `kind` | string | `""` | optional kind filter: "scalar", "series", or "breakdown". | > What latency metrics exist? ```json { "name": "list_metrics_catalog", "arguments": { "group": "latency" } } ``` ## list_spans List spans across every trace in the workspace (not grouped by trace), as a Markdown table — the cross-trace complement to get_agent_trace's single-trace waterfall. Use it to find spans by kind/session/agent regardless of which trace they landed in, e.g. "every failed tool call this week" or "this session's spans across however many traces it touched". | Argument | Type | Default | Description | |---|---|---|---| | `workspace` | string | `""` | optional workspace id, name, or `org-name/workspace-name` when the same name occurs in two of your orgs (defaults to your default; use list_workspaces to discover them). | | `hours` | integer | `24` | lookback window in hours (default 24), used for whichever of start/end is not given. | | `start` | string | `""` | optional absolute RFC3339 lower bound; overrides the hours-derived value when given. | | `end` | string | `""` | optional absolute RFC3339 upper bound; overrides the hours-derived value when given. | | `kind` | string | `""` | optional derived semantic span kind: "llm", "tool", "chain", "retriever", "agent", "embedding", or "other". Distinct from each row's own `kind` column, which is the raw OTLP span kind (SERVER/CLIENT/INTERNAL/...). | | `status` | string | `""` | optional span status filter, "Ok", "Error", or "Incomplete". | | `session_id` | string | `""` | optional exact match on the span's session id, across every trace in that session. Read one off the `session` column (reported here, on list_agent_traces and by get_agent_trace) rather than guessing. A span with no session of its own reports its trace id there, so passing a trace id selects that one trace's session-less spans. | | `agent` | string | `""` | optional exact agent-name filter — the span's own agent, not a trace-level rollup. Reported back in the `agent` column, so a listing names the agents it can filter by; a span whose run declared no agent carries its service name there instead. | | `instance` | string | `""` | optional exact agent-instance filter, narrowing to one running copy of `agent`. | | `user_id` | string | `""` | optional end-user scope — the exact id, as the `user_id` column reports it. Here the column is the SPAN's own end user rather than a trace-level rollup, so every row of a scoped listing shows the id it matched on. (On list_agent_traces the same column name is the ROOT span's, which is why a trace row there can match and still read blank. When that happens, this tool is how you find the spans that did carry the user.) | | `anonymous` | boolean | `false` | list the spans carrying no end user instead of one user's. Pass either `user_id` or `anonymous`, never both. | | `search` | string | `""` | optional case-insensitive contains match on span name, span id, trace id, or session id. | | `error_text` | string | `""` | optional free text over the failure itself — the status message and any recorded exception. Finds a failing span by what it said. | | `filters` | any | `null` | optional list of `{"field": ..., "op": ..., "values": [...]}` clauses, ANDed and composable with the named parameters. Promoted columns (`status`, `agent`, `service`, `model`, `span_kind`, `operation`, `session_id`) are cheap over any window; `attr.` and `resource.` reach a customer's own attributes, cost ~10x more, and are accepted only over 31 days or less — narrow with a column first. Ops: eq, ne, in, not_in, gt, gte, lt, lte, exists, not_exists. Call describe_search_catalog before guessing a key. | | `sort_field` | string | `""` | optional sort column: "start_time" (default), "duration_ms", "tokens", or "cost". | | `sort_dir` | string | `""` | optional sort direction, "asc" or "desc" (default "desc"). | | `limit` | integer | `50` | max rows (default 50). | | `cursor` | string | `""` | opaque page token from a previous call's next-page cursor, to fetch the page after it. | > Show me every errored tool call in the last day. ```json { "name": "list_spans", "arguments": { "kind": "tool", "status": "Error" } } ``` > All spans in session user-42-chat-7. ```json { "name": "list_spans", "arguments": { "session_id": "user-42-chat-7" } } ``` ## list_users The window's END USERS as a ranked register: who your agents served. The end user is the person on the other side of the agent — the `user.id` your SDK stamps — not a console login and not an org member. The words are worth keeping straight: an ORG is the Rius customer, a WORKSPACE is one of their own clients, and an end user is that client's user. Read a `user_id` off this register and pass it to `user_activity_summary` for that person's KPIs, or to `list_agent_traces(user_id=...)` for their runs. This is the same read the console's Users page makes. TOP-N by design, not by accident: a B2C workspace can hold millions of end users, so the server ranks and caps. When it reports more, `q` reaches PAST the cap by exact id — it is an equality probe, never a substring search, so a fragment finds nothing rather than scanning millions of ids. Three figures that are easy to misread, so each travels with its caveat: anonymous traffic is always reported and is a real subject rather than an error case; coverage is counted in TRACES because one trace can belong to two end users under the any-span rule; and a null cost means nothing in the window was priced, which is not the same as free. | Argument | Type | Default | Description | |---|---|---|---| | `workspace` | string | `""` | optional workspace id, name, or `org-name/workspace-name` when the same name occurs in two of your orgs (defaults to your default; use list_workspaces to discover them). | | `hours` | integer | `24` | lookback window in hours (default 24), used for whichever of start/end is not given. The register is an unindexed group-by, so the window is capped at 31 days and a wider one is refused. | | `start` | string | `""` | optional absolute RFC3339 lower bound (e.g. "2026-08-01T00:00:00Z"); overrides the hours-derived value when given. | | `end` | string | `""` | optional absolute RFC3339 upper bound; overrides the hours-derived value when given. | | `sort` | string | `traces` | "traces" (default), "failed_traces", or "cost" — all descending. A value outside that set is refused rather than quietly defaulted, since a wrong ranking under a right-looking header cannot be caught later. | | `limit` | integer | `20` | users per page (default 20, server max 100). | | `q` | string | `""` | an EXACT end-user id. Returns that user's row even when they fall outside the top-N, or an empty register when the window holds nothing for them. | > Who are my busiest end users this week? ```json { "name": "list_users", "arguments": { "hours": 168 } } ``` > Which end users are seeing the most failures? ```json { "name": "list_users", "arguments": { "hours": 168, "sort": "failed_traces" } } ``` > Is u_8f2 in the last 30 days at all? ```json { "name": "list_users", "arguments": { "hours": 720, "q": "u_8f2" } } ``` ## list_workspaces List the workspaces you have access to (id and name). On an interactive (OAuth) login this spans every organization you belong to, grouped under each org's name; an API-key connection sees the single workspace its key is bound to. Use it to find the right value for the `workspace` argument of the trace, metrics and alert tools. That argument takes a workspace id, a workspace name, or — when the same name occurs in two of your orgs — the org-qualified `org-name/workspace-name` form. No arguments. > Which Rius workspaces do I have? ```json { "name": "list_workspaces", "arguments": {} } ``` ## update_alert_channel Change a notification channel: rename it, re-point it, or enable/disable it. Only what you pass changes; a channel's secrets are left alone if you do not resubmit them. A channel's type cannot be changed — create a new one instead. A channel that has failed to deliver several times in a row is disabled automatically; pass enabled true to bring it back once you have fixed it. Needs the `channels:manage` capability. | Argument | Type | Default | Description | |---|---|---|---| | `channel_id` | string | required | the channel's id, from list_alert_channels. | | `name` | string | `""` | a new label. | | `url` | string | `""` | for a webhook — a new https URL to POST to. | | `recipients` | any | `null` | for email — the full replacement list of addresses. | | `enabled` | any | `null` | turn delivery on or off. | | `workspace` | string | `""` | optional workspace id, name, or `org-name/workspace-name` when the same name occurs in two of your orgs (defaults to your default). | > Disable the ops webhook for now. ```json { "name": "update_alert_channel", "arguments": { "channel_id": "8a1…", "enabled": false } } ``` ## update_alert_rule Reconfigure or toggle one alert rule, predefined or custom. `ref` decides which: a kind name (consistent_error_pattern, silent_failure, tool_loop) addresses the predefined rule of that kind; a uuid addresses a custom rule. Get either from list_alert_rules. Only what you pass changes. Turning a rule off stops detection, not just notification — gaps in history are permanent and nothing backfills them. The two rule shapes take DIFFERENT settings, and mixing them is refused with a message naming the right one: * a predefined rule has named integer knobs -> pass `config` * a custom rule has metric thresholds -> pass `rules` (+ `window_minutes`) | Argument | Type | Default | Description | |---|---|---|---| | `ref` | string | required | the rule's kind or uuid. | | `enabled` | any | `null` | turn detection on or off. | | `rca_enabled` | any | `null` | turn root-cause analysis on or off for this rule. | | `name` | string | `""` | rename a custom rule (predefined rules take their name from their kind). | | `config` | any | `null` | for a PREDEFINED rule only — its named knobs, e.g. `{"min_errored_spans": 10}`. consistent_error_pattern takes window_minutes, min_errored_spans, min_distinct_traces; silent_failure takes window_minutes; tool_loop takes window_minutes, min_identical_calls. Call describe_alert_catalog for the bounds. | | `rules` | any | `null` | for a CUSTOM rule only — replace its thresholds. Replaces the whole list, so pass window_minutes with it. | | `window_minutes` | integer | `0` | the window. For a custom rule it is part of the replaced config, so pass `rules` too; for a predefined rule put it in `config`. | | `filters` | any | `null` | for a CUSTOM rule only — replace its filters. Replaces the whole list. Same shape and the same verbatim-value rule as create_alert_rule. | | `channel_ids` | any | `null` | change where the rule delivers. Needs `channels:manage`. An empty list does NOT silence the rule — it re-points it at the region's default webhook. To stop notifications, set enabled to false. | | `workspace` | string | `""` | optional workspace id, name, or `org-name/workspace-name` when the same name occurs in two of your orgs (defaults to your default). | > Turn off the tool loop alert. ```json { "name": "update_alert_rule", "arguments": { "ref": "tool_loop", "enabled": false } } ``` > Make the error pattern alert less noisy — 10 errors, not 3. ```json { "name": "update_alert_rule", "arguments": { "ref": "consistent_error_pattern", "config": { "min_errored_spans": 10 } } } ``` ## user_activity_summary Summary KPIs for ONE end user's activity over a time window: trace count, LLM calls, error rate, failed vs errored traces, sessions, total/average cost, token usage, and latency and TTFT percentiles. An "end user" here is the person your agents serve — the `user.id` your SDK stamps via `rius.user(...)` / `withUser(...)` — not a Rius account. Use it when someone arrives with a complaint and an identifier: "what did user u_8f2 experience this week" is one call, and the answer is a rollup rather than a trace list you have to fold yourself. Same read, same window and the same figures the Rius console's user page shows for that id, so a number you report and a number a human reads there are the same number. Field names match agent_traces_summary wherever they mean the same thing. Read the **Failed traces** and **Errored traces** lines as the two different questions they are, and do not add them together or report one as "errors": a run whose ROOT span errored FAILED, while a run that errored somewhere and then recovered did not. | Argument | Type | Default | Description | |---|---|---|---| | `user_id` | string | `""` | the end user's exact id, as `list_agent_traces` reports it in the `user_id` column — read one off a listing rather than guessing. Matched against any span of the trace, so a trace counts for this user if the user scope was open anywhere inside it, not only at the root. | | `anonymous` | boolean | `false` | summarise the traffic that carries NO end user instead. This is a real subject, not an error case: it answers "what is happening to the runs nobody attributed", and a high error rate there is worth knowing. It is the console's `?user=anonymous`. Pass either `user_id` or `anonymous`, not both. | | `workspace` | string | `""` | optional workspace id, name, or `org-name/workspace-name` when the same name occurs in two of your orgs (defaults to your default; use list_workspaces to discover them). | | `hours` | integer | `24` | lookback window in hours (default 24), used for whichever of start/end is not given. | | `start` | string | `""` | optional absolute RFC3339 lower bound (e.g. "2026-08-01T00:00:00Z"); overrides the hours-derived value when given. | | `end` | string | `""` | optional absolute RFC3339 upper bound; overrides the hours-derived value when given. | | `filters` | any | `null` | optional further `{"field": ..., "op": ..., "values": [...]}` clauses, ANDed with the user scope — the same grammar and registry as list_agent_traces. Call describe_search_catalog before guessing a key. | > What did user u_8f2 experience in the last 24 hours? ```json { "name": "user_activity_summary", "arguments": { "user_id": "u_8f2" } } ``` > How has that user's week been? ```json { "name": "user_activity_summary", "arguments": { "user_id": "u_8f2", "hours": 168 } } ``` > How much of our traffic has no user attached, and is it failing? ```json { "name": "user_activity_summary", "arguments": { "anonymous": true } } ``` > What did that user's gpt-4o runs cost? ```json { "name": "user_activity_summary", "arguments": { "user_id": "u_8f2", "filters": [{ "field": "model", "op": "eq", "values": ["gpt-4o"] }] } } ``` ## workspace_metrics_overview Aggregated health of a whole workspace over a time window: the numbers behind the dashboard's overview: volume (traces/spans/LLM calls), cost, tokens, latency percentiles, TTFT, error rates, each with its previous-window baseline and delta, plus ranked breakdowns (per model, top agents, calls by kind, top exceptions, slowest spans). Use this to answer "how is my workspace doing" before drilling into individual traces with list_agent_traces / get_agent_trace. Values are milliseconds for latency/TTFT; `—` means not measured (null), which is never the same as a measured 0. Metrics listed as degraded failed to compute and are absent rather than zero. | Argument | Type | Default | Description | |---|---|---|---| | `workspace` | string | `""` | optional workspace id, name, or `org-name/workspace-name` when the same name occurs in two of your orgs (defaults to your default; use list_workspaces to discover them). | | `hours` | number | `24` | lookback window in hours (default 24). Bucket grain is server-decided from the window length: ≤2h → minute, ≤48h → hour, else day. `minute` and `hour` buckets are window-relative (bucket k starts at `from + k×step`); `day` buckets are UTC calendar days, so the first and last cover only the part of their day inside the window and a low value there is that clip, not a drop. The rendered series states which of its edges are clipped. | | `minutes` | integer | `0` | lookback in minutes instead of hours, for short "last 10 minutes" windows (ignored when 0). | | `breakdowns` | boolean | `true` | include the ranked per-model / per-agent / per-kind tables (default true). | | `series` | boolean | `false` | include the per-bucket sparkline values (default false; they are verbose). | > How is my workspace doing today? ```json { "name": "workspace_metrics_overview", "arguments": {} } ``` > Anything wrong in the last 10 minutes? ```json { "name": "workspace_metrics_overview", "arguments": { "minutes": 10 } } ``` ## Next steps - [Example workflows](/rius/mcp/workflows): the trace tools composed into complete investigations. - [Quick connect](/rius/mcp#quick-connect): connecting a client if you have not yet. --- # Example workflows Four investigation patterns you can run entirely from your AI client once the Rius MCP server is [connected](/rius/mcp#quick-connect). Each starts from a plain-language prompt; the tool sequence shows what your client does with it. ## Investigate a slow agent run > My agent felt slow this afternoon. Find the slowest runs from the last 6 > hours and show me where the time went in the worst one. What the client does: 1. `list_spans` with `hours: 6, kind: "agent", sort_field: "duration_ms"`, which returns the agent runs in the window, longest first. 2. `get_agent_trace` with the slowest run's `trace_id`. Don't sort `list_agent_traces` for this: it returns the 20 newest traces by default, so sorting that page by `dur_ms` only finds the slowest of the 20. The waterfall shows every step indented by depth with its duration, so the bottleneck is visible at a glance: one LLM call dominating the total is a model latency problem, many sequential tool calls of similar size is a fan-out you could parallelize, and a gap between spans points at uninstrumented work. Follow-ups that work well in the same conversation: > Is that latency normal? Compare against the p95 for the last week. (The client calls `agent_traces_summary` with `hours: 168` and compares the percentiles against the slow run.) ## Find failed runs this week > Which of my agent runs failed this week, and what actually went wrong? What the client does: 1. `list_agent_traces` with `hours: 168, root_status: "Error"`. 2. `get_agent_trace` on one or more failing runs. `root_status: "Error"` keeps the runs whose root span ended in error, the genuine failures. `status: "Error"` matches any trace with an errored span, so it also returns runs that retried and recovered. The list returns 20 traces at a time; the reply carries a cursor for the next page. In the waterfall, the failed span carries the error status. Failed tool calls show up as error-status TOOL steps inside otherwise healthy runs, so `status: "Error"` answers "find failed tool calls" too. If the list is long, narrow it: > Only the checkout-agent service, and group the failures by root span name. (`service: "checkout-agent"` on the list call; the grouping happens in the client from the returned table.) ## Watch cost and compare models > What did my agents cost this week, and which service is spending the most? What the client does: 1. `agent_traces_summary` with `hours: 168` for the total. 2. `agent_traces_summary` per service (`service: ...`) for the split. Because `list_agent_traces` includes a `model` and `cost` column per trace, model-level comparisons work from the same data: > List this week's traces and compare average cost per run between the > gpt-4o runs and the gpt-4o-mini runs. For a recurring version of this, ask the same question tomorrow; the tools always answer from a lookback window ending now, so "this week" stays current. ## Let one agent learn from another's failures A supervisor agent checks your other agents on a schedule, finds the one that is failing, and passes what it learned to the team or back to that agent. Give the supervisor **its own key** with `read`, and a name, for example `X-MCP-Agent-Name: supervisor` (see [Name your agent](/rius/mcp#name-your-agent)). Then prompt it: > Every hour, use Rius to find the agent with the highest failed rate in the > last 24 hours. Group its errors, compare its current version with the > previous one, and read two failing traces. Summarise the most likely cause > and a suggested fix. A typical run calls: 1. `list_agents` for the agent names, then `agent_traces_summary` with `agent: ..., hours: 24` for each, to find the highest failed rate. (`list_agents` lists heartbeat instances only and has no error figures. To start from the failures instead, call `agent_error_groups` with `hours: 24` across the workspace.) 2. `agent_error_groups` with `agent: ...` to group that agent's failures by cause. 3. `agent_versions` for the versions that agent ran, then `compare_agent_versions` with `agent`, `dimension`, `base`, and `head` taken from that list, to check whether a new version introduced the problem. 4. `list_agent_traces` with `agent: ..., root_status: "Error"`, then `get_agent_trace` to read the failing runs. 5. Optionally, with `alerts:manage`: `create_alert_rule` to watch for the same failure next time. Add `channels:manage` if the rule should notify a channel. What the supervisor does with the result is up to you: post it to a channel, open a ticket, or pass it to the failing agent as context for its next run. The supervisor can't acknowledge alerts; a person always does that. Check that the loop is working on [Usage and access](/rius/mcp/usage-and-access): the supervisor shows up as a **Named** client with a high answered rate and a low **Asked again** rate. ## Writing your own The pattern behind the first three: start wide with `agent_traces_summary` (is anything wrong? how much?), narrow with `list_agent_traces` filters (which runs?), finish with `get_agent_trace` (why?). Any question you can phrase in those three steps works, and the [tool reference](/rius/mcp/tools) lists every filter available at each step. ## Next steps - [Tool reference](/rius/mcp/tools): every argument available at each step. - [Usage and access](/rius/mcp/usage-and-access): see what your agents ask and whether they get an answer. - [Exploring traces](/rius/platform/exploring-traces): the same investigations in the console, when you want the full waterfall UI. --- # Interoperability Rius is convention-native OpenTelemetry: you can send traces without the SDK, from OpenLLMetry, OpenInference, vanilla OTel SDKs, or any OTLP-speaking collector. Two kinds of pages here: - The [span attribute reference](/rius/interoperability/attributes) is the contract: the OTLP endpoint, the attributes that drive taxonomy, model analytics, and cost, the GenAI message shape, and the supported-conventions matrix stating exactly what each attribute family gets today. - Sender guides wire specific setups to that contract: [vanilla OTel SDKs](/rius/interoperability/otel-sdks) for any language, [OpenLLMetry](/rius/interoperability/openllmetry) and [OpenInference](/rius/interoperability/openinference) for already-instrumented apps, and the [OTel Collector](/rius/interoperability/collector) for routed or fanned-out pipelines. Native SDKs exist for [Python and TypeScript](/rius/sdk). Everything in this section works from any language, because the endpoint is plain OTLP. --- # Span attribute reference The wire format Rius reads. If you emit spans from anything other than the SDKs (a vanilla OpenTelemetry SDK, a collector pipeline, another language), this page tells you which attributes to set so your traces get the same analytics as SDK-emitted ones. ## Where to send spans OTLP/HTTP with protobuf encoding: ```text POST https://ingest.eu.console.rius-glassflow.com/v1/traces Authorization: Bearer Content-Type: application/x-protobuf ``` The contract in full: - **Host**: region-qualified. All Rius endpoints carry the region in the subdomain (`ingest.eu.console.rius-glassflow.com`, `eu.console.rius-glassflow.com`); use your workspace's region. Examples throughout these docs use `eu`. - **Protocol**: OTLP/HTTP, either protobuf (`http/protobuf`, recommended) or JSON (`http/json`); there is no gRPC endpoint. JSON requests get JSON replies. Protobuf is the default of the Python, Go, and Java OTLP/HTTP exporters and of the collector's `otlphttp` exporter. In Node it is not: `@opentelemetry/exporter-trace-otlp-http` sends JSON, which works, but `@opentelemetry/exporter-trace-otlp-proto` is the better choice (the Rius TypeScript SDK already uses it). - **Compression**: `Content-Encoding: gzip` is accepted (and worth enabling; span batches compress well). - **Body limit**: 16 MiB per request. Exporters' default batch sizes sit far below this. - **Auth**: `Authorization: Bearer` with an API key from the console. `401` means the key is wrong or revoked. Setup for each common sender is one page away: a [vanilla OpenTelemetry SDK](/rius/interoperability/otel-sdks), [OpenLLMetry](/rius/interoperability/openllmetry), [OpenInference](/rius/interoperability/openinference), or an [OpenTelemetry Collector](/rius/interoperability/collector). ## Span taxonomy | Attribute | Values | Effect | |---|---|---| | `openinference.span.kind` | `AGENT`, `LLM`, `TOOL`, `RETRIEVER`, `EMBEDDING`, `CHAIN` | Classifies the span in trace views and per-kind analytics | | `gen_ai.operation.name` | `chat`, `text_completion`, `generate_content`, `embeddings`, `execute_tool`, `invoke_agent`, `create_agent`, `retrieval`, `invoke_workflow`, ... | The OpenTelemetry GenAI operation taxonomy | Set either one and the platform derives the other: `chat`, `text_completion`, and `generate_content` are `LLM`, `invoke_agent` and `create_agent` are `AGENT`, `execute_tool` is `TOOL`, `embeddings` is `EMBEDDING`, `retrieval` is `RETRIEVER`, and `invoke_workflow` is `CHAIN`. The SDKs set both. An **LLM call**, as the console and alerts count it, is an inference call: a span whose kind is `LLM`, set directly or derived from a `chat`, `text_completion`, or `generate_content` operation. A span with neither a kind nor an operation counts when it carries `gen_ai.request.model`. Agent, tool, and retrieval spans are not LLM calls even when they carry a model, and embedding calls are not either; their cost still appears in the per-model breakdown and the cost totals. Name spans the way the GenAI conventions ask, the operation followed by what it acted on: `chat gpt-4o`, `execute_tool get_weather`, `invoke_agent planner`, `retrieval product-kb`. The platform does not require it, but it is what the SDKs emit, so mixed fleets read alike. ## Agents, tools, and retrieval | Attribute | Applies to | Notes | |---|---|---| | `gen_ai.agent.name` | `invoke_agent` spans | The agent being invoked | | `gen_ai.agent.name` | `execute_tool` spans | The agent executing the tool | | `gen_ai.agent.id` / `gen_ai.agent.version` | `invoke_agent` spans | A hosted agent's id, and the invoked agent definition's version | | `gen_ai.tool.name` | `execute_tool` spans | The tool's own name, never the span name | | `gen_ai.tool.call.id` | `execute_tool` spans | The id of the model's tool call this execution answers | | `gen_ai.tool.type` | `execute_tool` spans | `function`, `extension`, `datastore`, ... | | `gen_ai.data_source.id` | `retrieval` spans | The index, collection, or knowledge base searched | | `gen_ai.retrieval.top_k` / `gen_ai.retrieval.documents` | `retrieval` spans | Documents asked for, and the `{"id", "score"}` list returned | | `error.type` | any span that ended in an error | A low-cardinality error class, such as `anthropic.NotFoundError` or `tool_error` | ## LLM analytics These drive model analytics and cost computation: | Attribute | Type | Notes | |---|---|---| | `gen_ai.request.model` | string | The requested model | | `gen_ai.usage.input_tokens` | int | Prompt tokens, including cached ones | | `gen_ai.usage.output_tokens` | int | Completion tokens, including reasoning ones | | `gen_ai.usage.cache_read.input_tokens` / `gen_ai.usage.cache_write.input_tokens` | int | Prompt-cache reads and writes, subsets of the input count | | `gen_ai.usage.reasoning.output_tokens` | int | Reasoning tokens, a subset of the output count | | `gen_ai.provider.name` | string | For example `openai` or `anthropic` | | `gen_ai.response.model` | string | Model reported by the provider | | `gen_ai.response.id` | string | The provider's completion id | | `gen_ai.request.*` | per key | The request parameters the GenAI conventions define, for example `gen_ai.request.temperature` or `gen_ai.request.max_tokens` | | `rius.request.*` | any | Request parameters the conventions do not define, under their own key, for example `rius.request.tool_choice` | | `gen_ai.response.finish_reasons` | string[] | Why generation stopped | | `gen_ai.response.time_to_first_chunk` | double | Seconds from the span start to the first streamed chunk | **Cost is computed server-side** from `gen_ai.request.model` plus the two `gen_ai.usage.*` token counts. A span missing any of the three gets no cost. Never send a cost attribute; send tokens and the model name. ## Content | Attribute | Applies to | Notes | |---|---|---| | `gen_ai.input.messages` / `gen_ai.output.messages` | LLM spans | JSON in the GenAI message shape (below) | | `gen_ai.system_instructions` | LLM spans | A system prompt sent separately from the chat history, as a JSON array of `{"type": "text", "content": ...}` parts. Counted as the system prompt in context attribution | | `gen_ai.tool.definitions` | LLM spans | The tool definitions the model was shown | | `input.value` / `output.value` | any span | Generic input/output, JSON or plain text | Content attributes are stored for trace inspection and are the ones covered by the SDK's [privacy controls](/rius/sdk/advanced#privacy-controls) when you export through it. ### The GenAI message shape `gen_ai.input.messages` and `gen_ai.output.messages` carry a JSON array of messages, each `{"role", "parts": [...]}`. Text parts are `{"type": "text", "content": ...}`; tool interactions have dedicated part types: ```json [ {"role": "user", "parts": [{"type": "text", "content": "What is 2+2?"}]}, { "role": "assistant", "parts": [ {"type": "tool_call", "id": "call_1", "name": "calculator", "arguments": "{\"expr\": \"2+2\"}"} ] }, { "role": "tool", "parts": [{"type": "tool_call_response", "id": "call_1", "response": "4"}] } ] ``` This is the OpenTelemetry GenAI message schema; the SDK's `set_input()` / `set_output()` normalize OpenAI-style dicts into it ([message formats](/rius/sdk/tracing#message-formats)). When emitting directly, produce this shape yourself so message rendering in the console works. Spans carrying it render their prompt and completion on the span's **Input / Output** tab: ![Prompt and completion rendered from GenAI message attributes](/assets/ui_span_genai.png) Spans without these attributes show "Content not captured" there; the rest of the span (timings, tokens, cost) is unaffected. ### List-valued attributes An attribute sent as an OTLP array or key-value list, such as `gen_ai.response.finish_reasons`, is stored as plain JSON: `["stop"]`, or an object for a key-value list. A saved search or alert that matches the stored text should match that form. Spans ingested before this storage change keep the older OTLP envelope form (`{"arrayValue":{"values":[...]}}`), and those rows are not rewritten. ### Context sizes The SDKs also send `rius.context.sizes` on every generation: a compact JSON record of the byte size of each tool definition and each message part. Rius uses it to divide a call's input tokens across the parts of its context, and it survives content stripping because it holds no content. It is optional: without it, the platform estimates the same breakdown from the captured messages, `gen_ai.system_instructions`, and tool definitions. ## Span events | Event name | Meaning | |---|---| | `gen_ai.first_token` | First streamed chunk arrived; time to first token is derived as this event's time minus the span start. The SDKs also set `gen_ai.response.time_to_first_chunk` and `gen_ai.request.stream: true` alongside it | | `exception` | Standard OpenTelemetry exception event (`record_exception`); surfaces in error analysis | For streaming LLM calls, emit `gen_ai.first_token` once, when the first content chunk arrives. The SDK's [`record_first_token()`](/rius/sdk/tracing#streaming-responses) does exactly this. ## Sessions and users | Attribute | Type | Notes | |---|---|---| | `session.id` | string | Groups the traces of one [session](/rius/concepts#sessions), such as a conversation or an agent run. Set it on every span of the trace, not only the root: the platform reads it per span, and a span without it falls back to being grouped by its trace id. | | `user.id` | string | The [user](/rius/concepts#users) a request served, on every span in scope. The platform also reads `enduser.id`, then `enduser.pseudo.id`, when `user.id` is absent. A span with none of them is anonymous. | The [SDK's session and user scopes](/rius/sdk/tracing#sessions) stamp these attributes for you; third-party senders set them directly. ## Resource attributes | Attribute | Effect | |---|---| | `service.name` | The service every trace view and filter groups by. Always set it. | | `service.version` | The build or release the process runs. | | `service.instance.id` | The process that produced the span; the SDKs send the same id in their heartbeats, which joins traces to the Agents view. | | `rius.main_agent.name` | The agent the process runs. The platform files a span under the first of `rius.main_agent.name`, the resource `gen_ai.agent.name`, the span's `gen_ai.agent.name`, and `service.name` that is set and is not a placeholder such as `unknown_service`. | | `rius.main_agent.id` / `rius.main_agent.description` / `rius.main_agent.version` | A stable id for that agent, what it does, and the version of its definition. | ## Attribute count limit OpenTelemetry SDKs keep at most 128 attributes per span unless configured otherwise, and drop the rest without an error. Instrumentations that flatten messages and tools into one attribute per field, OpenInference among them, pass that within a few turns of an agent loop, and the span then loses its model, tools, usage, or messages. The Rius SDKs raise the limit to 4096. When you export without them, set it yourself: ```bash export OTEL_SPAN_ATTRIBUTE_COUNT_LIMIT=4096 ``` ## Supported conventions What each attribute family gets today. "Analytics" means the promoted columns above (taxonomy, model, tokens, cost, time to first token); "stored" means the attribute lands with the span and is searchable in trace inspection either way. | Convention | Attributes | Analytics | Stored | |---|---|---|---| | OTel GenAI | `gen_ai.*` as documented above | ✓ Full: taxonomy, model, tokens, cost, TTFT | ✓ | | OpenInference kind | `openinference.span.kind` | ✓ Taxonomy | ✓ | | OpenInference generic I/O | `input.value` / `output.value` | ✓ Content | ✓ | | OpenInference LLM | `llm.model_name`, `llm.provider`, `llm.token_count.*`, `llm.finish_reason`, `llm.invocation_parameters`, `llm.tools.*`, `llm.input_messages.*` / `llm.output_messages.*` | ✓ Normalized at ingest | ✓ | | OpenInference session and user | `session.id`, `user.id` | ✓ Session and user grouping | ✓ | | OpenLLMetry / Traceloop | `traceloop.span.kind`, `traceloop.entity.*`, `llm.request.type`, legacy `gen_ai.usage.prompt_tokens` / `completion_tokens`, legacy `gen_ai.prompt.*` / `gen_ai.completion.*` | ✓ Normalized at ingest | ✓ | | Anything else | your own attributes | ✗ | ✓ | "Normalized at ingest" means the platform moves the values onto their canonical keys before storage. Native `gen_ai.*` keys always win; normalization fills gaps, never overwrites. For OpenInference: - The request model comes from `llm.request.model_name`, else the `model` member of `llm.invocation_parameters`, else `llm.model_name`. The response model comes from `llm.response.model_name`, else `llm.model_name`, but only when the call did not fail: a span with ERROR status gets no response model, because no response arrived. - `llm.token_count.prompt` / `completion` and their cache and reasoning details fill the token counts, which is what makes cost computation work. - The recognized members of `llm.invocation_parameters` become `gen_ai.request.*` and `rius.request.tool_choice`; its `tools` become `gen_ai.tool.definitions`, as do the indexed `llm.tools.*` schemas, and Anthropic's `system` parameter becomes the leading system message. - The flattened `llm.input_messages.*` / `llm.output_messages.*` are reassembled into the GenAI message shape, and the first-token span event is renamed to `gen_ai.first_token`. For OpenLLMetry, the Traceloop decorator kinds (workflow, task, agent, tool) and the provider span's `llm.request.type` become the span taxonomy; the decorated entity's name becomes the tool or invoked agent name; `traceloop.entity.input` / `output` become `input.value` / `output.value`; the older usage and streaming spellings move to their current keys; and the flattened `gen_ai.prompt.*` / `gen_ai.completion.*` messages are reassembled into the GenAI message shape. Keys with no canonical equivalent, such as `llm.usage.total_tokens`, ride through under their own names. The Rius SDKs apply the same OpenInference mapping in your process before export, apart from the `llm.model_name` fallback, which only the platform applies. See [what the SDK normalizes](/rius/sdk/integrations#what-the-sdk-normalizes). Unknown attributes are never dropped and never an error. ## Next steps - [Vanilla OpenTelemetry SDKs](/rius/interoperability/otel-sdks): emitting these attributes from any language. - [OpenTelemetry Collector](/rius/interoperability/collector): routing them through a collector pipeline. --- # Vanilla OpenTelemetry SDKs Any language with an OpenTelemetry SDK can send traces to Rius today: the ingest endpoint is standard OTLP/HTTP. This is the path for languages without a native SDK (everything except Python and TypeScript). ## Configuration by environment variables Every OTel SDK honors the standard exporter variables, so this works unchanged in Go, JS/TS, Java, Rust, .NET, and Python: ```bash export OTEL_EXPORTER_OTLP_ENDPOINT="https://ingest.eu.console.rius-glassflow.com" export OTEL_EXPORTER_OTLP_PROTOCOL="http/protobuf" export OTEL_EXPORTER_OTLP_HEADERS="authorization=Bearer " export OTEL_SERVICE_NAME="my-agent" # Keep long LLM spans whole; the default of 128 attributes is too low export OTEL_SPAN_ATTRIBUTE_COUNT_LIMIT=4096 ``` `http/protobuf` is the default protocol in most SDKs and the one we recommend, but set it explicitly: the endpoint accepts OTLP/HTTP in protobuf or JSON, and no gRPC (see the [contract](/rius/interoperability/attributes#where-to-send-spans)). In Node, the exporter package decides the encoding: `@opentelemetry/exporter-trace-otlp-proto` sends protobuf, while `@opentelemetry/exporter-trace-otlp-http` sends JSON, which also works. The attribute limit matters as soon as a span carries messages or tool definitions as one attribute per field; see [Attribute count limit](/rius/interoperability/attributes#attribute-count-limit). ## Emitting a well-formed LLM span The attributes decide what analytics you get. A minimal JS/TS example with everything the platform reads: ```typescript const tracer = trace.getTracer('my-agent') const span = tracer.startSpan('chat gpt-4o') span.setAttributes({ 'openinference.span.kind': 'LLM', 'gen_ai.operation.name': 'chat', 'gen_ai.request.model': 'gpt-4o', 'gen_ai.provider.name': 'openai', }) const response = await callTheModel() span.setAttributes({ 'gen_ai.usage.input_tokens': response.usage.prompt_tokens, 'gen_ai.usage.output_tokens': response.usage.completion_tokens, 'gen_ai.response.model': response.model, 'gen_ai.output.messages': JSON.stringify([ { role: 'assistant', parts: [{ type: 'text', content: response.text }] }, ]), }) span.end() ``` Model, tokens, and messages make the span a full generation: it gets cost computed server-side and appears in model analytics. The complete attribute tables, including the message shape and the streaming first-token event, are in the [span attribute reference](/rius/interoperability/attributes). Nest spans the normal OpenTelemetry way (parent context) and they arrive as one trace. Wrap each agent run in a single root span; that root's name, duration, and status are what run-level views show. ## What you give up versus a native SDK Raw OTel emission is fully supported, permanently. The native SDKs add conveniences on top of it, not a different protocol: message normalization, mapping third-party attribute dialects onto the canonical keys, a raised attribute limit, idempotent first-token capture, export-time privacy controls, and the auto-instrumentation integrations. Code written against raw OTel keeps working unchanged if you later adopt a native SDK. ## Next steps - [Span attribute reference](/rius/interoperability/attributes): every attribute the platform reads, and the GenAI message shape. - [OpenTelemetry Collector](/rius/interoperability/collector): put a collector between your services and the endpoint. --- # OpenLLMetry If your application is already instrumented with OpenLLMetry (Traceloop's SDK), point its exporter at Rius and your existing traces flow in; no re-instrumentation needed. ## Point the exporter here ```python from traceloop.sdk import Traceloop Traceloop.init( app_name="my-agent", api_endpoint="https://ingest.eu.console.rius-glassflow.com", headers={"Authorization": "Bearer "}, ) ``` OpenLLMetry exports OTLP/HTTP protobuf by default, which is exactly what the endpoint expects. The same values can come from OpenLLMetry's environment variables if you prefer configuration over code. ## What gets captured Everything OpenLLMetry emits is stored and inspectable: traces arrive, spans nest, prompt and completion content is visible in trace inspection. OpenLLMetry has used several attribute conventions across versions, and the platform normalizes all of them at ingest onto the canonical keys: current releases already emit OTel GenAI (`gen_ai.*`) attributes; older ones flatten messages into `gen_ai.prompt.*` / `gen_ai.completion.*`, spell usage as `gen_ai.usage.prompt_tokens` / `completion_tokens`, and mark streaming as `llm.is_streaming`. The Traceloop decorators' `traceloop.span.kind` (workflow, task, agent, tool) becomes the span taxonomy, the decorated function's name becomes the tool or agent name, and `traceloop.entity.input` / `output` become the span's input and output. Model, token, and cost analytics work across those versions; the mapping in full is in the [supported-conventions matrix](/rius/interoperability/attributes#supported-conventions). Two things are not mapped yet: the per-completion `gen_ai.completion.N.finish_reason` of older releases, and the flattened tool definitions under `llm.request.functions.*`. Both are stored under their own names. Verify in one minute: run one traced LLM call, open the trace in the console, and check the span shows a model name and token counts. For long agent runs on an older release, raise OpenTelemetry's per-span attribute limit, since those releases record messages one attribute per field; see [Attribute count limit](/rius/interoperability/attributes#attribute-count-limit). ## Next steps - [Span attribute reference](/rius/interoperability/attributes): which OpenLLMetry attribute families map to analytics today. - [OpenTelemetry Collector](/rius/interoperability/collector): fan out to Rius next to your existing backend while you evaluate. --- # OpenInference OpenInference instrumentors (the ones behind Arize Phoenix) work with Rius directly: they emit standard OpenTelemetry spans, so they only need an OTLP exporter pointed at the ingest endpoint. The Rius SDKs ship these same instrumentors as [integrations](/rius/sdk/integrations) and wire the exporter, the span attribute limit, privacy controls, and reliability behavior for you. This page is for running OpenInference **without** the SDK. ## Wiring an instrumentor ```python from opentelemetry.sdk.trace import SpanLimits, TracerProvider from opentelemetry.sdk.trace.export import BatchSpanProcessor from opentelemetry.exporter.otlp.proto.http.trace_exporter import OTLPSpanExporter from openinference.instrumentation.openai import OpenAIInstrumentor # Raise the attribute limit: see "Raise the span attribute limit" below. provider = TracerProvider(span_limits=SpanLimits(max_span_attributes=4096)) provider.add_span_processor( BatchSpanProcessor( OTLPSpanExporter( endpoint="https://ingest.eu.console.rius-glassflow.com/v1/traces", headers={"Authorization": "Bearer "}, ) ) ) OpenAIInstrumentor().instrument(tracer_provider=provider) ``` Note the exporter class: `otlp.proto.http` (protobuf over HTTP). The endpoint also accepts OTLP/JSON, but no gRPC. In Node, use `@opentelemetry/exporter-trace-otlp-proto`; the similarly named `@opentelemetry/exporter-trace-otlp-http` sends JSON, which works too. ## Raise the span attribute limit OpenInference writes one attribute per message field and per tool field, and OpenTelemetry keeps only 128 attributes per span by default. An agent loop with about ten tools passes that after six to nine turns, and from then on the span silently loses attributes: the model, request parameters, tool definitions, and system prompt in Python, the usage, output, and finish reason in Node. Raise the limit, either in code as above or for any language through the environment: ```bash export OTEL_SPAN_ATTRIBUTE_COUNT_LIMIT=4096 ``` The Rius SDKs set 4096 for you. ## What gets captured Everything. `openinference.span.kind` drives the span taxonomy (LLM, TOOL, CHAIN, ...), `input.value` / `output.value` are captured as span content, and the LLM detail attributes (`llm.model_name`, `llm.provider`, `llm.token_count.*`, `llm.invocation_parameters`, `llm.tools.*`, `llm.input_messages.*`) are **normalized into their `gen_ai.*` equivalents at ingest**, so OpenInference-instrumented calls get model analytics, token usage, and server-side cost like native spans. On streamed calls from the Python OpenAI instrumentor, the first-token event is likewise normalized to `gen_ai.first_token`, feeding time-to-first-token. Without the SDK there are no [privacy controls](/rius/sdk/advanced#privacy-controls) in your process: everything the instrumentor records, including the full request-parameter bag, is sent as recorded. Details of the mapping, including the native-wins precedence rule, are in the [supported-conventions matrix](/rius/interoperability/attributes#supported-conventions). ## Next steps - [Integrations](/rius/sdk/integrations): the same instrumentors, wired by the SDK, if your app is Python. - [Span attribute reference](/rius/interoperability/attributes): the full normalization contract. --- # OpenTelemetry Collector Route traces to Rius through an OpenTelemetry Collector when you want a single egress point, local buffering, or to fan the same traces out to more than one backend. ## Exporter configuration ```yaml exporters: otlphttp/glassflow: endpoint: https://ingest.eu.console.rius-glassflow.com # proto is the default encoding and the recommended one; json works too encoding: proto compression: gzip headers: authorization: Bearer ${env:RIUS_API_KEY} service: pipelines: traces: receivers: [otlp] processors: [batch] exporters: [otlphttp/glassflow] ``` The `otlphttp` exporter appends `/v1/traces` to the endpoint itself; give it the base URL. Keep the API key out of the config file via the `${env:...}` substitution shown. Use the `otlphttp` exporter, not `otlp`: the plain `otlp` exporter speaks gRPC, which the endpoint does not accept. ## Fan-out to a second backend Trying Rius next to an existing backend is one list entry, no application changes: ```yaml service: pipelines: traces: receivers: [otlp] processors: [batch] exporters: [otlphttp/glassflow, otlphttp/existing] ``` ## What gets captured The collector forwards spans unchanged, so analytics depend on what your applications emit, exactly as if they exported directly: see the [span attribute reference](/rius/interoperability/attributes) and its supported-conventions matrix. Collector processors that rename or drop attributes (`attributes`, `transform`) sit between your apps and those tables; if analytics fields come up empty, check the collector is not stripping `gen_ai.*` keys. ## Next steps - [Span attribute reference](/rius/interoperability/attributes): the contract the forwarded spans are read against. - [Vanilla OpenTelemetry SDKs](/rius/interoperability/otel-sdks): what the applications behind the collector should emit. --- # Release notes Notable changes to Rius, newest first. The hosted platform updates in place, so a platform release needs nothing from you unless its notes say so. SDK releases are yours to install; each SDK's full changelog is on GitHub ([Python](https://github.com/glassflow/rius-sdk-python/releases), [TypeScript](https://github.com/glassflow/rius-sdk-typescript/releases)). ## 2026-09-29: platform release, MCP server 0.10.0, SDK 1.0.0 **Action needed if you use the Python SDK's `GLASSFLOW_*` environment variables.** SDK 1.0.0 reads only `RIUS_*` names. See [Upgrading to 1.0](/rius/sdk/upgrading) before you upgrade. ### Search and filters - **A new filter bar on Traces and Spans.** Build filters as chips, combine them, exclude values, and share the result: filters now live in the URL. See [Search and filter](/rius/platform/exploring-traces#search-and-filter). - **Filter on any attribute.** Any span or resource attribute your agents send can be filtered, with suggested values. Suggestions skip payload attributes such as prompts, completions, and tool input and output, and long values. - **Declared workspace attributes.** Admins declare the attributes that matter to the team under **Settings → Attributes**, and declared attributes show up by their label in search. You can also declare an attribute straight from a span's attribute menu. - **Saved searches.** Save a filter set with a relative time window, such as the last 7 days, and come back to it. A saved search is private by default, or shared with everyone in the workspace. - **Span attribute actions.** On any span attribute you can filter by it, exclude it, copy it, or declare it. - **The health strip follows your search.** The summary above the trace list reflects your current filters. - New columns on the trace list: **User**, **Sent by** (who owns the API key that sent the trace), **Instance**, and **Version**, shown when your traces carry them. The trace header adds the session, linked to all its spans. Each is also a filter. ### Shared views - **Shared links keep your filters.** A shared view opens with the filters you had applied, and the viewer sees which filters are active. - **Public links show less.** A shared view no longer shows input and output previews, end user ids, instance ids, or who sent a trace. ### Agents - **Richer agent pages:** summary tiles scoped to the time window, Exceptions, Context usage, Versions, and Drift, plus a heartbeat timeline. - **LIVE and Cost columns** in the agents list. - **"Failed" is now "Errored traces"** everywhere. - **Time to first token** counts only calls where it was measured, and the console shows how many LLM calls that is ("n of m LLM calls measured"). - **LLM call counts** include model calls only. Embedding calls are no longer counted as LLM calls. - **Agent naming.** Agents are named from `rius.main_agent.name`, or `gen_ai.agent.name`. A process that sends neither no longer appears as an agent named after its service. The SDKs set both from `agent_name` (`RIUS_AGENT_NAME`), which defaults to `service_name`, so set a service name. With a plain OpenTelemetry SDK, set `rius.main_agent.name` as a resource attribute. - Traces that arrive without a root span now get an inferred root, so they count toward the right agent. ### End users - Rius picks up the end user from `user.id`, `enduser.id`, or `enduser.pseudo.id` on your spans. - Traces get a **User** column and a user filter. - **Users page.** A register of your end users, with a page per user showing their activity. See [Users](/rius/platform/users). ### Alerts and root-cause analysis - **Run root-cause analysis on demand** with **Run analysis** on a firing. Analyses have a monthly budget. Firings show the analysis status, for example **Over budget** or **No report**. See [Root-cause analysis on demand](/rius/platform/alerts#root-cause-analysis-on-demand). - **Reminder countdown.** A firing shows when the next reminder will be sent. - **More alert filters:** operation, session, instance, and "not in". Predefined alert kinds accept filters as well. - **Rule health.** A rule that keeps failing is detected, recorded, and stopped automatically, and one failing rule no longer affects the others. - **Editing a rule resolves its open alerts** and starts evaluating the rule afresh. - During this upgrade, a predefined rule could send one duplicate notification for an alert that was already open. ### Context and cost - **Context usage** on traces and spans: how much of the model's context window was used, including reasoning tokens and the provider preamble. - **Unknown cost is shown as blank instead of $0.** A call with no usage data no longer looks free. - **Cost and context window for more model ids.** Models called through Vertex AI (ids like `claude-sonnet-4-5@20250929`) and through gateways that prefix the vendor (ids like `openai.gpt-4.1`) now show cost and context-window numbers. Models that already showed them are unchanged. ### Instrumentations The platform now understands and normalizes spans from more instrumentation libraries: - **OpenLLMetry / Traceloop** - **Laminar**, including OpenHands agents - **OpenInference** (Arize), including tool definitions, cached and reasoning token counts, and tool choice See [Interoperability](/rius/interoperability). ### Data format changes for new data These apply to spans received after the upgrade. Spans you already stored are unchanged. - List-valued attributes are stored as JSON arrays. - Tool definitions are stored as a single JSON array. - Embedding vectors are no longer stored. If you have saved searches or alert filters that match the old text form of a list attribute, re-create them. ### API keys and workspaces - **Edit an API key** (name and scopes) without re-issuing it. The MCP page's Access tab shows whether each key is active and when it was last used. - Agent heartbeats are on by default. - Workspace names are limited to 60 characters. - Invitations that expire without being accepted are cleaned up automatically. ### MCP server 0.10.0 - **Eight new tools:** `describe_search_catalog`, `list_agents`, `agent_error_groups`, `agent_lifecycle_events`, `user_activity_summary`, `list_users`, `agent_versions`, and `compare_agent_versions`. See the [tool reference](/rius/mcp/tools). - Trace and span tools accept the same **filters** as the console, plus text search, error text, and user filters. - **Session and "sent by" columns** in call results, time-bucketed summaries (`group_by="bucket"`), and an optional `X-MCP-Agent-Name` header so an MCP client can declare its agent name. - **Multiple organizations.** `get_me` lists all your organizations. Pass a workspace as `org/workspace` when a name exists in more than one organization; an ambiguous name now returns an error. - **The MCP page in the console** has tabs for the overview, sessions, clients, tools, access, and queries. See [Usage and access](/rius/mcp/usage-and-access). - **What we log about MCP calls.** Rius records allow-listed tool arguments and row counts for each MCP call, so you can review your agents' usage. Tool results are never stored. Call-log rows are kept for 30 days. ### Plans and billing - **New organizations start on a 30-day trial** and subscribe to a plan from **Settings → Plan & usage** through Stripe Checkout. See [Plans and billing](/rius/platform/billing). - Organizations created before this release are not affected. ### SDK 1.0.0 (`glassflow-rius`, `@glassflow-ai/rius`) Version 1.0.0 finishes the move from the GlassFlow name to Rius and aligns span names with the OpenTelemetry GenAI conventions. The breaking changes and how to migrate are in [Upgrading to 1.0](/rius/sdk/upgrading). In short: - Python reads only `RIUS_*` environment variables. - The pending-span attribute is `rius.span.pending`, and the tracer scope is `rius`. - Unnamed spans are named `chat {model}`, `embeddings {model}`, `execute_tool {tool}`, `invoke_agent {agent}`, and `retrieval {data_source}`. - `model_parameters` land on the standard `gen_ai.request.*` keys, and anything else under `rius.request.*`, including `response_format`. - Spans can carry up to 4096 attributes, up from 128. - Rius can bridge the tracer provider of another OpenTelemetry SDK in the same process (Langfuse, Traceloop, Logfire, MLflow, OpenLIT, Laminar). The bridge is off by default; set `RIUS_BRIDGE_FOREIGN_PROVIDER=1` to turn it on. ### Other - Terms and Privacy links now point to glassflow.ai. --- # Introduction Tares is the open-source platform for always-on AI agents. Chat agents wait for a prompt. Tares agents wait for an event: every event from your systems lands on one timeline per thing, a trigger wakes an agent the moment it matters, and the finding it writes back is there for the next reader. Using a coding assistant? Start with [AI resources](/tares/agents/ai-resources), a page written for it. ## What is Tares? Tares sits between the systems you already run and the agents you want working on them. - **Connect anything that emits events.** Logs, metrics, alerts, deploys, commits, database rows, webhooks. A connector turns each one into events; nothing to change on the source side. - **One timeline per thing.** Every event that concerns a service, a repo, a customer or a job is merged into one time-ordered timeline for it. An agent asks "what happened to `checkout`?" once and gets the whole picture, across all sources. - **Agents that run on what happens.** Triggers watch the timelines. When a condition fires, Tares wakes an agent with the correlated timeline already in hand, over MCP or a webhook, or runs a Tares agent in-process. - **Findings that stay.** What the agent concludes is written back onto the timeline as an event. The next reader, human or agent, starts from the last conclusion instead of from scratch. Tares is MIT licensed, runs on your machine or your server, and stores everything in one local DuckDB file. No external database, no broker, no telemetry. ![Explore's agent payload: one correlated read for a service, exactly as an agent receives it](/assets/tares-explore-agent-view.png) ## How it works Four steps. 1. **Sources** bring events in. Poll connectors (Prometheus, GitHub, Postgres, Docker logs) fetch on an interval; push connectors (OTLP, Alertmanager, Vercel, webhooks) receive over HTTP. Each event keeps its original payload. [Connectors](/tares/connectors) 2. **Labels** join sources on a shared key. Events labeled `service=api-server` from logs, metrics, alerts and deploys read as one timeline for `api-server`. [Concepts](/tares/concepts) 3. **Triggers** watch a set of sources and fire on a condition: an alert lands, an error rate crosses a line, a commit touches a path. A cooldown keeps one incident from firing a hundred times. [Triggers](/tares/guides/triggers) 4. **Agents** get woken. An external agent receives the timeline over a webhook or reads it over MCP; a Tares agent runs inside Tares on your prompt and writes its finding back. [Tares agents](/tares/tares-agents), [Connecting agents](/tares/agents) A **project** holds the triggers and agents that do one job, the sources they read, and the skills its agents follow, and shows everything that happened on one page. [Projects](/tares/projects) Underneath, one daemon (`taresd`) serves the HTTP API and the console, and `tares-mcp` exposes the read and watch tools to any MCP client. ## Two ways to build Keep the agent you have (Claude Code, Cursor, Codex, your own loop) and give it one MCP call that returns the correlated history of anything. Best when you already run an agent and want it to stop stitching ten tool calls together. Write a prompt, attach it to a trigger, done. Tares runs it in-process when the trigger fires, reads the timeline, and writes a finding. Best when nobody is at a keyboard when it matters. The two combine: a Tares agent writes the first look, your coding agent picks it up from the timeline when you sit down. ## Key capabilities - **Correlated reads.** `read(selector, window)` returns any entity's timeline across all sources, or only a project's; `create_trigger` lets an agent set up its own watch. - **Triggers and delivery.** Conditions over live data, cooldowns, delivery to webhooks, Slack channels and Tares agents, with every attempt logged and retried. - **Tares agents.** Prompt plus trigger; runs on your model provider, read-only by default, with external MCP servers opt-in per agent. Each run is metered. - **Findings and memory.** Conclusions become events on the timeline; `remember` writes observations back for the next read. - **Projects and skills.** One page per job with its activity as threads; skills give a project's agents shared instructions they load when a task matches. - **Console and Ask.** Projects, Sources, Triggers, Tares agents, Firings, Explore, and Ask, an assistant over your own data (⌘K). - **Slack.** Subscribe a channel to any trigger; ask back with `/tares ask`. ## Choose your path Install, connect one source, connect your agent. About five minutes. Say what a project should achieve; Tares plans the sources, wake-ups and agents, shows you the plan, and sets it up when it looks right. The result is an ordinary project. Start from a Tares template, or assemble a project from objects you already have. The hosted version: sign up, connect sources, same timeline and MCP endpoint. ## Developer tools The `tares` CLI starts and inspects an instance: ```bash uv tool install tares # or: pipx install tares tares up # daemon + console on http://127.0.0.1:8787 tares status # readiness checklist and the one next step ``` Your coding agent can do the whole setup for you. Paste this into Claude Code, Codex or Cursor: > Run `npx skills add glassflow/tares --skill tares` and use the tares skill to install Tares and connect it to this agent. Full reference: [CLI](/tares/cli), [HTTP API](/tares/guides/http-api). ## Popular projects An alert fires; the agent reads the service's whole timeline and writes the diagnosis before anyone opens a dashboard. Commits land; when a change matters to the team, the agent opens a pull request against the shared context repository. Failed jobs, sandbox runs, voice calls: each gets a timeline, a trigger on failure, and a finding that says what broke. ## Need something Tares doesn't do yet? Custom connectors, missing features, or questions about Tares Cloud: email [help@glassflow.ai](mailto:help@glassflow.ai) or [book a call](https://cal.com/ashishbagri/glassflow). We're building against real use cases and reply quickly. More ways to reach us on the [Help page](/tares/help). --- # Quickstart If you are a coding assistant, start with [AI resources](/tares/agents/ai-resources). In about five minutes: install Tares, get events from a real system flowing into one correlated timeline, and connect an agent that reads it. Using a coding agent? Paste this into Claude Code, Codex or Cursor and it does the whole page for you, then connects itself: > Run `npx skills add glassflow/tares --skill tares` and use the tares skill to install Tares and connect it to this agent. ### Start Tares ```bash uv tool install tares # or: pipx install tares tares up # daemon + console on http://localhost:8787 ``` The compose runs two containers from the same image: the daemon, and the MCP endpoint that agents connect to in the last step. ```yaml # docker-compose.yml name: tares services: taresd: image: ghcr.io/glassflow/tares:latest command: ["tares", "up", "--host", "0.0.0.0", "--data-dir", "/data"] ports: ["8787:8787"] volumes: [tares-data:/data] mcp: image: ghcr.io/glassflow/tares:latest command: ["tares", "mcp", "--transport", "streamable-http", "--host", "0.0.0.0", "--port", "8788", "--taresd", "http://taresd:8787"] ports: ["8788:8788"] depends_on: [taresd] volumes: tares-data: ``` ```bash docker compose up -d # daemon on :8787, MCP endpoint on :8788/mcp ``` (For a server with one hostname, TLS, and auth, see the [full compose](/tares/deployment#server-compose--tls).) The demo path in the next step assumes the local install: its logs source tails `docker logs` on your machine, which doesn't work from inside the Tares container. Running in Docker, pick **Your own source** instead. Open the console at [`http://localhost:8787`](http://localhost:8787) and add a source. ### Add a source The demo is a self-contained stack (a small api-server, Prometheus, and a traffic generator) plus a catalog that wires up three correlated sources, a trigger over them, and a built-in agent. Two files, no checkout. Start the stack Tares will ingest from: ```bash curl -O https://raw.githubusercontent.com/glassflow/tares/main/demo/docker-compose.yml docker compose up -d ``` Stop the daemon from the first step (Ctrl-C) and restart it seeded with the demo catalog: ```bash curl -O https://raw.githubusercontent.com/glassflow/tares/main/demo/catalog.demo.yaml TARES_CATALOG=catalog.demo.yaml tares up ``` The startup log confirms the import: `imported catalog.demo.yaml into catalog (3 sources, 1 triggers)`. Everything lands in the **Default** project. The catalog imports only while your catalog is still empty. That is fine here, since you haven't created anything yet. If you *have* (say, you tried the other tab first), the import is skipped silently; restart on a fresh data directory instead: `TARES_CATALOG=catalog.demo.yaml tares up --data-dir ~/tares-demo` Open **Explore**, pick the `api-server` entity, and watch metrics, logs, and alerts merge into one timeline. To break it on purpose and watch an agent diagnose it, continue with [Build an AI SRE](/tares/guides/ai-sre). (Prefer no catalog at all? **Sources → Discover** proposes sources from your running containers; the catalog just pre-wires the trigger and the agent.) In the console: **Sources → Add source → github**. Set: - `repo`: `glassflow/clickhouse-etl` (or any public repo) Save. Sources poll every 5 seconds by default, so commits appear within moments, keyed by `repo` with `author` as a label. The source page shows its **Fields** (per-field coverage) and recent events; **Explore** lets you browse the repos and authors and read their timelines. Every connector works the same way; each [connector page](/tares/connectors) also shows an agent prompt that does this step for you. ### Connect an agent Agents read Tares over [MCP](/tares/agents). Start the MCP endpoint, a second process that proxies to the daemon (skip this if you're on the Docker compose; it's already running on `:8788`): ```bash tares mcp --transport streamable-http --port 8788 --taresd http://localhost:8787 ``` Point Claude Code at it: ```bash claude mcp add --transport http tares http://localhost:8788/mcp claude mcp list # tares: connected ``` Locally there's no auth, so the connect command needs no token; on a [deployed instance](/tares/deployment) that sets `TARES_AUTH_TOKEN`, add `--header "Authorization: Bearer "`. In a Claude Code session: > Use tares: list my sources and summarize what each one contains. The agent calls the MCP tools (`list_sources`, `catalog_describe`, `read`, …) against the daemon. For other clients (Codex, Claude Desktop), transports, and the full tool list, see [Connecting agents](/tares/agents). ### Verify `tares status` prints a checklist and the one next step: ```text Tares 1.11.0 at http://127.0.0.1:8787 data dir ~/.tares (1.2 MB) Daemon: running (uptime 0h 5m) Auth: off (open local instance) Sources: 1 configured, 1 receiving (last event 4s ago) Projects: 1 (Default) Triggers: 0 enabled Tares agents: none MCP endpoint: running at http://127.0.0.1:8788/mcp Agent clients: Claude Code: connected Slack: not configured Next: add a second source keyed by the same label so reads correlate. Docs: docs.glassflow.ai/tares/connectors ``` In the console, **Reads** lists each read as it happens, with `client = mcp`. ## Next - [Build an AI SRE](/tares/guides/ai-sre): cause an incident and watch an agent diagnose it and write the finding back. - [Concepts](/tares/concepts): the data model. - [Connectors](/tares/connectors): Vercel, Postgres, Prometheus, OTLP, Claude Code sessions, and more. - [Deployment](/tares/deployment): self-host the daemon, MCP server, and TLS with Docker. --- # Concepts Everything in Tares hangs off one pipeline. **Sources** ingest **events** from your systems; the **labels** on each event say which **entity** it belongs to. A **read** returns one entity's events across sources, merged in time order. A **trigger** watches a set of sources and, when its condition trips, emits a **dispatch** that wakes agents; an agent can write a **finding** back onto the entity's timeline. A **project** is a goal plus its wiring: which trigger wakes which agent, over sources, triggers, agents, MCP servers and skills that any number of projects can share. ``` connector → source → event → labels → entity ├→ read (on demand; agents + console) └→ trigger → dispatch → agents woken (project wiring; webhook subscriptions) └→ finding (written back) project = a goal + its wiring (which trigger wakes which agent, who hands off to whom) over parts shared on the instance: sources, triggers, agents, MCP servers, skills ``` The rest of this page defines each term, starting with the project and then in the order the data flows. ## Projects A **project** is the unit you set up and look after: one job, such as "diagnose alerts on the checkout service" or "keep the shared code context current", with everything it needs on one page. Sources, triggers, agents, MCP servers and skills belong to the instance, and any number of projects can use the same one: two projects can watch the same logs, or share one agent, without copying anything. What a project holds is its goal and its **wiring**: which trigger wakes which agent in it, whether that agent is on there, and who hands off to whom. A run belongs to the project whose wiring started it. Every instance has a **Default** project. It holds whatever was made outside another project (an API call or MCP tool that leaves `project` out lands there) and any part no project uses any more. When another project takes in a part, the part leaves Default. The Default project is listed first and cannot be deleted. A project's page shows the [activity](/tares/projects#activity) of everything it uses. See [Projects](/tares/projects) for how to start one and what its page shows, and **All resources** in the console for every part on the instance with the projects that use it. ## Sources A **source** is a configured connector instance. It has a name, a connector type, and a config object. Each source produces a single stream of events. Sources have one of three modes: - **Poll**: `taresd` fetches from the upstream on an interval (`poll`, e.g. `5s`, `1m`). Used by GitHub, Prometheus, Postgres, Docker logs. - **Push**: producers send events to `taresd` over HTTP. Used by Vercel, OTLP, Alertmanager, and webhooks. A push source has a generated `ingest_key`; producers POST to `/ingest/` (OTLP uses `/v1/{logs,traces,metrics}`). - **Reference**: declarative context, not a stream. The config *is* the data; it's re-materialized on edit and [always surfaced](#the-reference-source-type) regardless of the read window. Used by [`reference`](/tares/connectors/reference). Sources are added, edited, paused, and removed at runtime; no restart is required. A new source joins the project it is created in (the Default project when none is named) and can be added to more projects later. A project that takes in a trigger takes in the sources it reads too. ## Events Every event is stored with the same fields: | field | type | description | |---|---|---| | `source` | string | the source that produced the event | | `event_time` | timestamp | when the event occurred (source time if available, else ingest time) | | `event_type` | string | a coarse type, e.g. `commit`, `5xx_rate`, `error` | | `text` | string | the rendered line an agent reads | | `fields` | object | typed values extracted for filtering and triggers, e.g. `{ "status": 500 }` | | `labels` | object | named correlation axes, e.g. `{ "service": "checkout" }` | | `payload` | object | the original event, unmodified (lossless) | | `key_value` | string | the value of the primary label (the key) | ## Labels, keys, and entities A **label** is a named axis carried by an event. It is declared on the source as one of: - `const`: a fixed value applied to every event from the source, or - `field`: read per-event from a field in the connector's normalized event. Example label declarations on a source: ```yaml labels: - { name: service, field: service, primary: true } - { name: env, const: prod } ``` The label marked `primary: true` is the **key**: `key_value` is set from it. If no label is marked primary, the connector's default key is used. An **entity** is a `(label, value)` pair, e.g. `(service, checkout)` or `(repo, acme/api)`. The console's **Explore** page lets you pick any entity and read its correlated timeline; it lists each label's distinct values with event counts. Because labels are indexed, selecting events by `{ service: "checkout" }` is a lookup, not a text scan. A source's **Fields** tab (console, or `GET /api/sources//fields`) reports each label/field's coverage (how many sampled events actually carry it) and its top values. Use it to choose a key that is reliably present. ## Reading The core read is **`read(selector, window)`**: a correlated, time-ordered timeline of every event matching a `{ label: value }` selector, in one response. The selector is a strict-AND conjunction, so `{ service: "checkout" }` returns that service's logs, metrics, and deploys merged on one clock, and adding a label narrows it. Each row carries the labels it matched on, so a read is self-describing. A read covers every source by default. Name a `project` to read only that project's sources (and the findings recorded in that project), or `sources` to read only the ones you list (both together: the named ones within the project). Explore offers the same choice as a project picker. A [Tares agent](/tares/tares-agents) reads the sources of the projects its run is for unless it names others. ![Explore's agent payload: exactly what one read returns to an agent](/assets/tares-explore-agent-view.png) ### The reference source type Most sources are time-series: a read applies the `window`, so old events age out. A [`reference`](/tares/connectors/reference) source is different: it holds declarative context (documents attached to an entity by their labels), and its events are **always included** in an entity read, **regardless of the window**. A runbook or schema attached to `service=checkout` surfaces on every read of that entity, not just recent ones, so an agent correlating on an entity always has its reference material to hand. ## Triggers and subscriptions A **trigger** watches a set of sources and evaluates a condition as events arrive. It is defined by: - `sources`: the sources it watches (at least one), - `filters`: optional `[{ field, op, value }]` that narrow which events count (ops: `eq`, `neq`, `contains`, `gt`, `lt`, `gte`, `lte`), - `key_field`: optional, the label that identifies the entity across those sources (default: the primary label of the first source), - `condition`: an aggregate of a field, grouped by entity, compared to a threshold over a window, for example `max(rate_5xx) > 1.0` per entity over `1m`. A schedule trigger fires every interval instead (`condition: {every: 10m}`). When the condition holds, the trigger emits a **dispatch**: one firing for one entity, carrying the entity's timeline across the trigger's sources. Every dispatch is logged, even when nothing is woken; firings and delivery status are on the trigger's page and in the project's [Activity](/tares/projects#activity). Two kinds of agent are woken by a dispatch: - A **[Tares agent](/tares/tares-agents)** (a prompt configured in Tares that runs in-process) is woken through a project's **wiring**: each project that uses the agent says which trigger wakes it there and whether it is on. An agent can use any MCP server on the instance, and can have no trigger at all, so that only a [handoff](/tares/tares-agents/handoffs) from another agent starts it. - An **external agent** **subscribes**: a webhook URL that gets POSTed the timeline (see the [delivery contract](/tares/guides/triggers#receive-dispatches)). An outside agent can also [join a whole project](/tares/projects#join-be-woken-by-the-projects-triggers). See [Watch with triggers](/tares/guides/triggers) for the full shape. ## Findings A **finding** is a conclusion written back onto an entity's timeline. When a [Tares agent](/tares/tares-agents) runs on a dispatch, it reads the correlated timeline and writes its diagnosis as an event in a findings source (auto-provisioned on first use), labeled with the same axis as the evidence. Because it is a labeled event like any other, every later read of that entity includes it: the next agent (or human) to look starts from the previous conclusion instead of from scratch. External agents write back the same way with the [`remember`](/tares/agents#tools) tool, which stores observations in the agent-memory source. ## Runs and lineage Each time a Tares agent runs, Tares records a **run**: its status, rounds, cost, finding, and what woke it (`woken_by`: `trigger`, `schedule`, `manual`, `rerun`, `bootstrap`, `handoff` or `practice`, the last for [Run it once now](/tares/build#try-it); a finding an [outside agent](/tares/projects#outside-agents) records is kept as a run with `woken_by: external`). A rerun points at the run it repeats, a [handed-off](/tares/tares-agents/handoffs) run at the run that handed off, and a firing tripped by a finding at the run that wrote it. This lineage lets the project's [Activity](/tares/projects#activity) show an alert, the finding it led to and the next agent's root cause as one thread. ## Skills A **skill** is a named set of instructions, such as a runbook or a house style. Skills live on the instance, and projects use them: an agent sees the name and description of each skill of the projects its run is for, and loads the full text with the `skill` tool when a task matches. See [Skills](/tares/tares-agents/skills). ## The catalog The **catalog** is the set of configured sources, triggers, agents, MCP servers, projects and skills. It is stored in the embedded database and is also expressible as YAML: `GET /api/catalog/export` returns it, and importing YAML (or seeding from a file on first boot) recreates it. Each trigger, agent and MCP server names the `project` that made it, and each source the `projects` it is in, by name, so a file imports into another instance. A `wiring:` section holds each project's wiring: which trigger wakes which agent there, on or off, and its handoffs. The MCP `catalog_describe` tool (and, in the console, a source's detail page) reports any object's schema (event types and inferred typed fields), the entities it carries, freshness, lineage, and sample events. See [Connectors](/tares/connectors) for what can be ingested, and [Connecting agents](/tares/agents) for the read/watch surface. ### Deleting Objects depend on each other downward: a trigger on its sources, a Tares agent on its trigger. Deleting a source shows the triggers and agents that need it and offers to delete those too, in order (agents, then triggers); say no and the delete is refused, naming what would break. Deleting a trigger leaves the agents it woke in place, without a trigger of their own. Deleting a part removes it from every project that used it. Deleting a project deletes the triggers, agents, MCP servers and skills it made, keeps any part another project uses, and lets you pick which of its sources go too (see [Deleting a project](/tares/projects#deleting-a-project)). On the API: `GET /api/catalog/dependents?kind=source&name=` lists the dependents, and `cascade=true` on `DELETE /api/sources/{name}` takes them along. --- # Projects A **project** is what you set up and look after in Tares: one job, with everything it needs on one page. It uses: - **sources**: the data its triggers read, - **triggers**: what should fire, and on which sources, - **agents**: the Tares agents those triggers wake, and the agents they hand off to, - **MCP servers**: the external tools those agents may use, - **skills**: the [instructions its agents load](/tares/tares-agents/skills) when a task calls for them. These parts belong to the instance, not to one project. Any number of projects can use the same source, trigger, agent, MCP server or skill: the same GitHub MCP server in two projects, or one agent serving two goals. What a project owns is its **goal** and its **wiring**: - which trigger wakes which agent in this project, and whether that agent is on here, - which agent takes over when another concludes with a verdict (its [handoffs](/tares/tares-agents/handoffs)). So one agent can be woken by trigger A in one project and by trigger B in another, on in the first and off in the second, with different handoffs in each. A run belongs to the project whose wiring started it: each project's results, Activity, today's totals and spend count its own runs only. When two projects wire the same trigger to the same agent, it runs once and shows in both. Every part is also an ordinary Tares object on its own page; the project page brings together the ones it uses. The project that created a part is recorded as its maker (the **part of project** badge), which never stops another project from using it. **All resources** in the sidebar lists every part on the instance, one table per kind, with the projects that use each (`GET /api/resources`). Use it to see what is shared, or what no project uses any more. ## The Default project Every instance has a **Default** project. It holds whatever was made outside another project: a source, trigger, agent or MCP server created on the API or over MCP with no `project` lands there, and so does a part that no project uses any more. When another project takes in a part from the Default project, the part leaves Default, and Default's wiring of it comes along, so what ran there keeps running in the project it joined. The Default project is listed first under **Projects** and has a page like any other project, without **Edit** or **Delete**: it cannot be deleted. In the console, a trigger or agent is added from a project's Advanced setup (**+** next to **Triggers** or **Agents**), so it goes into that project. ## Starting a project A project starts in one of three ways, all from **Projects → Create new**: - **Guided setup.** Say what the project should achieve; Tares plans the sources, wake-ups and agents, reusing what is already on the instance, and shows the plan before anything runs. See [Guided setup](/tares/build). - **From a Tares template.** A template is a ready-made setup: pick one, answer a few questions, click **Start**, and Tares creates the objects behind it. - **From existing objects.** Assemble a project by hand from sources, triggers, agents and MCP servers you already have. Nothing is created; the project uses them. A guided setup you leave part way is kept as a **draft**: it shows on the **Projects** list with **Finish setting up**, which reopens it where it stopped, and **Delete draft**, which removes it. Nothing of a draft is set up yet, so deleting it touches no part. The **Projects** entry sits at the top of the console sidebar because it is the quickest way from an empty instance to something running. ## Tares templates | Template | What it does | Guide | |---|---|---| | **AI SRE demo** (tagged demo) | Watches the bundled demo stack: three sources keyed by `service` (Prometheus metrics, the api-server's logs, the alerts Prometheus fires), a trigger over all three that wakes an agent when an alert fires, and an agent that writes the first incident note back onto the timeline. The page has **Cause an incident** and **Clear the fault** buttons. | [Build an AI SRE](/tares/guides/ai-sre) | | **Shared code context** | Watches commits across your code repositories and keeps one shared context repository current: an agent reads each change and updates the pages that cover it, opening a pull request. | [Keep shared code context current](/tares/guides/shared-code-context) | | **Challenger workflow** | Codex on your laptop challenges Claude Code's plan and every commit in a marked session; Tares keeps the exchange on one timeline per session, writes the session summary when it ends and proposes what to remember for the next session in that repo. Created by itself the first time a session is marked with `/tares:challenger`. | [Challenge Claude Code with a second model](/tares/guides/challenger-workflow) | A template marked **demo** needs the demo stack rather than your own systems; its setup page shows what to run first, with copy buttons, and detects what is already running. ## Starting from a template Open **Projects → Create new**. That page asks for the goal of a guided setup; the template gallery is behind **Start from a template** on it (`/projects/new/templates`). Pick a template card, click **Set up**. The setup page asks only for what it cannot work out itself: the AI SRE demo looks at Docker and fills in the Prometheus and api-server URLs from the running containers; the shared code context wizard lists the repositories your GitHub token can see. The last step shows exactly what Start creates, with the names of the objects. Some setup steps check themselves (a [model provider](/tares/model-providers) that is already set shows as done). A template only takes over parts it plans that are still in the Default project, or new ones. If a part with a planned name was made by another project, the template stops and names that project, because a template reconfigures what it plans. ## Assembling from existing objects Next to the templates, **From existing objects** builds a project without creating anything: name it, pick the objects it is made of, click **Start**. - **Any part can be picked**, whichever project uses it already. Parts in other projects stay there and are shared; parts that were only in the Default project leave it. - The picker shows each source with what it watches (its repository, for example) and finds it by that too. - What an object needs comes along: an agent brings its trigger and MCP servers, a trigger brings its agents and its sources. - An agent that another project made joins with its trigger but off, and without that project's handoffs: turn it on, and add handoffs, in this project. A project assembled this way can also start empty and fill up as you add objects on its page. - **Edit** changes the list. Removing a part takes it, and this project's wiring of it, out of this project only. Nothing is deleted; a part no project uses any more goes to the Default project. - **Delete** removes the project with its triggers, agents and MCP servers (see [Deleting a project](#deleting-a-project)). - There is no plan behind a hand-assembled project, so **Repair** and **customized** do not apply: edit the objects on their own pages, the project shows them as they are. ## The project page Opening a project shows its **Overview**: what the project is for and what its agents found. The parts that make it work (sources, triggers, runs, raw events) sit one click away in [Advanced setup](#advanced-setup), for when something does not work as expected. ### Overview - **The goal**: one line saying what the project should achieve. A project made from a template starts with the template's goal; click it to change it. A project without one asks for it ("What should this project achieve?"). - **One sentence of how it works**, built from the setup, for example "When checkout-errors gets more than 5 events in 5 minutes for one service, checkout-triage looks first. If it concludes investigate, checkout-rca digs in." - **A health line**: **Working** (what is receiving and how many agents are ready), **Needs attention** (the most important issue first, with a button that opens the thing to fix, such as a source whose token was rejected), **Paused**, or **Setting up** (nothing has arrived yet). - **Today's totals**: how many things the agents looked at, how many need action, and what the project spent (days start at midnight UTC). - **What the agents found**: one card per conclusion, newest first, with **Load older** to page back. A card shows the headline, a short summary and the next step, marked **Needs action** or **No action**. When one agent [hands off](/tares/tares-agents/handoffs) to another, the card is the last agent's conclusion, not each step. Findings recorded by [outside agents](#outside-agents) show here too. At the top right are **Setup**, **Pause** (or **Resume**) and the template's actions (the AI SRE demo's **Cause an incident** and **Clear the fault**). Click a card to open the result: the next step first, then the full note, then **How Tares got here** (what arrived, which agent looked, what it concluded and which skills it used, in plain sentences), with the time and cost. **Mark as handled** records that someone dealt with it, and clears again with **Mark as not handled**. **See the raw events and runs** opens the same thread in Advanced setup's [Activity](#activity). ### Setup **Setup** shows the project as four steps, each item with its state and a **Change** link to its page in Advanced setup: 1. **Watches**: the sources, each receiving, silent, waiting for its first event, paused or in error. 2. **Wakes when**: each trigger's condition in plain words, and how long it waits before waking again for the same entity. 3. **Agents**: which agent looks first and which digs in after a handoff. 4. **Know-how**: the project's [skills](/tares/tares-agents/skills) and which agents loaded them. A template's panels (the context repository, the demo stack) are shown here too, with **Edit** and **Delete** for the project. **Advanced setup** at the top right leads to everything else. ### Advanced setup Advanced setup has its own navigation on the left, with **Back to the project** at the top. The header has **Pause** (or **Resume**), **Edit** and **Delete**, and cards for the counts that matter (runs, trigger last fired, created, plus whatever the template adds). The navigation: - **Activity**: everything that happened in the project, one thread per incident, with the firings, runs and raw findings (see [Activity](#activity)). - **Events**: the latest events from the project's sources. - **Sessions**: shown when the template reports sessions (the challenger workflow). - **Sources**, **Triggers**, **Agents** and **Skills**: one section each, listing the project's objects by name, with a **+** to add one. - **Settings**: **MCP servers**, **Subscribers** (the webhooks and Slack channels its triggers deliver to), **Keys** ([project keys](#project-keys) for agents outside Tares) and **Change history**. Click a section name for an overview table of everything in it. Click one object to see just that object: - a **source**: its status, labels, what in the project reads it, and its recent events. Adding one offers **Add existing source**, which takes a source from elsewhere into the project, and **Connect a new source**, which creates one in it. **Remove from project** takes a source out without deleting it. - a **trigger**: its settings, what it wakes, and its recent firings. - an **agent**: its settings, its [handoffs](/tares/tares-agents/handoffs) in both directions (whom it hands off to, who hands off to it), and its runs. The **Agents** section also lists the [outside agents](#join-be-woken-by-the-projects-triggers) that joined the project, marked external. - a **skill**: its body, and which agents loaded it. See [Skills](/tares/tares-agents/skills). Links made for the old tabbed page (`?tab=...`) and links to a setup view (`?view=activity` and the others) still open Advanced setup. **Pause** turns this project's wiring off: its agents stop running here. A trigger stops only when no other running project uses it, so pausing one project leaves the others alone. Sources keep ingesting unless you tick "also pause its sources", in which case Resume brings back exactly what Pause stopped. **Edit** reopens the setup with your values; on save the project re-plans and applies only what changed. #### Activity **Activity** lists what happened in the project, newest first, one row per **thread**. A thread starts with a firing (a trigger fired, and the runs it woke) or with a run that no firing woke (started by hand, or the first look when a project starts). Each row shows the time, what fired or who ran, the entity, and each agent that ran with how it ended. Open a row to see, in place: - the firing: its trigger, an excerpt of the payload it carried, and where it was delivered (Tares agents, Slack channels, webhooks), with a link to the full firing, - each run: its finding, what it produced, the skills it loaded, and a link to the run, - what each run led to: a rerun sits under the run it repeats, a [handed-off](/tares/tares-agents/handoffs) run sits under the run that handed off, and a firing that a run's finding tripped sits under that run, with the runs it woke in turn. A handoff skipped for its cooldown shows as a note on the run that would have handed off. So a watcher's alert, the finding it wrote and the root-cause run that finding started read as one thread, however many agents it took. Filter by trigger, agent, outcome (found something, nothing to report, failed, stopped by a cap, and so on) or entity, and use **Load older** to page back. A finding an agent outside Tares recorded is a thread of its own, marked as recorded from outside Tares. Runs and firings from before this view existed show under the project of their agent or trigger; what woke them shows as unknown. ## Outside agents An agent that runs outside Tares (Claude Code, Codex, your own service) can work inside one project next to its Tares agents: be woken by the project's triggers, read its sources, follow its skills, and record findings that land on the same timelines. It does this with a project key. The guide [Connect an outside agent to a project](/tares/guides/outside-agent) walks through it with Claude Code. ### Project keys A **project key** reads one project and records findings in it, and nothing else. Make one on the project page under **Settings → Keys**: name it after who holds it (the findings it records carry that name), and copy the secret, which is shown once. **Revoke** there cuts the agent off. With a project key: - **Reads cover the project only.** `POST /read` and stats read the project's sources, plus the findings recorded in this project. `GET /api/projects` and `/catalog` show this project only. - **The project's skills, timeline, findings, results, outline and health are readable**; another project's are not. - **It records findings** in the project, and **manages its own subscriptions** to it. - **Everything else answers 403** `this key only reads project and records findings in it`. Project keys are checked on a secured instance (one with `TARES_AUTH_TOKEN`, see [Deployment](/tares/deployment#project-keys)). On an open instance nothing is checked, so there are no keys to hand out; the MCP tools then take the project by name. ### Join: be woken by the project's triggers `POST /api/projects/{id}/subscribe {"url": "https://my-agent.example.com/hook"}`, or the MCP tool `join_project(url)`, sends every firing of every trigger in the project to that URL, including triggers added later. The body is the usual [firing body](/tares/guides/triggers#receive-dispatches): `dispatch_id`, `trigger`, `project`, `kind`, `key` (the entity), `fired_at`, `payload` (the timeline), and `run_ids`, the Tares agent runs the same firing started. Subscribing the same URL again with the same key returns the subscription it already has. `DELETE /api/projects/{id}/subscribe/{subscription_id}` leaves; a project key removes only its own. The project's **Agents** section lists the outside agents that joined, marked external. Click one to see where it delivers (the URL masked), the key that made it, and the last delivery. **Revoke** there stops the deliveries; the key keeps working until you revoke it under **Settings → Keys**. ### Record a finding `POST /api/projects/{id}/findings` records what an outside agent concluded: ```json { "entity": "checkout", "finding": "Errors began after deploy 9f2c81d ...", "verdict": "rca", "label": "service" } ``` - `entity` is what the finding is about, `finding` is markdown (up to 64 KB). - `verdict` is optional, one lowercase word such as `rca` or `resolved`. - `label` is the label the entity is a value of; left out, it is the entity label of the project's first trigger. - `headline` (one line, up to 100 characters) and `next_step` (up to 300 characters, left out when nothing needs doing) are optional; they head the finding's card on the Overview. Left out, both are taken from the note. The finding is stored like a Tares agent's: it lands on the entity's timeline, every later read of the entity includes it, and a trigger over the `findings` source can fire on it. It carries the key's name as its agent, shows as a card under **What the agents found** on the Overview, and in Advanced setup's **Activity** it is a thread marked as recorded from outside Tares. A key named like one of the instance's Tares agents cannot record findings (409); give it another name. `GET /api/projects/{id}/findings?entity=&agent=&limit=` lists the project's findings, newest first, the Tares agents' and the outside agents' together; each carries `external: true` or `false`. `POST /api/projects/{id}/stats {"by": "service", "window": "30m"}` counts events per value of a label over the project's sources, this window against the one before, with optional `where`, `top` and `sources`. ## Deleting a project **Delete** removes the project and the triggers, agents and MCP servers it made, revokes its keys and ends the subscriptions of the agents that joined it. A part it made that another project uses is kept, and that project becomes its maker (listed as `kept_shared`); a part it only used is not touched. Its skills go unless another project uses them. Sources are shared, so the dialog lists the project's sources with a checkbox each, none ticked: - A ticked source is deleted too, unless another project uses it; then it is kept and listed as kept. - An unticked source stays connected. If no other project uses it, it moves to the Default project. - Events already stored stay unless you tick "also purge the events of the sources deleted and its triggers' firings". The Default project has no Delete button. Deleting a source on its own page lists the triggers and agents that depend on it and offers to delete them as well; without that the delete is refused, naming what would break. Deleting any part on its own page takes it off every project's list: deleting it was the choice, so no project shows it as missing. The agents a deleted trigger woke stay, with no trigger of their own: a handoff still starts them, and you can give them another trigger. A deleted MCP server drops off the agents that listed it. ## Makers and templates A part carries a **part of project** badge on its own page naming the project that made it, and is fully ordinary there. The maker never locks it: any project can use it. For a project started from a template: - **Edit** a part by hand and it is marked **customized**; the project keeps your version on its next re-plan instead of overwriting it. **Repair** resets a customized part back to the plan. - A part that already existed with the same name in the Default project is **adopted**, not duplicated (this is how the AI SRE demo picks up a demo catalog you imported earlier). One that another project made stops the template, naming that project. Setting a trigger's `project` (`PUT /api/triggers/{name}` with `project`) adds it, with its sources, to that project; it stays in the projects that already use it, and leaves only the Default project. ## Upgrading from views Earlier versions had **views**: saved sets of sources that triggers watched. Views are gone; a trigger now names its own `sources`, `filters` and `key_field`. The first start after upgrading does the move for you: - Each trigger takes the sources, filters and key field of the view it used. A trigger whose view was already deleted is paused with no sources, so it shows up to be fixed or deleted. - Everything is placed in a project. A trigger that was in no project goes to the Default project, an agent follows its trigger, an MCP server goes to the project whose agents use it (else the Default project), and a source in no project joins the Default project. Objects a template or custom project already held stay there. - Schedule triggers keep their last tick, so none fires early. The pass runs at every start and changes nothing the second time. A catalog file exported while views existed still imports: each trigger that names a view gets that view's sources, filters and key field. `/api/views`, `POST /query` and `POST /derive` now answer 404; read with [`POST /read`](/tares/guides/http-api#read-one-correlated-timeline) instead. ## In the catalog A project can be declared in catalog YAML, so a seed catalog can ship one and `tares up` creates it on first boot: ```yaml projects: - template: ai_sre_demo name: AI SRE demo params: prometheus_url: http://localhost:9090 api_server_url: http://localhost:8080 container: tares-demo-api-server - template: custom name: checkout watch objects: - { kind: source, name: checkout_logs } - { kind: trigger, name: checkout_errors } - { kind: agent, name: incident-first-look } ``` Import creates the project by name or updates an existing one; export includes the section with the parameters (never credential values). Triggers, agents and MCP servers name their `project` (the one that made them), and sources the `projects` they are in, by name. Each project's wiring exports under a top-level `wiring:` section, its wake-ups as `{project, wake, agent, enabled}` and its handoffs as `{project, agent, verdict, to, cooldown}`, and import restores it. A project's `goal` is exported and imported with it. The Default project is listed under `projects:` only when it has a goal, and then only its goal is imported; objects that name it go to the importing instance's own Default project, and so do objects that name no project. The project's skills export under a top-level `skills:` section (see [Skills](/tares/tares-agents/skills#in-the-catalog)). The old form (`usecases:` with `recipe:`) is still read until two releases after 1.14. ## The API Everything the console does is on the management API. `{id}` is the project id (`uc_...`) from `GET /api/projects`. | Call | Does | |---|---| | `GET /api/projects/templates` | the available templates with their parameters, tags, setup steps, actions and starter sentence | | `GET /api/projects/templates/{key}` | one template, hidden ones included | | `POST /api/projects/templates/{key}/detect` | what the template can work out from the environment (the AI SRE demo asks Docker what is running) | | `POST /api/projects` `{template, name?, params, goal?}` | create from a template; all or nothing. `goal` is one line of up to 200 characters; left out, the template's goal | | `POST /api/projects` `{template: "custom", name, objects}` | assemble from existing objects; `objects` is `[{kind, name}, ...]`, kinds `source`, `trigger`, `agent`, `mcp_server`. Any part on the instance can be named | | `GET /api/projects` and `GET /api/projects/{id}` | list (the Default project first, with `default: true`; drafts with `status: "draft"`), or one project with its objects. An object is `missing` only when it no longer exists | | `GET /api/resources` | every part on the instance (`sources`, `triggers`, `agents`, `tools`, `skills`, `keys`), each with what it is, its state and `used_by`, the projects that use it | | `PUT /api/projects/{id}` `{params, name?, goal?}` (or `{objects}` for a custom project) | re-plan and apply the difference. A body with only `goal` sets it (an empty string clears it) and changes nothing else; this works on the Default project too | | `POST /api/projects/{id}/sources` `{name}` | add an existing source to the project | | `DELETE /api/projects/{id}/sources/{name}` | take a source out of the project; refused while one of the project's triggers reads it | | `POST /api/projects/{id}/pause` and `/resume` | triggers and agents off or on; `{"sources": true}` on pause also pauses its sources | | `POST /api/projects/{id}/repair` `{key}` | re-create or reset one planned object (template projects only) | | `POST /api/projects/{id}/actions/{name}` | run one of the project's actions (`inject` with `{scenario}` and `clear` on the demo; `summarize` with `{session}` on the challenger workflow) | | `GET /api/projects/{id}/summary` | the project plus what its page shows (runs, sources, last fired) | | `GET /api/projects/{id}/timeline` | the Activity threads; see [below](#the-timeline-api) | | `GET /api/projects/{id}/outline` | how the project works in plain sentences: `sentence`, and `watches`, `wakes`, `agents`, `skills` with each item's state | | `GET /api/projects/{id}/health` | `state` (`working`, `attention`, `paused`, `setting_up`), a `message`, and `issues`, most important first, each with a `severity`, `message` and a suggested `fix` | | `GET /api/projects/{id}/results?limit=&before=` | what the agents found, newest first; see [below](#the-results-api) | | `GET /api/projects/{id}/results/{run_id}` | one result with its full `note` and the `steps` that led to it | | `POST /api/projects/{id}/results/{run_id}/handled` `{"handled": true}` | mark a result handled, or `false` to clear the mark | | `GET`, `POST`, `PUT`, `DELETE /api/projects/{id}/skills...` | the project's skills; see [Skills](/tares/tares-agents/skills#on-the-api) | | `GET /api/projects/{id}/keys` and `POST /api/projects/{id}/keys` `{name}` | the project's keys (no secrets), or make one; the secret is in the response only. See [Project keys](#project-keys) | | `POST /api/projects/{id}/subscribe` `{url}` and `DELETE /api/projects/{id}/subscribe/{sid}` | join the project with a webhook, or leave | | `GET /api/projects/{id}/external-agents` | the agents that joined: masked URL, key, last delivery | | `GET /api/projects/{id}/findings` and `POST /api/projects/{id}/findings` | list the project's findings, or record one from outside | | `POST /api/projects/{id}/stats` `{by, window?, where?, top?, sources?}` | counts per label value over the project's sources, returned as `{stats: text}` | | `DELETE /api/projects/{id}?delete_sources=a,b&purge_events=true` | delete the project with the triggers, agents and MCP servers it made (those another project uses are kept, listed under `kept_shared`) and the skills no other project uses. `delete_sources` names the sources to delete too (each one kept, and listed under `kept`, when another project uses it); `all` names every source of the project. Left out (or `none`), every source is kept. `purge_events` purges the deleted sources' events and the deleted triggers' firings. A draft is deleted the same way | | `GET /api/catalog/dependents?kind=source&name=...` | what stops working if that source goes, in delete order; `DELETE /api/sources/{name}?cascade=true` takes it along | Creating an object in a project: `POST /api/sources`, `/api/triggers`, `/api/agents/builtin` and `/api/mcp-servers` take `project` (an id or a name; the Default project when left out). The list endpoints report it: `project` on a trigger, agent and MCP server (the project that made it), and `projects` (every project it is in). An agent may use any trigger and MCP server on the instance. The agent routes take `?project=` for one project's view of an agent: `GET /api/agents/builtin` returns each agent's trigger, handoffs, on or off and run counts as that project wires them, and `POST /api/agents/builtin/{name}/enable` (or `/disable`) and `GET .../runs` act on that project only. `PUT /api/agents/builtin/{name}` with a `project` other than the agent's maker changes that project's wiring, not the agent's own trigger and handoffs. The routes behind guided setup and drafts are on [Guided setup](/tares/build#on-the-api). The pre-1.14 routes (`/api/usecases*`, with their old response shape) keep working until two releases after 1.14. ### The results API `GET /api/projects/{id}/results` returns one result per chain of runs: when one agent hands off to another, the result is the last agent's conclusion. A run that concluded with nothing to report is listed only when it wrote a note. ```json { "results": [ { "id": "run_4be1c0d2a9f3", "thread": "9f2c81d4…", "at": "2026-09-29T09:14:40+00:00", "entity": "checkout", "kind": "action", "headline": "Checkout returns 502 since the payments deploy", "summary": "Errors began two minutes after deploy 9f2c81d of payments-api…", "next_step": "Roll back payments-api to the previous release.", "verdict": "rca", "chain": ["checkout-triage", "checkout-rca"], "cost_usd": 0.04, "duration_ms": 24000, "handled": null, "external": false } ], "next_before": "2026-09-28T17:02:11+00:00", "today": { "looked_at": 12, "found": 1, "spent_usd": 0.31 } } ``` - `kind` is `no_action` when there is no next step, or the verdict is one such as `ok`, `resolved` or `noise`; otherwise `action`. - `headline` and `next_step` come from the agent's [`conclude`](/tares/tares-agents/tools) call. For a run without them, Tares takes them from the note: its heading, bold lead or first sentence, and the text after "Next step:", "Next:" or "Recommendation:". - `today` counts since midnight UTC: threads started, results that need action, and what the project's runs cost. - `handled` is `{at, by}` once someone marked the result handled. - Page with `before` set to the previous page's `next_before`. ### The timeline API `GET /api/projects/{id}/timeline` returns the Activity threads, newest first: | Parameter | Does | |---|---| | `limit` | threads per page, default 50, at most 200 | | `before` | an ISO timestamp; pass the previous page's `next_before` to get the next page | | `trigger`, `agent`, `entity` | keep threads where that trigger fired, that agent ran, or that entity appears, anywhere in the thread | | `outcome` | keep threads with a run that ended this way: `finding`, `no_op`, `failed`, `capped`, `empty`, `exhausted`, `running`, or `none` for a firing that woke no agent | ```json { "threads": [ { "id": "9f2c81d4…", "kind": "firing", "at": "2026-09-29T09:14:03+00:00", "trigger": "incident", "entity": "api-server", "fired": { "dispatch_id": "9f2c81d4…", "trigger": "incident", "kind": "condition", "key": "api-server", "fired_at": "2026-09-29T09:14:03+00:00", "payload_excerpt": "…the first 600 characters of what the firing carried…", "subscribers": 1 }, "deliveries": [ { "kind": "tares", "target": "incident-first-look", "ok": true, "error": null, "at": "2026-09-29T09:14:40+00:00" } ], "runs": [ { "id": "run_4be1…", "agent": "incident-first-look", "status": "ok", "outcome": "finding", "woken_by": "trigger", "skills": ["checkout-triage"], "finding": "…", "children": [], "firings": [] } ] } ], "next_before": "2026-09-29T08:02:11+00:00" } ``` A thread's `kind` is `firing` or `run` (a run no firing woke; `fired` is then absent). A finding recorded from outside Tares is a `run` thread whose run has `external: true` and `woken_by: external`. A run carries the fields of the agent's runs list (status, outcome, verdict, entity key, model, rounds, tool calls, cost, duration, finding cut to 4,000 characters, results, skills, `woken_by`), plus `children` (its reruns and the runs it handed off to) and `firings` (firings its finding tripped, each shaped like a thread). `next_before` is `null` on the last page. Want a template that is not here yet? A template is a small Python class (parameters, the objects it plans, an optional summary and actions). Tell us what you would set up next: [help@glassflow.ai](mailto:help@glassflow.ai). --- # Guided setup Say what a project should achieve, the way you would to a colleague. Tares writes a plan for it: what to watch, when to wake, who does the work and what they may use. You see the whole plan in plain words, change any part of it, and nothing runs until you click **Looks right, set it up**. What you end up with is an ordinary [project](/tares/projects): every part is on its own page and stays editable. ## Where it is **Projects → Create new.** The first step also links to **Start from a template** (the [template gallery](/tares/projects#tares-templates)) and to **build it by hand from existing objects**, for when you would rather pick the parts yourself. ## The steps The setup has four steps, shown at the top of the page: **Goal**, **Plan**, **Connect** and **Try it**. ### Goal Answer **What should this project achieve?** in a sentence, or click one of the examples under **Or start from one of these**. Then pick **Who does the work?**: - **Tares agents**: agents that run inside Tares on your model provider. Nothing to host. - **Your own agent**: Claude Code or a service of yours joins with a [project key](/tares/projects#project-keys) and is woken with what happened. Click **Plan it**. ### Plan Tares writes the plan in the background and shows what it is doing as it goes: reading what is already on your Tares, looking at what a source sends, writing the plan, checking it and fixing what the check found, with the seconds the current step has taken. It usually takes under a minute. The project exists from this moment as a **draft**. You can leave the page while it plans or while you edit the plan: the draft waits on the Projects list with **Finish setting up**, which opens it where you left it. **Delete draft**, on that row or at the foot of the setup page, removes it. Nothing of a draft is set up yet, so nothing else goes with it. The plan then shows as four cards, each item with **Change** and **Remove**: 1. **Watches**: the sources the project reads. A source already on your Tares is reused as it is. Adding or changing a source starts with the kind of source; Tares then lists your sources of that kind to pick from, or **Connect a new** one of that kind. 2. **Wakes when**: when the agents are woken, in a sentence with the numbers you can change in place, and how long to wait before waking again. 3. **Agents**: who looks first and who digs in after a [handoff](/tares/tares-agents/handoffs). **Add an agent** can **Use one already on Tares** (pick it from the list, then **Use it**) or start from a template of agent instructions. An agent that posts to Slack gets a channel picker with the channels the Tares bot is in. With **Your own agent**, this card is your agent instead. 4. **Know-how**: optional [skills](/tares/tares-agents/skills), the notes the agents follow. **Add a skill**, **Upload SKILL.md**, or **Use one already on Tares**. Under the cards, **Tools the agents can use** lists the MCP servers in the plan. A tool already on your Tares is on, since someone set it up already; a new one stays off until you turn it on. **Attach one already on Tares** or **Add a new one** adds more. Parts are shared between projects, so the plan reuses what you already have: an existing source, agent, tool or skill is used as it is and stays in the projects that already use it. To change the plan in words, type in **Say what to change** (for example "only for payments-api") and click **Update the plan**; Tares plans again from your edited plan, shown as it happens. **Show what Tares sets up for you** lists every part the plan creates or uses. When it reads right, click **Looks right, set it up**: Tares creates the project and everything it needs in one go. ### Connect The one step only you can do. Tares lists what it cannot connect by itself, for example the endpoint your system sends events to (with an example event and **Send a test event for me**), a credential a new source needs, a new tool's address, or your own agent's key (shown once). Each item shows whether it is connected yet. **Continue** moves on; **I will connect it later** leaves it for the project page. When there is nothing to connect, the page says so. ### Try it **Run it once now** runs the agent that looks first, once, on the latest event its wake-up would count, so you see a result before a real one arrives. While it works, the step shows a spinner and the seconds so far; the result appears as a card with the steps that led to it. It uses your model provider like a real run, is marked **Practice**, and is left out of today's totals. With your own agent, the same button sends your agent a practice wake-up and waits for its finding. **Open the project** goes to the project's Overview. ## What it needs A [model provider](/tares/model-providers) on the instance, the same one [Ask](/tares/ask) uses. Without one, the goal step says so and links to **Add a model provider**. ## On the API | Call | Does | |---|---| | `POST /api/setup/drafts` `{goal, who?}` | makes a draft project and starts writing its plan in the background (202); `who` is `tares` or `own` | | `GET /api/projects/{id}/setup` | where the setup is: for a draft, its `goal`, `who`, `planning` steps and `plan`; once set up, the `step`, `checks` and what Connect shows | | `POST /api/projects/{id}/setup/plan` `{goal, who?}` or `{instruction, plan?}` | plans a draft again, from a changed goal or as the instruction says (202) | | `PUT /api/projects/{id}/setup` `{plan}` or `{step}` | keeps the edited plan on a draft; once set up, moves to `connect`, `try` or `done` | | `POST /api/setup/check` `{plan, project?}` | the plan normalized as apply would, and its `problems` per item; no model call | | `POST /api/setup/apply` `{plan, project?}` | creates the project and everything it needs from the plan; `project` is the draft that becomes the project | | `POST /api/projects/{id}/setup/test-event` `{source}` | sends the plan's example event into a source your system pushes to | | `POST /api/projects/{id}/setup/practice` | the practice run: `{run_id}` for a Tares agent, `{dispatch_id}` for your own agent | | `DELETE /api/projects/{id}` | deletes a draft, like any project | The plan uses the connectors installed on your instance. If none fits part of your goal, the plan says so in a note rather than forcing a poor match. Tell us what you would connect next: [help@glassflow.ai](mailto:help@glassflow.ai). --- # Deployment Tares is a single process writing to a single DuckDB file. There is no external database or broker to run. DuckDB is single-writer, so a deployment is exactly **one `taresd` and one data volume**. Do not run multiple replicas against the same data. ## Local Install the package and run `tares up`: ```bash uv tool install tares # or: pipx install tares tares up # console on http://127.0.0.1:8787, data in ~/.tares ``` `tares up` accepts `--host`, `--port`, `--data-dir`, `--open`, and `--auth` (see [Authentication](#authentication), off by default). To expose the MCP endpoint for external agents, also run `tares mcp` as a second process: ```bash tares mcp --transport streamable-http --port 8788 --taresd http://localhost:8787 ``` The MCP endpoint is then at `http://localhost:8788/mcp`. ## Docker One image serves both processes: it runs the daemon by default, and the MCP server when started with the `tares mcp` command. Run them as two containers on a shared network so they can reach each other: ```bash docker network create tares docker run -d --name taresd --network tares -p 8787:8787 -v tares-data:/data \ ghcr.io/glassflow/tares:latest docker run -d --name tares-mcp --network tares -p 8788:8788 \ ghcr.io/glassflow/tares:latest \ tares mcp --transport streamable-http --host 0.0.0.0 --port 8788 --taresd http://taresd:8787 ``` The console is at `http://localhost:8787`, the MCP endpoint at `http://localhost:8788/mcp`. (Only want the console? The first two commands are enough.) Running both plus TLS is what the compose file below wires up for you. To tear it down: ```bash docker rm -f taresd tares-mcp docker network rm tares docker volume rm tares-data # only if you also want to delete the data ``` ## Server (compose + TLS) For a server, run the daemon, the MCP server, and a reverse proxy that terminates TLS and routes one hostname. Two files in one directory: `docker-compose.yml` and the `Caddyfile` it mounts. Both ship in the repo under [`deploy/compose/`](https://github.com/glassflow/tares/tree/main/deploy/compose), or copy them from here. The image serves both processes (same image, different command): ```yaml # docker-compose.yml name: tares services: taresd: image: ghcr.io/glassflow/tares:${TARES_VERSION:-latest} command: ["tares", "up", "--host", "0.0.0.0", "--data-dir", "/data"] environment: TARES_AUTH_TOKEN: "${TARES_AUTH_TOKEN:?set TARES_AUTH_TOKEN}" volumes: [tares-data:/data] expose: ["8787"] restart: unless-stopped mcp: image: ghcr.io/glassflow/tares:${TARES_VERSION:-latest} command: ["tares", "mcp", "--transport", "streamable-http", "--host", "0.0.0.0", "--port", "8788", "--taresd", "http://taresd:8787"] environment: TARES_AUTH_TOKEN: "${TARES_AUTH_TOKEN:?set TARES_AUTH_TOKEN}" expose: ["8788"] depends_on: [taresd] restart: unless-stopped caddy: image: caddy:2 ports: ["80:80", "443:443"] environment: TARES_DOMAIN: "${TARES_DOMAIN:-:80}" volumes: ["./Caddyfile:/etc/caddy/Caddyfile:ro", "caddy-data:/data"] depends_on: [taresd, mcp] restart: unless-stopped volumes: tares-data: caddy-data: ``` Save this next to it as `Caddyfile` — the compose file mounts it into the Caddy container (`./Caddyfile:/etc/caddy/Caddyfile`), so compose fails to start without it: ```caddyfile # Caddyfile: one hostname; /mcp and /sse go to the MCP server, the rest to the daemon {$TARES_DOMAIN} { handle /mcp* { reverse_proxy mcp:8788 } handle /sse* { reverse_proxy mcp:8788 } handle { reverse_proxy taresd:8787 } } ``` Set the domain and token, then start it from that directory: ```bash export TARES_AUTH_TOKEN=$(openssl rand -hex 24) TARES_DOMAIN=tares.example.com docker compose up -d ``` A real `TARES_DOMAIN` enables Caddy's automatic HTTPS (point its DNS A record at the host first); unset, it serves plain HTTP on `:80`. The console is at `https://`; the MCP endpoint at `https:///mcp`. ### Image versions Images are published to `ghcr.io/glassflow/tares`: `:latest` (the default branch) and a tag per release (`:0.1.0`, `:0.1`). Pin `TARES_VERSION` for reproducible deploys. ## Configuration Both processes are configured by environment variables. The **read by** column says which process uses each one: the daemon (`taresd`), the MCP server (`tares-mcp`), or both. variable read by default description `TARES_DB` `taresd` `tares.duckdb` path to the DuckDB file (`tares up` uses `~/.tares`) `TARES_HOST` `taresd` `127.0.0.1` bind address (`0.0.0.0` to expose) `TARES_PORT` `taresd` `8787` bind port `TARES_CATALOG` `taresd` `catalog.yaml` catalog YAML imported on first boot if the DB is empty `TARES_CATALOG_SYNC` `taresd` unset if set, re-import the catalog YAML on every boot (file is source of truth) `TARES_AUTH_TOKEN` both unset require this bearer token everywhere (what `tares up --auth` sets); `tares-mcp` also sends it to the daemon `TARES_OTLP_GRPC_PORT` `taresd` `4317` OTLP/gRPC receiver port (`off` to disable; needs the `otlp-grpc` extra) `ANTHROPIC_API_KEY` `taresd` unset the Anthropic [model provider](/tares/model-providers) for Ask and [Tares agents](/tares/tares-agents) (or add providers in the console) `ANTHROPIC_AUTH_TOKEN` `taresd` unset a bearer token instead of the key, for a [gateway](#using-an-llm-gateway) that wants `Authorization: Bearer`; beats the key when both are set `ANTHROPIC_BASE_URL` `taresd` `https://api.anthropic.com` an Anthropic-compatible [gateway](#using-an-llm-gateway) to send model calls through; `TARES_ANTHROPIC_BASE` is the old name, still read `OPENAI_API_KEY` `taresd` unset seeds an OpenAI [model provider](/tares/model-providers); `OPENAI_BASE_URL` its base URL, for Azure or a proxy `TARES_MODEL_PROVIDER` `taresd` unset id of the default provider (`anthropic`, `openai`, or a saved endpoint's id) when none is chosen in the console `TARES_AGENT_MODEL` `taresd` `claude-sonnet-4-6` the default model on the default provider, for the Ask assistant and Tares agents `TARESD_URL` `tares-mcp` `http://127.0.0.1:8787` the daemon to proxy to (what `--taresd` sets) `TARES_MCP_TRANSPORT` `tares-mcp` `stdio` `stdio`, `streamable-http`, or `sse` `TARES_MCP_HOST` `tares-mcp` `127.0.0.1` bind address for the HTTP transports `TARES_MCP_PORT` `tares-mcp` `8788` bind port for the HTTP transports
## Authentication Auth is one switch, set at launch: - **`tares up`**: **open**. No login; the API, console, and ingest are all reachable without a credential. The local default. - **`tares up --auth`**: **secured**. Every route requires a credential: the console and API, and ingest too. A bare `--auth` generates a **root token**, persists it to the data dir, and prints a click-to-login URL each launch (`…/?token=`). `--auth=` (or setting `TARES_AUTH_TOKEN`) uses your own token, the shape for hosted/scripted deploys. There is no separate ingest token and no read-only mode. On a secured instance you hand machines their own **scoped [API keys](#api-keys)**, never the root token. ### API keys The root token is the operator's login; you mint narrower credentials from it. In the console → **Settings → API keys**, create a key with a subset of three scopes: | scope | grants | |---|---| | `read` | reads, timelines, catalog, projects and their skills, an agent's own subscriptions (the MCP read surface) | | `ingest` | `POST /ingest/*`, `/v1/*`, write memories | | `admin` | every change: sources, triggers, agents, skills, projects, MCP servers, integrations, settings, keys, a project's subscriptions (implies the others) | | `findings` | recording a finding in a project; only on a [project key](#project-keys) | Keys are shown once at creation, revocable, and never returned again. Example key types: | holder | scopes | |---|---| | an MCP agent | `read` | | an agent that works inside one project | a [project key](#project-keys): `read` + `findings` | | a producer (Vercel drain, OTLP exporter, webhook) | `ingest` | | the Claude Code plugin | `read` + `ingest` | On a secured instance, creating a **push source** mints an `ingest` key for it and shows it once. Hand that to the producer as `Authorization: Bearer …`. It appears in **Settings → API keys** like any other key, where you can mint new ones and deactivate existing ones. ### Project keys A **project key** belongs to one [project](/tares/projects). It reads that project and records findings in it, and nothing else. Make one on the project page (**Settings → Keys → New key**), with `POST /api/projects/{id}/keys {"name": "claude-code"}`, or with `POST /api/keys {"name": "claude-code", "project": "checkout watch"}` (the project by id or name). Its scopes are `read` and `findings`; pass `"scopes": ["read"]` for one that only reads. The key's name is the name its findings carry. What a project key can do is listed under [Outside agents](/tares/projects#outside-agents); any other call answers 403 `this key only reads project and records findings in it`. Revoking a project key removes the subscriptions it made, and deleting the project revokes its keys. Like every key, project keys are checked on a secured instance; on an open instance nothing is checked, and tools take the project by name instead. The root token is the console login. For per-user SSO, put a proxy (oauth2-proxy, Tailscale, Caddy basic-auth) in front of the console; machines keep their scoped API keys. ## Settings **Settings** in the console footer holds the instance's access mode and credentials, in four tabs (`/settings?tab=…` deep-links each): - **Access and API keys**: the auth mode this instance was launched with, and the [API keys](#api-keys). - **Model providers**: what [Tares agents](/tares/tares-agents) and Ask run on. A list of [providers](/tares/model-providers), Anthropic, OpenAI or any OpenAI-compatible endpoint, one of them the default. Values stored here win over the environment (`ANTHROPIC_API_KEY`, `OPENAI_API_KEY`, `TARES_MODEL_PROVIDER`); with none stored, the environment's values show as such. Credentials are never returned by the API. - **GitHub**: a GitHub token stored **once**, by name. Sources of the [`github`](/tares/connectors/github) connector reference it as `credential: ` instead of a token per source, and MCP servers reference it as their auth value `credential:github/`. **Test** shows the login it belongs to; the row lists which sources and MCP servers use it; **Rotate** replaces the token in one place and every user of it follows on its next poll or connection. The token is never returned by the API and never included in a catalog export. Use a fine-grained token with Contents (read, or read and write on a repository an agent should update), Pull requests read and write, Metadata read. - **Slack**: the workspace bot token findings and firings are posted with, and the signing secret behind inbound Slack events. ## Using an LLM gateway Tares agents and Ask talk to api.anthropic.com by default. An organisation that routes all model traffic through a gateway (LiteLLM, Portkey, Helicone, a proxy in front of Bedrock or Vertex) can point Tares at it. Two ways, and both reach every model call, for trigger-woken agents and for Ask alike. **In the console**, under **Settings → Model providers**: edit the Anthropic entry, put the gateway's URL in its base URL, and its token or your key in the key field, save. The change applies from the next model call, no restart. This is the path on a hosted cell, where the environment is not yours to set; the platform key stops being used, exactly as when you store your own key. **Stop using the gateway** returns to the environment's gateway if the deployment set one, else to Anthropic. **In the environment**, with the same variables Claude Code uses: ```bash ANTHROPIC_BASE_URL=https://llm-gateway.internal # serves the Anthropic Messages format ANTHROPIC_AUTH_TOKEN= # sent as Authorization: Bearer tares up ``` Values stored in the console win over the environment. The credential is sent one of two ways: a gateway token (stored, or `ANTHROPIC_AUTH_TOKEN`) as a bearer header, or a key (stored, or `ANTHROPIC_API_KEY`) as the Anthropic key header, which gateways accept too. A stored gateway token comes first, then a stored key, then the environment's token, then its key. Two things to know when a gateway is in the path: - **The gateway decides what answers.** Tares sends a Claude model id and accepts any well-formed reply; a gateway that maps that id to another model is the operator's choice. The agent prompts and the guided setup are written and tested against Claude. - **Spend is priced at Claude rates.** The console's spend meter prices runs from Tares's own price table, by the model name in the reply. Behind a gateway, the gateway's bill is the truth; a reply naming a model Tares does not price shows as an uncosted run. The environment variables are read when `taresd` starts; the console values are read on every call. A LiteLLM can also be added as an OpenAI-compatible [model provider](/tares/model-providers) instead, its native format: the picker then offers the aliases your key may use, and LiteLLM's own cost figure lands on each run. ## Upgrading from 0.x 1.0 renamed the project from NavFlow to Tares. There is no compatibility layer: the old names are not read at all. If the daemon finds leftovers from a pre-1.0 install, an old environment variable or an old database file, it stops at startup and tells you exactly what to rename. **Environment variables.** Every `NAVFLOW_*` variable is now `TARES_*`, with the same meaning. Nothing falls back to the old name. If any `NAVFLOW_*` variable is still set, `tares up` and `taresd` exit and print the exact renames you need: ```text tares 1.0 renamed every NAVFLOW_* environment variable to TARES_*, and does NOT read the old names. Still set in this environment: NAVFLOW_DB -> TARES_DB Rename them and start again. ``` Three variables are gone rather than renamed: `NAVFLOW_INGEST_TOKEN` and `NAVFLOW_READONLY` were folded into `--auth` plus scoped [API keys](#api-keys) in 0.2.0, and `NAVFLOW_ANTHROPIC_KEY` became the standard `ANTHROPIC_API_KEY`. **The database file.** `navflow.duckdb` is now `tares.duckdb`. DuckDB creates a missing file happily, so an upgrade that left the old file in place would come up healthy and completely empty with your data untouched beside it. Instead the daemon stops: ```text found a pre-1.0 database at ~/.tares/navflow.duckdb, and none at ~/.tares/tares.duckdb. ``` Migrating is one move, with the daemon stopped: ```bash mv ~/.tares/navflow.duckdb ~/.tares/tares.duckdb # or /data/… in a container ``` The data directory itself also moved, from `~/.navflow` to `~/.tares`. If you never set `--data-dir` or `TARES_HOME`, move the whole directory (`mv ~/.navflow ~/.tares`) before renaming the file inside it. **Everything else** is a straight rename, with no runtime guard: the package and command (`navflow` to `tares`), the daemon (`navflowd` to `taresd`), the MCP proxy (`navflow-mcp` to `tares-mcp`), the `--navflowd` flag (`--taresd`), the image (`ghcr.io/glassflow/navflow` to `ghcr.io/glassflow/tares`), and the Claude Code plugin (`navflow@navflow` to `tares@tares`). ## Backups The data is the DuckDB file in the volume. Back it up by snapshotting the volume (or the host) or copying `/data/tares.duckdb`; restore by putting the file back before start. --- # Connectors A connector defines how a [source](/tares/concepts#sources) gets events into Tares. These are the supported connectors: | connector | ingests | mode | discover | |---|---|---|---| | [Prometheus](/tares/connectors/prometheus) | metrics you pick (by name or label) | poll | yes | | [Prometheus alerts](/tares/connectors/prometheus-alerts) | alerts Prometheus's rules fired (+ resolved) | poll | yes | | [Alertmanager](/tares/connectors/alertmanager) | alerts Alertmanager routes (webhook) | push | no | | [Docker logs](/tares/connectors/docker-logs) | a running container's logs | poll | yes | | [OpenTelemetry (OTLP)](/tares/connectors/otlp) | OpenTelemetry logs/traces/metrics | push | no | | [GitHub](/tares/connectors/github) | pull requests, pushes, reviews, issues, releases, CI runs (App); commits and pull requests (token) | push (App) or poll (token) | yes | | [Postgres](/tares/connectors/postgres) | new/changed table rows | poll | yes | | [Vercel](/tares/connectors/vercel) | Vercel log drain | push | no | | [Claude Code](/tares/connectors/claude-code) | Claude Code session transcripts (via the plugin) | push | no | | [Webhook](/tares/connectors/webhook) | arbitrary JSON | push | no | | [HTTP API (poll)](/tares/connectors/http-poll) | any JSON endpoint, one event per item | poll | yes | | [Reference](/tares/connectors/reference) | documents attached to an entity (always surfaced) | reference | no | | [Memory](/tares/connectors/memory) | agent observations (via `remember`) | push | no | Your system isn't on the list? The [HTTP API](/tares/connectors/http-poll) connector polls any JSON endpoint, the [webhook](/tares/connectors/webhook) connector accepts arbitrary JSON from anything that can POST, and [OTLP](/tares/connectors/otlp) covers anything instrumented with OpenTelemetry. New connector ideas are welcome as [GitHub issues](https://github.com/glassflow/tares/issues). ![The Sources page: every source with its health, poll cadence, and last ingest](/assets/tares-sources.png) ## Setting one up A source's config is the connector's fields plus a universal `labels` array. Every connector can be set up three ways — all paths normalize to the same stored config: - **With an agent**: ask a [connected agent](/tares/agents) to set it up; it calls the [setup tools](/tares/agents#set-up-sources-with-an-agent) (`discover_source`, `test_source`, `create_source`). - **In the console**: **Sources → Add source**, pick the connector, fill the form. - **As YAML / API**: declare it in the [catalog YAML](/tares/concepts#the-catalog) or `POST /api/sources`. Each connector page shows all three. ## Modes - **Poll**: `taresd` fetches from the upstream every `poll` interval (e.g. `5s`, `1m`). - **Push**: producers send events to `taresd` over HTTP. A push source has a generated `ingest_key`; producers POST JSON or NDJSON to `/ingest/`. OTLP uses `/v1/{logs,traces,metrics}`. - **Reference**: declarative, not polled or pushed. The config *is* the data (documents attached to entities); it's re-materialized on edit and always surfaced regardless of the read window. Used by [`reference`](/tares/connectors/reference). ## Labels Every connector accepts a `labels` array (the [label model](/tares/concepts#labels-keys-and-entities)). Each entry is `{ name, const | field, primary?, type? }`. `type: number` stores the label as a number so triggers can aggregate it (`avg`, `max`, `sum`); the default is `string`: ```yaml labels: - { name: service, field: service, primary: true } # the key - { name: env, const: prod } - { name: value, field: value, type: number } # aggregatable in triggers ``` Connectors that synthesize a normalized event advertise the fields they **provide**, e.g. [Vercel](/tares/connectors/vercel) provides `project`, `environment`, `source`, `path`, `host`, `deployment`, `branch`. The console's label editor offers these; a source's **Fields** tab shows each field's actual coverage. ## Discovery Some connectors support `discover`: given partial config they introspect the upstream and return a proposed config (e.g. GitHub validates the repo and finds the default branch; Postgres reads `information_schema` to pick a cursor and labels; Prometheus lists the metrics and labels you pick from). Discovery powers both the console's form and an agent's `discover_source` call. `GET /api/connectors` lists every connector's fields and whether it supports discovery. --- # Prometheus alerts: `prometheus_alerts` Polls Prometheus's own [`/api/v1/alerts`](https://prometheus.io/docs/prometheus/latest/querying/api/#alerts), the alerts its alerting rules have already fired. One event per active alert, keyed by a label, plus a `resolved` event when it clears. No Alertmanager and no PromQL: Prometheus decides what's an alert; Tares correlates it and can dispatch it to an agent. State is tracked across polls, so each alert fires **once** (re-emitting only on a state change) and emits a `resolved` event when it disappears, not one copy every tick. Supports [discovery](/tares/connectors#discovery): given a `url`, it lists the configured alerting rules and the severities present. **Prerequisites:** a reachable Prometheus server with alerting rules configured. ## Set up Ask a [connected agent](/tares/agents): > Use tares to ingest the firing alerts from the Prometheus at `localhost:9090`. The agent calls `discover_source` (lists the configured rules and the severities present), then `create_source`. **Sources → Add source → Prometheus alerts**. Enter the `url` (+ any auth) and **Discover**. It lists the configured alerting rules and their severities. Optionally filter by **severity** (blank = all) and toggle **include pending**. It proposes the always-present labels (`severity`, `state`); add per-alert labels like `namespace` / `service` from the **Fields** tab once alerts have been ingested. ```yaml - name: alerts connector: prometheus_alerts poll: 30s config: url: http://localhost:9090 severities: critical,warning # blank = all labels: - { name: severity, field: labels.severity, primary: true } - { name: state, field: state } ``` Or `POST /api/sources` with the same object. Each alert becomes an event with `event_type` = the alert name, `text` = its summary, and its labels as Tares labels plus a synthetic `state` (`firing` / `pending` / `resolved`). ## Configuration | field | type | description | |---|---|---| | `url`* | string | Prometheus base URL, e.g. `http://localhost:9090` | | `bearer_token` | string · secret | optional `Authorization: Bearer` token (managed Prometheus / auth proxy) | | `username` | string | optional HTTP basic-auth username | | `password` | string · secret | optional HTTP basic-auth password / API token, paired with `username` | | `severities` | string | comma-separated severities to ingest (blank = all), e.g. `critical,warning` | | `include_pending` | bool | also ingest alerts still `pending` (waiting out their `for:` duration) | Discover only proposes the labels **guaranteed** to be present (`severity`, `state`). An alert's dynamic labels (`namespace`, `service`, …) only exist while it's firing. Add those from the **Fields** tab once real alerts have been ingested. ## Verify Open the source: **Recent events** shows one event per active alert (and `resolved` events as they clear); **Fields** shows the labels the alerts carry, so you can promote `namespace` / `service` to correlate on. --- # Docker logs: `docker_logs` Tails a running container's logs, one event per line, all lines by default, with optional `match`/`drop` regex filters. Supports [discovery](/tares/connectors#discovery), and the dedicated `discover_docker` tool scans the whole local Docker environment for candidate containers. **Prerequisites:** access to the Docker daemon: run `taresd` on the host, or mount the Docker socket and include the Docker CLI in the image. ## Set up Ask a [connected agent](/tares/agents): > Use tares to find my running containers and ingest the api-server's logs. The agent calls `discover_docker` (scans running containers, proposes one source per candidate) or `discover_source` for a known container, `test_source` (dry-run, tails a few lines), then `create_source`. **Sources → Add source → docker_logs**. Set: - `container`: the container (or compose service) name **Discover** lists the running containers to pick from. If the container runs under Compose, set `compose_file` so the tail follows restarts. Save. ```yaml - name: logs connector: docker_logs poll: 5s config: container: tares-demo-api-server # the container name (docker ps) labels: - { name: service, const: api-server, primary: true } ``` If the container runs under Compose without a fixed `container_name`, set `container` to the service name and add `compose_file` (an absolute path, or relative to where the daemon runs) so the tail follows restarts. Or `POST /api/sources` with the same object. ## Configuration | field | type | description | |---|---|---| | `container`* | string | container (or compose service) name | | `compose_file` | string | path to `docker-compose.yml` if the container runs under Compose | | `match` | string | keep only lines matching this regex (default: all), e.g. `ERROR\|WARN` | | `drop` | string | skip lines matching this regex, e.g. `HTTP/1.1"` to drop access logs | | `label_pattern` | string | regex with named groups → per-line label context | ## Verify Open the source in the console: **Recent events** shows lines on the next poll. If nothing arrives, check that `taresd` can run `docker logs `, the same access it needs. --- # Claude Code sessions: `claude_code` Ingests Claude Code session transcripts into the data plane, one event per message, keyed by `session`, with `project`, `branch`, and `model` as labels and token-usage fields. Sub-agents roll up into the same source. Your agent sessions become a queryable source like any other: correlate what the agent did with what your systems did, and let the agent read back its own history. Sessions are fed by the **Tares plugin for Claude Code**, which ships each session's transcript to the daemon over HTTP as the session progresses. This works the same against a local **or** remote daemon, and the one install also wires up MCP read-back. ## Set up The console has a one-click page, **Sources → Add source → `claude_code`**, that shows the install command wired to *your* instance's URL (and token, if it needs one). Or run it directly in Claude Code: ``` /plugin marketplace add glassflow/tares /plugin install tares@tares ``` The install prompts for: - **Tares URL**: the daemon's base URL (the default `http://127.0.0.1:8787` matches `tares up`; use your instance's URL otherwise) - **Access token** (optional): only on a [secured instance](/tares/deployment#authentication); prefer a `read + ingest` [API key](/tares/deployment#api-keys) so the plugin can both stream sessions and read back over MCP. Stored in the OS keychain. - **Stream this session into Tares**: the capture toggle (on by default) That's the only step. One install wires both directions: - **Capture**: hooks ship new transcript lines to `/ingest/claude_code` on each prompt, tool use, and session end. The plugin creates the push source on the daemon the first time it runs, with no manual source setup. - **Read-back**: the plugin registers the `tares` MCP server, so the same agent can [read the data plane](/tares/agents). Capture is **forward-only**: sessions stream from when the plugin is installed onward; existing transcripts already on disk aren't backfilled. ## Configuration The push source is created automatically by the plugin; these fields tune what's stored: | field | type | description | |---|---|---| | `redact` | bool | redact obvious secrets/tokens before storing (default `true`) | | `include_thinking` | bool | include assistant thinking blocks in the rendered text (default `false`) | Redaction runs **server-side** in the connector, so it applies before anything is stored. ## Provided labels `session` (the key), `project`, `branch`, `model`, `type` (message type), `sidechain` (sub-agent messages). ## Challenger sessions A session marked with `/tares:challenger` (or "make this a challenger session") carries the `flow` label on every event from the mark onward, plus the events the challenger hooks write next to the transcript: `session_flow`, `challenge_plan`, `challenge_commit`, `challenge_waived` and `session_end`, with `verdict`, `sha`, `round`, `finding_count` and `blocking_count` as labels. The [challenger workflow guide](/tares/guides/challenger-workflow) walks a session end to end and lists the events. ## Verify Start a Claude Code session and do some work. In the console, **Explore** lists sessions under the `session` key; the source's **Recent events** shows messages as they ship. With the plugin installed, you can also just ask: > Use tares to show me my current session's timeline. --- # HTTP API (poll): `http_poll` Polls a JSON endpoint on the source's schedule and stores one event per item. The generic path for the APIs no other connector covers: a weather service, a status page, a SaaS export, an endpoint of your own. Nested values are reachable by dotted name everywhere, so a label, a trigger filter or a trigger condition can watch `current_weather.windspeed`. The [webhook](/tares/connectors/webhook) connector is for systems that call Tares. This one is for APIs Tares calls. ## Set up Ask a [connected agent](/tares/agents), or describe the goal in the [guided setup](/tares/build): > Tell me when Berlin gets storm winds, from a public weather API. The plan includes an `http_poll` source with the URL, and Tares polls it itself; no script on your side. `discover_source` reads one reply and fills in the rest. **Sources → Add source → HTTP API (poll)**. Fill in the request: method, URL, credentials if the API wants any (one header name and value, stored as a secret), additional headers, and a body for POST. Press **Discover**: Tares calls the API once, shows the reply it got, and fills in what becomes an event from it. Pick the entity key from the fields it saw, then Create. ```yaml - name: weather_berlin connector: http_poll poll: 10m config: url: https://api.open-meteo.com/v1/forecast?latitude=52.52&longitude=13.41¤t_weather=true event_type: weather event_time_field: current_weather.time id_field: current_weather.time text_template: 'Berlin wind {current_weather.windspeed} km/h, {current_weather.temperature} C' labels: - { name: city, const: berlin, primary: true } - { name: windspeed, field: current_weather.windspeed, type: number } ``` Or `POST /api/sources` with the same object. ## The reply becomes events - **`payload_key`** points at the part of the reply that is the payload, e.g. `data` or `data.items`. Empty means the entire JSON. An object there is one event; a list is one event per entry. - **`event_time_field`** names the field holding the event's time (ISO-8601 or epoch). Empty means the poll time. - **`id_field`** is the deduplication key: an item whose value was seen in recent polls is not stored again. Use the entry's `id` for a list API, or the reading's own time for a single reading that only changes every few minutes. Empty stores every poll. - **`event_type`** is the word trigger filters match and triggers count by, the same for every event; `event_type_field` takes it from a field of the item instead. - **`text_template`** is the event summary, one line per event with values from the payload in braces, dotted names included. Empty stores the payload's JSON. The payload is stored as received, so labels declared later can still reach every field. ## Authentication One credential travels in one header. `credential` holds the whole value and is stored as a secret, never returned by the API and never exported. `credential_header` names the header, `Authorization` by default: ```yaml config: url: https://api.github.com/user credential: Bearer ghp_xxx # a bearer token credential_header: Authorization ``` ```yaml config: url: https://api.example.com/v1/readings credential: abc123 # an API key credential_header: X-API-Key ``` Other headers the API wants on every request go in `headers`, which is not secret. ## Rate limiting A polled API has limits. The connector: - refuses a `poll` under 10 seconds when the source is saved; - backs off on a 429 or any 5xx: no request is made until the wait is over, and the wait doubles from the poll interval up to an hour. A 429 with `Retry-After` uses that value. The source's health says "rate limited by the API, next try at HH:MM"; - surfaces any other 4xx as a config error on the source's health, with the status and a slice of the reply; - clears the backoff on the next good poll. ## Configuration | field | type | description | |---|---|---| | `url` | string | the endpoint, query string included. Checked on save: http or https, a host, no spaces | | `method` | `GET` \| `POST` | default `GET` | | `body` | object | POST only: the JSON object to send | | `headers` | map | extra request headers, not secret | | `credential` | string, secret | the whole credential value, e.g. `Bearer xyz` or an API key | | `credential_header` | string | the header the credential is sent in (default `Authorization`) | | `payload_key` | string | the key in the reply that holds the payload; empty for the entire JSON | | `event_type` | string | fixed event type (default `api_reading`) | | `event_type_field` | string | field of the item to read the event type from | | `text_template` | string | the event summary, with `{field}` and `{a.b}` references | | `event_time_field` | string | field holding the event's time | | `id_field` | string | deduplication key; empty stores every poll | ## Verify Open the source: **Recent events** shows each poll's events with the summary line; **Fields** lists every field seen, dotted names included, with its coverage. A trigger on a number label, `max(windspeed) > 62 over 15m`, fires from the next reading that crosses it. --- # Alertmanager: `alertmanager` A [push](/tares/connectors#modes) receiver for [Alertmanager](https://prometheus.io/docs/alerting/latest/alertmanager/): point a `webhook_configs.url` at this source's ingest endpoint and every alert Alertmanager routes becomes an event. Alertmanager has already evaluated, grouped, deduped and (with `send_resolved`) tracks firing→resolved. Tares just records what it pushes, and correlates it with your other sources. Use this over [`prometheus_alerts`](/tares/connectors/prometheus-alerts) when you want Alertmanager's grouping / silencing / resolved semantics and real-time delivery. ## Set up Ask a [connected agent](/tares/agents): > Use tares to create an Alertmanager source and give me the webhook URL. The agent calls `create_source` and returns the ingest URL to configure as an Alertmanager receiver. **Sources → Add source → Alertmanager alerts**. Name it and **Create**. The source page shows a copy-paste `alertmanager.yml` receiver block with the ingest URL already filled in (and the auth block when the instance requires a token). Add the receiver to your `alertmanager.yml` and reload Alertmanager: ```yaml receivers: - name: tares webhook_configs: - url: http://localhost:8787/ingest/ send_resolved: true route: receiver: tares ``` On a [secured instance](/tares/deployment#authentication) (`tares up --auth`), add an `ingest`-scoped [API key](/tares/deployment#api-keys) to the `webhook_configs` entry: ```yaml http_config: authorization: type: Bearer credentials: ``` Alertmanager POSTs a batch (`{ alerts: [...], ... }`); Tares fans out the `alerts` array into one event each: `event_type` = the alert name, `text` = its summary, its labels as Tares labels plus a synthetic `status` (`firing` / `resolved`). The full alert (including `fingerprint`) is kept in the payload. ## Configuration A push connector, so no polling config. The entity key is auto-derived from a label (`namespace` → `service` → `job` → `instance`, or a declared `primary` label). | field | type | description | |---|---|---| | `key_label` | string · advanced | alert label to key on (default: `namespace` / `service` if present) | ## Verify Send a test batch to the ingest endpoint, then check **Recent events**: ```bash curl -X POST http://localhost:8787/ingest/ \ -H 'Content-Type: application/json' \ -d '{"alerts":[{"status":"firing","labels":{"alertname":"PostgresDown","severity":"critical","namespace":"prod"},"annotations":{"summary":"Postgres is down"},"startsAt":"2024-01-01T00:00:00Z"}]}' ``` **Fields** shows the alert labels, so you can promote `namespace` / `service` to correlate on. --- # GitHub Tares connects to GitHub in one of two ways. You pick a credential, and Tares decides how events arrive. | | GitHub App (recommended) | Personal token | |---|---|---| | How events arrive | as they happen, by webhook | polled, every 2 minutes by default | | What arrives | pull requests, pushes, reviews, review comments, comments, issues, releases, CI runs | commits, and pull requests opened, merged or closed | | Which repositories | every repository the App is installed on, in one source | one source per repository you add | | Agents act as | the App (`your-app[bot]`) | the token's user | | Check runs from agents | yes | no | ## With the GitHub App ### On Tares Cloud In your workspace settings, choose **Connect GitHub**, pick the organization and the repositories, and confirm on GitHub. Your workspace gets a `github` source carrying every event of those repositories. To add another organization, choose **Connect another account**. **Disconnect** removes the credential from your workspace and uninstalls the App on GitHub. ### Self-hosted 1. Open **Settings > GitHub** and choose **Create GitHub App**. 2. Enter the GitHub organization to create it in (leave it empty for your own account). Under **Address and App name**, check that the address is how GitHub reaches this Tares. 3. Choose **Continue on GitHub**. GitHub shows the App with its permissions and events filled in. Confirm it. 4. Back in Tares, choose **Install on GitHub**, pick the repositories, and install. Tares stores the App (its id, private key and webhook secret) as a credential and creates a `github` source for its webhook. Nothing is pasted by hand. GitHub must be able to reach your Tares for webhooks to arrive. A local `tares up` is not reachable from the internet, so run a tunnel and use its address as the public URL, for example: ```bash cloudflared tunnel --url http://localhost:8787 TARES_PUBLIC_URL=https://.trycloudflare.com tares up ``` The App can still be created without one; deliveries start once Tares is reachable. **Already have an App?** Add it under **Settings > GitHub** through the API with its app id, private key, webhook secret and installation ids (`POST /api/integrations/github` with `kind: app`), then point the App's webhook at the `github` source's ingest URL. The App asks for these permissions, which you can narrow on GitHub's page: | permission | access | why | |---|---|---| | Metadata | read | required by GitHub | | Contents | read and write | agents read code and write files on a branch | | Pull requests | read and write | agents open pull requests and review them | | Issues | read and write | agents comment | | Checks | read and write | agents post their verdict as a check run | | Actions | read | CI run events | | Commit statuses | read | commit status events | and these events: pull request, pull request review, pull request review comment, push, issues, issue comment, release, workflow run. Every delivery is checked against the App's webhook secret before anything is stored. An unsigned or wrongly signed request gets a 401 and is counted on the credential's row in **Settings > GitHub**. A delivery GitHub sends twice is stored once. An installation that was not started from this Tares (someone installing a public App on their own account) is not added. ## With a personal token 1. Create a fine-grained token on GitHub with the repositories you want and these permissions: **Metadata** read, **Contents** read, **Pull requests** read. Add **Contents** and **Pull requests** write only if agents should change repositories with it. A classic token needs the `repo` scope for private repositories. 2. Open **Settings > GitHub**, choose **Add a personal token**, and paste it. 3. Add a source per repository: **Sources > Add source > GitHub**, pick the credential and the repository, and save. Each source polls its repository's commits and its pull requests. The first poll imports recent commits and no old pull requests. A pull request reopened between two polls is not reported. If the token cannot read pull requests, commits still arrive and the daemon log says why once. ```yaml - name: checkout-api connector: github poll: 2m config: repo: acme/checkout-api credential: github labels: - { name: repo, field: repo, primary: true } ``` Or `POST /api/sources` with the same object. | field | type | description | |---|---|---| | `repo`* | string | `owner/name`, e.g. `acme/checkout-api` | | `credential` | string | a GitHub credential from **Settings > GitHub**, resolved at every poll | | `token` | string | a token for this source only (secret); prefer a credential | | `branch` | string | branch to follow (default: the repository's default branch) | | `limit` | number | commits fetched per poll (default 20) | | `files` | bool | add each new commit's changed files (capped) to its payload (default true) | | `prs` | bool | also report pull requests opened, merged or closed (default true) | | `api_url` | string | GitHub API base for GitHub Enterprise (default `https://api.github.com`) | ## Events and labels Both ways produce the same events, so a trigger keeps working when you switch from a token to the App. | `event_type` | arrives with | key | |---|---|---| | `pull_request` | both (a token: opened, merged, closed) | `owner/repo#number` | | `commit` | personal token | `owner/repo` | | `push` | App | `owner/repo` | | `pull_request_review`, `pull_request_review_comment` | App | `owner/repo#number` | | `issues`, `issue_comment` | App | `owner/repo#number` | | `release` | App | `owner/repo` | | `workflow_run` | App | `owner/repo` | Every GitHub event carries these labels when they apply: `repo`, `action` (`opened`, `synchronize`, `merged`, `closed`, `reopened`, `ready_for_review`, `submitted`, `created`, `published`, `completed`, `pushed`), `number`, `author`, `branch`, `base`, `state`, `draft`, `sha`, `url`, `title`, `conclusion` (CI runs), `release_tag`, `workflow`, `commits` (pushes) and `on_default_branch` (pushes). A closed pull request that merged reads `merged`. **Example: every merged pull request in two repositories.** A trigger on the `github` source with these filters, one firing per pull request: ```yaml - name: pr-merged sources: [github] filters: - { field: event_type, op: eq, value: pull_request } - { field: action, op: eq, value: merged } - { field: repo, op: in, value: [acme/checkout-api, acme/payments] } condition: { aggregate: count, predicate: "> 0", window: 5m } cooldown: 5m ``` In the console's trigger editor, a filter on `event_type` or `action` over a GitHub source offers these values to pick from. ## Agents on GitHub In a Tares agent's settings, the **GitHub** section picks a credential and what the agent may do: read repositories, or read and write (branches, files, pull requests, comments, reviews). Reads and writes go through GitHub's MCP server, authenticated with that credential, so with the App every write shows as the App. Tares sets the server up the first time; there is nothing to register. With the App, the agent can also post its verdict on a pull request as a **check run**: a pass, fail or neutral result in the pull request's checks, with notes on the lines it is about. Ask for it in the agent's instructions, for example "post your verdict as a check run on the pull request's head commit". Every GitHub call shows in the run's record, and a check run appears in the run's results. Prefer pull requests over writing to the default branch: ask the agent to open a pull request with its change, so a person reviews it. ## Troubleshooting - **No deliveries from the App.** Check that Tares is reachable at the address the App uses (a local Tares needs a tunnel) and that the App is installed on the repository. GitHub's App settings list recent deliveries under **Advanced**, with their responses. - **Deliveries refused (401).** The webhook secret on GitHub does not match the credential's. A recreated App gets a new one; reconnect it from **Settings > GitHub**. - **A 403 from GitHub.** The App or token lacks a permission; the error names the call. On the App, accept new permissions on GitHub after changing them. - **Pull requests do not arrive on a token source.** The token lacks **Pull requests** read. --- # Agent memory: `memory` The agent's own observations, written back via the MCP `remember` tool (or `POST /remember`). Joined into reads and triggers like any other source: what an agent concluded about `service=checkout` last week sits in the same timeline as the service's logs and deploys. ## Set up None needed. The first `remember` call auto-provisions an `agent_memory` source; every connected agent has the tool: > Use tares to remember that the checkout latency spike on July 1 was caused by the pool-size > change. Create a `memory` source explicitly (console or YAML) only to set a custom fallback key or run several memory lanes: ```yaml - name: agent_memory connector: memory config: key: agent ``` ## Configuration | field | type | description | |---|---|---| | `key` | string | fallback entity key when a memory's payload has none (default `agent`) | ## Verify After a `remember` call, the observation appears in the source's **Recent events**, keyed by the entity it was remembered against, and in that entity's correlated timeline. --- # OpenTelemetry: `otlp` Receives OTLP/HTTP logs, traces, and metrics at `POST /v1/{logs,traces,metrics}`. One source ingests every service: resource attributes (e.g. `service.name`) become labels, so everything an OTel SDK or Collector exports correlates by service with no per-service setup. **Prerequisites:** something exporting OTLP, such as an instrumented app or an OpenTelemetry Collector, pointed at the daemon. For OTLP/gRPC, the `otlp-grpc` extra (`pip install 'tares[otlp-grpc]'`); the receiver listens on `:4317` (`TARES_OTLP_GRPC_PORT`, `off` to disable). ## Set up Ask a [connected agent](/tares/agents): > Use tares to create an OTLP source keyed by service. The agent calls `create_source`; then point your exporter at the daemon (below). **Sources → Add source → otlp**. There is no required config; the `service` label (from `service.name`) is the natural key. Save. ```yaml - name: otel connector: otlp config: labels: - { name: service, field: service, primary: true } ``` Or `POST /api/sources` with the same object. Then point the exporter at the daemon: ```bash OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:8787 # OTLP/HTTP → /v1/{logs,traces,metrics} # or gRPC (otlp-grpc extra): OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4317 ``` On a [secured instance](/tares/deployment#authentication) (`tares up --auth`), exporters send an `ingest`-scoped [API key](/tares/deployment#api-keys) as `Authorization: Bearer ` (e.g. `OTEL_EXPORTER_OTLP_HEADERS=Authorization=Bearer `). ## Configuration No connector-specific fields, just `labels`. Resource attributes are available as label fields (`service` from `service.name`). ## Verify **Recent events** shows spans/logs/metric points as they arrive; **Explore** lists services under the `service` key. --- # Postgres table: `postgres` Polls a table incrementally, one event per new/changed row. The cursor tracks a monotonic column (an autoincrement `id`, or `updated_at`); an entity column (e.g. `tenant_id`) becomes the key via a `primary` label. Your application's source-of-truth data in the timeline. Supports [discovery](/tares/connectors#discovery): given the connection URL it lists the tables it can see, then reads the chosen table's columns to propose the cursor and labels. **Prerequisites:** a Postgres reachable from the Tares host. The driver ships with Tares, so no extra to install. ## Set up Ask a [connected agent](/tares/agents): > Use tares to ingest the `orders` table at ``, keyed by `tenant_id`. The agent calls `discover_source` (lists tables, then proposes the cursor and labels from the columns), `test_source` (dry-run, fetches sample rows), then `create_source`. **Sources → Add source → Postgres**. Enter the **Connection URL** (`dsn`) and **Discover**. It lists the tables it can see; pick one, and it proposes the cursor, entity key and labels from the columns. Choose which **columns** to pull (all by default), then save. ```yaml - name: orders connector: postgres poll: 10s config: dsn: postgresql://user:pass@host:5432/appdb table: orders cursor_column: updated_at columns: id,tenant_id,status,amount,updated_at # empty = every column labels: - { name: tenant_id, field: tenant_id, primary: true } - { name: status, field: status } ``` Or `POST /api/sources` with the same object. The `dsn` is stored as a secret (redacted in the API, omitted from catalog exports). ## Configuration | field | type | description | |---|---|---| | `dsn`* | string · secret | `postgresql://user:pass@host:port/dbname`, this source's connection URL | | `table`* | string | table to poll, e.g. `orders` or `public.orders` (Discover lists the tables) | | `cursor_column`* | string | column that only ever grows, such as an `id` (inserts) or `updated_at` (also updates). Discover picks it | | `columns` | string | comma-separated columns to pull (empty = every column). The cursor / key / time columns are always included | | `time_column` | string | timestamp column for `event_time` (default: the cursor if it's a timestamp, else ingest time) | | `limit` | number | rows to fetch per poll | | `text_template` | string · advanced | optional `str.format` template over the row, e.g. `'{tenant_id}: {status} ${amount}'` | `database` and `table` are also available as label fields (from config), regardless of which columns you pull. ## Verify Open the source: **Recent events** shows rows on the next poll; **Fields** reports each column's coverage. Use it to confirm the key column is reliably present. --- # Prometheus: `prometheus` Ingests the Prometheus metrics you pick. Each series becomes a metric event on every poll tick, joinable with logs, deploys and alerts on the same key. You **choose which metrics** (by name, or by a label they carry) and Tares does the rest: **there is no PromQL to write.** The numeric value is stored as a number-typed `value` label, so [triggers](/tares/guides/triggers) can aggregate it. Supports [discovery](/tares/connectors#discovery): given a `url`, it lists the server's metrics and labels for you to pick from. **Prerequisites:** a reachable Prometheus server (its base URL, e.g. `http://localhost:9090`). ## Set up Ask a [connected agent](/tares/agents): > Use tares to ingest the `pg_*` metrics from the Prometheus at `localhost:9090`. The agent calls `discover_source` (lists the metrics and labels, samples your picks, proposes the config), `test_source` (one poll), then `create_source`. You name the metrics you want. It never writes PromQL. **Sources → Add source → Prometheus**. Enter the `url` (+ any auth) and **Discover**, then pick the metrics to ingest: - **By name**: type a metric name or a `prefix_*` pattern; tick the matches. - **By label**: pick a label; it lists the metrics that carry it; tick the ones you want. Confirm, and Tares proposes the entity key and labels from a sample. No query language, at any step. The console and agent generate the config for you, so you rarely hand-write it. Your picks compile to a single selector that ingests every chosen metric, each event named by its own metric name: ```yaml - name: metrics connector: prometheus poll: 10s config: url: http://localhost:9090 queries: - promql: '{__name__=~"(pg_stat_database_xact_commit|pg_up)"}' # generated from your picks by_name: true labels: - { name: service, field: metric.service, primary: true } - { name: value, field: value, type: number } # the metric value, aggregate it in triggers ``` Or `POST /api/sources` with the same object. ## Configuration | field | type | description | |---|---|---| | `url`* | string | Prometheus base URL, e.g. `http://localhost:9090` | | `bearer_token` | string · secret | optional `Authorization: Bearer` token (managed Prometheus / auth proxy) | | `username` | string | optional HTTP basic-auth username (e.g. a Grafana Cloud instance id) | | `password` | string · secret | optional HTTP basic-auth password / API token, paired with `username` | | `default_key` | string | entity key for series that carry no key label (default `unknown`) | | `queries`* | list | the metrics to ingest, generated from your picks (below) | Each `queries` entry is a metric selector Tares builds from your picks. You don't author these by hand: | field | type | description | |---|---|---| | `promql`* | string | the metric selector; for a picked basket, a `{__name__=~"…"}` matcher built for you | | `by_name` | bool | basket mode, naming each event by its own metric name (set on a generated basket) | | `exclude` | string | comma-separated substrings to drop by metric name (e.g. `_bucket`) | | `event_type` | string | for a computed series: the event type to emit (default `metric`) | | `field` | string | for a computed series: the typed field to store the value under (default `value`) | | `text` | string | for a computed series: the rendered line, e.g. `"p99 {service}={val}ms"` | The metric value is stored as a **number-typed `value` label** (proposed automatically), so a [trigger](/tares/guides/triggers) can `max` / `avg` / `sum` it. Filter the trigger to one metric by `event_type`, then aggregate `value`. Number labels are excluded from entity faceting. **Advanced: a computed series.** A `queries` row can also be a single PromQL expression (a derived rate, a `histogram_quantile` p99) with an explicit `event_type` and `field`, the escape hatch when you want a *computed* metric rather than a raw one. The pick-metrics flow above covers raw ingestion without touching PromQL. ## Verify Open the source: **Recent events** shows one event per series per poll; **Fields** shows the labels (`metric.service`, …) and the numeric `value`. Watch a metric move in **Explore** by picking the entity the series is keyed on. --- # Reference documents: `reference` Documents (json / csv / md / txt) attached to an entity by their labels: project notes, schemas, runbooks. Unlike the event connectors this is **declarative reference material, not a stream**: it's [always surfaced](/tares/concepts#the-reference-source-type) when correlating on that entity, **regardless of the read time window**. A runbook doesn't "age out" of a 15-minute read. The config *is* the data: each attachment carries its own labels and content. Editing the source re-materializes it, so there's no poll interval, and no entity key (correlation is label-native). The labels you tag each document with become real Tares labels you can read and trigger on. ## Set up **Sources → Add source → Reference documents**. Upload json / csv / md / txt files (read into text), tag each with the labels of the entity it describes (e.g. `service=tares`, `environment=production`), and **Create**. Re-open the source and **Upload more** to extend it. ```yaml - name: runbooks connector: reference config: attachments: - name: restart.md format: md content: | 1. kubectl rollout restart deploy/tares 2. watch the pod come healthy labels: { service: tares, environment: production } labels: - { name: service, field: service } - { name: environment, field: environment } ``` Or `POST /api/sources` with the same object. `labels` declares the label names (so reads can correlate on them); each attachment provides the values. ## Configuration | field | type | description | |---|---|---| | `attachments`* | list | the documents, each materialized into one always-surfaced event | Each `attachments` entry: | field | type | description | |---|---|---| | `name`* | string | file name / title | | `content`* | string | the document's text | | `format` | string | `json` \| `csv` \| `md` \| `txt` | | `labels` | object | entity labels, e.g. `{ "service": "tares" }` | ## Verify Open the source: **Recent events** shows one event per document; **Fields** shows the labels they carry. Read the entity they describe (`read({ service: tares })`) and the documents come back in the timeline, even outside the read window. --- # Vercel logs: `vercel` Push source for Vercel logs: point a Vercel log drain (JSON) at the source's ingest endpoint. One event per log entry, keyed by `project`, with `environment` and `source` as labels. A single drain can carry multiple projects; they appear as distinct entities. **Prerequisites:** the ingest endpoint must be **publicly reachable**: Vercel delivers from its cloud. Use a [deployed instance](/tares/guides/self-host) or a tunnel; a bare `localhost` daemon will not receive drains. ## Set up Ask a [connected agent](/tares/agents): > Use tares to create a vercel source and give me the ingest URL for the log drain. The agent calls `create_source` (no required config) and returns the source's ingest endpoint. Then add the drain in Vercel as below. **Sources → Add source → vercel**. There is no required config; the `project` (key), `environment`, and `source` labels are pre-filled. Save. The source page shows its **ingest endpoint**. It is a stable URL of the form `https:///ingest/`. Copy it. ```yaml - name: web-logs connector: vercel config: labels: - { name: project, field: project, primary: true } - { name: environment, field: environment } - { name: source, field: source } ``` Or `POST /api/sources` with the same object; the response includes the `ingest_key`. Then, in Vercel: **Team Settings → Log Drains → Add Log Drain**, where endpoint = the ingest URL, delivery format = JSON. Vercel verifies the endpoint via an `x-vercel-verify` header, which Tares echoes back from Vercel's verification request. On a [secured instance](/tares/deployment#authentication) (`tares up --auth`), add an `ingest`-scoped [API key](/tares/deployment#api-keys) to the drain as a custom header (`Authorization: Bearer `). ## Configuration No connector-specific fields, just `labels`. ## Provided labels `project` (the key; from the payload's `projectName`, else `projectId`), `environment` (`production` | `preview`), `source` (`lambda` | `build` | `edge` | `static` | `external` | `redirect`), `path`, `host`, `deployment`, `branch`. ## Verify Once the drain is saved and traffic flows: **Recent events** shows entries arriving; **Fields** shows which `project`s appear and each field's coverage. If `project` reads sparse, pick a denser field as the key, or slice by `source` / `environment`. --- # Inbound webhook: `webhook` Push ingestion of arbitrary JSON (or NDJSON): producers POST to the source's ingest endpoint. The payload is stored lossless; declare labels to map payload fields into the envelope. The catch-all connector for anything that can send an HTTP request: CI systems, GitHub webhooks, cron jobs, your own services. ## Set up Ask a [connected agent](/tares/agents): > Use tares to create a webhook source for my CI events, keyed by the payload's `pipeline` field. The agent calls `create_source` and returns the ingest URL to point your producer at. Use `test_source` with a sample payload to check the label mapping first. **Sources → Add source → webhook**. Declare a label per payload field you want to correlate on (mark one `primary`). Save, then copy the **ingest endpoint** from the source page. ```yaml - name: ci-events connector: webhook config: event_type_field: action text_template: '{action} by {sender}' labels: - { name: pipeline, field: pipeline, primary: true } ``` Or `POST /api/sources` with the same object; the response includes the `ingest_key`. Producers then POST JSON (one object, a list, or NDJSON) to `/ingest/`: ```bash curl -X POST http://localhost:8787/ingest/ \ -H 'Content-Type: application/json' \ -d '{"action": "deploy", "sender": "ci", "pipeline": "web"}' ``` On a [secured instance](/tares/deployment#authentication) (`tares up --auth`), producers send an `ingest`-scoped [API key](/tares/deployment#api-keys) as `Authorization: Bearer `. Creating a push source in the console mints one for it and shows it once. ## Configuration | field | type | description | |---|---|---| | `event_type` | string | fixed event type (default `webhook_event`) | | `event_type_field` | string | payload field to read the event type from, e.g. `action` | | `text_template` | string | render template over payload fields, e.g. `'{action} by {sender}'` | | `event_time_field` | string | payload field holding an ISO-8601 event timestamp | ## Verify POST a test payload (as above) and check **Recent events**; **Fields** shows which payload fields arrive and how often. Use it to pick a reliable key. --- # Connecting agents (MCP) Connect Claude Code, Codex, Cursor, or any MCP client to Tares and ask questions like *"what happened to api-server in the last 15 minutes?"*. The client discovers the Tares [tools](#tools) and answers from the correlated timeline: logs, metrics, alerts, and findings in one read. This page is about **connecting an external agent** that lives in your own infrastructure and can act on your systems. For an agent that runs *inside* Tares, waking on a trigger to write a finding, see [Tares agents](/tares/tares-agents). ## 1. Get your endpoint The MCP endpoint depends on where Tares runs: | where Tares runs | your MCP endpoint | |---|---| | your machine (`tares up`) | `http://localhost:8788/mcp` (start the MCP server below first) | | your own server ([compose deployment](/tares/deployment#server-compose--tls)) | `https:///mcp` | | Tares Cloud | shown in your console under **Connect**; each instance has its own hostname | Running locally? The daemon alone does not serve `/mcp`. Start the MCP server as a second process: ```bash tares mcp --transport streamable-http --port 8788 --taresd http://localhost:8787 ``` On a server or Tares Cloud instance the MCP server is already running; there is nothing to start. ## 2. Connect your client The snippets below use the local endpoint, `http://localhost:8788/mcp`. Connecting to a server or Tares Cloud instance? Replace the URL with yours and add the credential from [Authentication](#authentication). The console's **Connect** page generates these exact commands with the endpoint and token filled in. ![The console's Connect tab: pick your client and get its exact command, endpoint and token filled in](/assets/tares-connect-mcp.png) The [Tares plugin](/tares/connectors/claude-code) is the default path for Claude Code. One install wires both directions: the MCP read-back **and** session capture into the [`claude_code`](/tares/connectors/claude-code) source. ``` /plugin marketplace add glassflow/tares /plugin install tares@tares ``` The install prompts for the Tares URL, an optional auth token (stored in the OS keychain), and a capture toggle. It requires the `tares` package on PATH (for `tares-mcp`). To connect without capturing sessions, use the CLI tab instead. Run in your terminal: ```bash claude mcp add --transport http tares http://localhost:8788/mcp ``` For a remote, secured instance, pass the credential as a header: ```bash claude mcp add --transport http tares https:///mcp \ --header "Authorization: Bearer " ``` Run in your terminal. Keep `--url` before the URL, a bare URL registers a stdio server: ```bash codex mcp add tares --url http://localhost:8788/mcp ``` For a remote, secured instance, Codex reads the credential from an environment variable: ```bash export TARES_API_KEY= codex mcp add tares --url https:///mcp \ --bearer-token-env-var TARES_API_KEY ``` Add to `~/.cursor/mcp.json` (global) or `.cursor/mcp.json` (per-project), then approve the server under Settings → MCP: ```json filename="~/.cursor/mcp.json" { "mcpServers": { "tares": { "url": "http://localhost:8788/mcp" } } } ``` Add to `claude_desktop_config.json` (Settings → Developer → Edit Config), then restart Claude Desktop: ```json filename="claude_desktop_config.json" { "mcpServers": { "tares": { "url": "http://localhost:8788/mcp" } } } ``` Any MCP client that supports remote servers can connect with three facts: - **Transport**: streamable HTTP - **URL**: your endpoint from [step 1](#1-get-your-endpoint) - **Auth**: none on an open local instance; `Authorization: Bearer ` on a [secured](#authentication) one Most accept the generic shape: ```json filename=".mcp.json" { "mcpServers": { "tares": { "type": "http", "url": "http://localhost:8788/mcp", "headers": { "Authorization": "Bearer " } } } } ``` (Drop the `headers` line on an open local instance.) Clients with their own config file or field names: | Client | Config file | Difference from the generic shape | |---|---|---| | VS Code (Copilot) | `.vscode/mcp.json` | Top-level key is `servers`; select the server in the Copilot Chat Agent view | | Windsurf | `~/.codeium/windsurf/mcp_config.json` | `serverUrl` instead of `url`; press Refresh in the MCP panel | | Cline | `cline_mcp_settings.json` | `"type": "streamableHttp"` | | Zed | `settings.json` | Top-level key is `context_servers`, with `"source": "custom"` | | Gemini CLI | `~/.gemini/settings.json` | `httpUrl` instead of `url` | Clients that only support stdio servers have two options: the native [stdio transport](#transports) (the `tares` package installed where the agent runs), or bridging to the HTTP endpoint with `npx mcp-remote http://localhost:8788/mcp` as the stdio command. ## 3. Verify Ask your client: > Use tares: what are you ingesting right now? The client should call `catalog_list` and answer with your sources, triggers, and projects. Running the [demo](/tares/quickstart)? Ask *"what happened to api-server in the last 15 minutes?"* and it answers from the correlated timeline. In the console, **Reads** lists each read as it happens, tagged `client = mcp`. ## Authentication On a [secured instance](/tares/deployment#authentication) (`tares up --auth`, every server and Tares Cloud instance), the MCP surface requires a credential. Prefer a scoped [API key](/tares/deployment#api-keys) with the `read` scope over the root token: - **HTTP**: the client sends `Authorization: Bearer `; the server forwards it to the daemon. Each client tab above shows where the header goes. - **stdio**: set `TARES_AUTH_TOKEN=` in `tares-mcp`'s environment. For an agent that should work inside one project only, use a [project key](/tares/deployment#project-keys) instead: it reads that project and records findings in it, and nothing else. On an open instance (plain `tares up`), no credential is needed. ## Transports The Tares MCP server supports two transports: - **streamable-http**: the MCP server runs as a network endpoint and the client connects over HTTP. This is the default path used above, and the only one for remote instances. - **stdio**: the client spawns `tares-mcp` as a subprocess; it proxies to the daemon at `TARESD_URL`. Use it for an agent on the same machine as the daemon when you'd rather not run the HTTP server. `tares-mcp` is installed with the `tares` package. The stdio shape for clients that take a config object: ```json { "mcpServers": { "tares": { "command": "tares-mcp", "env": { "TARESD_URL": "http://localhost:8787", "TARES_AUTH_TOKEN": "" } } } } ``` Or with the Claude Code CLI: ```bash claude mcp add tares \ --env TARESD_URL=http://localhost:8787 \ -- tares-mcp ``` ## Tools The MCP server exposes the following tools. A key's [scope](/tares/deployment#api-keys) determines which succeed: a `read` key gets the read surface; writing (ingest, source management) needs the matching scope. | tool | kind | description | |---|---|---| | `read` | read | a correlated, time-ordered timeline across **all** sources matching a `{label: value}` selector (strict AND); `project` or `sources` narrows it | | `catalog_list` | read | list sources, triggers, and projects | | `catalog_describe` | read | one object's schema, entities, freshness, lineage, and sample events | | `list_sources` | read | sources with their config and live health | | `list_connectors` | read | connector types and their fields | | `create_trigger` | write | create a trigger over named `sources`, with optional `filters`, `key_field` and `project` | | `update_trigger` | write | change an existing trigger's sources, filters, key field, condition, emit and cooldown, or move it to another `project` | | `remember` | write | write an observation to the agent-memory source | | `subscribe` | write | register a webhook to be pushed when a trigger fires | | `list_projects` | project | the projects you can work in; with a project key, its one project | | `join_project` | project | subscribe a webhook to every trigger of the project, triggers added later included | | `stats` | project | counts per value of a label over the project's sources, this window against the one before | | `list_skills` / `get_skill` | project | the project's skills, and one skill's instructions | | `list_findings` | project | the findings recorded in the project, Tares agents' and outside agents', newest first | | `record_finding` | project | record a finding on an entity, under the key's name, with an optional `headline` and `next_step` | | `project_timeline` | project | what happened in the project lately, as in its Activity view | | `discover_source` | setup | introspect an upstream and return a proposed source config | | `discover_docker` | setup | scan the local Docker environment for sources | | `test_source` | setup | dry-run a source config without creating it | | `create_source` | setup | create a source (ingestion starts immediately) | A typical agent flow: `read` any entity on the fly; or `catalog_list` / `catalog_describe` to learn what's there, `read` with `sources` to look at just the ones that matter, `create_trigger` to be woken when it happens again, and `remember` to write back what it found. `create_trigger`, `update_trigger` and `create_source` take an optional `project` (an id or a name); left out, the object goes to the Default project. See [Projects](/tares/projects). The tools of kind **project** work inside one project. With a [project key](#authentication) the project is implied; otherwise pass `project` (an id or a name), which may be left out while the instance has only one project. See [Connect an outside agent to a project](/tares/guides/outside-agent). ## Set up sources with an agent The setup tools make source configuration conversational: the agent does what you would do in the console form, against the same validation: > Use tares to ingest the `orders` table from my Postgres, keyed by `tenant_id`. 1. `discover_source`: introspects the upstream from partial config and returns a proposed source (for Postgres: reads `information_schema` to pick the cursor and key columns). `discover_docker` scans the local Docker environment and proposes one source per running container. 2. `test_source`: dry-runs the config: fetches sample events without creating anything, so the agent (and you) can check the labels and key before committing. 3. `create_source`: creates it; ingestion starts immediately, no restart. Every [connector page](/tares/connectors) shows the agent prompt next to the console and YAML forms. Because all paths normalize to the same stored config, a source an agent creates exports to the same [catalog YAML](/tares/concepts#the-catalog) as one you click together. ## In-app agent The console includes [**Ask**](/tares/ask), the same idea hosted inside Tares: a chat loop on the daemon with the read tools, for exploring or debugging your data without wiring up an external client. Open it under **Ask** in the console, or summon it anywhere with ⌘K. --- # AI resources This page is written for coding assistants (Claude Code, Codex, Cursor, or an agent of your own) that are asked to set up, configure, or explain Tares. Humans are welcome too. ## Markdown endpoints Every Tares docs page is available as plain Markdown. | Endpoint | What it is | |---|---| | `https://docs.glassflow.ai/tares/llms.txt` | The Tares index: every page with a one-line description, in reading order. Start here. | | `https://docs.glassflow.ai/tares/llms-full.txt` | All Tares pages in one file. Large; use it only when one or two pages are not enough. | | Any page URL + `.md` | The page as Markdown, for example `https://docs.glassflow.ai/tares/connectors/prometheus.md`. The docs root is `/tares.md`. | | `https://docs.glassflow.ai/llms.txt` | The whole GlassFlow index, other products included. Not needed for Tares work. | Content negotiation with an `Accept: text/markdown` header is not supported; the server answers with HTML. Use the `.md` suffix. ## Retrieval order 1. Fetch `/tares/llms.txt`. 2. Pick the one or two pages that match the task from the router below and fetch their `.md` URLs. 3. Fetch `/tares/llms-full.txt` only if the answer spans many pages. Do not scrape the rendered HTML pages; the Markdown is the same content without the navigation. ## Task router | The user asks | Read first | Then | |---|---|---| | What Tares is, what it is for | [Introduction](/tares.md) | [Concepts](/tares/concepts.md) | | Install it and get it running | [Quickstart](/tares/quickstart.md) | [CLI reference](/tares/cli.md) | | Add a source of type X | [Connectors](/tares/connectors.md) | The connector's own page, for example [Prometheus](/tares/connectors/prometheus.md), [OTLP](/tares/connectors/otlp.md), [Docker logs](/tares/connectors/docker-logs.md), [GitHub](/tares/connectors/github.md), [Webhook](/tares/connectors/webhook.md) | | Connect Claude Code, Codex, Cursor or another client over MCP | [Connecting agents](/tares/agents.md) | [Quickstart, Connect an agent](/tares/quickstart.md) | | Build an AI SRE | [Build an AI SRE](/tares/guides/ai-sre.md) | [Tares agents](/tares/tares-agents.md) | | Receive dispatches, write an agent of their own | [Watch with triggers](/tares/guides/triggers.md) | [The HTTP API in five minutes](/tares/guides/http-api.md) | | Tares agents, findings, what an agent writes back | [Tares agents](/tares/tares-agents.md) | [Concepts, Findings](/tares/concepts.md) | | Give a Tares agent external tools (MCP servers) | [Tares agents, External tools](/tares/tares-agents.md) | [Connecting agents](/tares/agents.md) | | Deploy on a server, Docker, TLS, auth | [Deployment](/tares/deployment.md) | [Self-host on a server](/tares/guides/self-host.md) | | The HTTP API | [The HTTP API in five minutes](/tares/guides/http-api.md) | [Connectors](/tares/connectors.md) for `POST /api/sources` bodies | | Ready-made setups | [Projects](/tares/projects.md) | The matching guide | | Group triggers and agents, see what happened in one place | [Projects](/tares/projects.md) | [Concepts, Projects](/tares/concepts.md) | | Give a project's agents shared instructions (SKILL.md) | [Skills](/tares/skills.md) | [Tares agents](/tares/tares-agents.md) | | Let this agent work inside one project (project key) | [Connect an outside agent to a project](/tares/guides/outside-agent.md) | [Projects, Outside agents](/tares/projects.md) | | Is it working, what next | `tares status` in the [CLI reference](/tares/cli.md) | [Quickstart](/tares/quickstart.md) | ## Agent instructions Paste this into a system prompt or a project instruction file: ```text When the user asks about Tares (docs.glassflow.ai/tares): - Answer from the docs. Fetch https://docs.glassflow.ai/tares/llms.txt first, then the one or two pages that match, as Markdown (append .md to the page URL). Cite the page URL you used. - For POST /api/sources bodies, use the JSON shape and keys from that connector's page under /tares/connectors/. Never invent a connector config key; if the page does not list it, say so. - Commands and flags come from /tares/cli.md and the quickstart. Do not invent flags. - Secrets (GITHUB_TOKEN, ANTHROPIC_API_KEY) come from environment variables; never ask the user to paste one into the chat. - When the user wants Tares installed or connected to this agent, use the tares skill: run `npx skills add glassflow/tares --skill tares`, then follow it. It installs Tares, starts it, adds a first source, connects this agent over MCP and shows one read. - If the running instance disagrees with the docs, trust the instance (`tares status`, GET /health) and say that the docs may be behind. ``` ## Guardrails - Do not invent CLI flags, API routes, connector keys or MCP tool names. Everything real is in the pages above. - Treat `llms.txt` as a map, not as an answer. - Never place a credential in a command line, a config file you show, or a chat message. - Tares is read-only for agents by default. Do not describe write actions that are not on the Tares agents page. --- # Tares agents A **Tares agent** is a prompt attached to a [trigger](/tares/guides/triggers). When the trigger fires, the agent is handed the correlated timeline for the affected entity, reads it (and can read a wider window or another entity), and writes its conclusion back into Tares as a **finding** on that entity's timeline. It's a real agent (it reasons with an LLM), configured *inside* Tares. That distinguishes it from a **connected agent**, an external agent you wire up over [MCP](/tares/agents) or a webhook, which lives in your own infrastructure. Both kinds are woken by the same trigger; what a Tares agent may do is deliberately narrower ([the boundary](/tares/tares-agents/tools)). Because a finding is also stored as an event on the entity's timeline, the next agent to `read` that entity (including your own connected agent) receives prior Tares conclusions as part of the evidence. Tares doesn't replace your agent; it gives it a head start. ## Create one In the console, open a project's **Advanced setup** and click **+** next to **Agents**, or open a trigger there and choose **Add a Tares agent**. A [guided setup](/tares/build) plans agents too. You supply the **prompt**, optionally seeded from a preset, and may pin a **provider** and a **model** (see [Model providers](/tares/model-providers)); everything else is fixed (see [runtime and guardrails](#runtime-and-guardrails)). An agent belongs to the instance, and any number of [projects](/tares/projects) can use it. Each project wires it its own way: which trigger wakes it there, whether it is on there, and whom it hands off to. A run belongs to the project whose wiring started it, so an agent's page inside a project shows that project's wiring and that project's runs. The agent may use any MCP server and hand off to any agent on the instance. A Tares agent is **on** in a project when a trigger of that project wakes it. New agents start **off**; enable it to run on the next firing. It is listed under **Agents** on each project that uses it, on its trigger's page, under **All resources** with the projects that use it, and under **Firings** wherever it was woken. ### No trigger of its own The **trigger** field has a first choice, **No trigger: only a handoff starts it**. Such an agent never wakes on its own; it runs only when another agent [hands off](/tares/tares-agents/handoffs) to it. Its page says "Only a handoff from triage starts it" with an **on handoff** badge, and has no **Enable** button (enabling one is refused with 409). You can pick a trigger, change it, or clear it again at any time under **Edit**. Deleting a trigger leaves the agents it woke in place, without a trigger of their own. ### In the catalog An agent is a catalog object, so it exports/imports with everything else and can be shipped in a seed catalog: Optional fields: `trigger` (leave it out for an agent only a handoff starts), `provider` (a provider id from Settings; omit for the instance default) and `model` (a model id that provider serves; omit for its default), `slack_channel` (a channel ID the workspace bot posts to), `webhook_url` / `webhook_token` (the [write-back webhook](/tares/tares-agents/delivery); the token, like `slack_webhook`, exports only with secrets included), `mcp_servers` (names from the [MCP servers registry](/tares/tares-agents/tools#external-tools-mcp) this agent may use), and `handoffs` (the agents that take over after a finding, see [Hand off to another agent](/tares/tares-agents/handoffs)), and `concludes` and `verdicts` (see [How a run ends](/tares/tares-agents/how-a-run-ends)). The registry itself is a catalog object too: a top-level `mcp_servers:` list of `{name, url, auth_header, auth_value}`, with `auth_value` secret-gated on export. ```yaml agents: - name: incident-first-look project: Default # optional; the project that made it trigger: incident # the trigger that wakes it enabled: true # on in its project prompt: | You are an SRE taking the first look when an alert fires on this service. You are handed the correlated timeline: the firing alert plus the signals behind it and the request logs. Produce a tight incident note: what is failing and since when, the most likely cause tied to specific evidence lines, and a suggested next action. Do not speculate beyond the evidence. ``` The bundled [demo](/tares/guides/ai-sre) ships exactly this agent, so `tares up` closes the loop with nothing to deploy. ## Watch it run Fire the agent's trigger (in the demo: inject a fault) and follow it: 1. The conclusion shows on the project's [Overview](/tares/projects#overview) under **What the agents found**, with its headline, summary and next step. For debugging, the firing is on the trigger's page, under **Firings**, and in Advanced setup's [Activity](/tares/projects#activity), with the run it woke nested under it. 2. The run (status, rounds, duration, errors) is under the agent's page → **Runs & findings**. A run that concludes "inconclusive" or fails is recorded here and never pollutes a timeline. For an agent that concludes, an **outcome** column shows how each run ended: its verdict, **no verdict**, or **no finding**, with the headline beside it; an open run shows the same above its finding. The list can be filtered to successful or failed runs only, and **Show more** pages past the first fifty (`GET /api/agents/builtin/{name}/runs?status=ok&offset=50`). 3. The finding appears in **Explore** on the entity's timeline, alongside the evidence it was drawn from. ![A Tares agent's page: the prompt, the run, and the incident note it wrote back](/assets/tares-agent-finding.png) The [Build an AI SRE](/tares/guides/ai-sre) guide walks this exact loop end to end. ## Findings An agent's conclusion is written to the built-in **`findings`** source (auto-provisioned on the first finding), keyed to the entity the trigger fired on. Because it's treated as an event, it lands on that entity's timeline and is returned by `read` like everything else. Each finding carries the agent, the trigger, the firing, and a hash of the prompt that produced it. ## The model provider A Tares agent runs on a [model provider](/tares/model-providers) the instance holds: Anthropic, OpenAI, or an OpenAI-compatible endpoint. Provide one two ways: - **`ANTHROPIC_API_KEY`** (or `OPENAI_API_KEY`) in the daemon's environment, or - the console → **Settings → Model providers**. A provider saved in the console wins over the environment. Without one an agent can be created but not enabled; if it's already enabled, each firing is logged as "no model provider" and no finding is written. The same providers power the in-app [Ask](/tares/ask) assistant, which runs on the default. ## Runtime and guardrails Only the prompt is yours to configure per agent; the runtime is fixed so a data-plane feature doesn't become an agent builder. The numbers: - **Provider and model**: pick a [provider](/tares/model-providers) and a model it lists, or leave both on the default to follow the instance (`TARES_AGENT_MODEL`, `claude-sonnet-4-6` unless set, on the default provider). Catalog YAML accepts any model id, so a model newer than the picker works without an upgrade. - **Budget per run**: `max_rounds` model rounds (1 to 24; set under **Advanced** on the agent form or as `max_rounds` in catalog YAML), 2,048 tokens per call. Unset, the default is 6, or 12 once the agent uses external MCP servers, since a run that reads a diff or a file and writes back needs more than the read-and-conclude budget. Every run records the cap it was held to and shows `rounds/max`. When the budget runs out mid-investigation the model gets one final call with tools disabled to conclude from what it has; if it still cannot, the run ends **`exhausted`**, keeps the last text as a partial note, and says to raise max rounds. - **Cooldown**: the agent runs at most once per the trigger's cooldown per entity. - **Daily cap**: at most 50 runs per agent per day (`TARES_AGENT_DAILY_CAP`), so a trigger in a hot loop can't run up an unbounded API bill. - **Handoff chains**: at most three handoffs in a row; see [Hand off to another agent](/tares/tares-agents/handoffs). - **No self-feeding**: an agent can't be woken by a trigger that watches the `findings` source it writes to, unless the trigger is filtered to another agent's findings (`agent eq `); Tares rejects that wiring at definition time (it would fire itself forever). ## More on Tares agents - [Handoffs](/tares/tares-agents/handoffs): pass a finding to another agent by verdict. - [How a run ends](/tares/tares-agents/how-a-run-ends): the `conclude` tool, and the verdicts an agent may give. - [Tools and MCP servers](/tares/tares-agents/tools): what an agent can call, and the read-only boundary. - [Skills](/tares/tares-agents/skills): instructions agents load when a task calls for them. - [Deliver findings](/tares/tares-agents/delivery): Slack channels and write-back webhooks. ## Related - [Build an AI SRE](/tares/guides/ai-sre): the full loop, end to end, on a demo system. - [Triggers](/tares/guides/triggers): the condition that wakes an agent. - [Connecting agents (MCP)](/tares/agents): external agents that read on demand and can act. --- # How a run ends An agent that ends with a conclusion (see [below](#set-it-on-the-agent)) gets the **`conclude`** tool, to end a run on purpose: `no_op` when there is nothing to report (no finding is recorded), or a finding with a `verdict` about a named entity. With a finding it also gives: - **`headline`**: one line of up to 100 characters, what was found in the reader's terms. - **`next_step`**: up to 300 characters, what a person should do; empty when nothing needs doing. These are what the project's [Overview](/tares/projects#overview) shows on each card, and agents are told to give both. For a run without them, Tares takes the headline from the note's heading, bold lead or first sentence, and the next step from the text after "Next step:", "Next:" or "Recommendation:". See [Watch, then escalate](/tares/guides/watch-then-escalate). ## Set it on the agent The agent form's **How it ends** section sets how a run finishes: - **Ends every run with a conclusion** (`concludes: true`): the agent always gets the `conclude` tool, whatever its prompt says, and Tares adds the instructions for it, so the prompt only describes the job. If a run stops without concluding, Tares asks once more with `conclude` as the only choice. Off, the agent's last message is its finding, with no verdict. An agent whose prompt names `conclude` still gets the tool, as before; tick the box to make it required. - **Verdicts it can give** (`verdicts`): your own words, each with when to give it. Up to 10, each one word (letters, digits, dashes), listed once, and not `no_op` (nothing to report is always possible). With a list, the tool accepts only those words and tells the model what each means, a finding must carry one, and an off-list word or a missing verdict goes back to the agent to fix within the same run. Without a list, a finding can carry any verdict, or none. ```yaml agents: - name: triage trigger: watch-web concludes: true verdicts: - { verdict: investigate, when: one entity looks like a problem and needs a closer look } prompt: | ... ``` The **Triage (on a schedule)** preset comes with `investigate`; **Root cause after a handoff** with `rca` (you found what is failing and why) and `resolved` (it was noise, or it is already over). The agent's summary shows how it ends, and its [handoffs](/tares/tares-agents/handoffs) key off these words. --- # Deliver findings Every finding lands on the entity's timeline; the agent's **Deliver findings** options also send it where people and systems already look. Each is a toggled row on the agent's form: - **Slack channel**: the workspace bot posts the full finding to a channel picked from the bot's own membership list (connect the bot under **Settings**). The same bot serves [trigger subscriptions](/tares/guides/triggers), where deliveries are also retried and recorded in the delivery ledger. - **Write-back webhook**: every finding is POSTed as JSON to your own automation, with an optional bearer token sent as an `Authorization` header. The body carries the finding and its run metadata, never a key or token: ```json { "event": "finding", "agent": "incident-first-look", "trigger": "incident", "key": "api-server", "finding": "…the incident note…", "run_id": "run_9f2c81d4a6b3", "dispatch_id": "c0f35f8210…", "model": "claude-sonnet-4-6", "rounds": 2, "tool_calls": 3, "started_at": "2026-08-14T12:01:03+00:00", "finished_at": "2026-08-14T12:01:35+00:00", "duration_s": 32.6, "prompt_hash": "1c9f2d" } ``` Transient failures are retried; a delivery failing never loses the finding, which is already stored. Delivering a finding is not acting: the [boundary](/tares/tares-agents/tools) stands. - **Slack incoming webhook**: the older per-agent webhook URL still works but is neither retried nor logged, and is used only when no channel is set; prefer the channel. --- # Handoffs An agent can pass its finding to another agent, by verdict. A cheap agent that watches often can hand the one entity that needs a closer look to a thorough agent, without a second trigger in between. A **handoff** is three values: a **verdict**, the **agent** that takes over, and a **cooldown**. When a run ends with a finding whose verdict matches (case does not matter), Tares starts that agent on the entity the finding is about. The agent is handed the finding, after a line such as `Handed off by triage with verdict "investigate" on service=checkout.` It fetches any further evidence itself with its tools. A verdict comes from the `conclude` tool, so the handing agent must end its runs with a conclusion (see [How a run ends](/tares/tares-agents/how-a-run-ends)). In the console, the agent form has a **When it concludes** section: **Add a handoff**, then a verdict, the agent that takes over, and a cooldown (`30m` by default). The verdict field offers the agent's own [verdicts](/tares/tares-agents/how-a-run-ends) as a dropdown and also takes any word you type; when a handoff names a word the agent never gives, the form says so, since that handoff would never run. On the project's page, each agent shows its handoffs in both directions. Handoffs are the project's wiring: the same agent can hand off differently in two projects. In the catalog and on the API (`POST` and `PUT /api/agents/builtin`), `handoffs` is a list: ```yaml agents: - name: triage trigger: watch-web concludes: true verdicts: - { verdict: investigate, when: one entity looks like a problem and needs a closer look } prompt: | ... handoffs: - { verdict: investigate, agent: rca, cooldown: 30m } - name: rca # no trigger: it runs only when handed off prompt: | ... ``` The rules: - **Any other agent.** The target is any other agent on the instance; the run belongs to the project whose wiring holds the handoff. At most 10 handoffs per agent, and each verdict and agent pair once. - **The target runs whether or not it is on for its own trigger.** Give it no trigger when it should only run when handed off. - **Cooldown.** At most one handoff from this agent to that agent per entity within the cooldown. A handoff inside the cooldown starts no run; the finishing run's results say `handoff to rca skipped: cooldown`. - **Chains stop at depth 3.** An agent that was handed off to can hand off in turn. After three handoffs in a row, the next is recorded as a **capped** run with the error `handoff chain stopped at depth 3`. - **Nothing is dropped silently.** When the target is already running for that entity, or has hit its daily cap or budget, the handoff is recorded as a capped run with the reason. - **Deleting the target removes the handoffs that point to it.** The delete response lists the agents it was removed from under `handoffs_removed_from`. - An update that leaves `handoffs` out keeps them; an empty list clears them. A handed-off run is recorded with `woken_by: handoff` and the finishing run as its parent. On the project's [Activity](/tares/projects#activity) it sits under the run that handed off, so a triage finding and the root cause it led to read as one thread. A [trigger over the `findings` source](/tares/guides/watch-then-escalate#hand-off-to-the-main-agent) still wakes an agent as before; handoffs are the simpler way to chain two agents. --- # Skills A **skill** is a set of instructions for your agents: a runbook for one kind of incident, the checklist for a release, the house style for incident notes. A skill lives on the instance and [projects](/tares/projects) use it: any number of projects can use the same skill, and editing it changes it for all of them. Every Tares agent in a project that uses a skill sees its name and description, and loads the full text only when the task in front of it matches. You write a procedure once and keep each agent's prompt short. A skill has three parts: | Part | Rules | |---|---| | **name** | 1 to 64 lowercase letters, digits and dashes, e.g. `checkout-triage`. Unique on the instance; the agent loads the skill by this name. | | **description** | One paragraph, up to 1,024 characters. The agent reads it to decide when to load the skill, so say what the skill covers and when to use it. | | **body** | Markdown, up to 64 KB. The instructions themselves. | ## How agents use skills When the projects a run is for use skills, Tares adds two things to the run: 1. After the agent's own prompt, a section **Skills available in this project** lists every skill as `- name: description`, followed by one line telling the agent to load a skill with the `skill` tool before relying on it, and only when the task matches its description. 2. A **`skill`** tool that takes a `name` and returns that skill's body. An unknown name returns an error that lists the skill names, so the agent can correct itself. The agent pays for a body only when it loads one; the list costs one line per skill. A project with no skills leaves the prompt and tools exactly as they were. Each run records the skills it loaded, in order. They show as chips in the runs table on the agent and project pages and in the project's [Activity](/tares/projects#activity), and as `skills` on each run in the API. An agent sees the skills of the projects its run is for (the projects whose wiring started it), not every skill on the instance. [Ask](/tares/ask) does not use skills. ## Write a skill A skill is written as a `SKILL.md` file: YAML front matter with `name` and `description` between two `---` lines, then the body. Other front matter keys are ignored. ```markdown --- name: checkout-triage description: How to triage an incident on the checkout service. Use when checkout returns 5xx errors or its latency alert fires. --- # Checkout triage 1. Read the last 30 minutes of the checkout service with `read`, then run `stats` by `status_code` to see which responses moved. 2. Check for a deploy of checkout or payments in the hour before the first error. 3. If the errors come from the payment provider (status 502 from `/pay`), say so and stop: that is the provider's incident, not ours. 4. End the note with the owning team: checkout is #team-payments. ``` Good descriptions name the situation, not the content: "Use when checkout returns 5xx errors" tells the agent when to load the skill; "Checkout knowledge" does not. ## In the console Open the project and click **Skills** in its navigation. The overview shows each skill's name, description, size, when it was last updated, and the agents of the project that loaded it in the last 7 days. Click a skill to see its body and which agents loaded it; **+** next to **Skills** adds one. - **New skill** opens a form with name, description and body, and a preview of the body as it renders. A name already on the instance is refused: use that skill instead. - **Use one already on Tares** picks a skill another project uses, by name from a list, and this project uses it too. - **Upload SKILL.md** reads a file in the format above. A skill with the same name is replaced, in every project that uses it. - **Edit** changes the description and body for every project that uses the skill; the name stays. - **Remove** takes the skill out of this project. Its agents stop seeing it from their next run. The skill is deleted only when no other project uses it. All resources in the sidebar lists every skill with the projects that use it. A skill that breaks a rule (a name with capitals, a description with a blank line in it, an empty body) is refused with a message that says which rule. ## On the API `{id}` is the project id from `GET /api/projects`. | Call | Does | |---|---| | `GET /api/skills` | every skill on the instance, without bodies: `name`, `description`, and `used_by`, the projects that use it | | `GET /api/projects/{id}/skills` | the project's skills without their bodies: `name`, `description`, `updated_at`, `size` (bytes), and `loaded_by` (the project's agents that loaded it in the last 7 days) | | `GET /api/projects/{id}/skills/{name}` | one skill: `name`, `description`, `body`, `updated_at` | | `POST /api/projects/{id}/skills` `{name, description, body}` | create a skill; 409 when a skill with that name is already on the instance | | `POST /api/projects/{id}/skills/{name}/use` | the project uses a skill already on the instance; 404 when there is none by that name | | `PUT /api/projects/{id}/skills/{name}` `{description?, body?}` | change the description, the body, or both, for every project that uses it; a field left out keeps its value | | `DELETE /api/projects/{id}/skills/{name}` | the project stops using the skill; it is deleted when no other project uses it. The response has `removed`, `deleted` (the name, or `null` when kept) and `kept_for`, the projects still using it | | `POST /api/projects/{id}/skills/upload` | the raw request body is a `SKILL.md`; creates the skill or replaces the one with the same name (in every project that uses it), has the project use it, and returns it with `created: true` or `false` | Upload a file: ```bash curl -s -XPOST localhost:8787/api/projects/uc_1a2b3c/skills/upload \ -H 'content-type: text/markdown' --data-binary @SKILL.md ``` A missing or invalid field answers 400 with a plain message, such as `the front matter has no description:`. Reading skills needs the `read` [scope](/tares/deployment#api-keys); creating, changing or deleting one needs `admin`, since a skill changes what the project's agents do. ## In the catalog Skills export and import with the catalog, under a top-level `skills:` section, each skill once. `project` names the project that made it (a skill with no `project` goes to the Default project) and `used_by` lists the other projects that use it. ```yaml skills: - project: checkout watch name: checkout-triage description: How to triage an incident on the checkout service. Use when checkout returns 5xx errors or its latency alert fires. body: | # Checkout triage ... used_by: [payments watch] ``` Deleting a project deletes the skills no other project uses; a skill another project uses stays. A project template can also plan skills, which it creates with the rest of the project. Skills are plain instructions, not tools. What an agent can do is still set by its [tools and MCP servers](/tares/tares-agents/tools); a skill can tell it how to use them. ## Related - [Projects](/tares/projects): the projects that use skills. - [Tares agents](/tares/tares-agents): prompts, tools and guardrails. --- # Tools and MCP servers By default a Tares agent has two tools, both routed through the same Tares read path and both covering the sources of the projects its run is for, unless it names others with `sources`: - **`read`**: one correlated timeline for an entity. - **`stats`**: counts per value of one label, this window against the window before, largest change first. For a busy stream where reading lines would only show the latest few. When a project the run is for has [skills](/tares/tares-agents/skills), the agent also gets the **`skill`** tool, which loads one skill's instructions by name. Each run records the skills it loaded. The agent can also end its runs with the [`conclude`](/tares/tares-agents/how-a-run-ends) tool. ## The boundary By default a Tares agent **reads and concludes; it does not act** (no restarting, deploying, or ticketing). Connecting [external tools](#external-tools-mcp) moves that boundary for that one agent: tools from an MCP server can act on whatever the server exposes, so you decide per agent which servers it may touch, and every run records what it actually called. ## External tools (MCP) An agent can use tools from **external MCP servers** alongside its built-in reads. Two steps: 1. **Register the server** under **Settings → MCP servers** in a project's Advanced setup; any project's agents can then use it: a name, a streamable-HTTP URL, and an optional auth header (the value is stored as a secret, never shown again; stdio servers are not supported). The auth value can also point at a stored GitHub credential (`credential:github/`, see [Settings](/tares/deployment#settings)), so rotating the token in one place rotates the server too. Under **Advanced: extra headers** you can add non-secret headers sent with every request; GitHub's hosted MCP server takes `X-MCP-Toolsets: repos,pull_requests` to limit the tools it offers and `X-MCP-Readonly: true` for a read-only agent. **Test** connects live and lists the server's tools. 2. **Opt the agent in** on its form, under **External tools**: pick any registered server; each selection shows as a removable tag. At run time, the selected servers' tools are offered to the model alongside `read` and `stats`, prefixed by server name (`github__create_issue`). Guardrails: - A tool result is capped at 8,000 characters, so a verbose server cannot crowd out the evidence. - A server that is down when the run starts is skipped and logged; the run continues with the tools that remain, and a failed call is returned to the model as an error to reason about. - Each run records the external tools it called, shown on the run under **Runs & findings**. That is the audit trail for what an agent touched outside Tares. --- # Ask **Ask** is the assistant built into the console: type a question about your data and it investigates with the same read API everything else uses, showing each tool call as it works. Open it under **Ask** in the sidebar, or summon it from anywhere with **⌘K**. > Which service had the most errors in the last 24 hours, and what happened to it? ![Ask investigating a question: the tool calls it makes, and the verdict it reaches](/assets/tares-ask.png) Use it to check what's flowing, debug a source that looks off, or explore an instance you've just connected, without wiring up an external client first. ## What it can do Ask runs as a chat loop on the daemon (up to 10 tool rounds per question). Its tools are thin calls to the daemon's own read endpoints, so it sees exactly what the API exposes and nothing more: - **Explore the data**: list sources and connectors, describe any catalog object (schema, entities, freshness, samples), profile a source's fields, list entities, read recent events, list projects, and `read` a correlated timeline, across every source or only a project's. - **Debug something**: the same read tools answer "is anything not ingesting?", "what looks sparse?", "why is this label missing?" from live health and field coverage. - **Organize it**: two proposal tools (`propose_labels`, `propose_trigger`) draft catalog changes as cards you **Apply or skip**. A proposed trigger names its sources and, when you apply it from Ask, goes to the Default project. The proposals themselves change nothing; Apply goes through the same validated management APIs the console forms use. The empty state offers starter questions for each of the three. To set up a whole project from a goal instead of asking questions, use the [guided setup](/tares/build). ## What it needs A [model provider](/tares/model-providers) on the instance: `ANTHROPIC_API_KEY` in the daemon's environment, or one added in the console under **Settings → Model providers**. Ask runs on the instance's **default** provider, and the chat says which; the same providers power [Tares agents](/tares/tares-agents). The model is that provider's default: `TARES_AGENT_MODEL` (`claude-sonnet-4-6` unless set) on Anthropic. ## Ask vs your own agent Ask lives inside the console and reads this one instance. For an agent in your own workflow (Claude Code, Cursor, your own service) with the same read surface plus subscriptions, [connect it over MCP](/tares/agents). Both benefit from the [findings](/tares/concepts#findings) Tares agents leave on the timeline. --- # Model providers [Tares agents](/tares/tares-agents) and [Ask](/tares/ask) reason with a model. Which model, and whose, is a **provider** the instance holds under **Settings → Model providers**. An instance can hold several: one agent on Claude, another on GPT, a third on a model your own router serves. One provider is the **default**, what Ask and the guided setup run on and what an agent without a choice of its own uses. ## Kinds Kind What it is You supply Anthropic Claude models through the Anthropic API, or a gateway that speaks its format an API key; a base URL only for a [gateway](/tares/deployment#using-an-llm-gateway) OpenAI GPT models through the OpenAI API an API key; a base URL only for Azure or a proxy OpenAI-compatible endpoint anything that speaks OpenAI chat completions: LiteLLM, OpenRouter, Ollama, vLLM, Azure a name, the base URL (ending in `/v1`), and a key if the endpoint wants one
The add form has presets for LiteLLM, OpenRouter and Ollama that fill in the URL; **Other** takes any URL. Ollama and a local vLLM need no key: a base URL is enough. ## What the picker offers Saving a provider asks the endpoint which models it serves and stores the list, so the agent form offers exactly what your key can use. For a LiteLLM that is the aliases the key is allowed; for OpenRouter, Ollama and vLLM, everything they hold; for Anthropic and OpenAI, their current model lists, so a model newer than this release shows up without an upgrade. **Refresh models** on a provider's row re-reads it after the admin adds an alias or the key's allowance changes. When the endpoint cannot be read the row says why (the key was rejected, the endpoint did not answer, no models endpoint at that URL), the last list is kept, and the built-in list stands in for Anthropic and OpenAI. An agent can always name a model by hand: when a provider lists nothing, the model field on the agent form is free text. ## Per agent The agent form has a **provider** picker next to the **model** picker. Leave the provider on the cell default and the agent follows whatever the default is; pick one and the agent is pinned to it. Leave the model empty and the agent runs on that provider's default model: `TARES_AGENT_MODEL` on Anthropic, else the first model the provider lists. Every run records the provider and model it ran on, on the agent page and in the runs table, so the history stays readable after a provider is removed. An agent that names a provider this instance does not hold, because it came from a template or a catalog import, is not an error: it runs on the default, and the agent page says so until you pick a provider that exists here. In catalog YAML the fields are `provider` (the id from Settings: `anthropic`, `openai`, or the slug of an endpoint's name) and `model`. ## Cost The spend meter on the Overview prices each run from the model that answered: - **Anthropic and OpenAI models** from Tares's own price table, by model family. Cached input is counted the way each API reports it. - **A router that reports its own cost** wins over the table: OpenRouter in the reply, LiteLLM through its cost header when its cost tracking is on. Behind a router, the router's bill is the truth. - **A model with no price** (a local Ollama model, an alias Tares cannot read) records its tokens with no dollar figure, and the meter says how many calls were unpriced rather than showing zero. Spend is split by provider on the Overview once more than one has run. ## The environment The console values win over the environment. A deployment can still seed providers: ```bash ANTHROPIC_API_KEY=... # the Anthropic entry (ANTHROPIC_AUTH_TOKEN, ANTHROPIC_BASE_URL as before) OPENAI_API_KEY=... # an OpenAI entry OPENAI_BASE_URL=... # its base URL, for Azure or a proxy TARES_MODEL_PROVIDER=openai # the default, when none is chosen in the console TARES_AGENT_MODEL=... # the default model on the default provider ``` The Anthropic entry is the same key and gateway settings as before this release, under a new door: an instance configured through `ANTHROPIC_API_KEY` or the older Model access tab shows up as a configured Anthropic provider with nothing to redo. ## Small and local models Connecting a small open model is one provider entry. Whether it does the job is another matter. The agent loop hands the model tools over several rounds; a small model will sometimes write its tool call as JSON text instead of making a real call, mis-case a tool name, or answer with nothing. Tares runs a call written as text, matches a mis-cased name, and marks a run that ends with no conclusion and no tool call with a note to check that the model supports tool calling. An 8B-class model on a laptop (llama3.1:8b on Ollama) produces a correct finding on a simple incident in about twelve seconds, and on an empty result it will invent events. Treat that size as a way to try things out. For root-cause work on real data, use a hosted model or a 30B-class one and above. ## LiteLLM, two ways A LiteLLM can sit in front of Tares in either of its formats: - **As an [LLM gateway](/tares/deployment#using-an-llm-gateway)** in the Anthropic format: the base URL on the Anthropic entry, or `ANTHROPIC_BASE_URL`. Tares sends Claude model ids; the gateway maps them. This is unchanged from earlier releases. - **As an OpenAI-compatible provider**: LiteLLM's native format. The picker offers exactly the aliases the key may use, whatever sits behind them, and LiteLLM's cost figure lands on each run. The second is the natural one once an instance mixes models. --- # Guides End-to-end walkthroughs for common tasks. Each assumes a running instance (see the [Quickstart](/tares/quickstart)) and links to the relevant [reference](/tares/connectors) where useful. - [**Build an AI SRE**](/tares/guides/ai-sre): the end-to-end walkthrough. Stand up a monitored system, wire Tares, break it, and watch an agent diagnose it. - [**Keep shared code context current**](/tares/guides/shared-code-context): point Tares at your code repositories and a context repository; an agent keeps the pages current, as pull requests. - [**The HTTP API in five minutes**](/tares/guides/http-api): the whole loop with nothing but curl. - [**Watch with triggers**](/tares/guides/triggers): fire on a condition and push to a subscribed agent. - [**Self-host on a server**](/tares/guides/self-host): daemon, MCP server, and TLS with Docker Compose. Looking for connector setup? Each [connector page](/tares/connectors) shows its full setup three ways (agent, console, YAML). Connecting an MCP client lives in [Connecting agents](/tares/agents). --- # Build an AI SRE This guide builds an incident-response agent on Tares, end to end. By the last step you have a working AI SRE: when a service misbehaves, a trigger wakes an agent with one correlated timeline of metrics, logs, and alerts; the agent names the root cause and writes its conclusion back where the next investigation will find it. You also have an MCP client connected, so you can investigate the same evidence interactively. The split is: Tares does the data side (ingestion, per-service correlation, triggers, the MCP read surface); you bring the agent. The walkthrough uses a bundled demo system as the thing being monitored, so it runs on a laptop with nothing else prepared; the [last step](#point-it-at-your-real-systems) swaps the demo sources for your real ones. ```mermaid flowchart TD subgraph systems["your systems"] M[metrics] L[logs] D[deploys] C[config] end subgraph tares["Tares"] V["one timeline per service (sources labeled by service)"] end M --> V L --> V D --> V C --> V V -- "pull: the agent reads it" --> A["your agent"] V -- "push: a trigger fires and wakes it" --> A A -- "finding written back" --> V ``` ## Prerequisites - **Docker** running (for the demo system). - **uv** or **pipx** (to install Tares). - An **Anthropic API key**, so the built-in agent in step 4 can actually run. ### Stand up a system to monitor An SRE needs a production to watch. The demo stack stands in for yours: a small **api-server** (Prometheus metrics, request logs, and a fault switch you'll use to cause incidents), **Prometheus** scraping it and evaluating three alerting rules (`HighErrorRate`, `HighLatency`, `DependencyDown`), and a **traffic generator**. One compose file, no checkout: ```bash curl -O https://raw.githubusercontent.com/glassflow/tares/main/demo/docker-compose.yml docker compose up -d ``` Give it ~10 seconds, then confirm it's alive: ```bash curl -s localhost:8080/api/stats # {"ok": true, ...} curl -s 'localhost:9090/api/v1/query?query=up' # prometheus is scraping ``` ### Wire Tares to it Install Tares, then wire it to the stack one of two ways. They are separate paths, not two halves of one: the console path starts a plain `tares up` and does the rest from the browser; the catalog path starts Tares already seeded, and only seeds an empty instance. Pick one. ```bash uv tool install tares # or: pipx install tares ``` Start Tares and open the console: ```bash tares up ``` At [`http://127.0.0.1:8787`](http://127.0.0.1:8787) go to **Projects** and pick the **AI SRE demo** template (tagged demo). The setup page looks at what Docker is running and fills in the Prometheus URL, the api-server URL and the log container from the actual containers and their published ports; if the stack is not up yet, it shows the two commands from step 1 with copy buttons. Paste an Anthropic key on the same page (or set one under **Settings > Anthropic**); the built-in agent needs it. Click **Start**. Everything listed below is now in place, each object on its own page with a "part of project" badge, and the project page has a **Cause an incident** button for step 4. Read more in [Projects](/tares/projects). Download the demo catalog, export your key, and start Tares seeded with it: ```bash curl -O https://raw.githubusercontent.com/glassflow/tares/main/demo/catalog.demo.yaml export ANTHROPIC_API_KEY=sk-ant-… TARES_CATALOG=catalog.demo.yaml tares up ``` The catalog is imported on start, while the instance is still empty. Already ran `tares up` in this data directory? Start on a fresh one: `TARES_CATALOG=catalog.demo.yaml tares up --data-dir ~/tares-sre`. Either way, that one setup just created your entire AI SRE wiring; open the catalog file (or the project's **Sources**, **Triggers** and **Agents** on its page) side by side with the console and find each piece: - **Three sources**, all keyed by the same `service` label: [`demo_metrics`](/tares/connectors/prometheus) (5xx rate, p99, DB connections, dependency health, polled from Prometheus), [`demo_logs`](/tares/connectors/docker-logs) (the api-server container's request logs), and [`demo_alerts`](/tares/connectors/prometheus-alerts) (the alerts Prometheus's own rules fire). - **One timeline per service**, because all three carry `service`. Open **Explore**, pick `api-server`: metrics, logs, and alerts merged on one clock. This single read is what every agent in this guide works from. Flip to **What the agent gets** to see the exact text an agent gets. - **One trigger**, `incident`, watching the three sources keyed by `service`: it fires when an alert event arrives (`sum(alert_active) > 0` over 1m, per service). The division of labour is deliberate and it is the one you already run: **Prometheus keeps owning alerting**; Tares ingests what fired, correlates it with the evidence, and handles the waking. Nothing is re-thresholded. - **One Tares agent**, `incident-first-look`, subscribed to that trigger. Its whole definition is a prompt (read it under **Agents** in the project's Advanced setup): take the first look, tie the failure to specific evidence lines, suggest a next action. Run Tares before with other sources? Both paths work best on a fresh data directory (`--data-dir ~/tares-sre`). The project adopts an already imported demo catalog rather than duplicating it, and the catalog only seeds an empty instance. ### Connect your MCP client This is the pull half: you (or any agent you already use) investigating on demand. Start the MCP endpoint in a second shell and point your client at it: ```bash tares mcp # MCP endpoint on http://127.0.0.1:8788/mcp # e.g. Claude Code: claude mcp add --transport http tares http://localhost:8788/mcp ``` (Codex, Cursor, Claude Desktop, and others: [per-client setup](/tares/agents).) Then ask: > Use tares: what happened to api-server in the last 15 minutes? The client calls `read` with `{"service": "api-server"}` and answers from the correlated read. Right now the timeline is healthy traffic; the next step changes that. ### Cause an incident and watch the SRE work This is the push half. Break the api-server on purpose. On the project page, pick a scenario and click **Cause an incident**; or from a shell: ```bash curl -s -XPOST localhost:8080/demo/inject -H 'content-type: application/json' \ -d '{"scenario": "error_spike"}' ``` Within ~30 seconds (Prometheus's rules have a 15s `for:`, then Tares polls the alerts), the chain you built in step 2 runs on its own. Follow it in the console: 1. The 5xx rate climbs and **`HighErrorRate` fires**; the alert event lands in **Explore** next to the error logs and the metric that tripped it (the timeline turns red). 2. The **`incident` trigger fires** on the alert event. The firings are on the [trigger's page](http://127.0.0.1:8787/triggers/incident) and under **Firings**. 3. **`incident-first-look` wakes**, reads the correlated timeline, and **writes a finding** onto api-server's timeline: what broke, since when, the likely cause tied to evidence lines, and a next action. It appears on the project's [Overview](/tares/projects#overview) under **What the agents found**, with a headline and the next step; click it for the full note and how Tares got there. The same finding is on api-server's timeline in **Explore**. To debug, open **Setup → Advanced setup**: **Activity** shows the firing and the run it woke as one thread, and **Tares agents → incident-first-look → Runs & findings** has every run. That is the AI SRE working: nothing polled, nobody paged it, and the diagnosis is on the timeline before you've looked. Now ask your connected client the same question as before; it reads the evidence **and the finding**, so it starts from the previous conclusion instead of from scratch. That's the loop closing: every investigation leaves the timeline smarter. Try the other scenarios (`latency`, `dependency_outage`), and roll back with **Clear the fault** on the project page or `{"scenario": "clear"}` from the shell; the alerts resolve and a `resolved` event lands in the timeline. ### Point it at your real systems Everything the demo wired is ordinary configuration, so this step repeats what step 2 did, against your systems instead. Four moves. **1. Recreate the three demo sources against your stack.** In the console (**Sources → Add source**), or ask your connected agent to [set them up](/tares/agents#set-up-sources-with-an-agent). Keep everything keyed by the same `service` label: | signal | connector | what changes vs the demo | |---|---|---| | metrics | [`prometheus`](/tares/connectors/prometheus) | your real PromQL, with `service` read from the metric labels instead of a constant | | logs | [`docker_logs`](/tares/connectors/docker-logs) or [OTLP](/tares/connectors/otlp) | per-container, or your OpenTelemetry pipeline | | alerts | [`prometheus_alerts`](/tares/connectors/prometheus-alerts) or [`alertmanager`](/tares/connectors/alertmanager) | keep your alerting where it is; Tares ingests what fires | **2. Add the signal the demo lacks: deploys and config changes.** Most real root causes are a change, so this is the highest-value source you'll add. Create a [`webhook`](/tares/connectors/webhook) source (**Sources → Add source → webhook**) with a primary `service` label (read from the payload's `service` field), `event_type: deploy`, and a text template like `deploy {commit} by {author}: {message}`. Creating it gives you a stable ingest URL. Then one line in your CD pipeline, run on every deploy: ```bash curl -X POST https:///ingest/ \ -H 'content-type: application/json' \ -d '{"service": "checkout", "commit": "9f2c81d", "author": "dana", "message": "raise db pool size"}' ``` Each POST lands as a deploy event on that service's timeline, so the agent sees "deploy landed 14:02, errors started 14:04" the way you'd want to see it. A second webhook source with `event_type: config` covers config changes the same way. **3. Rebuild the triggers.** Triggers over your sources, keyed by `service`, with conditions for the incident shapes you care about: keep reacting to fired alerts as the demo does, or threshold the typed fields directly (`max(p99_ms) > 1000` for latency, an error-rate predicate for 5xx storms). **4. Pick who gets woken, per trigger.** - **A Tares agent**, like `incident-first-look`: edit the prompt for your stack, no infrastructure. - **Your own agent service**, over a webhook: Tares POSTs the timeline to your endpoint and the investigation starts with zero reads. The [delivery contract](/tares/guides/triggers#receive-dispatches) is three rules; the [AI SRE cookbook](https://github.com/glassflow/tares-cookbooks) is a complete working implementation (an Anthropic SDK agent that queries over MCP, gets woken by the trigger, and writes back), including a measured comparison against a tool-per-system agent if you want the numbers. - **A Slack channel**, so every firing and finding lands where your team already looks. ## Teardown ```bash curl -s -XPOST localhost:8080/demo/inject -H 'content-type: application/json' -d '{"scenario": "clear"}' docker compose down # from the directory with docker-compose.yml ``` Stop `tares up` and `tares mcp` with Ctrl-C. The demo objects live in the data directory you ran with; delete it (or the `--data-dir` you passed) for a clean slate. --- # Keep shared code context current Many teams keep a repository of shared context: what each service does, its interfaces, its configuration, how the pieces depend on each other. It goes stale the week after it is written. This guide sets up a project from the **Shared code context** template: Tares watches commits across your code repositories, and when something lands an agent reads the change and updates the context pages that cover it, opening a pull request for review. By the last step the context repository is kept current by the commits themselves. The split is the usual one: Tares does the data side (one commits source per repository, one timeline per repository, a trigger that fires when commits land) and runs the agent, which reads and writes GitHub through GitHub's hosted MCP server with the same token. Everything the project creates is an ordinary object on its own page; see [Projects](/tares/projects). ## Prerequisites - A running Tares (`uv tool install tares && tares up`, see the [Quickstart](/tares/quickstart)). - An **Anthropic API key**, set under **Settings > Anthropic** or as `ANTHROPIC_API_KEY`; the agent is a real agent. - A **GitHub fine-grained personal access token** (GitHub: Settings, Developer settings, Personal access tokens, Fine-grained tokens). Under Repository access pick the source repositories and the context repository. Repository permissions: | Permission | Access | Why | |---|---|---| | Contents | **Read and write** | read commits and diffs in the source repos; create branches and files in the context repo | | Pull requests | **Read and write** | open the pull request in the context repo | | Metadata | Read-only | added by GitHub automatically; lists the repos | GitHub starts every permission at Read-only when you add it. Check the access level of Contents and Pull requests before you generate the token: with Pull requests at Read-only the agent can push its branch but the pull request fails. ### GitHub access Open **Projects**, pick **Shared code context**, click **Set up**. Step 1 asks for the token: pick a credential you stored before or add one (a name and the token; the "?" next to the token field repeats the permission table). The token is stored once under **Settings > GitHub** and used by every source the project creates and by the agent when it writes. **Test** shows the GitHub login it belongs to. ### Source repositories Step 2 lists the repositories the token can see; tick the ones whose commits should feed the context (up to 50), or paste `owner/name` lines. Each row follows one branch, the default branch unless you change it. "Every commit to the branch" is what wakes the agent. ### Context repository Step 3 is the repository the agent maintains. Pick it (it cannot also be a source), the branch pull requests target, and the path where the pages live; leave the path empty for the root. As soon as the repository is picked, the page shows what is at that path, so you can see the layout you are handing over. Two page layouts: - **Keep the existing pages, update them in place** (the default). The agent lists the folder, reads the index and the page that covers the change, corrects what the change made outdated, and adds what is new, keeping the pages' structure and voice. It creates a page only when nothing existing covers the topic. This is the right choice for a repository that already has its own pages, one per topic. - **One page per source repository plus an index.** The agent keeps `.md` per source repository under the path, with a fixed section template, and a `README.md` index listing them. The right choice for a fresh folder. **How it writes:** open a pull request (recommended; a person merges) or commit straight to the branch. ### Trigger and agent Step 4 names the project, shows the trigger (every commit to the chosen branch, batched per repository, once per five minutes), lets you pick the model and the round budget (12 by default; reading diffs and pages, writing them and opening a pull request needs more than the plain 6), and previews exactly what Start creates: one commits source per repository, the trigger over them (one timeline per repository), GitHub's hosted MCP server registered with your credential (toolsets `repos,pull_requests`), and the agent. **First look on start** (on by default) runs the agent once per source repository over the last seven days of commits, so the context repository starts current instead of waiting for the next commit. Turn it off if the pages are already current or to save model spend. Click **Start**. You land on the project page. ### Watch a commit land Push a commit to one of the source repositories. Within a minute the source ingests it, the trigger fires for that repository, and the agent runs: 1. It calls `github__get_commit` for each commit in the attached timeline and reads the diff (and specific files with `github__get_file_contents` when a diff is truncated). 2. It decides whether the change alters anything a teammate or an agent in another repository must know: interfaces and contracts, configuration and environment variables, data schemas, runtime behaviour, dependencies between repositories, conventions. Refactors, tests, formatting and version bumps that change no behaviour are skipped. 3. It reads the covering page in the context repository, corrects statements the change made false first, then adds what is new, with the commit's short sha next to each claim, and writes it with `github__create_or_update_file` on a branch named `tares/context--`, then opens the pull request with `github__create_pull_request` (or commits to the branch, if you chose that). 4. It finishes with a **finding** on the repository's timeline: what changed in the context repository and the pull request link, or "no update needed" and why. On the project page, the Overview shows what the agent concluded under **What the agents found**: each card is one change, with the pull request or "no update needed". For debugging, **Setup → Advanced setup**: **Activity** shows every run with its status and result, and the agent under **Agents** lists its runs with rounds. Runs marked **first look** are the ones from Start. ## Living with it - The project page: **Setup** shows the context repository (repo, branch, path, page layout, how it writes) and each repository watched, with its state. In Advanced setup, the source repositories are under **Sources** with their status and recent events, the trigger, agent and MCP server in their own sections, and the change history under **Settings → Change history**. - **Edit** reopens the wizard with your values; add or remove repositories and save, the project creates or removes only those sources. **Pause** turns the trigger and agent off while the sources keep ingesting. **Delete** removes what it created. - The objects are ordinary: edit the agent's prompt on its own page if your team's pages need a different voice; the project keeps your version. - **Pull requests or direct commits.** Pull requests keep a person in the loop and are the default; switch to commits to the branch once you trust the agent for a repository. - **Many repositories.** One project takes up to 50 source repositories; each is one source polling every 60 seconds with the same token, and the trigger batches commits per repository so a busy day becomes one run per repository per five minutes. ## Related - [Projects](/tares/projects): the concept, ownership rules, catalog YAML and the API. - [Tares agents](/tares/tares-agents): rounds, findings, and external tools. - [Connectors: GitHub](/tares/connectors/github): the commits source, the stored credential and the file list per commit. --- # Challenge Claude Code with a second model One model writes the code, a second one argues with it. In a **challenger session**, Claude Code plans and builds as usual, and the OpenAI Codex CLI on the same laptop critiques the plan when Claude leaves plan mode and reviews every commit Claude makes. A blocking finding sends Claude back to fix and amend before it can move on. Tares is the record and the after-session brain: the Claude and Codex exchange lands on one timeline per session, and when the session ends a Tares agent writes the summary and proposes what the next session in that repo should remember. The challenger runs locally and never waits on Tares; Tares never calls Codex. This guide sets up the **Challenger workflow** project and walks one session end to end. Everything the project creates is an ordinary object on its own page; see [Projects](/tares/projects). ## Prerequisites - A running Tares (`uv tool install tares && tares up`, see the [Quickstart](/tares/quickstart)), or a Tares Cloud instance. - The **Tares plugin for Claude Code**, version 0.2 or later. In Claude Code: ``` /plugin marketplace add glassflow/tares /plugin install tares@tares ``` The install asks for the Tares URL and, on a secured instance, a `read + ingest` [API key](/tares/deployment#api-keys). Details on the [Claude Code sessions](/tares/connectors/claude-code) page. - The **Codex CLI**, logged in. Codex runs on your laptop and is billed to your OpenAI account: ``` npm install -g @openai/codex codex login ``` - An **Anthropic API key** for the summarizer, set under **Settings > Anthropic** or as `ANTHROPIC_API_KEY`. Tares Cloud instances come with one. ### Mark the session Start Claude Code in a project and say **"make this a challenger session"**, or type `/tares:challenger`. Claude calls the `set_session_flow` tool of the Tares MCP server; the plugin sees that call in the transcript, marks the session on your laptop, and stamps every line it ships from then on with `flow=challenger`. Nothing else to set up. The first marked session creates the **Challenger workflow** project on Tares by itself: a source with one timeline per session, a trigger that fires when a challenger session ends, and the `challenger_summarizer` agent. It shows up under **Projects**. You can also create it there first, if you want to set a Slack channel or a model. `/tares:challenger off` turns the challenger off for the rest of the session. A session that was not marked is streamed like any other and nothing runs. ### The plan gets challenged Ask for something in plan mode. When you approve the plan and Claude leaves plan mode, the plugin hands the plan to Codex (`codex exec`, read-only sandbox). Codex critiques it for gaps, wrong architecture, scope, unhandled risks and missing verification, and tags each finding `[P1]` (the plan fails as written), `[P2]` (will cause rework) or `[P3]` (advice). The critique comes back to Claude as context right after your approval, so Claude's first message after the plan mentions the findings and adjusts. A plan critique never blocks: only `[P1]` counts as blocking on a plan, and even then Claude is asked to revise or to tell you why it disagrees. Codex takes 30 to 90 seconds on a plan, so that first reply is slower. On Tares, a `challenge_plan` event lands on the session: "Challenger reviewed the plan x.md: 9 findings (2 blocking): [P1] ...". ### Every commit gets challenged Let Claude implement and commit. After each `git commit`, the plugin runs `codex exec review --commit ` on that commit. Then: - **No findings**: Claude carries on. A `challenge_commit` event with "no findings" lands on the session. - **`[P1]` or `[P2]` findings**: Claude is blocked with the findings and told to fix them and fold the fix into the same commit with `git commit --amend` (or a new commit when the reviewed one is already on a remote). The amended commit is reviewed again, as round 2, and so on until Codex is satisfied. The loop is capped at 8 rounds per commit and 5 turn ends per session; after that the findings come back as context instead. - **`[P3]` findings**: context only, never blocking. - A Codex timeout, error or an inconclusive review never blocks. If you disagree with a finding, `/tares:challenger-waive` lists the blocking findings and waives one (or all); the waiver is remembered for that finding on later rounds and shipped to Tares as a `challenge_waived` event. To make commits advisory as well, set the plugin option `challenger_mode` to `advise`. ### Read the exchange on Tares Open the project page. **Sessions** lists every challenger session with its repo and branch, the plan outcome, one badge per reviewed commit (`Findings (N)` or `Pass`) and whether the session is live, ended or summarized. Click a session: the Claude and Codex exchange reads as one thread (challenge events only), with a switch to the whole session read across the project's sources. **Explore** shows the same session next to everything else Tares knows. ### End the session `/exit`. The plugin ships a `session_end` line, the `challenger_session_ended` trigger fires, and `challenger_summarizer` reads the whole session and writes a finding with five sections: what was asked and built, the plan and how Codex changed it, each commit and what Codex caught, cost, and **Memory proposals**: up to five sentences about the repo worth carrying into the next session. The summary appears on the project's Overview under **What the agents found** within a minute or two; Advanced setup has the run under **Agents**. **Summarize** on a session row runs the summarizer on demand, on a live session too. ### Accept what to remember Open a summarized session under **Sessions**: its **Memory proposals** list the open proposals with **Accept** and **Reject**. Accept writes the sentence to the `agent_memory` source as a decision keyed by the repo; reject records a rejection there too, so the choice holds in every browser. Nothing reaches memory without an accept. Start the next Claude Code session in that repo. The plugin fetches the accepted decisions for the repo at session start and hands them to Claude as context, before your first prompt: ``` Memory from earlier Tares sessions in this repo (accepted by the user): - Race conditions in async hooks are a recurring source of Codex findings in this repo; ... ``` Ask Claude "what do you remember about this repo from Tares?" to see them. ## Living with it - **Where things run.** The plan critique and the commit reviews run on your laptop, in the Claude Code hooks, against the Codex CLI and your OpenAI account. Tares only receives the results. A Tares that is down or slow never blocks a review; the plugin retries shipping on the next hook. - **State on your laptop.** The session mark lives in the plugin's data directory and is removed when the session ends. Review state, the fix-loop counters, the review history (`tares-challenger-reviews.jsonl`) and waivers live under the repository's `.git/`. - **Plugin options.** `challenger_mode` (`strict`, the default, or `advise`), `codex_bin` (the Codex binary, when it is not on PATH), `codex_sandbox` (`workspace-write` or `danger-full-access` when Codex needs to run the project's commands; the default is read-only). - **Project parameters.** `slack_channel` posts each session summary to a Slack channel (needs the [Slack bot](/tares/tares-agents/delivery)); `model` picks the summarizer's model. **Edit** on the project page changes them. - **Costs.** Codex runs are billed by OpenAI; a session with a plan and three commits is typically five to eight Codex runs. The summarizer is one Tares agent run per session, metered like every other agent run. - **Cloud.** On Tares Cloud the same plugin install points at your instance URL with an API key; the project, the summarizer key and the console are already there. ## The events The plugin ships these lines into the `claude_code` source, next to the transcript, all carrying `flow=challenger`: | Event | When | Labels | |---|---|---| | `session_flow` | the session was marked (or cleared) | `flow` | | `challenge_plan` | Codex reviewed the plan | `verdict`, `finding_count`, `blocking_count`, `duration_seconds` | | `challenge_commit` | Codex reviewed a commit | `verdict`, `sha`, `round`, `finding_count`, `blocking_count`, `duration_seconds` | | `challenge_waived` | a finding was waived | `finding_count` | | `session_end` | the session ended | `flow` | `verdict` is Codex's own word (`PASS`, `FAIL`, `INCONCLUSIVE`, `TIMEOUT`, `ERROR`) and is what trigger filters use; the console shows what was found instead. The review prose and findings are in each event's payload. The review mechanics (post-commit review, priority-tagged findings, the blocking fix loop, plan critique) are adapted from [codex-review](https://github.com/andreidavid/codex-review) by Andrei David (MIT). ## Related - [Projects](/tares/projects): the concept, ownership rules and the API. - [Claude Code sessions](/tares/connectors/claude-code): the plugin and the `claude_code` source. - [Tares agents](/tares/tares-agents): rounds, findings and memory. --- # The HTTP API in five minutes Everything the console and the MCP tools do goes through the daemon's HTTP API. This guide drives the whole loop with `curl`: create a source, feed it, read a correlated timeline, define a trigger, watch it fire, and write an observation back. No upstream systems required. You need a running daemon ([Quickstart](/tares/quickstart)): `tares up`, API at `http://127.0.0.1:8787`. ### Ingest: create a source and feed it Create a push ([webhook](/tares/connectors/webhook)) source. The config maps payload fields into the envelope; the label marked `primary` is the entity key: ```bash curl -s -XPOST localhost:8787/api/sources -H 'content-type: application/json' -d '{ "name": "checkout_probe", "connector": "webhook", "config": { "event_type": "probe", "text_template": "latency {latency_ms}ms on {endpoint}", "labels": [{ "name": "service", "field": "service", "primary": true }] } }' # {"ok":true,"name":"checkout_probe","ingest_key":"webhook-…"} ``` Feed it: ```bash curl -s -XPOST localhost:8787/ingest/checkout_probe -H 'content-type: application/json' \ -d '{"service": "checkout", "endpoint": "/pay", "latency_ms": 120}' curl -s -XPOST localhost:8787/ingest/checkout_probe -H 'content-type: application/json' \ -d '{"service": "checkout", "endpoint": "/pay", "latency_ms": 1450}' curl -s -XPOST localhost:8787/ingest/checkout_probe -H 'content-type: application/json' \ -d '{"service": "search", "endpoint": "/q", "latency_ms": 45}' ``` Numeric payload fields (`latency_ms`) become typed fields triggers can aggregate over; the full payload is kept lossless. This is the generic inbound path for anything that can send JSON. Locally you can post to the source by name. The response's `ingest_key` is the stable, unguessable path (`/ingest/`). Use that when producers deliver over the network. On a [secured instance](/tares/deployment#authentication), producers also send an `ingest`-scoped [API key](/tares/deployment#api-keys) as `Authorization: Bearer `. ### Read: one correlated timeline The primary read needs no setup at all: a `{label: value}` selector across **all** sources: ```bash curl -s -XPOST localhost:8787/read -H 'content-type: application/json' \ -d '{"selector": {"service": "checkout"}, "window": "15m"}' ``` You get `checkout`'s events, time-ordered, from every source that carries the label. With one source it's modest; the payoff is when logs, metrics, and commits arrive interleaved on one clock. To read only some sources, name them with `sources`, or name a `project` to read only that project's sources: ```bash curl -s -XPOST localhost:8787/read -H 'content-type: application/json' \ -d '{"selector": {"service": "checkout"}, "window": "15m", "sources": ["checkout_probe"]}' ``` ### Watch: a trigger that wakes someone A trigger names the sources it watches, the label that identifies the entity, and the condition. Start a subscriber to be woken (stands in for your agent's webhook) in a second terminal: [`examples/woke_receiver.py`](https://github.com/glassflow/tares/blob/main/examples/woke_receiver.py) in the repo listens on `http://127.0.0.1:9999/woke`. Then define the condition and subscribe it: ```bash curl -s -XPOST localhost:8787/api/triggers -H 'content-type: application/json' -d '{ "name": "slow_checkout", "sources": ["checkout_probe"], "key_field": "service", "condition": {"aggregate": "max", "field": "latency_ms", "predicate": "> 1000", "window": "5m"}, "emit": {"kind": "slow_checkout", "context_window": "15m"}, "cooldown": "1m" }' # {"ok":true,"project":"uc_…"} curl -s -XPOST localhost:8787/subscribe -H 'content-type: application/json' \ -d '{"trigger": "slow_checkout", "url": "http://127.0.0.1:9999/woke"}' ``` Cause the condition: ```bash curl -s -XPOST localhost:8787/ingest/checkout_probe -H 'content-type: application/json' \ -d '{"service": "checkout", "endpoint": "/pay", "latency_ms": 2100}' ``` Within a few seconds the receiver prints the dispatch, **with the 15-minute correlated timeline attached**. That's the core move: the store wakes the agent, and the agent starts with context instead of fetching it. Every firing (even with zero subscribers) is logged: ```bash curl -s localhost:8787/api/activity/dispatches ``` (console: **Firings**.) ### See it in the project You named no project, so the source and the trigger landed in the Default project, the one `GET /api/projects` lists first. Its timeline shows the firing as a thread, with where it was delivered: ```bash curl -s localhost:8787/api/projects/uc_…/timeline # the project id the trigger call returned ``` (console: **Projects → Default → Setup → Advanced setup → Activity**.) To keep a job separate, create a project first and pass its id or name as `project` when you create the source and the trigger. See [Projects](/tares/projects). ### Write back: the agent surface over HTTP The [MCP tools](/tares/agents#tools) map onto the same endpoints, so you can drive the agent loop by hand. Describe an object: inferred schema, entities, freshness, sample events: ```bash curl -s localhost:8787/catalog/source:checkout_probe ``` Write an observation back. The first call auto-provisions the [`agent_memory`](/tares/connectors/memory) source, and the memory shows up inside the entity's timeline on the next read: ```bash curl -s -XPOST localhost:8787/remember -H 'content-type: application/json' \ -d '{"key": "checkout", "content": "latency spikes on /pay correlate with payments deploys"}' ``` To do all of this from a real agent instead, [connect one over MCP](/tares/agents): the tool set (`read`, `catalog_list` / `catalog_describe`, `create_trigger`, `remember`, `subscribe`, plus the source-setup tools) is this API with discovery built in. ### Keep it: the catalog as YAML Everything you just built is catalog state; YAML is its portable form: ```bash curl -s localhost:8787/api/catalog/export > catalog.yaml # git it, share it ``` Importing (console → **Catalog**, or `POST /api/catalog/import`) supports merge or replace, validated as a whole before anything is written. A fresh daemon pointed at that YAML (`TARES_CATALOG=catalog.yaml tares up`) reproduces the whole setup on first boot. --- # Watch with triggers A [trigger](/tares/concepts#triggers-and-subscriptions) watches one or more sources and evaluates a condition as events arrive. When it fires, Tares pushes to any subscribed webhook, so an agent is woken with the relevant timeline instead of polling. A trigger is used by one or more [projects](/tares/projects); each project says which agents it wakes there. ### Have a source with a numeric field Triggers aggregate a typed `field`, so at least one of the trigger's sources must produce one. For example, a Prometheus source emitting `rate_5xx`, labeled by `service`. See [Connectors → prometheus](/tares/connectors/prometheus). ### Define the trigger A trigger names its `sources`, optional `filters` and `key_field`, a `condition`, what to `emit`, and a `cooldown`. Add it on the project's page (**+** next to **Triggers**), under **Triggers → Add trigger**, or in the catalog YAML: ```yaml triggers: - name: error_spike project: checkout watch # optional; the Default project when left out sources: [checkout_metrics, checkout_logs] key_field: service # optional; default: the first source's primary label filters: # optional; only these events count - { field: env, op: eq, value: prod } condition: aggregate: max # count | sum | avg | max | min | any field: rate_5xx predicate: "> 1.0" # fire when max(rate_5xx) over the window exceeds 1.0 window: 1m group_by: [key_value] # evaluated per entity (per service) emit: kind: error_spike context_window: 15m # how much timeline to hand the agent cooldown: 5m # minimum gap between firings for the same entity ``` - **`sources`** are the sources the trigger watches, at least one. They join the trigger's project if they are not in it yet. - **`key_field`** is the label that names the entity across those sources, such as `service`. Each source should carry it. - **`filters`** narrow which events count and which are handed over. Each is `{field, op, value}` with `op` one of `eq`, `neq`, `contains`, `gt`, `lt`, `gte`, `lte`; `field` is a label the sources carry or one of `event_type`, `source`, `text`, `key_value`. The condition is checked as events are ingested. `group_by: [key_value]` evaluates it per entity, so each service fires independently. To look at the sources on a clock instead of on a condition, give the trigger a schedule (`condition: {every: 10m}`): it fires once per interval for all its events and hands over a summary of the window. See [Watch, then escalate](/tares/guides/watch-then-escalate). Over MCP, an agent does the same with `create_trigger` and `update_trigger`, which take the same fields (see [Tools](/tares/agents#tools)). ### Subscribe an agent A [Tares agent](/tares/tares-agents) is woken by the trigger in a project that wires it to that trigger, once you turn it on there. An external agent registers a webhook over MCP with the [`subscribe`](/tares/agents#tools) tool: > Use tares to subscribe to the `error_spike` trigger and deliver to `https://my-agent.example.com/hook`. `subscribe(trigger, url)` returns a subscription id. (You can also register via `POST /subscribe`.) The trigger's page shows everything it delivers to, with per-subscriber delivery counts: ![A trigger's page: the condition, and every subscriber with its delivery record](/assets/tares-trigger.png) ### Receive dispatches When the condition holds, Tares POSTs one JSON body to each subscriber: ```json { "dispatch_id": "9f2c81d4…", "trigger": "error_spike", "project": "uc_1a2b3c", "projects": ["uc_1a2b3c"], "kind": "error_spike", "key": "api-server", "fired_at": "2026-07-17T09:14:03+00:00", "payload": "…the entity's correlated timeline, ready to hand to the model…", "run_ids": ["run_4be1c0d2a9f3"] } ``` `projects` lists the running projects that use the trigger, and `project` is the first of them (the one that made the trigger, when it is one). `run_ids` lists the Tares agent runs the same firing started (empty when none). To receive every trigger of a project at once, an outside agent can [join the project](/tares/projects#join-be-woken-by-the-projects-triggers). `payload` is the entity's correlated timeline across the trigger's sources over `context_window`: the deploy, the logs, the metrics around the spike, so the agent has context without making a follow-up call. Your endpoint can be anything that accepts a POST and starts your agent with the body as context: a small FastAPI/Express route, a serverless function, a workflow-engine webhook. It must be reachable from the Tares server. Delivery rules: - **At-least-once.** A firing can be delivered more than once; dedupe on `dispatch_id`. - **Acknowledge with a 2xx.** 5xx responses and transport errors are retried with backoff; a 4xx is recorded as a failed delivery and not retried. - **Every firing is logged**, even with zero subscribers. Firings and per-subscriber delivery status are in the console under **Firings**, on the trigger's own page, and on the project's [Activity](/tares/projects#activity). Each dispatch has its own page with the delivery outcomes and the exact payload that was sent: ![A dispatch's page: delivery status and the correlated timeline that was POSTed](/assets/tares-dispatch.png) `cooldown` prevents a flapping condition from firing repeatedly for the same entity. Pick different aggregates/fields for different incident shapes, e.g. `max(p99_ms) > 1000` for latency vs `max(rate_5xx) > 1.0` for an error storm. Upgrading from a version with views? Each trigger took its view's sources, filters and key field on the first start. The API refuses a trigger that names a `view` with "views were removed: give the trigger `sources` (and `filters`)". A catalog file exported with a `views:` section still imports: each trigger gets its view's sources, filters and key field. See [Upgrading from views](/tares/projects#upgrading-from-views). --- # Watch, then escalate Alert rules catch what someone thought to write a rule for. This guide puts a first level in front of your root-cause agent: a **triage** agent looks at your sources every few minutes, says "normal" in a line most of the time, and when something moves, hands that one entity to the **main** agent for a root-cause analysis. Two agents, linked by a handoff. The triage agent is cheap and frequent; the main agent is thorough and rare. Every step is recorded: each tick, each triage verdict, each handoff and each root-cause note sits on the entity's timeline. ### Pick the sources to watch Any sources work; put both agents in one [project](/tares/projects). Label the fields you want counted, such as `service` and `status_code`, so the triage agent can see which values moved. For example, your request logs in a `web_logs` source, labeled by `service`. ### Add a schedule trigger A schedule trigger fires every interval for all the events of its sources, whether or not anything happened. It hands the agent it wakes a summary of the window instead of raw lines: for each label you name, the count per value in this window against the window before, largest change first, plus a few recent lines. A busy stream of tens of thousands of lines becomes a page the model can read. On the project's page click **+** next to **Triggers**, then **fires: on a schedule**. Or in the catalog: ```yaml triggers: - name: watch-web sources: [web_logs] key_field: service condition: every: 10m # at least 1m summary_by: [service, status_code] # labels to count; default: the trigger's key field ``` ### Add the triage agent Create a Tares agent on `watch-web` and seed its prompt from the **Triage (on a schedule)** preset. Pick the cheapest model on your provider that calls tools reliably, and set a budget so the cadence cannot run up a bill. The preset tells the model to consider only values that grew at least 3x and by at least 50 events since the window before (or are new with 50 or more), to ignore routine noise such as uptime probes, and to judge among what is left. The numbers are in the prompt, so tune them by editing it. The preset also fills in **How it ends**: **Ends every run with a conclusion** is ticked, and **Verdicts it can give** lists `investigate`, "one entity looks like a problem and needs a closer look". Tares then holds the agent to it: every run ends with the `conclude` tool, and a finding carries `investigate` or goes back to the agent to fix (see [How a run ends](/tares/tares-agents/how-a-run-ends)). Every run ends one of two ways: - **no_op**: nothing needs a closer look. The run is a success with no finding; the runs table shows it as "no finding" with the one-line reason. - **finding** with verdict **investigate**: one entity looks off. The finding is recorded on that entity (for example `service=checkout`), naming the numbers that moved. The preset tells the model that this verdict hands the entity off to the agent that takes a closer look. ### Hand off to the main agent The simplest link is a **handoff** on the triage agent: when it concludes with verdict `investigate`, the main agent takes over on the same entity. Create the main agent in the same project and seed its prompt from **Root cause after a handoff** (it comes with the verdicts `rca` and `resolved`). Set its trigger to **No trigger: only a handoff starts it**: it never wakes on its own, and its page says "Only a handoff from triage starts it". Then open the triage agent, and under **When it concludes** choose **Add a handoff**: pick `investigate` from the verdict dropdown, the main agent, cooldown `30m`. In the catalog: ```yaml agents: - name: triage trigger: watch-web concludes: true verdicts: - { verdict: investigate, when: one entity looks like a problem and needs a closer look } prompt: ... # from the Triage (on a schedule) preset handoffs: - { verdict: investigate, agent: rca, cooldown: 30m } # at most two root-cause runs per hour per entity - name: rca # no trigger: it runs only when handed off concludes: true verdicts: - { verdict: rca, when: you found what is failing and why } - { verdict: resolved, when: it was noise, or it is already over } prompt: ... # from the Root cause after a handoff preset ``` The main agent is handed the triage finding, not the logs, so it fetches its own evidence with `read`, `stats` and any [MCP tools](/tares/tares-agents/tools#external-tools-mcp) you give it, then writes its note on the same entity with `conclude`. See [Hand off to another agent](/tares/tares-agents/handoffs) for the cooldown, the depth limit and what is recorded when a handoff does not start. **Or wake it with a trigger over findings.** A handoff is the simpler fit, and it shows on the triage agent's page under **When it concludes**. A trigger is worth it only when you need a condition, such as several `investigate` findings in a window or findings from more than one agent. A trigger over the `findings` source, filtered to the triage agent's `investigate` findings, wakes the main agent: ```yaml triggers: - name: escalate sources: [findings] key_field: service filters: - {field: agent, op: eq, value: triage} - {field: verdict, op: eq, value: investigate} condition: {aggregate: count, predicate: "> 0", window: 5m} cooldown: 30m # at most two root-cause runs per hour per entity ``` Create the main agent on `escalate`, enable it, and seed its prompt from **Root cause after a handoff** the same way. Use one link or the other, not both, or the main agent runs twice per flag. An agent can be woken by findings only through a trigger filtered to **another** agent's findings (`agent eq `). A trigger over all findings, or over the agent's own, is refused: the agent would wake itself forever. ### Watch it work Open the project. When triage flags something, the main agent's root cause shows on the [Overview](/tares/projects#overview) under **What the agents found**: one card for the whole chain, with the headline and the next step. Click it to see how Tares got there: the tick, the triage finding and the root cause, in order. To look closer, **Setup → Advanced setup**. The triage agent's runs (click it under **Agents**) show mostly "no finding" rows in the **outcome** column, each with its reason and cost; a flagged run shows an `investigate` chip with its headline. Advanced setup's [Activity](/tares/projects#activity) shows the tick, the triage finding and the root cause as one thread. ## Turn it off Disable the triage agent, or pause its schedule trigger. Either stops the watch; with no new `investigate` findings, the main agent goes quiet too. Alert-driven agents keep running as before. ## Costs The triage agent runs every interval: at 10 minutes that is 144 runs a day, above the default limit of 50 runs per agent per day. Raise it under **Settings → Agents** (or with `TARES_AGENT_DAILY_CAP`), and give the agent a budget. A small model reading a summary costs well under a cent a run. The main agent only runs when triage flags something, at most once per cooldown per entity. ## Related - [Watch with triggers](/tares/guides/triggers): condition triggers and dispatch. - [Tares agents](/tares/tares-agents): prompts, models, tools and guardrails. - [Build an AI SRE](/tares/guides/ai-sre): the alert-driven agent this pattern sits in front of. --- # Connect an outside agent to a project After this guide, Claude Code works inside one Tares [project](/tares/projects): it reads the project's sources, follows the project's [skills](/tares/tares-agents/skills), sees what the Tares agents already found, and records its own findings on the same timelines. Everything it records shows on the project's Overview. The same steps work for any MCP client (Codex, Cursor, your own agent); only the connect command differs, see [Connecting agents](/tares/agents). **You need:** - A running Tares instance with a project that has sources and a trigger, for example the [AI SRE demo](/tares/guides/ai-sre). - The instance started with auth (`tares up --auth`, or `TARES_AUTH_TOKEN` set), so keys are checked. On an open instance there are no keys; skip step 1 and name the project in your prompts instead. - The MCP endpoint running: `tares mcp` (it serves `http://127.0.0.1:8788/mcp`). ### Make a project key Open the project, go to **Settings → Keys**, and choose **New key**. Name it after the agent that will hold it, such as `claude-code`: every finding it records carries this name. Copy the secret now; it is shown once. The key reads this project only and records findings in it. Any other call answers 403. See [Project keys](/tares/projects#project-keys) for the full list. ### Connect Claude Code with the key ```bash claude mcp add --transport http tares http://localhost:8788/mcp \ --header "Authorization: Bearer " ``` Over stdio, start `tares-mcp` with `TARES_AUTH_TOKEN=` in its environment instead. With a project key the project is implied: the tools need no `project` argument. Check the connection in a Claude Code session: > Use tares: which project can you work in? It calls `list_projects` and names the one project the key belongs to. ### Work in the project Ask for something the project is about: > Use tares: what happened to api-server in the last 30 minutes? Check the project's skills first, > and record what you conclude. Claude Code works through the project tools: 1. `list_skills`, then `get_skill` for a skill whose description matches the task. 2. `stats` to see which values moved, and `read` for the entity's timeline across the project's sources. 3. `list_findings` and `project_timeline` to see what the Tares agents already concluded, so it builds on that instead of repeating it. 4. `record_finding(entity, finding, verdict)` when it concludes: the entity is what the finding is about (here `api-server`), the finding is markdown, the verdict one lowercase word such as `rca`. ### See it in the project Open the project. The finding is a card under **What the agents found** on the Overview, under the key's name. In Advanced setup's **Activity** it is a thread of its own, marked as recorded from outside Tares. It is also on the entity's timeline in **Explore**, so the next Tares agent that reads `api-server` starts from it. ### Optional: be woken by the project's triggers Claude Code runs when you ask it. An agent that runs on its own, such as a service with a webhook, can join the project instead: `join_project(url)` (or `POST /api/projects/{id}/subscribe {"url": ...}`) sends every firing of every trigger in the project to that URL, triggers added later included. The body carries `project`, `dispatch_id`, `key` (the entity), `payload` (the timeline) and `run_ids`, the Tares agent runs the same firing started. The agent shows under **Agents** on the project's page, marked external; click it for its last delivery. To cut the agent off, revoke the key under **Settings → Keys**. Revoking removes the key's subscriptions too; **Revoke** on the outside agent under **Agents** stops only the deliveries. ## Related - [Projects, outside agents](/tares/projects#outside-agents): what a project key can do, and the API. - [Connecting agents (MCP)](/tares/agents): every client and every tool. - [Skills](/tares/tares-agents/skills): the instructions the agent loads. --- # Self-host on a server Run a single-tenant Tares instance on a server: the daemon, the MCP server, and a reverse proxy (Caddy) that terminates TLS and serves one hostname. DuckDB is single-writer, so this is exactly one `taresd` and one volume. ### Provision a host Any Linux host with Docker. A 1 GB VM is sufficient: it pulls a prebuilt image and does not build one. ```bash curl -fsSL https://get.docker.com | sh # if Docker isn't installed ``` ### Point DNS Create an `A` record for your hostname (e.g. `tares.example.com`) pointing at the host's IP. Caddy needs this resolving before it can obtain a TLS certificate. ### Open the firewall Allow SSH and HTTP/HTTPS: ```bash ufw allow 22 && ufw allow 80 && ufw allow 443 && ufw --force enable ``` ### Add the compose and config Create the `docker-compose.yml` and `Caddyfile` from [Deployment → Server (compose + TLS)](/tares/deployment#server-compose--tls) on the host. Then set the secrets and domain: ```bash cat > .env <" ``` ## Operate - **Upgrade**: pin a version with `TARES_VERSION` in `.env`, then `docker compose pull && docker compose up -d`. - **Back up**: snapshot the host, or copy the data volume's `tares.duckdb`. - **Auth**: the root token secures the console, API, MCP, and ingest. Hand machines their own scoped [API keys](/tares/deployment#api-keys) rather than the root token. For per-user SSO, front the console with a proxy (oauth2-proxy, Tailscale). See [Deployment → Authentication](/tares/deployment#authentication). --- # CLI reference The `tares` package installs four entry points. | command | purpose | |---|---| | [`tares up`](#tares-up) | start the daemon and console | | [`tares mcp`](#tares-mcp) | run the MCP server (for remote agents) | | [`tares status`](#tares-status) | readiness checklist and the next step | | [`taresd`](#taresd) | the daemon, configured by environment only | | [`tares-mcp`](#tares-mcp-1) | the stdio MCP proxy (spawned by an agent client) | ## tares up Starts `taresd` with a persistent data home and prints the console URL. ```bash tares up [--host HOST] [--port PORT] [--data-dir DIR] [--open] [--auth[=TOKEN]] ``` | flag | default | description | |---|---|---| | `--host` | `127.0.0.1` | bind address; `0.0.0.0` to expose on the network | | `--port` | `8787` | bind port | | `--data-dir` | `~/.tares` | directory for the DuckDB file and catalog | | `--open` | off | open the console in a browser | | `--auth[=TOKEN]` | off | require a login. Bare `--auth` generates and persists a **root token** (printed as a `…/?token=…` login URL each launch); `--auth=TOKEN` uses your own. Omit for an open instance. See [Authentication](/tares/deployment#authentication). | `tares up` sets `TARES_DB` and `TARES_CATALOG` under `--data-dir` unless they are already set in the environment. `--auth` exports `TARES_AUTH_TOKEN`, so setting that variable is equivalent. ## tares mcp Runs the MCP server, a network endpoint for remote agents (`streamable-http` is the default). For a client that spawns the server itself over stdio, use [`tares-mcp`](#tares-mcp-1) instead. ```bash tares mcp [--transport {stdio,sse,streamable-http}] [--host HOST] [--port PORT] [--taresd URL] ``` | flag | default | description | |---|---|---| | `--transport` | `streamable-http` | `stdio`, `sse`, or `streamable-http` | | `--host` | `127.0.0.1` | bind address (HTTP transports) | | `--port` | `8788` | bind port (HTTP transports) | | `--taresd` | `http://127.0.0.1:8787` | the daemon URL to proxy to | ```bash tares mcp --transport streamable-http --host 0.0.0.0 --port 8788 --taresd http://localhost:8787 # serves http://:8788/mcp ``` ## tares status ``` tares status [--taresd URL] [--data-dir DIR] [--json] ``` Asks the running daemon (default `http://127.0.0.1:8787`, or `TARESD_URL`) and prints one line per check: daemon, auth, sources configured and receiving, projects, triggers, Tares agents and whether an Anthropic key is set, the MCP endpoint, which agent clients on this machine have Tares registered (Claude Code, Cursor, Codex; read-only), Slack. The last line is the one thing to do next. `--json` prints the same as a stable object. Exit code 1 when nothing answers. When auth is on, the root token is read from `--data-dir` (or `TARES_AUTH_TOKEN`). ## taresd The daemon itself, with no CLI flags, configured entirely by environment variables (see [Configuration](/tares/deployment#configuration)). `tares up` is a thin wrapper over this. ```bash TARES_DB=/data/tares.duckdb TARES_HOST=0.0.0.0 TARES_PORT=8787 taresd ``` ## tares-mcp The stdio MCP proxy, the entry point an agent client (Claude Code, Claude Desktop) spawns. It reads: | variable | default | description | |---|---|---| | `TARESD_URL` | `http://127.0.0.1:8787` | the daemon to proxy to | | `TARES_AUTH_TOKEN` | unset | bearer token, if the daemon requires one | | `TARES_MCP_TRANSPORT` | `stdio` | `stdio`, `sse`, or `streamable-http` | See [Connecting agents](/tares/agents) for client configuration. --- # Release notes Notable changes to Tares, newest first. The project follows [Semantic Versioning](https://semver.org/); earlier `0.0.x` history is in the git log. Entries below 1.0.0 name the commands and variables as they were at that release, when the project was called NavFlow. They are history, not current usage. See [Upgrading from 0.x](/tares/deployment#upgrading-from-0x) for the full mapping. ## 1.38.0: unreleased (release candidate) **Added** - **Projects are the unit.** Every instance has a Default project that holds whatever was made outside another one. A project has a goal, a one-sentence outline of how it works, a health line, today's totals and **What the agents found**: one result per chain of runs, with a headline and a next step, that you can mark as handled. Advanced setup's Activity shows one thread per firing, with the runs it woke and what they led to. See [Projects](/tares/projects). - **Parts are shared.** Sources, triggers, agents, MCP servers and skills belong to the instance, and any number of projects can use the same one. A project holds its own wiring: which trigger wakes which agent, on or off, and which agent takes over on whose verdict. A run belongs to the project whose wiring started it. Pausing a project turns only its wiring off, and deleting one keeps every part another project uses. **All resources** lists every part with the projects that use it (`GET /api/resources`), and the catalog export carries each project's wiring. - **Guided setup.** **Projects → Create new** starts from a goal: Tares writes a plan in plain words (what it watches, when it wakes, who does the work, tools and know-how), you change any part in place, then connect what only you can and **Run it once now** to see a result. The plan is kept as a draft you can finish later from Projects, or delete. It reuses sources, agents, tools and skills already on the instance, and posts findings to a Slack channel you pick. See [Guided setup](/tares/build). - **[Skills](/tares/tares-agents/skills)**: named instructions (a runbook, a house style) that agents load when a task matches. A skill is shared: editing it changes it everywhere, and removing it from a project deletes it only when no other project uses it. - **Handoffs.** An agent names, per verdict, the agent that takes over on the same entity, with a cooldown. A chain stops after three handoffs. An agent can have no trigger of its own, so only a handoff starts it. See [Tares agents](/tares/tares-agents/handoffs). - **How an agent ends.** "Ends every run with a conclusion" gives an agent the `conclude` tool whatever its prompt says. Its verdicts are a list you set, each with when to give it; a finding must carry one of them, and the handoff form offers them as a dropdown. The runs table shows each run's verdict and headline in an outcome column. - **Outside agents in a project.** A project key reads one project and records findings in it. An agent outside Tares can join a project's firings, record findings with a headline and next step, and use new MCP tools such as `join_project`, `record_finding` and `project_timeline`. See [Connect an outside agent to a project](/tares/guides/outside-agent). - A trigger can say what wakes it in plain words (`description`), and the project sentence uses it. **Changed** - **Views are gone.** A trigger names its own `sources`, `filters` and `key_field`. The first start after upgrading moves each view into the triggers that used it, and places every object in a project. `/api/views`, `POST /query` and `POST /derive` answer 404. - Deleting a trigger, agent, MCP server or source removes it from every project. The agents a deleted trigger woke stay, without a trigger. - Every write needs the admin scope, apart from reads, ingest, recording a finding and subscribing. A read key can no longer create projects or add MCP servers. - An agent's trigger can be changed after the agent is made, and the console names sources by what they watch (a repo, a host), with the name underneath. **Fixed** - Upgrading from 1.37.0 and then stopping the instance hard no longer leaves the database unusable. ## 1.37.0: 2026-09-29 **Added** - The `rius_rca` template takes a `daily_cap`, so each workspace's root-cause agent can be sized by plan. **Changed** - A finding in Slack is posted whole when it fits in one message; only a longer note gets an excerpt in the channel and the full note in the thread. **Fixed** - Clicking a button on a Tares message in Slack no longer shows "This app is not configured to handle interactive responses". ## 1.36.0: 2026-09-29 **Changed** - Slack messages from Tares read like an alert: the entity as a header, the agent, trigger, verdict and model as fields, a short excerpt, and **View in Tares** and **Open timeline** buttons (when `TARES_PUBLIC_URL` is set). The full note goes in the thread. - Wide markdown tables in Slack become one line per row, and long notes no longer split inside a code block. ## 1.35.0: 2026-09-28 **Added** - **Watch, then escalate.** A `triage` preset runs on a schedule and flags the entity that looks off; a root-cause preset digs in on what it flagged. See [Watch, then escalate](/tares/guides/watch-then-escalate). - Schedule triggers fire every N minutes and hand the agent a summary of the window. - Tares agents get a `stats` tool (counts per label value, this window against the one before) and can end a run with `conclude`: `no_op` when there is nothing to report, or a finding with a verdict about a named entity. - Runs record what they produced (a pull request, a commit, a Slack message, a write-back), read off their own tool calls. - Runs per agent per day is a setting under **Settings → Agents**. ## 1.34.0: 2026-09-28 **Added** - A push delivery with `X-Tares-Bypass-Cooldown: true` wakes the triggers over that source now, even inside their cooldown. **Changed** - Agent traces follow the OpenTelemetry GenAI conventions more closely: one run is one session, and spans carry the agent's name, tool definitions and tool call details. ## 1.33.0: 2026-09-15 **Fixed** - A model provider set in the environment lists its models at start, instead of waiting for a refresh under Settings. ## 1.32.0: 2026-09-15 **Added** - A deployment can hand an instance a model provider (`TARES_PLATFORM_PROVIDER_URL`, `_KEY`, `_NAME`): an OpenAI-compatible entry that is the default until you pick another. Tares Cloud uses it for trial instances. ## 1.31.0: 2026-09-14 **Added** - `GET /metrics`: the daemon's own counters in the Prometheus text format (ingest, polls, agent runs, model spend, database size, trigger passes). Counts only, never an entity or payload. ## 1.30.0: 2026-09-14 **Added** - **[Model providers](/tares/model-providers).** An instance holds a list of providers under **Settings → Model providers**: Anthropic, OpenAI, or any OpenAI-compatible endpoint (LiteLLM, OpenRouter, Ollama, vLLM). Each agent picks a provider and a model; Ask and the builder run on the default. Saving a provider reads the models it serves, with a refresh, and an agent can name a model by hand when it lists none. `OPENAI_API_KEY` and `OPENAI_BASE_URL` seed an OpenAI entry; `TARES_MODEL_PROVIDER` names the default. The Anthropic key and gateway settings are unchanged under the new tab, and an agent that names a provider the instance lacks runs on the default. - The spend meter prices OpenAI models, takes a router's own cost figure when it reports one, splits spend by provider, and records tokens without a dollar figure for a model it cannot price. Traces name the provider on every model span. - Small-model hardening: a tool call written as JSON text is run, a mis-cased tool name still matches, and a run with no conclusion and no tool call says to check tool calling. **Changed** - Console, CLI and README say "model provider" where they said "Anthropic key". The Settings tab **Model access** is now **Model providers**. ## 1.29.1: 2026-09-10 **Fixed** - The RCA write-back reported the wrong delivery id when more alerts for the same service arrived while the agent was running. The `key` is resolved when the run starts, and the body carries the firing's labels as `labels` so a receiver can check the attribution. ## 1.29.0: 2026-09-08 **Added** - Storage is measured against the volume the database sits on when no `TARES_MAX_DB_SIZE` is set; at 95% of the limit ingest is refused with 507 and poll connectors wait, with the reason on the source's health and the Overview. A run records whether its finding reached the write-back webhook. Agents can report a label's value as the write-back's `key` (`webhook_key_label`). ## 1.28.0: 2026-09-08 **Added** - **Model access through an [LLM gateway](/tares/deployment#using-an-llm-gateway).** Tares agents and Ask can talk to any server that speaks the Anthropic Messages format: LiteLLM, Portkey, a proxy in front of Bedrock or Vertex. From the environment with `ANTHROPIC_BASE_URL` and `ANTHROPIC_AUTH_TOKEN`, the names Claude Code uses, or from **Settings → Model access**, stored on the instance and winning over the environment, so a hosted cell with a mandated proxy is configured by its owner. The gateway token is sent as a bearer header and never returned. The Settings tab is now called Model access and leads with where model calls go. Thanks to KurochkaR for the environment half. ## 1.27.0: 2026-09-08 **Added** - **[HTTP API (poll)](/tares/connectors/http-poll), the `http_poll` connector.** Polls any JSON endpoint on a schedule and stores one event per item, for the APIs no other connector covers: a weather service, a status page, a SaaS export, your own API. GET or POST with a body, extra headers, one credential header stored as a secret, a payload key into the reply, the webhook connector's mapping and a deduplication key. Nested values are reachable by dotted name in labels, the fields profile, view filters and trigger fields. A poll under 10 seconds is refused; a 429 or 5xx backs the source off, up to an hour, honouring Retry-After. Discover fetches once and proposes the rest. - The source form for it reads in order: method, URL, credentials yes or no, additional headers as key-value rows, body for POST. The mapping appears only after Discover, as decisions already made with the sample value beside each, under a panel showing what Tares fetched. - The builder proposes `http_poll` for a goal that reads a public or third-party API, instead of a webhook plus a script; "tell me when a city gets storm winds, from a public weather API" now builds in one sitting. **Changed** - Source form: test and save results sit above the buttons, not at the top of the page, and a required field the click found empty turns red and scrolls into view. A URL field is checked on save (http or https, a host) on Prometheus, Prometheus alerts and Loki as well. ## 1.26.0: 2026-09-07 **Added** - **The builder in two columns.** The conversation on the left with the answer box pinned under it, and a "To do" column on the right holding every card the assistant proposed. A decided card folds to one line; the pointer the chat leaves for each card opens it. A one-line head carries the steps, the project name and the goal. - Overview shows the Projects panel with **Create new** also on an instance with no project yet. **Changed** - The builder no longer invents a trigger for the agent: the daemon refuses an agent proposal whose trigger does not exist, Continue on the views and triggers step waits until a trigger exists, the step names sources that have no events yet, and the agent card never prefills an unknown trigger. - Front door: the starter sentences keep a fixed order instead of reordering while you type, the picked one is marked, and the call to action reads **Build it**. - The assistant shows a readable line for a non-JSON error reply, such as a proxy's 502 page. **Fixed** - Behind an nginx ingress, a builder step sent about five seconds after the previous one could fail with 502 "upstream prematurely closed connection": the proxy reused a pooled connection the daemon was closing at that moment. The daemon now keeps idle connections open longer than the proxy's pool. ## 1.25.0: 2026-09-04 **Added** - **[Build with Tares](/tares/build), the guided project builder.** Describe what you need; the assistant proposes sources from the installed connectors, then views and triggers, then an agent, one step at a time, asking before it guesses. Each proposal is the object's own form, prefilled, with the fields only you can fill marked. Nothing is created until you click, every Apply goes through the normal API, and the result is an ordinary project. A goal that matches a template is proposed as that template. `POST /api/agent/chat` takes `mode: "build"` and `step`. - **A new front door.** An instance with no project of its own opens on one question, "What do you want to build?", with starter sentences from the templates, a paste-your-last-incident door and the demo as a one-click offer. The same screen is Projects → Create new; the template gallery is behind **Use a guided template**. `GET /api/projects/templates/{key}` serves one template. - Project page: source rows fold open to the ingest endpoint or the polled target, with Configure. Framed empty states for runs, firings and events. **Changed** - **Deleting takes dependents along.** A source or view delete lists what depends on it and offers to delete those too (`cascade=true`; `GET /api/catalog/dependents` lists them). A project delete lists its objects with picks; unpicked ones stay (`DELETE /api/projects/{id}?delete=kind:name,...`). ## 1.24.0: 2026-09-04 **Added** - Runs on an agent's page and a project's Agents tab filter to successful or failed runs, and **Show more** pages past the first fifty (`status` and `offset` on the runs endpoint). **Fixed** - Edit on a project from a template without its own wizard opened the create form and said the template did not exist. The form loads the template by key, prefills the project's parameters (secrets blank, blank keeps the stored value) and saves in place. **Changed** - The root span of a traced run carries `tares.instance` and `tares.agent` as attributes. ## 1.23.0: 2026-09-03 **Added** - **Agent tracing.** Every Tares agent run and every Ask turn can be exported as an OpenTelemetry trace: a root span, one span per model call and one per tool call, in the conventions GenAI observability backends read. Rius is a preset; any OTLP/HTTP endpoint works with the `otlp` provider. Settings → Observability holds the switch; `TARES_TRACING_*` sets the same from the environment. Off unless switched on. ## 1.22.0: 2026-09-03 **Added** - **Pause a project with its sources.** Pause asks whether to pause the sources too; Resume brings back exactly what Pause stopped. `{"sources": true}` on the pause endpoint. - The GitHub source form picks a stored token from a dropdown and the repo from the list that token can see; a new token can be saved from the same form. **Changed** - The challenger project's sessions open in place, with the summary, that session's memory proposals and the exchange under the row. The project page shows the status badge beside the name. ## 1.21.0: 2026-09-02 **Added** - The `rius_rca` project template: the Tares half of the Rius RCA integration, created by the Rius control plane over the API and hidden from the gallery. **Fixed** - Unknown `/api` and `/ingest` paths answer with a JSON 404 instead of the console's HTML. - PUT on a view or agent no longer requires the name in the body; a rename is still refused. - `GET /api/sources/discover` explains that discover is POST-only. ## 1.20.0: 2026-09-01 **Changed** - **The side nav has two groups.** Projects at the top with Overview and Ask; everything a project is made of in one Catalog group in pipeline order. - The demo's logs source drops routine 2xx access lines in hosted mode. **Fixed** - Deleting a template project with purge also deletes its triggers' firings. ## 1.19.0: 2026-09-01 **Changed** - **Every project renders on one page**: Setup (sources, views and triggers editable in place, subscribers), Events, Firings, Agents, and Sessions where a template reports them. Template actions, Repair and the change history moved with it. - Templates describe their page extras as data (panels and cards); a new template needs no console work. ## 1.18.0: 2026-09-01 **Added** - The project page manages subscribers: a Subscribers box lists everyone subscribed to the project's triggers, with what each received, and adds or removes them there. - The project Firings tab shows who each firing was delivered to. - `/projects` is the list of projects; the ways to start one moved to `/projects/new`. **Fixed** - Deleting a trigger also removes its subscriptions. ## 1.17.0: 2026-09-01 **Changed** - **Deliveries is now Firings.** A firing is the event, a delivery is what happens to it per recipient; `/deliveries` redirects. External subscribers moved to the agents page. - The Sources, Views, Triggers and Firings pages became lists with filters; the firing page is one facts box with the payload beneath. **Fixed** - A delivery whose Tares agent is still running showed as failed; running, delivered and failed are distinct. ## 1.16.0: 2026-08-31 **Added** - Hand-assembled projects got their own page with four tabs: Setup, Events, Firings, Agents. **Changed** - Trigger page: the watched view and the project badge moved into the first box. ## 1.15.1: 2026-08-31 **Changed** - Rerun is offered on every finished agent run, not only failed ones. ## 1.15.0: 2026-08-31 **Added** - **A per-agent budget.** `budget_usd` on a Tares agent caps its lifetime spend; once reached, runs are capped before any model call and the run says where to raise or clear it. - On a hosted demo stack the AI SRE demo's agent is born with a $2 budget. ## 1.14.0: 2026-08-31 **Changed** - **Use cases are now projects; recipes are templates.** A project is a named set of sources, views, triggers, agents and MCP servers with one page; the shipped recipes are Tares templates. The API moves to `/api/projects` and `/api/projects/templates`, catalog YAML uses `projects:` with `template:`, and the seed variable is `TARES_SEED_PROJECT`. The old routes, YAML keys and variable keep working for two releases. - `claude_code` events label the repository the session ran in as `repo` (was `project`); saved sources, views and stored data follow on upgrade. **Added** - **Projects from existing objects.** Assemble a project from the sources, views, triggers, agents and MCP servers you already have; nothing is created, and removing an object from the project leaves it in place. - **Rerun an agent run.** A run that failed, ran out of rounds, was capped or came back empty has a Rerun button: same trigger, same entity, same firing data, against the agent's current definition. Runs also open with the agent's previous finding for the entity, a head start instead of rediscovering it. - The challenger session thread lists every finding of a review in full. ## 1.13.0: 2026-08-27 **Added** - **Challenger workflow in the console.** The use case page lists every challenger session with the plan and per-commit review outcomes, the Claude/Codex exchange as one thread, a Summarize button per session, and the summarizer's memory proposals with Accept / Reject. Decisions are kept on the memory source, so they hold in every browser. - The first session marked as a challenger session creates the `challenger_workflow` use case by itself; `/tares:challenger` in Claude Code is the whole setup. **Fixed** - Plugin fixes for marketplace installs, `git -c ... commit`, and Codex 0.150's sandbox flags; only `[P1]` findings block on a plan critique. - Use case actions that start an agent run (`summarize`) failed under `tares up` and left a run stuck at running. - Challenge outcomes read "no findings" / "N findings (M blocking)" instead of PASS/FAIL, which elsewhere in the console means a broken run. ## 1.12.0: 2026-08-27 **Added** - **Challenger workflow.** A second model challenges Claude Code's plan and every commit, locally, while Tares keeps the record: a per-session view, a trigger on session end and a summarizer agent that writes a session summary with memory proposals. The `claude_code` connector gains the `flow` label and challenge events with verdict, sha, round and finding counts. - **Claude Code plugin 0.2.0.** `/tares:challenger` turns a session into a challenger session; the plugin runs Codex on plan exit and after each commit (blocking on P1/P2 findings, with a fix loop and `/tares:challenger-waive`), ships every review to Tares, and hands accepted memory to Claude at session start. ## 1.11.0: 2026-08-26 **Added** - **Install skill for coding agents**: `npx skills add glassflow/tares --skill tares`. From one prompt, an agent installs Tares, starts it, adds a first source, connects itself over MCP and shows one read. - **`tares status`**: a readiness checklist for a running instance that ends with the one next step; `--json` for scripts. `tares up` prints the same "Next:" line under the console URL. **Changed** - An agent run without a key, and the banners on the Agents pages, say what to do: set `ANTHROPIC_API_KEY` before `tares up`, or add a key under Settings. ## 1.10.0: 2026-08-25 **Changed** - **A key stored in the console now takes precedence over `ANTHROPIC_API_KEY`** (it was the other way around). If you relied on the env var overriding a stored key, clear the stored key. **Added** - **Grafana Loki connector.** Polls a LogQL stream selector; one event per log line with the stream's labels and the same derived fields as docker_logs. Works against any reachable Loki, including Grafana Cloud. - **The AI SRE demo works against a hosted demo stack** when the `TARES_DEMO_*` URLs are set; with them unset the local docker compose flow is unchanged. - **The spend meter records which key paid**: `GET /api/usage/model` reports a `by_key_source` split, so an operator-provided key's spend is separable from your own. - **`TARES_SEED_USECASE`**: seed a named use case once on first boot, so an instance starts with a working setup instead of an empty catalog. ## 1.9.0: 2026-08-24 **Added** - **Model usage and cost per agent run.** Every run records its model, token usage and a USD cost priced at write time; Ask turns are metered the same way. Runs from before this release show no cost (unknown, never guessed). - **`GET /api/usage/model`**: the instance's Anthropic spend as all-time totals plus a per-day tail, split by surface. - **The Tares agents page is an operational surface**: stat cards, tabs, and runs as a table with model, rounds, tokens and cost, expandable to the finding. ## 1.8.2: 2026-08-19 **Fixed** - A trigger no longer misses a key whose source ingested right after another; a skipped evaluation is re-run once the debounce interval ends. - Shared code context: the `every_commit` trigger's detection window is 5 minutes, matching the 60-second source poll. ## 1.8.1: 2026-08-19 **Added** - **AI SRE demo as a use case.** Use cases > AI SRE demo (tagged demo) creates the same three sources, `service_timeline` view, `incident` trigger and `incident-first-look` agent the demo catalog seeds, with one click; an already imported demo catalog is adopted, not duplicated. The setup page asks Docker what is running and fills the Prometheus and api-server URLs and the log container from it, shows the docker commands with copy buttons when the stack is not up, and takes an Anthropic key inline. The use case page has **Cause an incident** (error spike, latency, dependency outage) and **Clear the fault** buttons. Recipes can declare tags, setup steps, actions, a guide link and a detect hook. **Fixed** - **Auto-discover (Docker) works again** when a Prometheus container is running; it proposes a reachable starter metrics source and says how many metrics wait to be picked on the source page. ## 1.8.0: 2026-08-18 **Added** - **Use cases.** A new console section and framework: a use case is a ready-made setup that creates ordinary Tares objects and owns them (badge on their pages, editable and deletable there; an edit marks the object customized, a hand delete shows as missing with Repair). Create, update by re-plan, pause and resume, delete, repair; `/api/usecases`; `usecases:` in catalog YAML. Use cases are now [Projects](/tares/projects). - **Shared code context** use case: one commits source per repository, a view with one timeline per repository, a trigger on new commits, GitHub's hosted MCP server registered with the stored credential, and an agent that keeps a context repository current as pull requests; existing pages updated in place or one page per repository; optional first look on start. See [the guide](/tares/guides/shared-code-context). - **GitHub credential stored once** under Settings > GitHub; `credential: ` on `github` sources, `credential:github/` on MCP servers; rotation in one place. - **MCP servers take extra headers** (for example `X-MCP-Toolsets` on GitHub's hosted server). - **Per-agent round cap** `max_rounds` (default 6, 12 with external MCP servers) and an `exhausted` run status with a partial note. - **GitHub commits carry their changed files** in the payload (capped; `files: false` to skip). - **Settings has tabs**: Access and API keys, Anthropic, GitHub, Slack. ## 1.0.0-1.0.1: 2026-08-05 **Changed** - **NavFlow is now Tares. This release is breaking, with no compatibility layer.** The package and command are `tares`, the daemon is `taresd`, the MCP proxy is `tares-mcp`, and `--navflowd` is `--taresd`. Every `NAVFLOW_*` environment variable is now `TARES_*`, and the old names are not read. The image is `ghcr.io/glassflow/tares`, the repository is [glassflow/tares](https://github.com/glassflow/tares), and the Claude Code plugin is `tares@tares`. - **The database file is `tares.duckdb`**, previously `navflow.duckdb`, inside a data home that moved from `~/.navflow` to `~/.tares`. **Two guards instead of a fallback.** Both renames above would otherwise fail quietly, coming up healthy and empty while the real data sat untouched beside the new file. So the daemon refuses to start if any `NAVFLOW_*` variable is still set, or if a pre-1.0 database sits next to a missing `tares.duckdb`, and prints the rename or the `mv` you need. Full instructions: [Upgrading from 0.x](/tares/deployment#upgrading-from-0x). ## 0.2.0: 2026-07-26 **Added** - **[Tares agents](/tares/tares-agents)**: a prompt attached to a trigger. When the trigger fires, Tares reads the correlated timeline and writes a **finding** back onto the entity's timeline (a built-in `findings` source). Configured in the console (**Agents**) or the catalog (`agents:`); enabled ⟺ subscribed to its trigger; read-only (it concludes, it doesn't act). The [demo](/tares/guides/ai-sre) ships one that diagnoses the injected incident out of the box. - **`navflow up --auth`**: one switch for authentication. Bare `--auth` generates and persists a **root token** and prints a `…/?token=…` login URL each launch; `--auth=` uses your own. Open by default (`navflow up`). - **Per-source API keys**: creating a push source on a secured instance mints an `ingest`-scoped [API key](/tares/deployment#api-keys) for it (shown once). The Security page groups Access, API keys, and the Anthropic key. **Changed** - **Ingest is gated by auth like every route.** Producers authenticate with scoped `ingest` API keys (`Authorization: Bearer `), not a shared token. **Removed** - **`NAVFLOW_INGEST_TOKEN`** and **`NAVFLOW_READONLY`**: folded into the one auth switch + scoped API keys. - **`GITHUB_TOKEN`** and **`NAVFLOW_VERCEL_VERIFY`** env vars: GitHub tokens come from the source's `token` config; Vercel drain verification echoes Vercel's own probe header. - **`NAVFLOW_ANTHROPIC_KEY`**: use `ANTHROPIC_API_KEY` (or the console-stored key). ## 0.1.36: 2026-07-23 **Added** - **[`alertmanager`](/tares/connectors/alertmanager) connector**: a push receiver for Alertmanager. Point a `webhook_configs.url` at the source's ingest endpoint; each routed alert becomes an event (keyed by a label, firing / resolved). The source page shows a copy-paste `alertmanager.yml` receiver block. ## 0.1.35: 2026-07-23 **Added** - **[`prometheus_alerts`](/tares/connectors/prometheus-alerts) connector**: polls Prometheus's own `/api/v1/alerts` and emits one event per active alert (keyed by a label), plus a `resolved` event when it clears. Discover lists the configured rules with an optional severity filter. - **[`reference`](/tares/connectors/reference) connector**: documents (json / csv / md / txt) attached to an entity by their labels, always surfaced when correlating on that entity regardless of the read window. **Removed** - **`alerts` and `static` connectors**: superseded by `prometheus_alerts` / `alertmanager` and `reference` respectively. ## 0.1.34: 2026-07-22 **Changed** - **[Prometheus](/tares/connectors/prometheus): pick the metrics, no PromQL.** Discover now lists the server's metrics and labels; you pick what to ingest (by name or by label) and Tares writes the query. The metric value is stored as a number-typed `value` label, so triggers can aggregate it. Added bearer / basic auth. ## 0.1.32-0.1.33, 2026-07-22 **Changed** - **[Postgres](/tares/connectors/postgres)**: the connection URL (`dsn`) is a required per-source config field, stored as a secret; the driver ships in the base package (no `[postgres]` extra); you can select which columns to pull. Dropped `key_column` (the key is a `primary` label) and `cursor_type` (inferred from the value). ## 0.1.4: 2026-07-03 **Removed** - **`changelog` and `config` connectors**: dummy, demo-only connectors that had outlived their use. Also drops the demo api-server's unused `/admin/changelog` and `/admin/config` endpoints and renames its fault switch `/admin/inject` → `/demo/inject`. ## 0.1.3: 2026-07-03 **Added** - **`include_payload` on `read`/`query`**: opt-in flag that returns the full lossless stored record as `raw` on each row, alongside the summary `text`. Exposed over HTTP and the MCP `read`/`query` tools; covers all connectors. **Fixed** - **Claude Code plugin install**: publish a root `marketplace.json` (`/plugin marketplace add glassflow/navflow`) and fix `plugin.json` load errors on Claude Code 2.1 (duplicate hooks ref, missing `ingest_token` default, `navflow_url` required flag hiding its default). - **Double-ingest for `claude_code`**: the first pushed event flips a poll-mode source to push mode, so a source fed by the plugin no longer also tails files and ingests every event twice. ## 0.1.2: 2026-07-02 **Added** - `navflow --version`. ## 0.1.1: 2026-07-02 First public (soft-launch) release. **Added** - **`read(selector, window)` primitive**: a correlated, time-ordered read across *all* sources matching a strict-AND conjunction of `label=value` constraints, with no view required. Exposed over HTTP (`POST /read`) and MCP (the `read` tool). Views become an optional narrowing lens; triggers still attach to a view. - **Console redesign**: a selector-first **Explore** (pick an entity, add filters, read across every source, with a human/agent view toggle), a **⌘K Ask** command palette, a three-act navigation, and separate Views / Triggers pages. - **Agents → Reads**: a client filter (defaults to `mcp`) over the read activity log. **Changed** - Package and CLI distribution renamed from `navflow-mvp` to **`navflow`**. --- # Help Stuck, found a bug, or want to talk through a use case? We're happy to help. - **Email**: [help@glassflow.ai](mailto:help@glassflow.ai) - **Book a call**: [cal.com/ashishbagri/glassflow](https://cal.com/ashishbagri/glassflow) - **GitHub**: [open an issue](https://github.com/glassflow/tares/issues) for bugs and feature requests